DoRA
[ICML2024 (Oral)] Official PyTorch implementation of DoRA: Weight-Decomposed Low-Rank Adaptation
- 1k
- Python
- 8 mo ago
[ICML2024 (Oral)] Official PyTorch implementation of DoRA: Weight-Decomposed Low-Rank Adaptation
The Paper List of Large Multi-Modality Model (Perception, Generation, Unification), Parameter-Efficient Finetuning, Vision-Language Pretraining, Conventional Image-Text Matching for Preliminary Insight.
Exploring the potential of fine-tuning Large Language Models (LLMs) like Llama2 and StableLM for medical entity extraction. This project focuses on adapting these models using PEFT, Adapter V2, and LoRA techniques to efficiently and accurately extract drug names and adverse side-effects from pharmaceutical texts
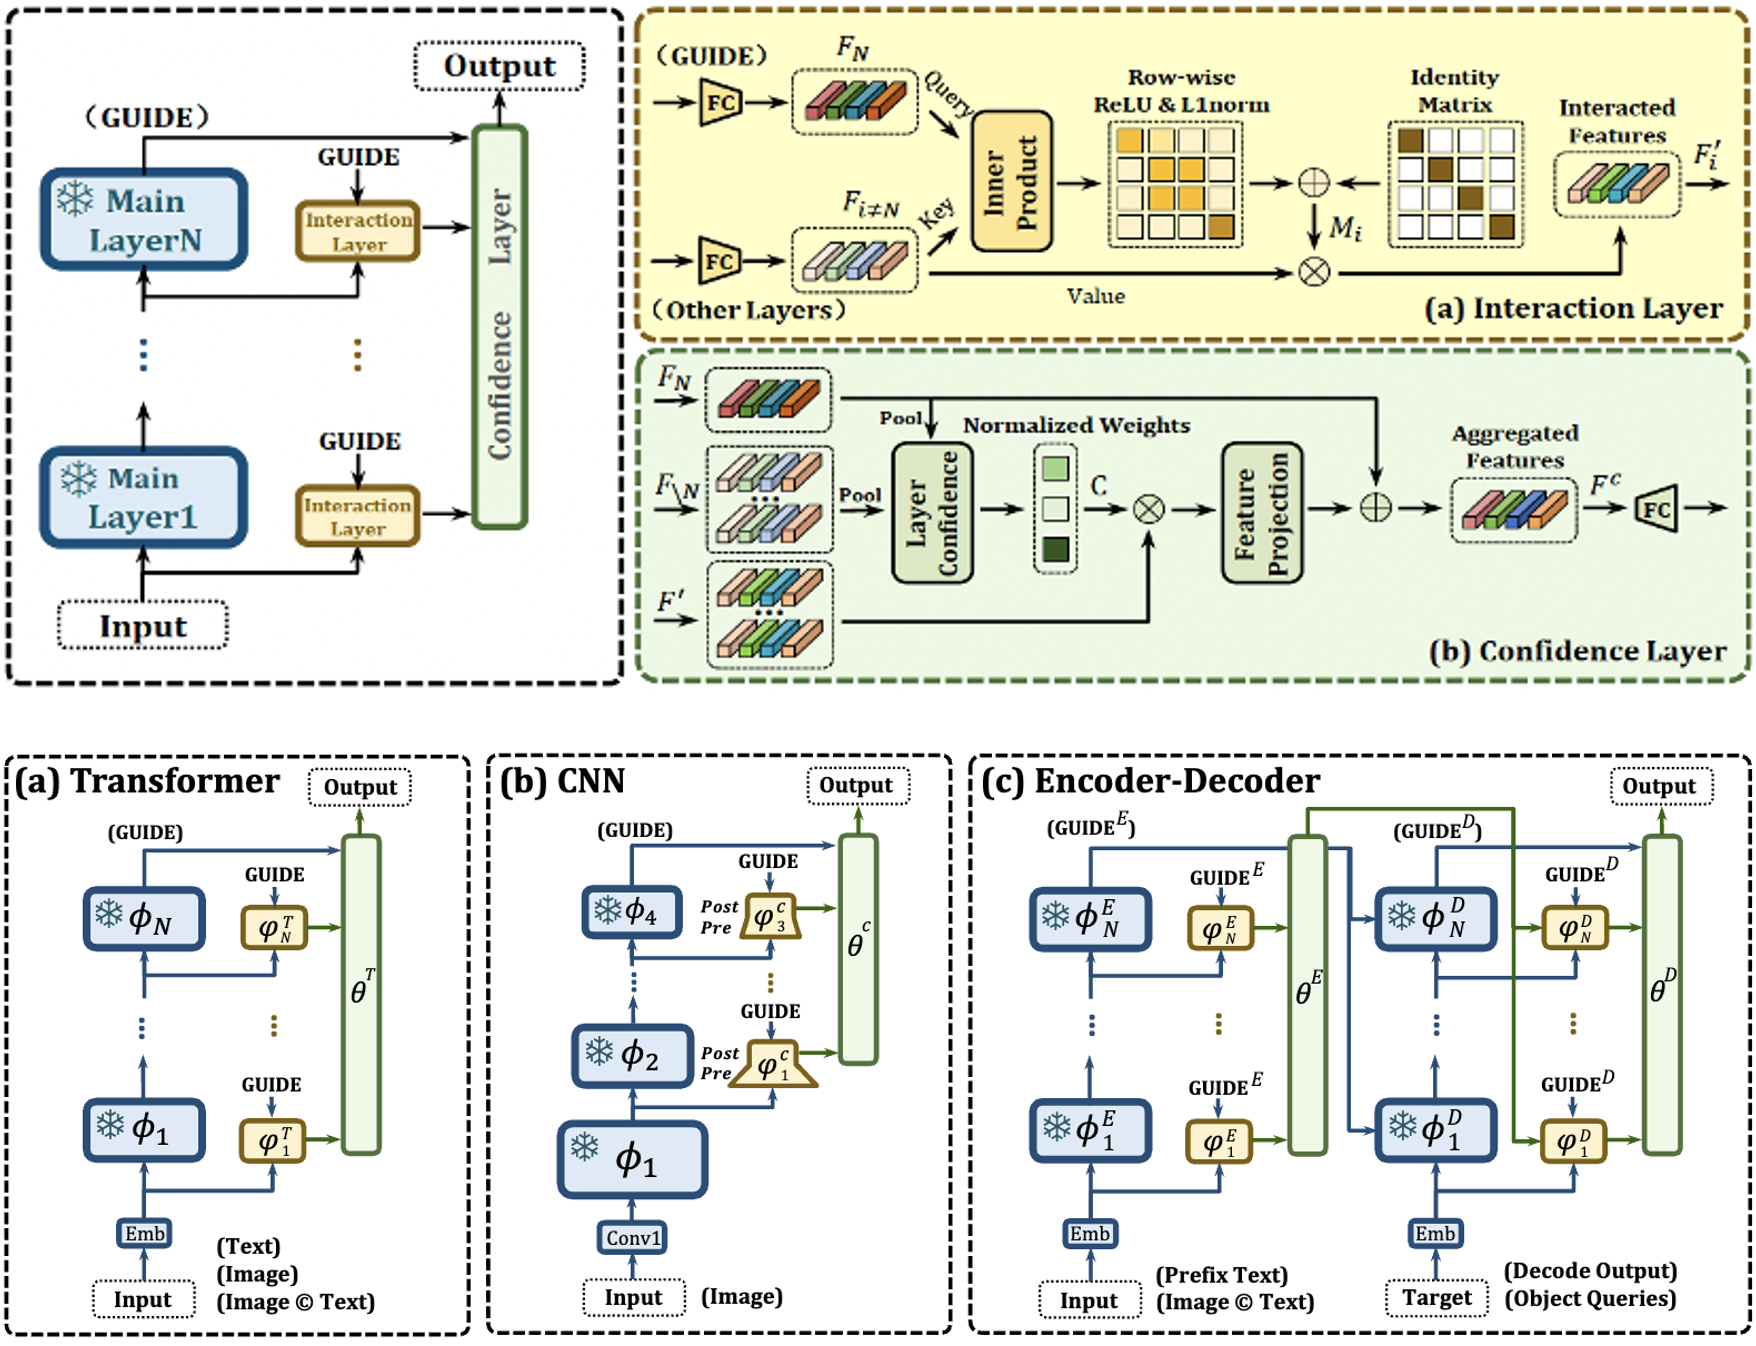
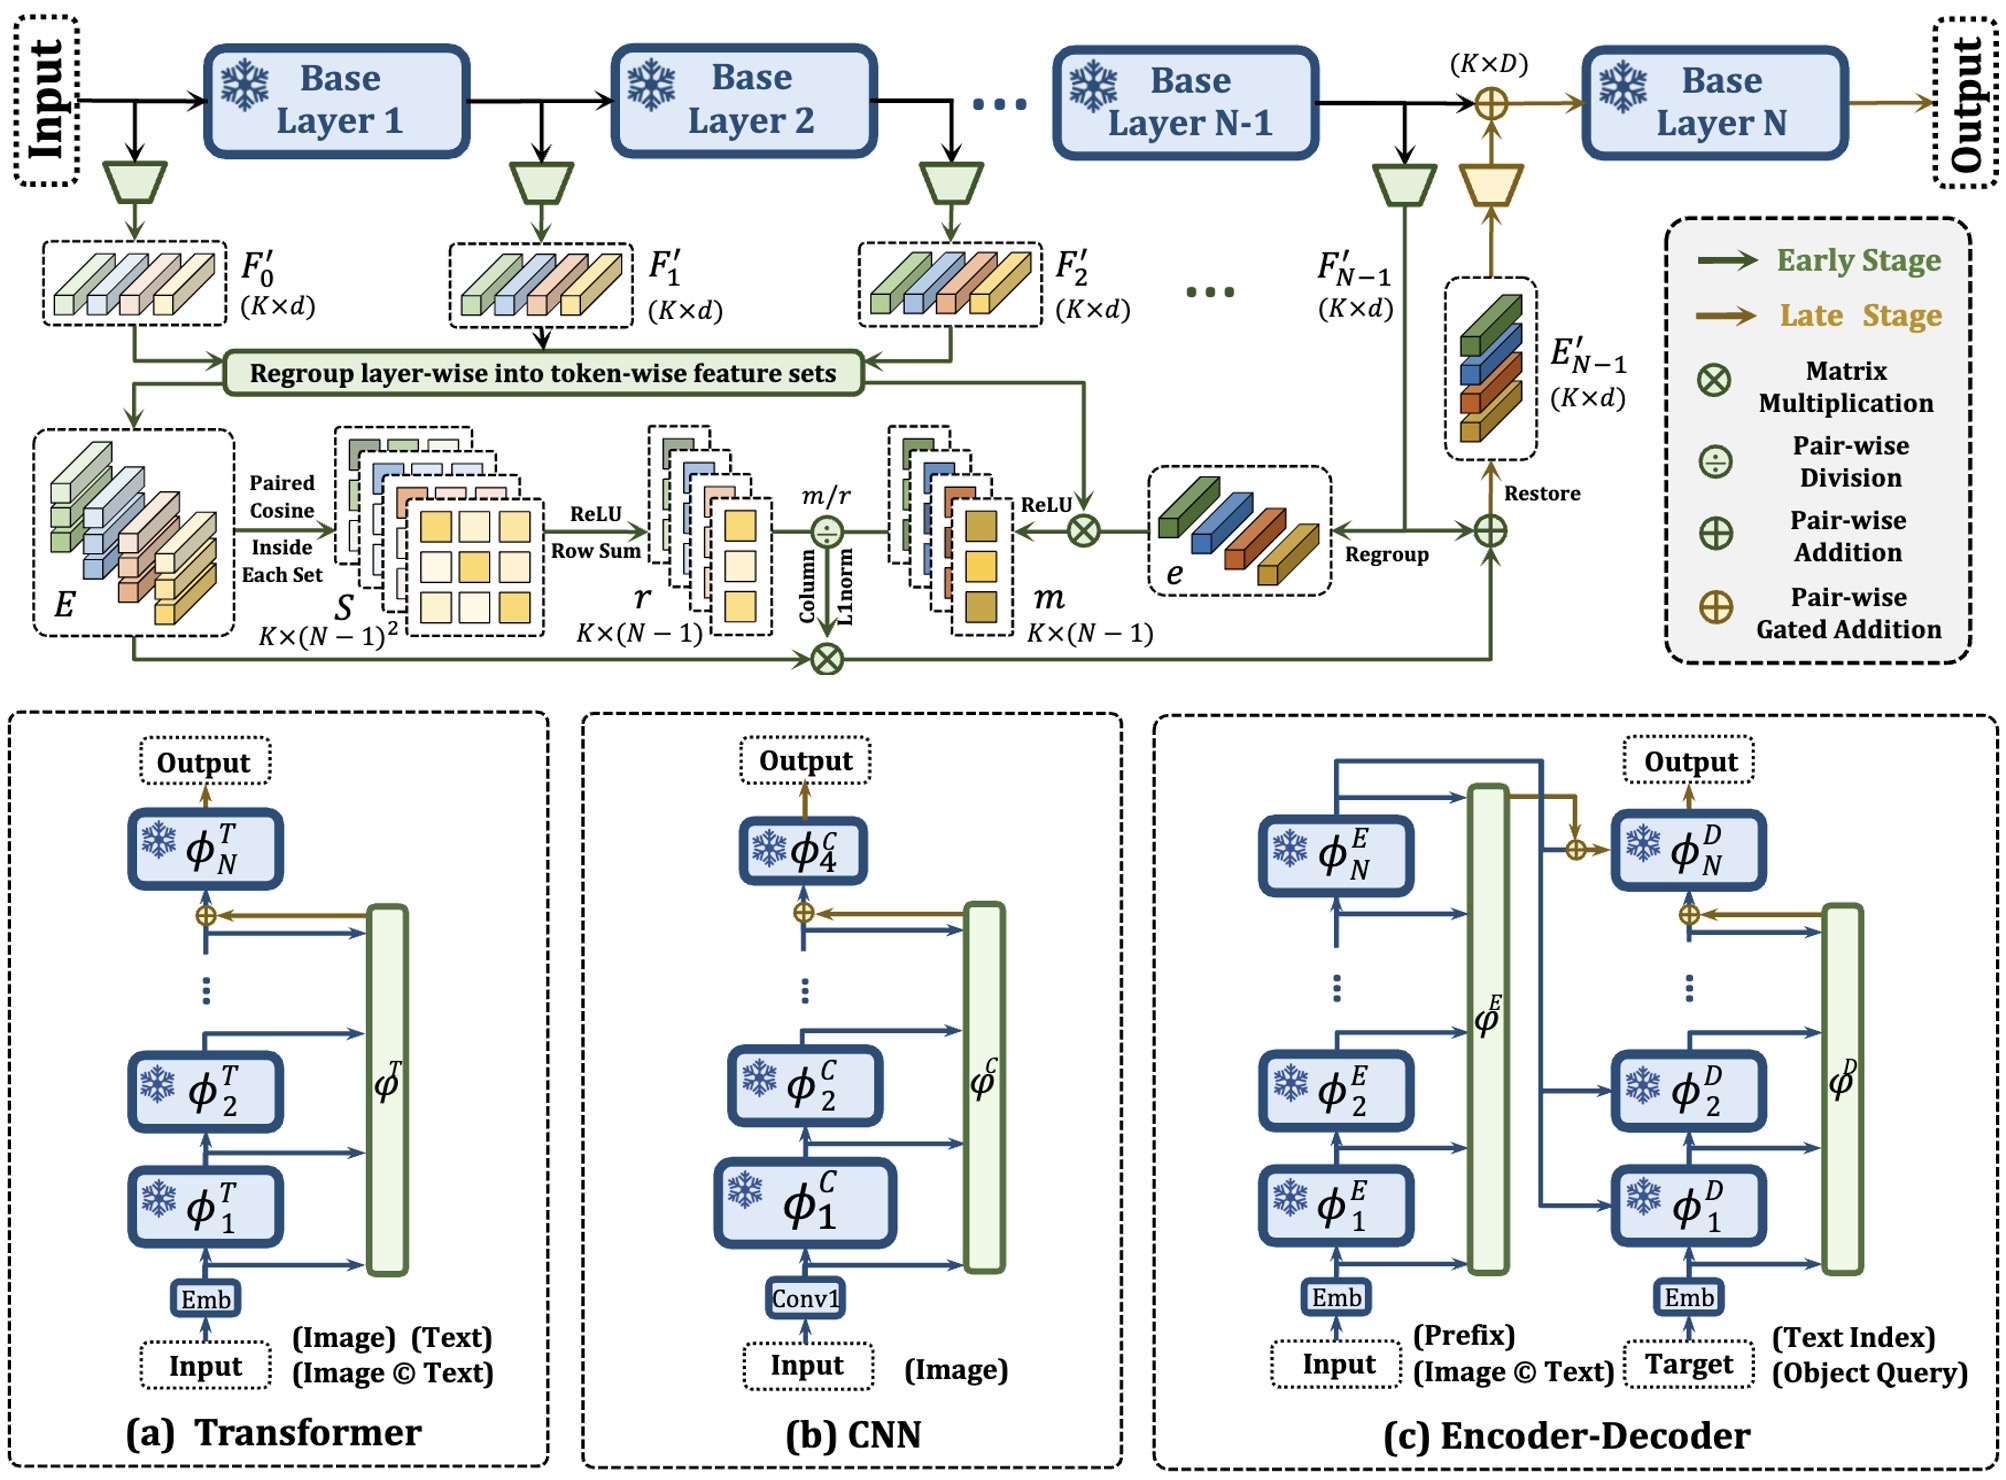
[CVPR2024] The code of "UniPT: Universal Parallel Tuning for Transfer Learning with Efficient Parameter and Memory"
[CVPR 2024] Domain generalization by interpolating original feature styles with styles obtained using random descriptions in natural language
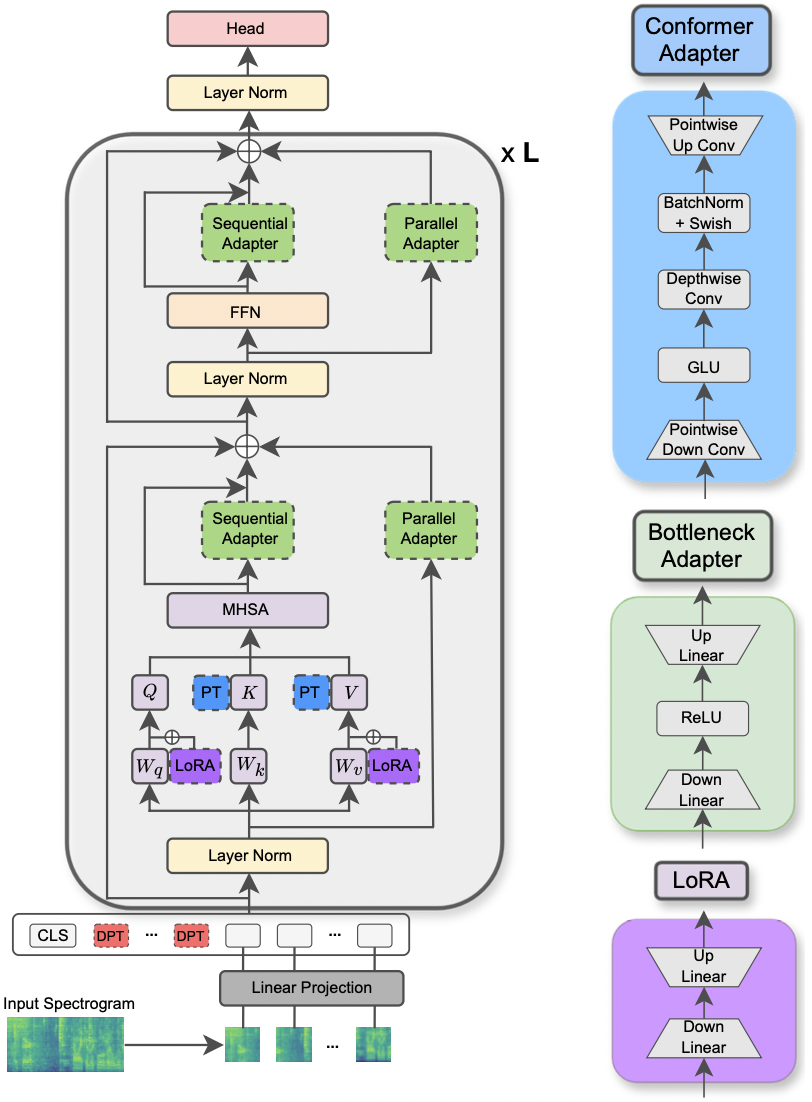
This is the official repository of the papers "Parameter-Efficient Transfer Learning of Audio Spectrogram Transformers" [IEEE MLSP 2024] and "Efficient Fine-tuning of Audio Spectrogram Transformers via Soft Mixture of Adapters" [Interspeech 2024].
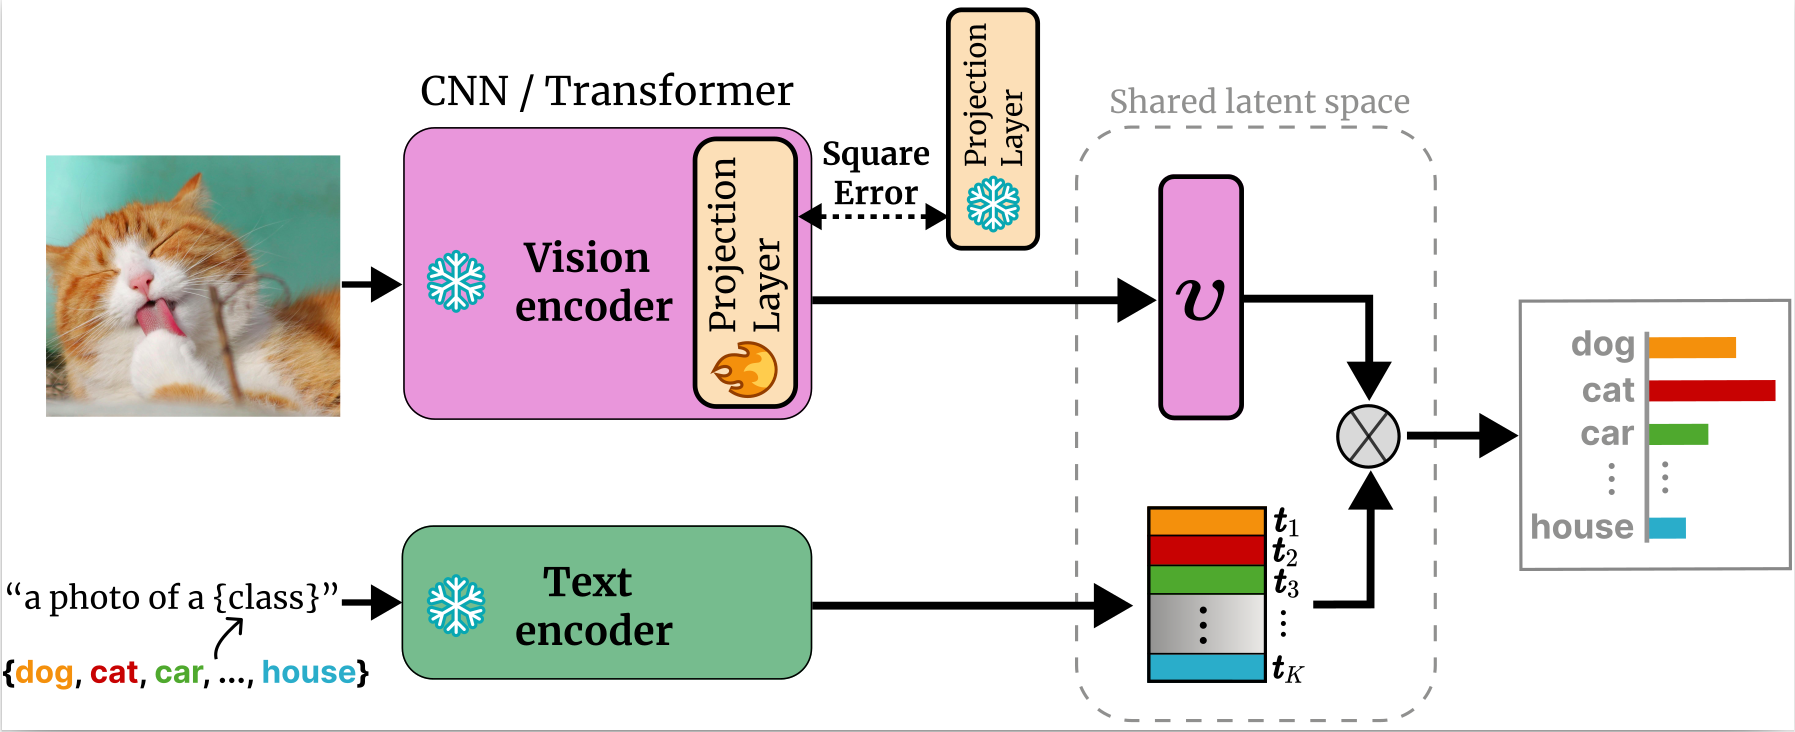
[WACV 2026] An extremely simple method for validation-free efficient adaptation of CLIP-like VLMs that is robust to the learning rate.
[ECCV2024] The code of "SHERL: Synthesizing High Accuracy and Efficient Memory for Resource-Limited Transfer Learning"
Text generation model, used with transformers.
A LoRA adapter that teaches Qwen2.5-1.5B-Instruct to summarise conversations. 18.5M trainable parameters — 1.20% of the base model — tuned on DialogSum, lifting ROUGE-1 from 0.2822 to 0.4185 over prompting the same weights. Loads on top of the base model with PEFT in two lines.
A practical Large Language Model (LLM) fine-tuning repository focused on Low-Rank Adaptation (LoRA) and Parameter-Efficient Fine-Tuning (PEFT). Covers LoRA architecture, adapter configuration, dataset preparation, supervised fine-tuning, model evaluation, and efficient LLM customization using Python, PyTorch, and Hugging Face Transformers.
Large Language Model (LLM) fine-tuning repository focused on Quantized Low-Rank Adaptation (QLoRA) and memory-efficient training. Covers 4-bit quantization, NF4, Double Quantization, LoRA adapters, supervised fine-tuning, dataset preparation, and model evaluation using Python, PyTorch, Hugging Face PEFT, TRL, and BitsAndBytes.
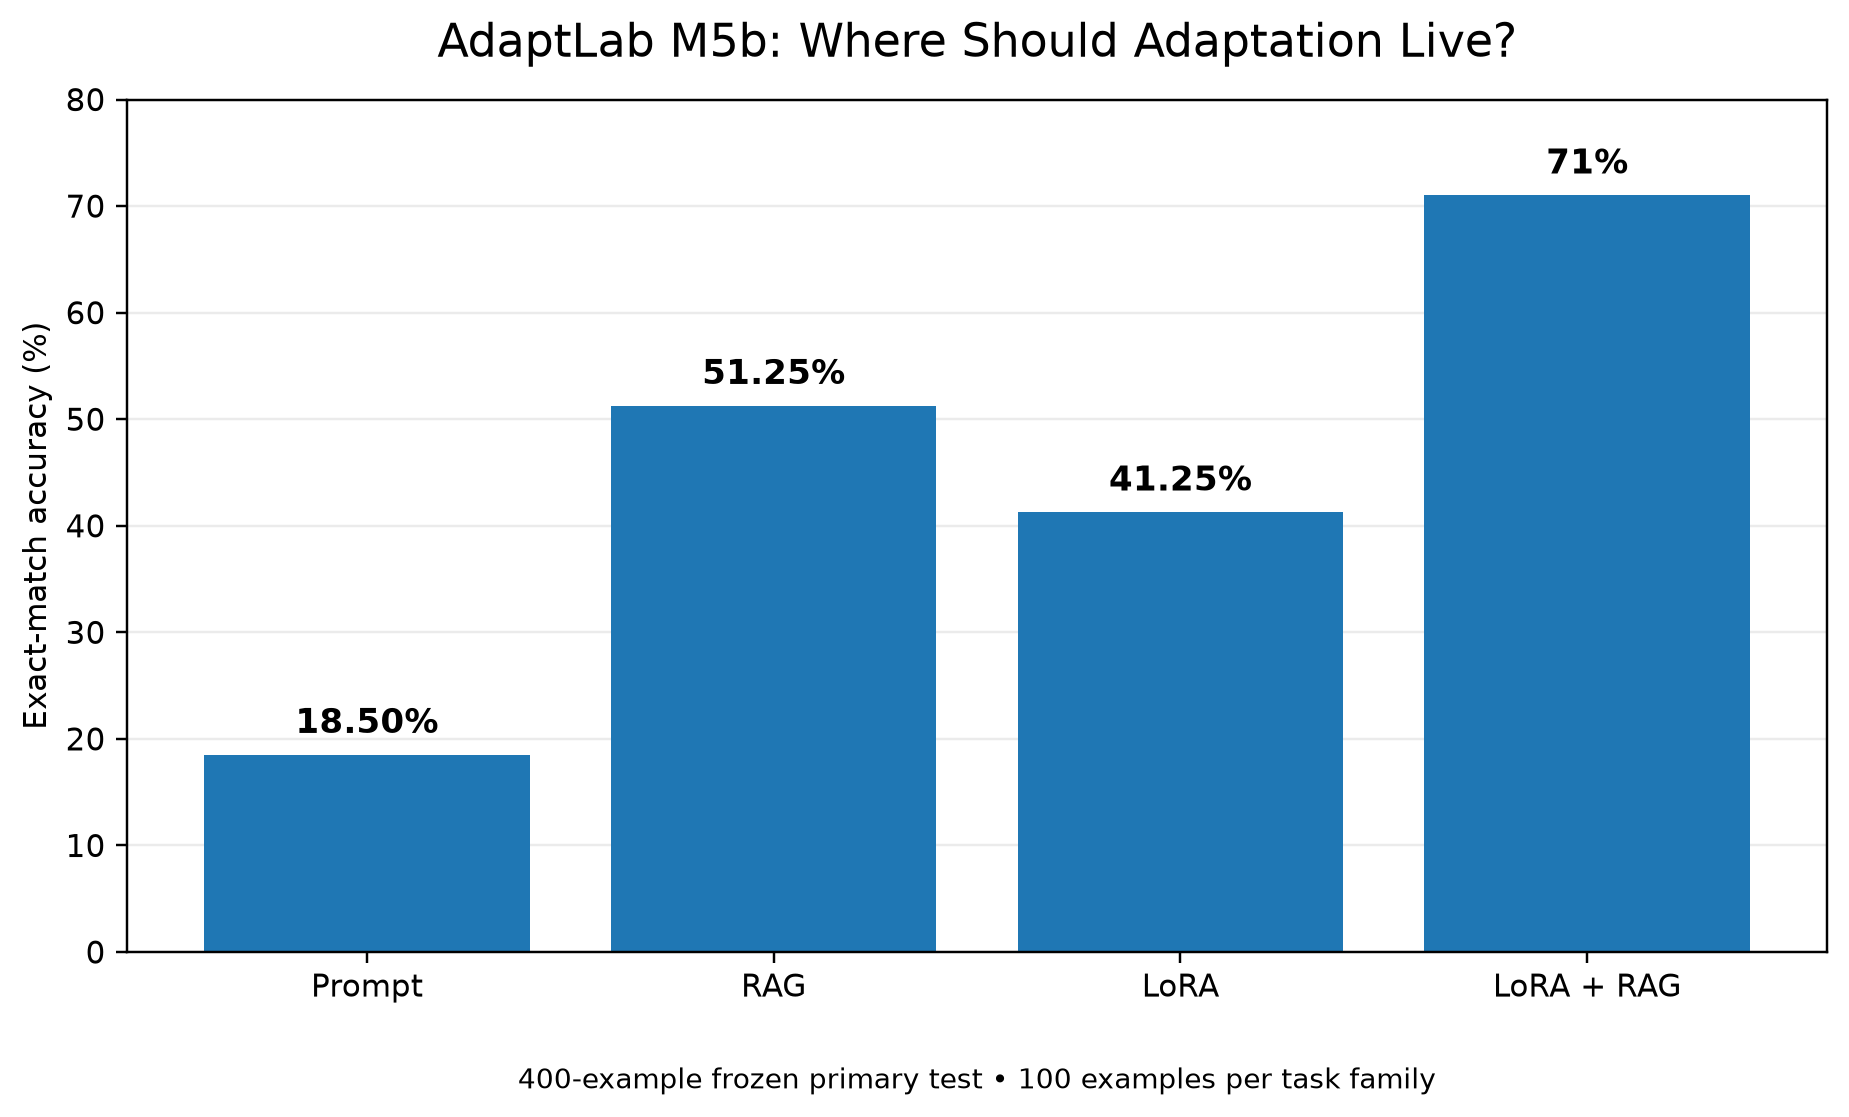
Controlled experiments comparing prompting, RAG, and LoRA for LLM adaptation.
End-to-end fine-tuning of Hugging Face models using LoRA, QLoRA, quantization, and PEFT techniques. Optimized for low-memory with efficient model deployment