PraisonAI
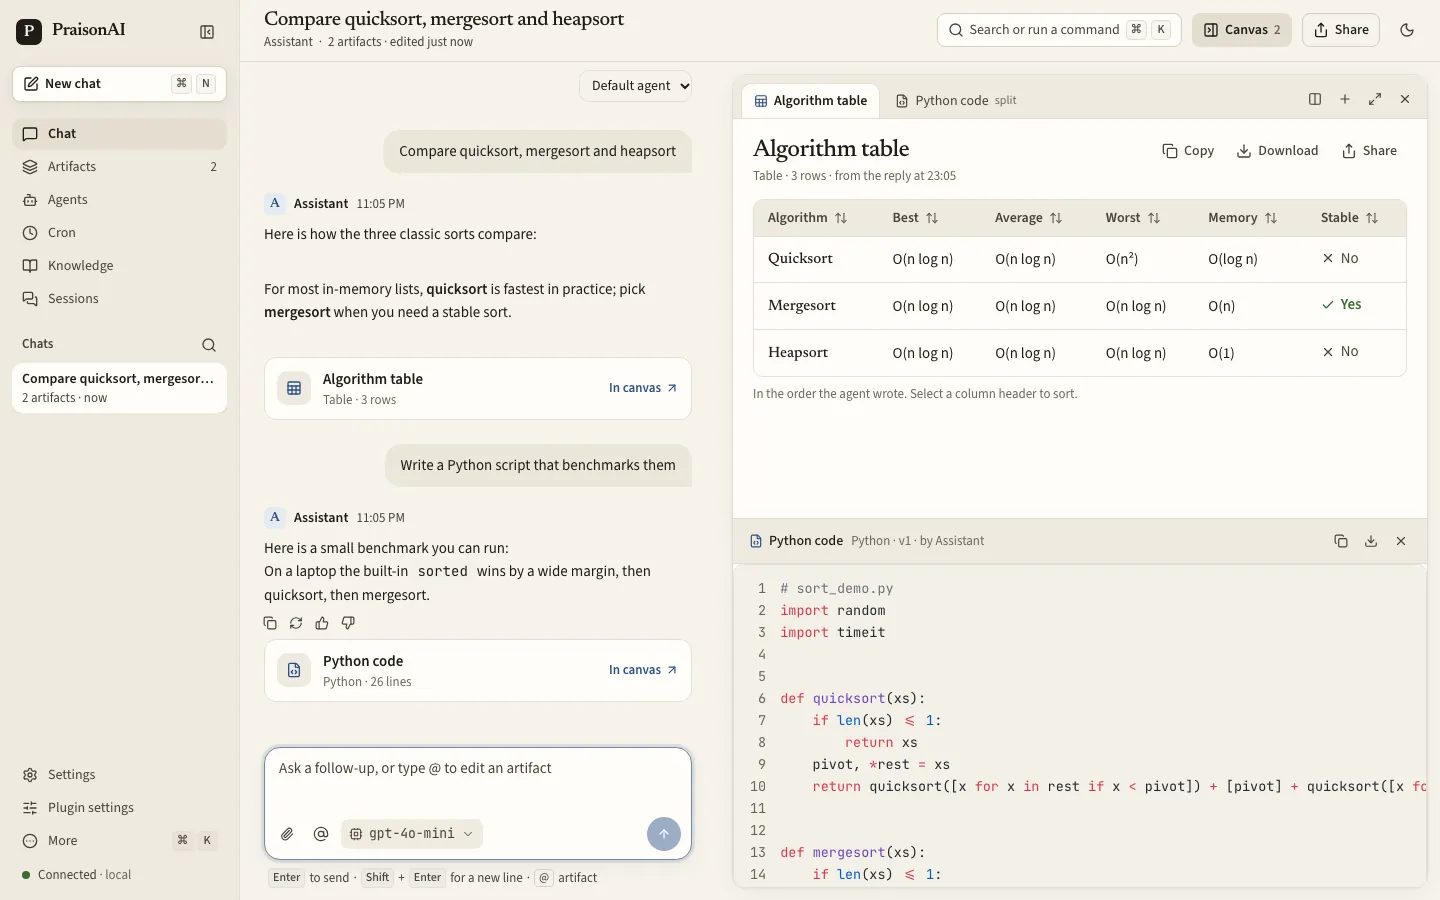
Private AI agents for highly regulated teams, and for anyone who wants AI on their own computer. Open-source Python agent framework that runs fully offline.
- 9.4k
- Python
- MIT
- 2 d ago
Private AI agents for highly regulated teams, and for anyone who wants AI on their own computer. Open-source Python agent framework that runs fully offline.
The open-source context layer for AI agents and enterprise AI search. Permission-aware search and cited answers across 30+ sources, including Slack, Drive, Jira, GitHub and Microsoft 365, for people and agents through MCP, SDKs and built-in agents. Self-hosted or Cloud.
Open-source AI coding assistant for VS Code. Coding agent, code completion, chat, edits and reviews with local or hosted models. Your models, your infrastructure.
Hit your Claude Code usage limit? Keep going free and offline on a local model: Qwen 3.8, Gemma 4, and Qwen 4 the day it ships. Runs on Apple Silicon Macs (MLX), Linux and Windows (llama.cpp) with no API key. Your code stays home.
An easier way to use AI on your own computer. A free, open-source alternative to Claude and ChatGPT that runs open-weight models like Gemma and gpt-oss locally on Mac, Windows and Linux. Private, and works offline.
Alzeo is an open-source installer that turns an NVIDIA DGX Spark, or any GB10 machine (ASUS, Dell, HP, Lenovo, MSI, GIGABYTE, Acer), into a private AI server in one command: measured model lanes, OpenAI and Anthropic APIs, and a local cockpit.
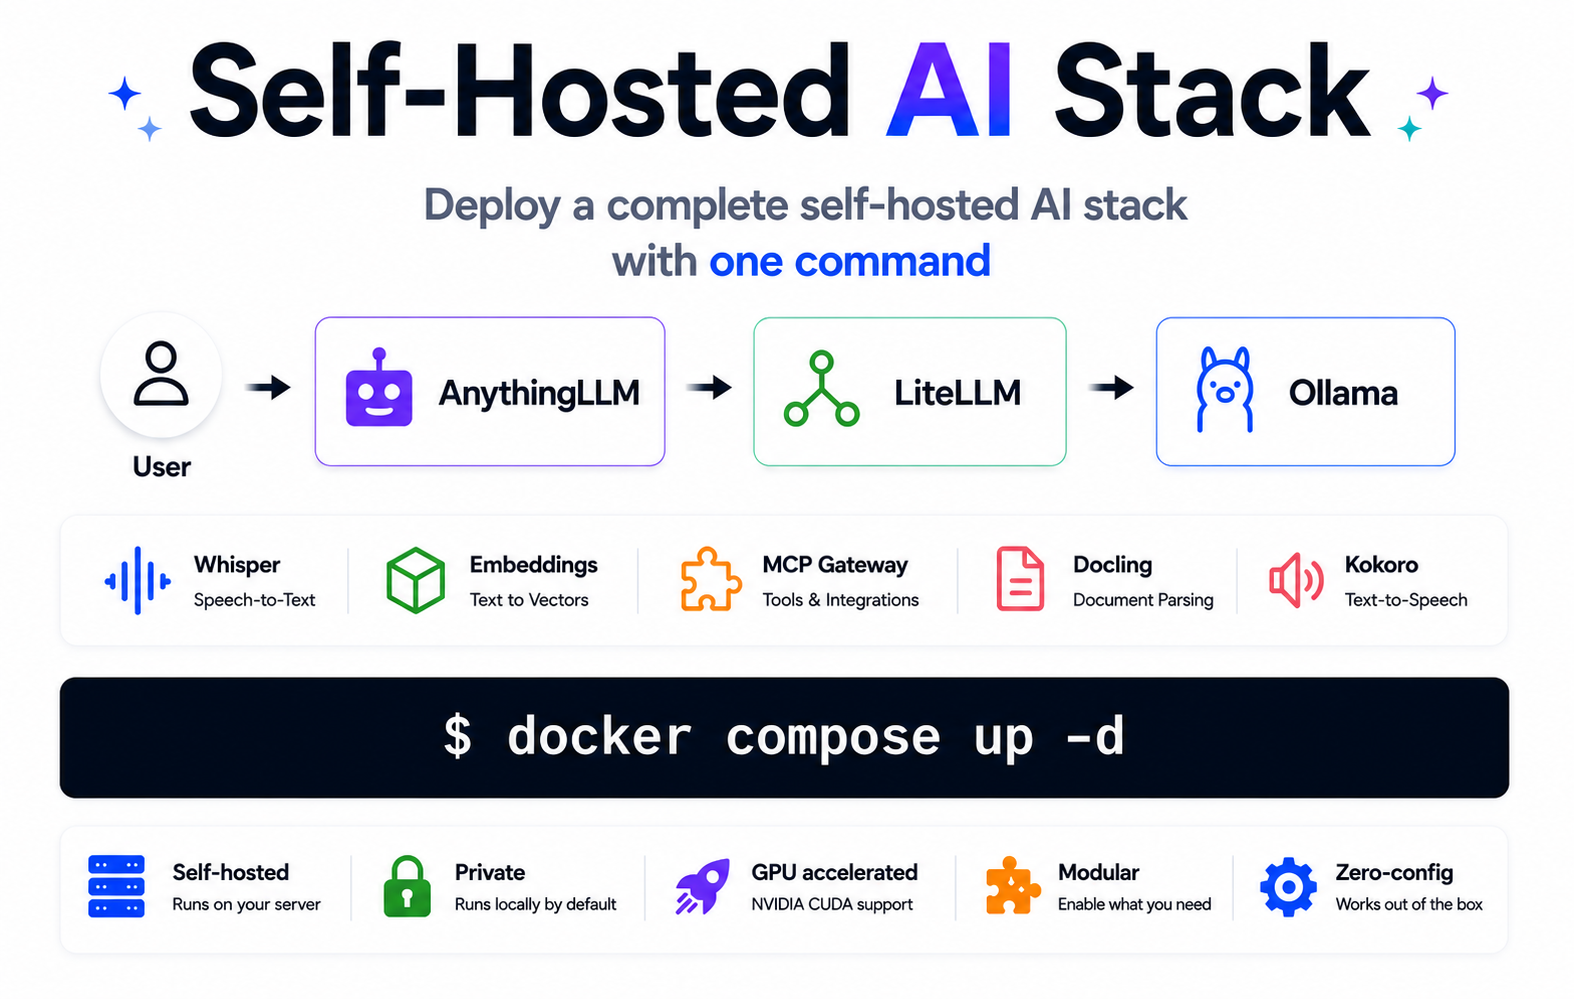
Deploy a self-hosted AI stack with Docker Compose: local LLMs, chat, document parsing, embeddings, transcription, text-to-speech and MCP tools. Powered by Ollama, LiteLLM, AnythingLLM and more. Local-first with auto-configured authentication, lightweight stacks, optional HTTPS and NVIDIA GPU support. MIT licensed. Multi-arch: amd64, arm64.
A modular desktop workspace for configuring and running local AI models.
Ollama Local AI Offline: Run Local LLMs Fully Offline on Desktop
Turn one machine into a private ChatGPT for a whole room. One command sets up Ollama, Open WebUI, RAG and an OpenAI-compatible API sized to your hardware, and pondok-ai share lets a classroom or office chat from their own phones.
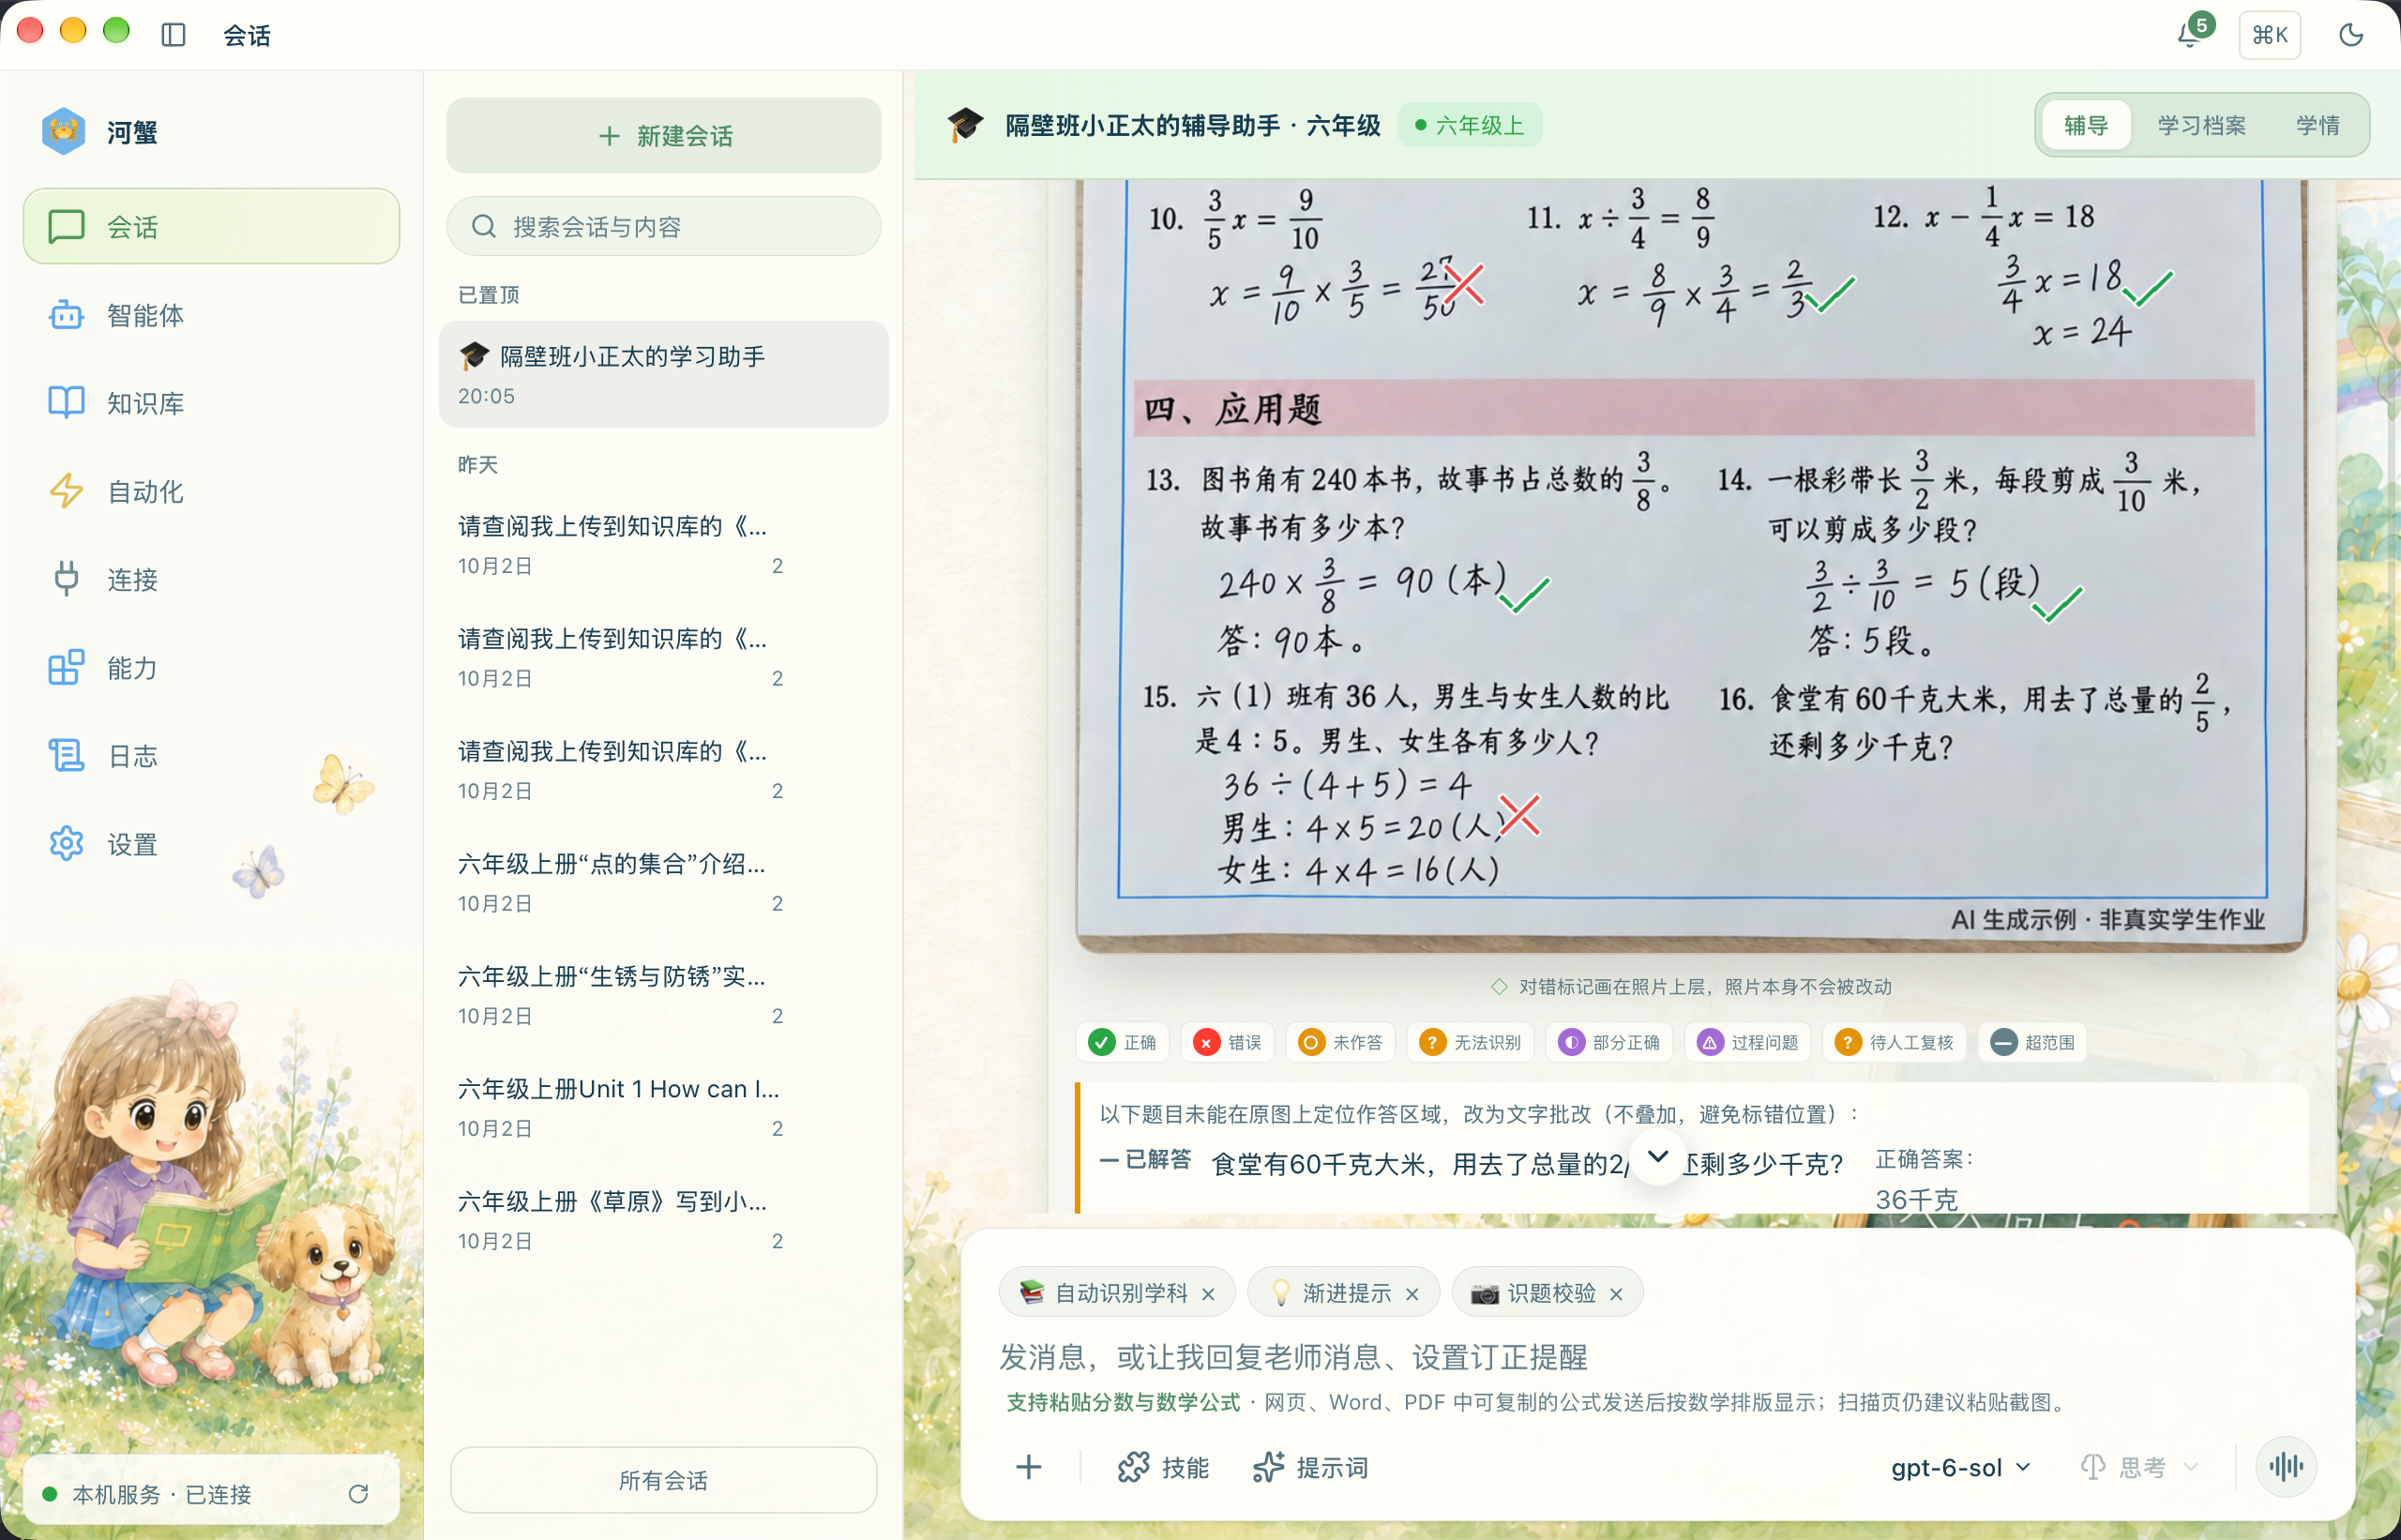
基于 Tauri 2 与 Vue 3 的 AI Agent 桌面工作台,支持本机或云端 HexClaw 服务,集成多模型对话、知识库、工具、任务自动化与作业辅导。
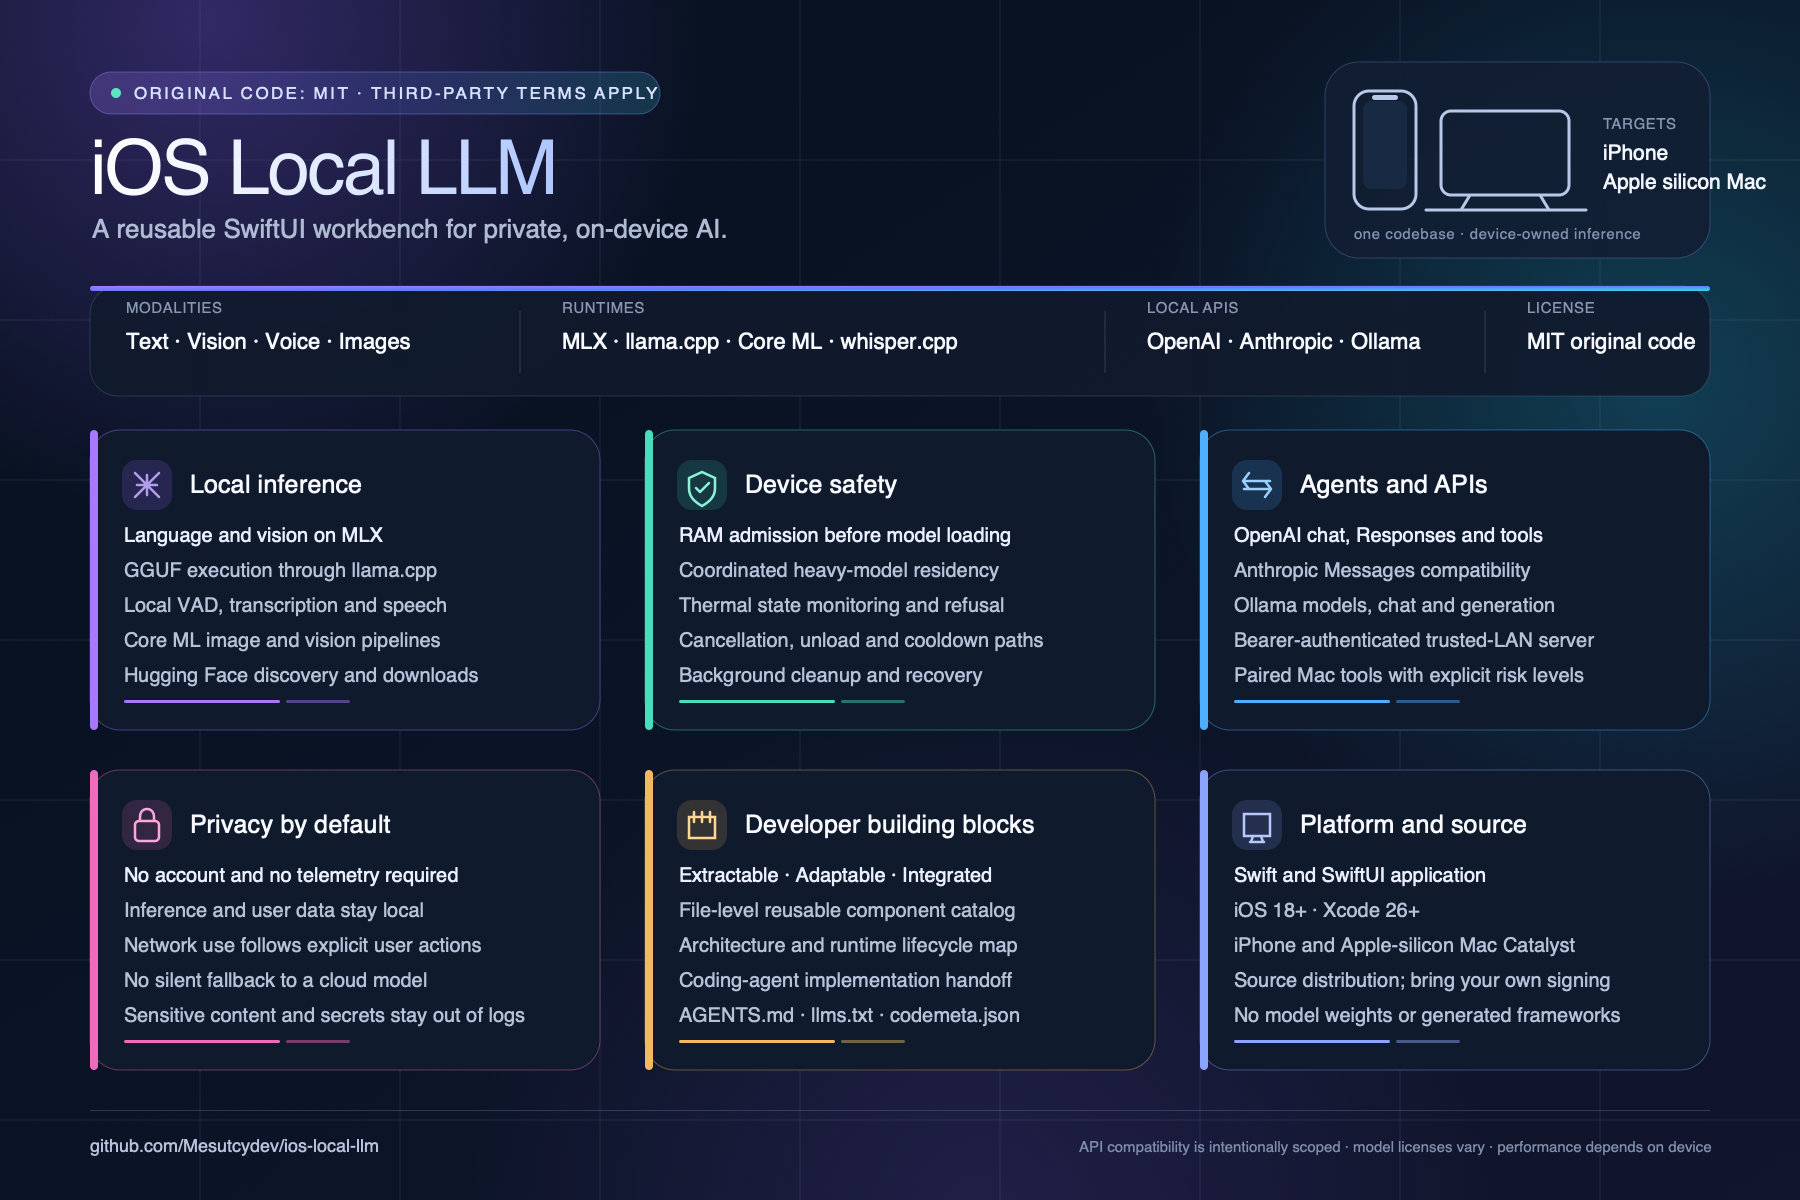
OnDevice Local AI Studio — run LLMs on iPhone offline. SwiftUI workbench with MLX, llama.cpp, whisper.cpp, RAG, and authenticated OpenAI/Anthropic/Ollama-compatible local APIs.
Priveedly: A django-based content reader and recommender for personal and private use
Run IBM Granite 4.0 locally on Raspberry Pi 5 with Ollama.This is a privacy-first AI. Your data never leaves your device because it runs 100% locally. There are no cloud uploads and no third-party tracking.
Apache 2.0-licensed open source operations stack for private AI inference with open models. Run LLMs (7B-70B) locally with vLLM, OpenAI-compatible API, web dashboard, chat UI, admin panel, and hardware monitoring.
An advanced, fully local, and GPU-accelerated RAG pipeline. Features a sophisticated LLM-based preprocessing engine, state-of-the-art Parent Document Retriever with RAG Fusion, and a modular, Hydra-configurable architecture. Built with LangChain, Ollama, and ChromaDB for 100% private, high-performance document Q&A.
InferCrate: self-hosted local LLM server powered by Ollama. Secure by default with auto-generated Bearer token auth. Native Ollama API and an OpenAI-compatible /v1 API subset. First-start model pre-pull, NVIDIA GPU (CUDA) acceleration, and persistent model storage. Docker deployment on CPU (amd64/arm64) or CUDA (amd64).
PocketLFM — run Liquid AI's LFM2.5 large language model fully on-device on Android. Offline, private, no cloud. Open-source edge AI via llama.cpp (GGUF). First independent open-source Android app to run LFM2.5 outside Liquid's own Apollo/LEAP.
Oracle is a local-first inference runtime aimed at efficient hybrid-model execution on constrained consumer hardware. Phase 1E adds stateful CPU reference execution: embeddings, Qwen3.5 RoPE, grouped-query causal attention, Gated DeltaNet recurrent state, deterministic sampling, and exact cache-memory planning.
AI tools that protect your data sovereignty. Privacy-first by design.
Security guide for deploying AI systems in regulated industries. Covers threat modeling, data protection, model security, and compliance mapping for HIPAA, CMMC, and SOC 2.
Complete guide to deploying private, on-premise AI and LLMs: hardware selection, model comparison (ollama vs vLLM vs llama.cpp), security hardening, and AI governance policy templates. By Petronella Technology Group.
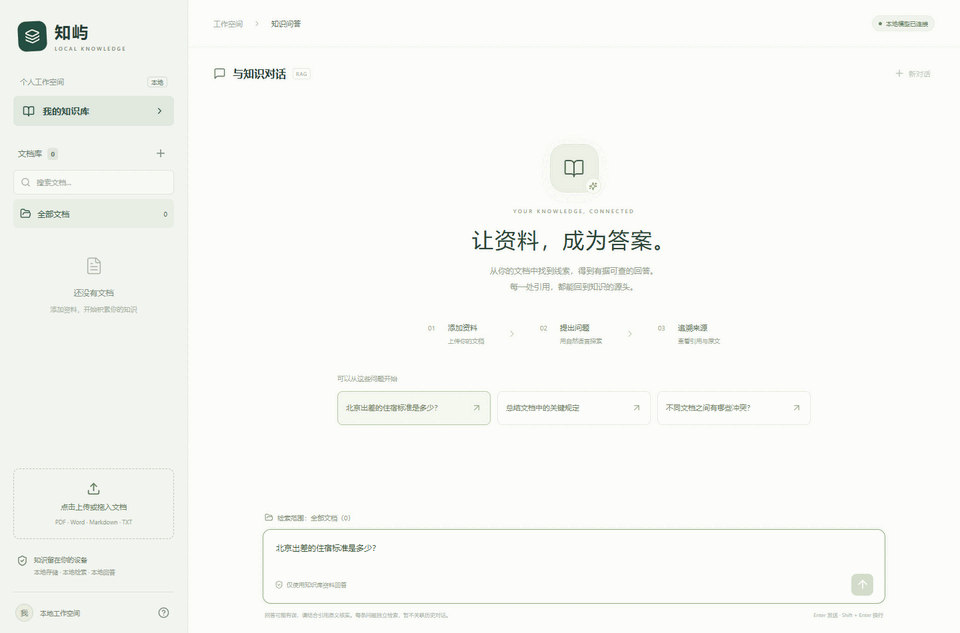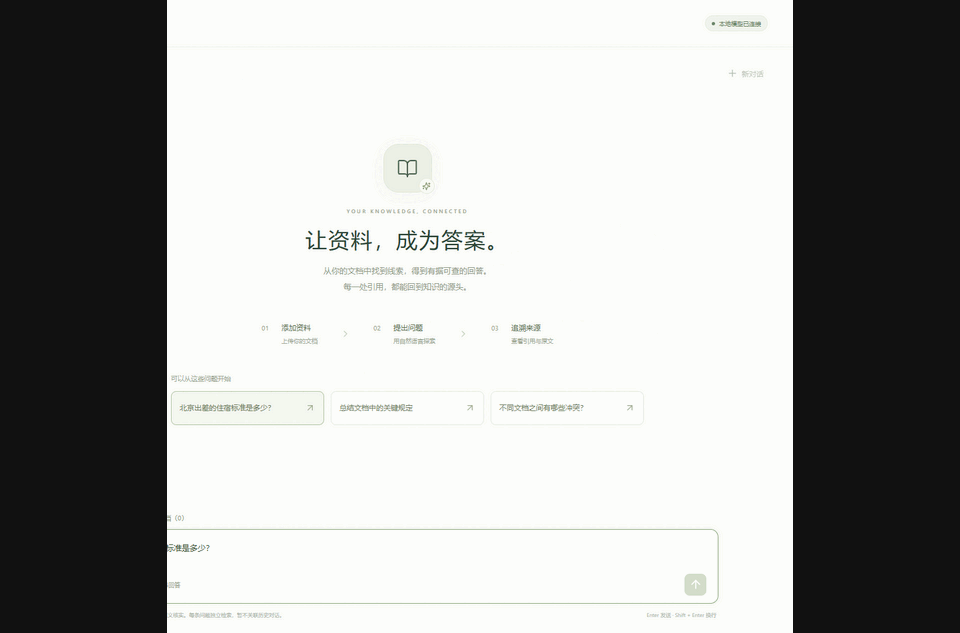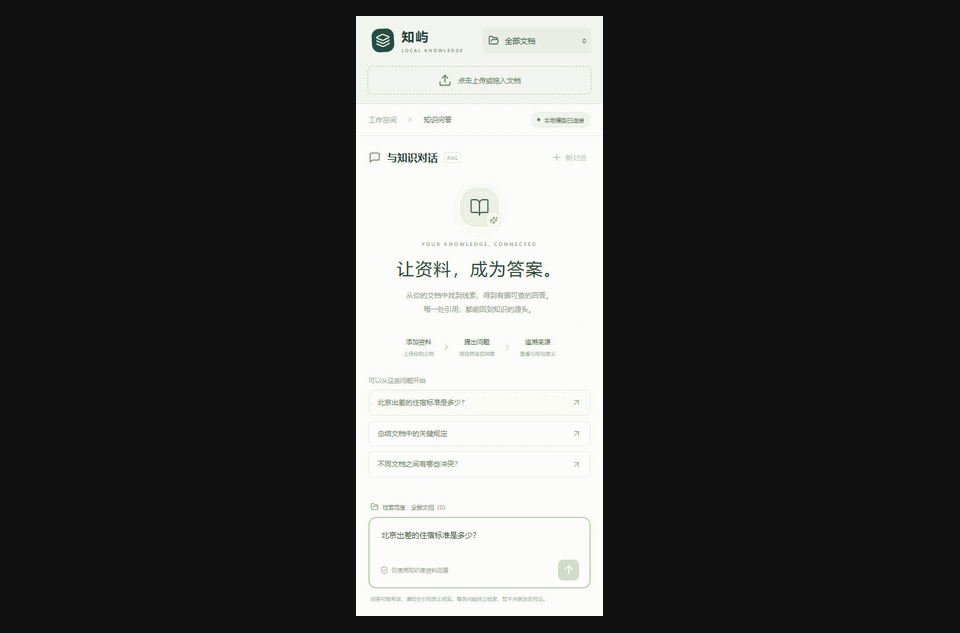
Local-first RAG knowledge base with clickable source citations, BGE-M3 reranking, Qdrant, Ollama and React. Runs on consumer GPUs.
TC Mini: private on-device AI that runs in your phone or PC browser (WebGPU) or Ollama/LM Studio. Abliterated Qwen3 4B/1.7B/0.6B, signed + hash-verified downloads, no server, no telemetry, works offline.
A private, remote AI chat experience that runs on your own machine, using local models.