BentoML
The easiest way to serve AI apps and models - Build Model Inference APIs, Job queues, LLM apps, Multi-model pipelines, and more!
- 8.9k
- Python
- Apache-2.0
- 6 d ago
The easiest way to serve AI apps and models - Build Model Inference APIs, Job queues, LLM apps, Multi-model pipelines, and more!
Extension for Scikit-learn is a seamless way to speed up your Scikit-learn application
Repo for vLLM Hook, an vLLM plug-in for programming internal states of models deployed on vLLM
Production-ready code examples for Telnyx AI Communications Infrastructure — Voice AI, SMS, SIP, and IoT APIs
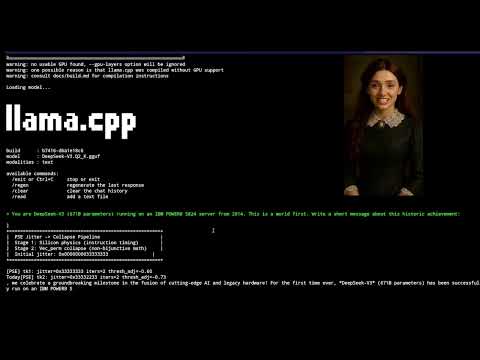
LLM infrastructure cost reduction via NUMA-aware weight banking: 147 t/s (8.8x stock llama.cpp) on refurbished enterprise POWER8. Self-hosted inference, no cloud APIs. Part of the Proof of Physical AI stack.
llama.cpp optimizations for IBM POWER8: vec_perm non-bijunctive collapse, PSE hardware entropy, DCBT prefetch. Sovereign inference. Part of the Proof of Physical AI stack.
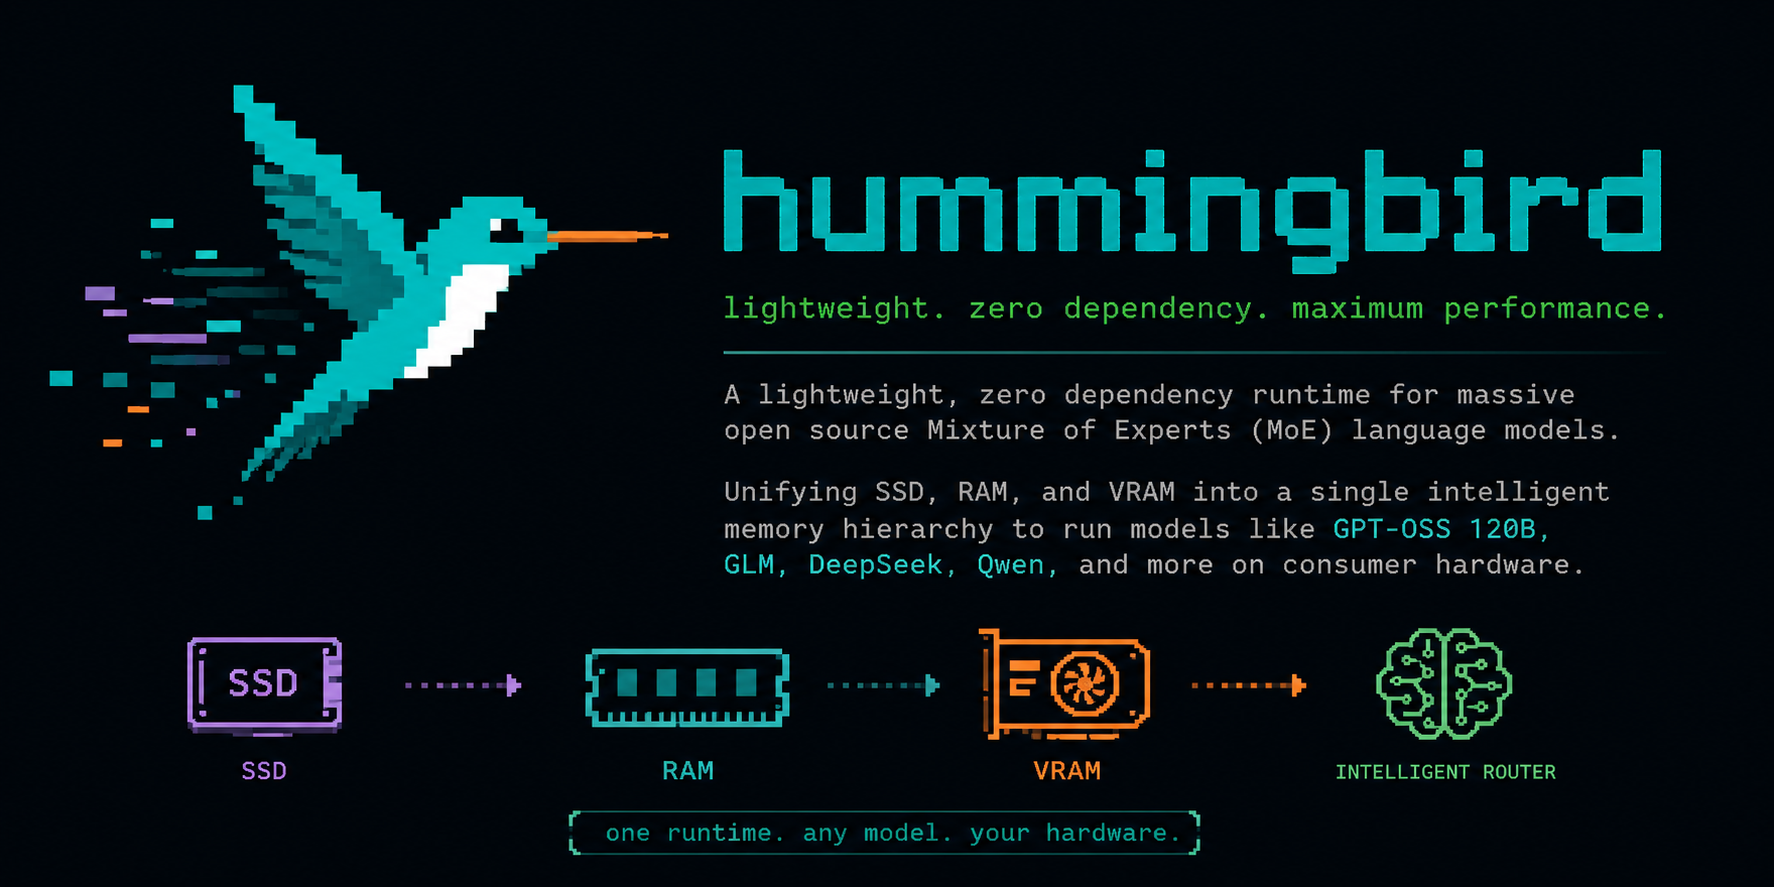
hummingbird is a lightweight, zero dependency runtime for massive open source Mixture of Experts (MoE) language models. It unifies SSD, RAM, and VRAM into a single intelligent memory hierarchy, enabling inference of models like GPT-OSS 120B, GLM, DeepSeek, Qwen, and more on consumer hardware
Windows-first OpenAI-compatible local LLM server powered by OpenVINO GenAI for Intel CPU/GPU/NPU, with chat UI, model conversion, and setup scripts.
一套功能完整、轻量稳定的 ComfyUI 实用节点集。初衷是为了平替一些断更插件的功能,会持续更新一些新开发的节点插件。有好的创意可以发Issues,我会力所能及想办法做出来。全中文界面,原生控件,不依赖第三方库。
High-performance, AI-native server built from scratch in C + hand-written Assembly (SSE2/AVX2/AVX-512). Supports 10 AI providers — OpenAI, Groq, Anthropic Claude, Google Gemini, DeepSeek, Moonshot/Kimi, Zhipu GLM, Perplexity, Mistral AI, and local models via Ollama — all in one binary.
Can my GPU run this? Pick a GPU to get 3 fitting AI models, quantization, VRAM, speed ranges, and run commands. 한국어·English.
Unity TTS plugin: Piper neural synthesis + pure C# G2P (6 languages: ja/en/zh/es/fr/pt) + Unity Inference Engine. Windows/Mac/Linux/Android/iOS/WebGL ready. High-quality voices for games & apps.
Lynn 原生 LLM 推理引擎 · W4A8/NVFP4 量化 · 自写 CUDA/Triton kernel · MoE · 投机解码 | Lynn-native LLM inference engine for NVIDIA Blackwell
⚡ 100% offline, zero-cost drop-in alternative to TypeSafe Jev System One decision models in Rust (<18ms on CPU)
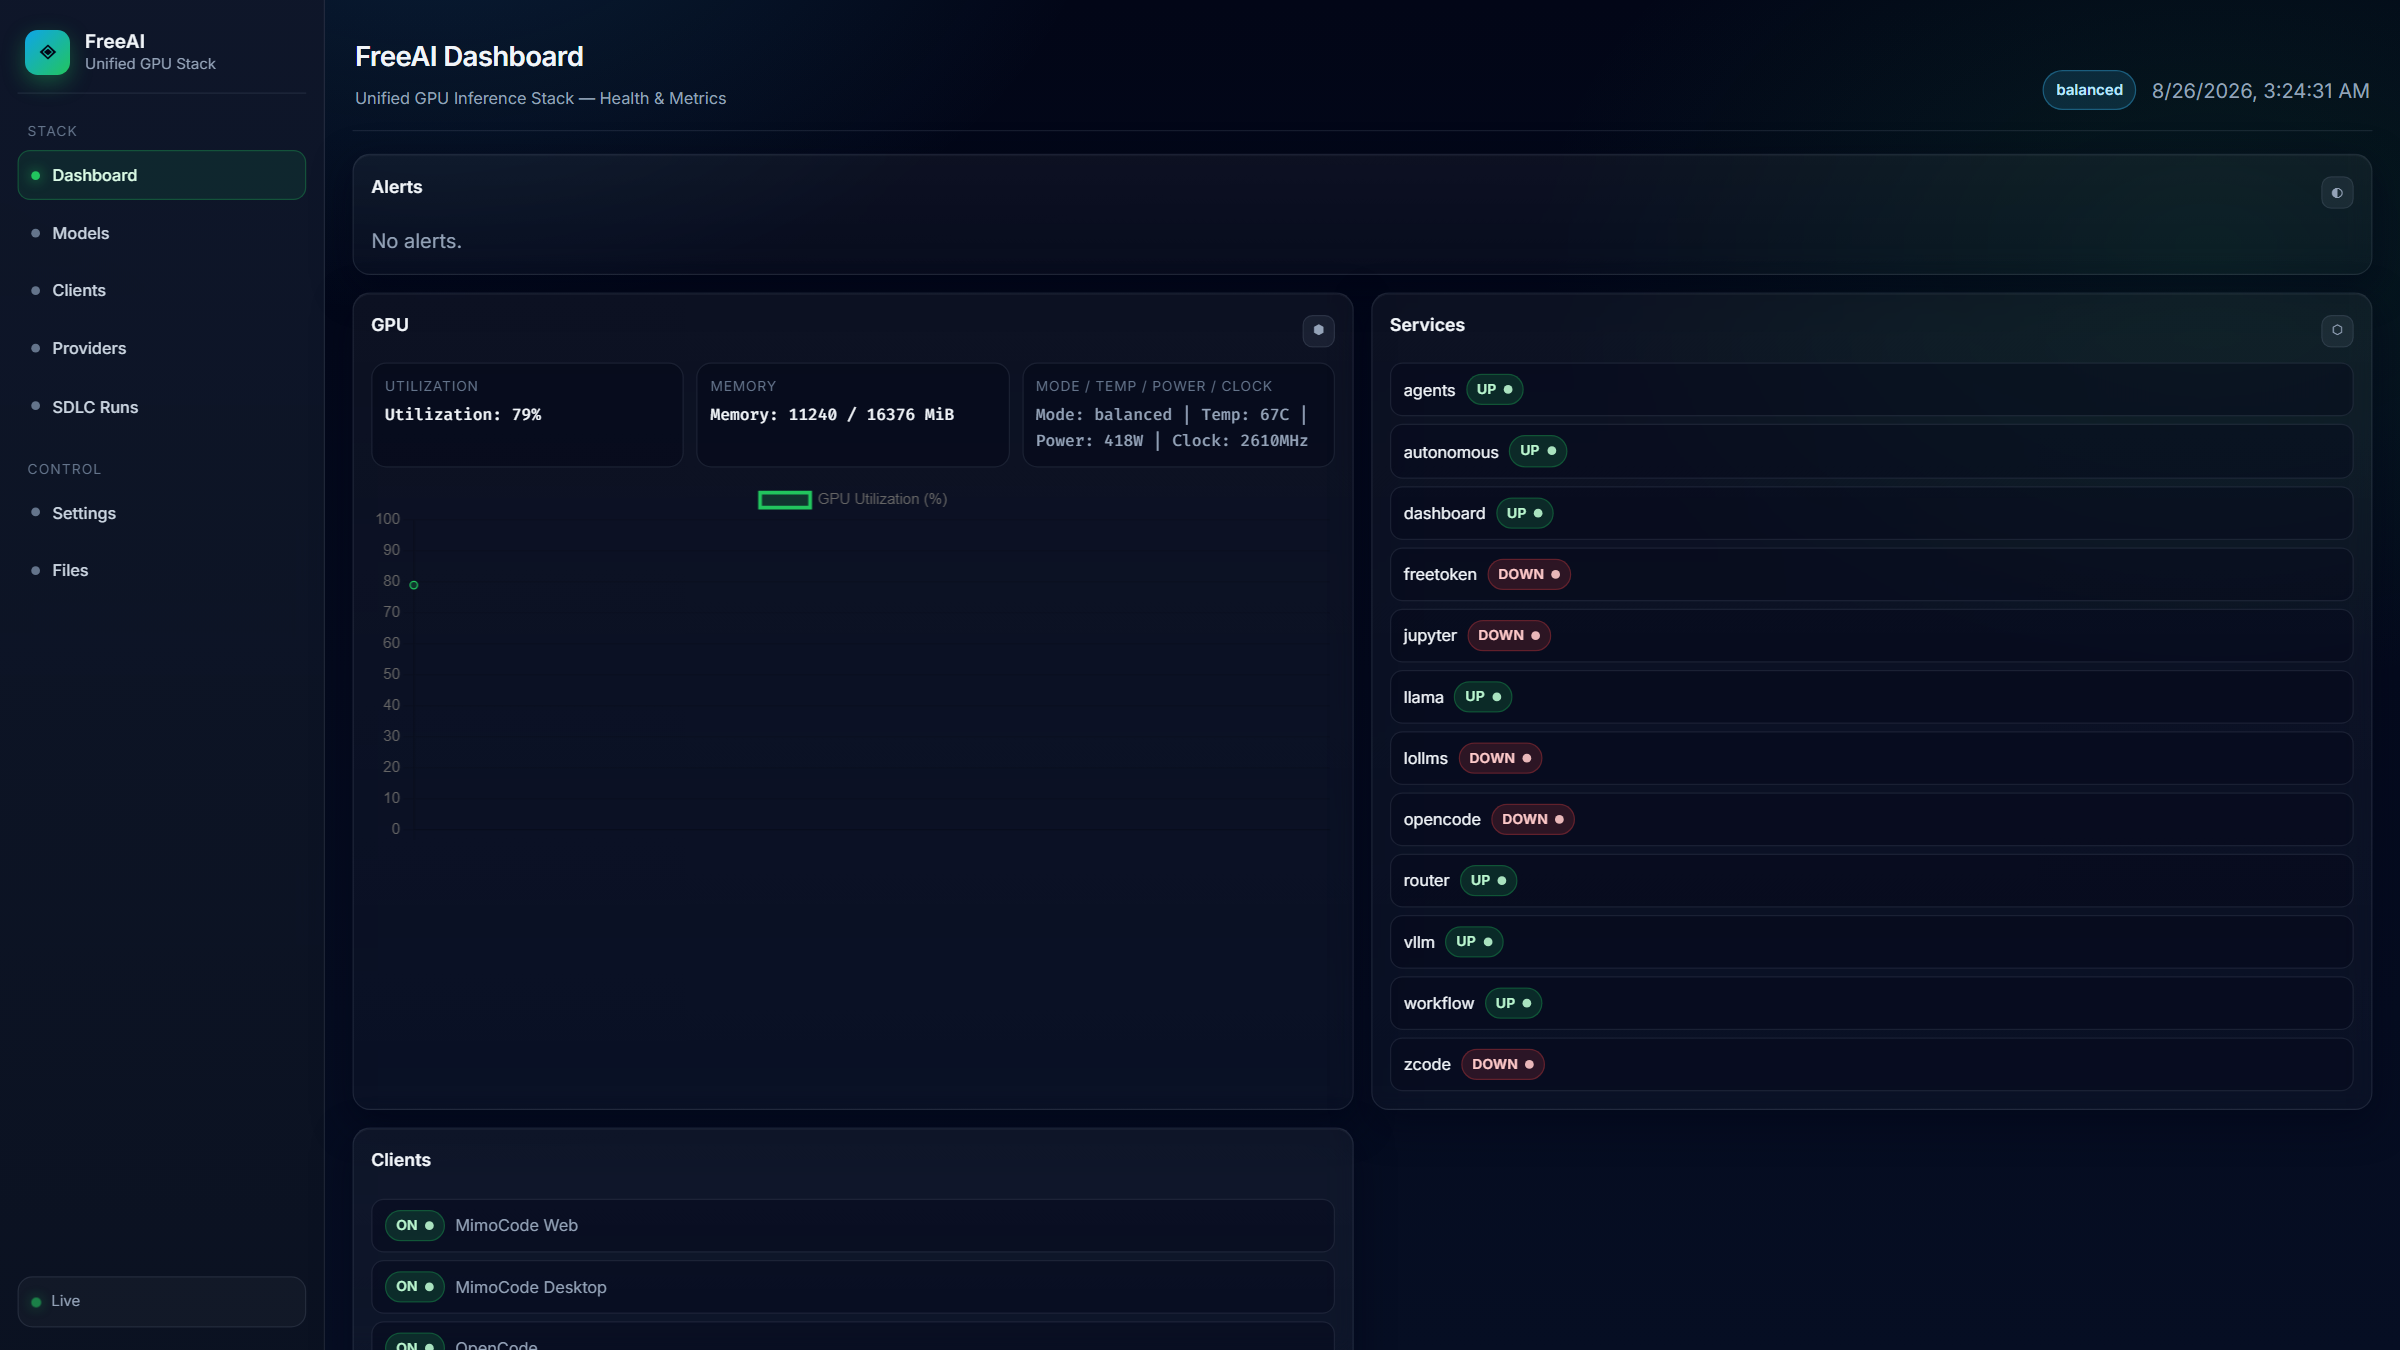
FreeAI: Unified AI Inference Workstation — local LLMs, autonomous agents, full SDLC automation, security tools, and multi-provider routing. One self-hosted stack.
Apache 2.0-licensed open source operations stack for private AI inference with open models. Run LLMs (7B-70B) locally with vLLM, OpenAI-compatible API, web dashboard, chat UI, admin panel, and hardware monitoring.
Open-source AI inference server powered by Llamatik. Run LLMs locally, expose inference APIs, and share computing power across a decentralized network.
Durable, resumable OpenAI-compatible inference streams that survive disconnects, backend loss, and Kubernetes rolling updates.
A practical 12-day roadmap for engineers who want to move from building AI features to designing production-ready AI systems.
Terminal CLI for ZeroGPU — an ultra-fast, compute-efficient inference provider for apps and agents. Purpose-built small and nano models on an edge network, with zero GPU infrastructure, serverless, and auto-scaling built in.
Multi-level AI inference with semantic zoom: routes queries through deterministic, tiny-model and LLM tiers by complexity for cost-aware inference
Making Generative AI Faster — a measured optimization course (Qwen-Image-2.1 on a single Radeon PRO W7900): syllabus, 8 modules, runnable lab, full evidence (baseline 55.2s → BEST 9.02s = 6.12×)
GPU benchmark suite for AI inference workloads. Test throughput, latency, and power efficiency across NVIDIA, AMD, and Apple Silicon. By Petronella Technology Group.
Pluggable AI inference library — LLM backends, embeddings, vision, TTS