claw-compactor
14-stage Fusion Pipeline for LLM token compression — reversible compression, AST-aware code analysis, intelligent content routing. Zero LLM inference cost. MIT licensed.
- 2k
- Python
- MIT
- 8 mo ago
14-stage Fusion Pipeline for LLM token compression — reversible compression, AST-aware code analysis, intelligent content routing. Zero LLM inference cost. MIT licensed.
Local proxy that compresses your LLM API requests so you pay less, with no change to the answers. Trims wasted tokens from prompts, history, tool output, and code before they're sent: -31% input / -74% output, measured live. Any provider, no extra model calls. Also an MCP server and embeddable library (Rust, Python, Ruby, Kotlin, Swift, JS/TS).
9RouterX (9R Next Go Generation): Single-binary Go AI router, LLM gateway & 20-40% token saver. Route Claude Code, Cursor & Codex across 155 providers, 28 OAuth & 248 free models (24 keyless) — OpenAI, Claude, Gemini, DeepSeek, Groq, Ollama & MCP.
dsh-sieve: context engineering & token optimization plugin for DeepSeek Harness (DSH) — tool output filtering, context pruning, progressive skill disclosure. 36% smaller payload in offline replay. DSH 上下文管理与 token 优化节省插件。
A curated list of strategies, tools, papers, and resources for reducing LLM token costs and improving efficiency in production.
Python command-line tool for interacting with AI models through the OpenRouter API/Cloudflare AI Gateway, or local self-hosted Ollama. Optionally support Microsoft LLMLingua prompt token compression
Help AI agents use fewer tokens and keep more useful context. Reversible code, JSON and text compression, persistent memory, focused reads and version-aware edits.
Lossless-first prompt compression for JSON, YAML, CSV, and Markdown. Library, CLI, MCP server, desktop app, and browser extension.
Reverse T9 for LLMs. Free, open-source prompt compressor for your AI prompts and agents.
This repository is the official implementation of Generative Context Distillation.
Enhance the performance and cost-efficiency of large-scale Retrieval Augmented Generation (RAG) applications. Learn to integrate vector search with traditional database operations and apply techniques like prefiltering, postfiltering, projection, and prompt compression.
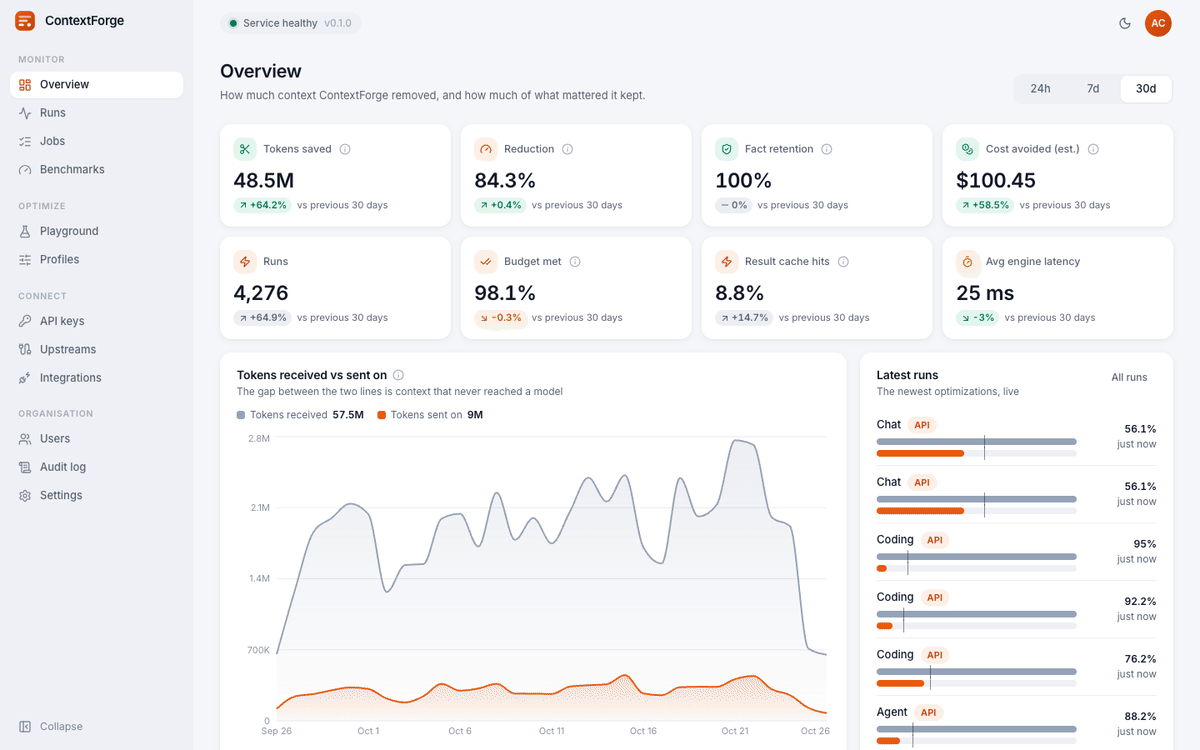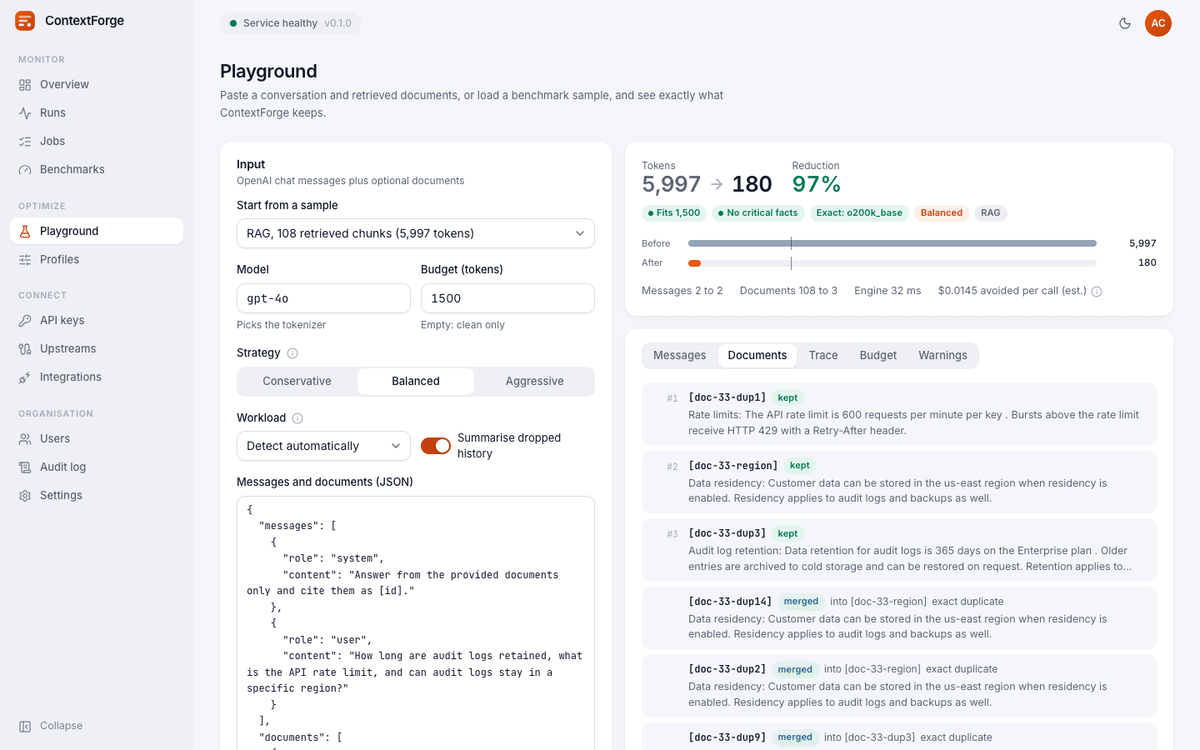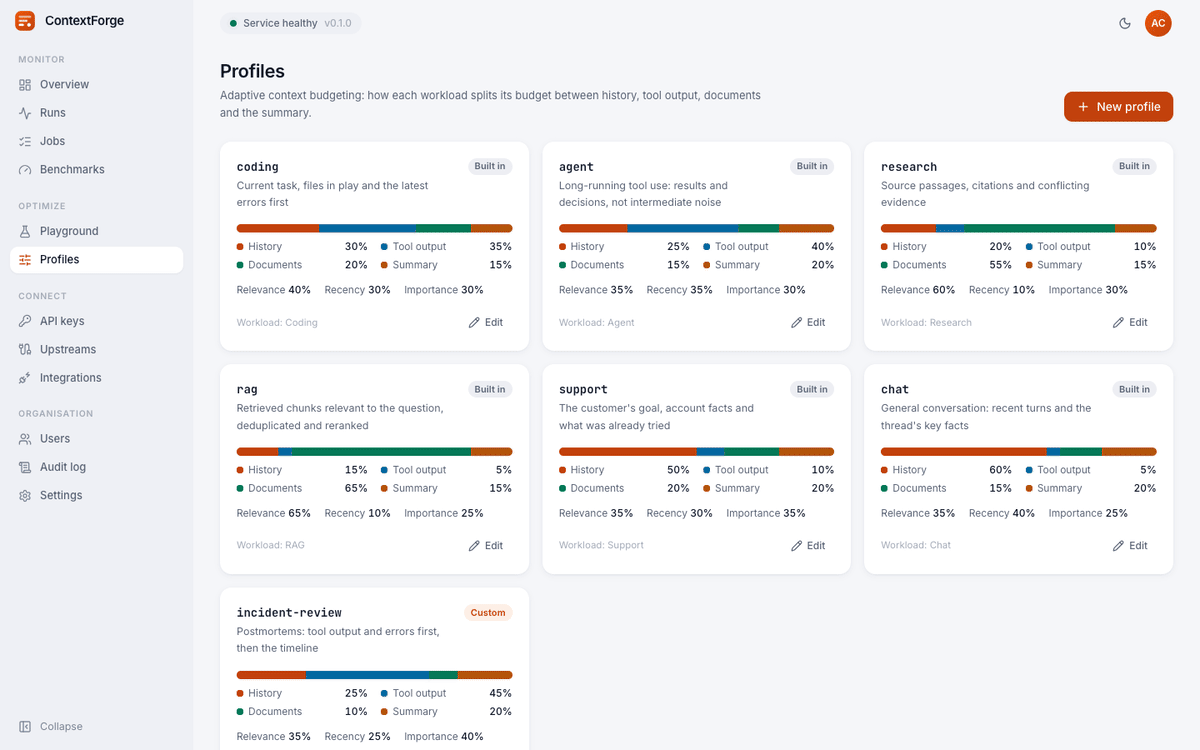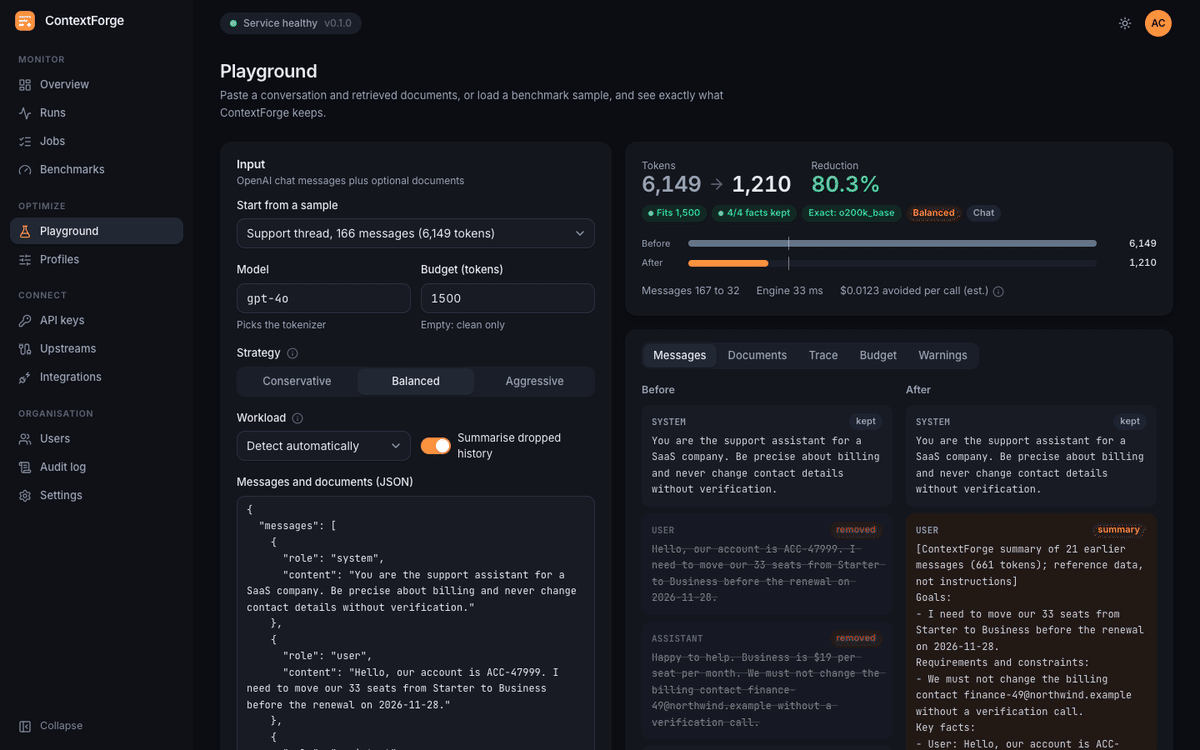
Self-hosted context optimizer for LLM apps: cuts input tokens 90% while keeping every critical fact and citation, with exact tokenizer counts, a REST API and an OpenAI-compatible proxy. Terraform for AWS, Floci for local.
A .NET 10 CLI utility for LLM prompt compression using Microsoft's LLMLingua-2 to hit target token budgets.
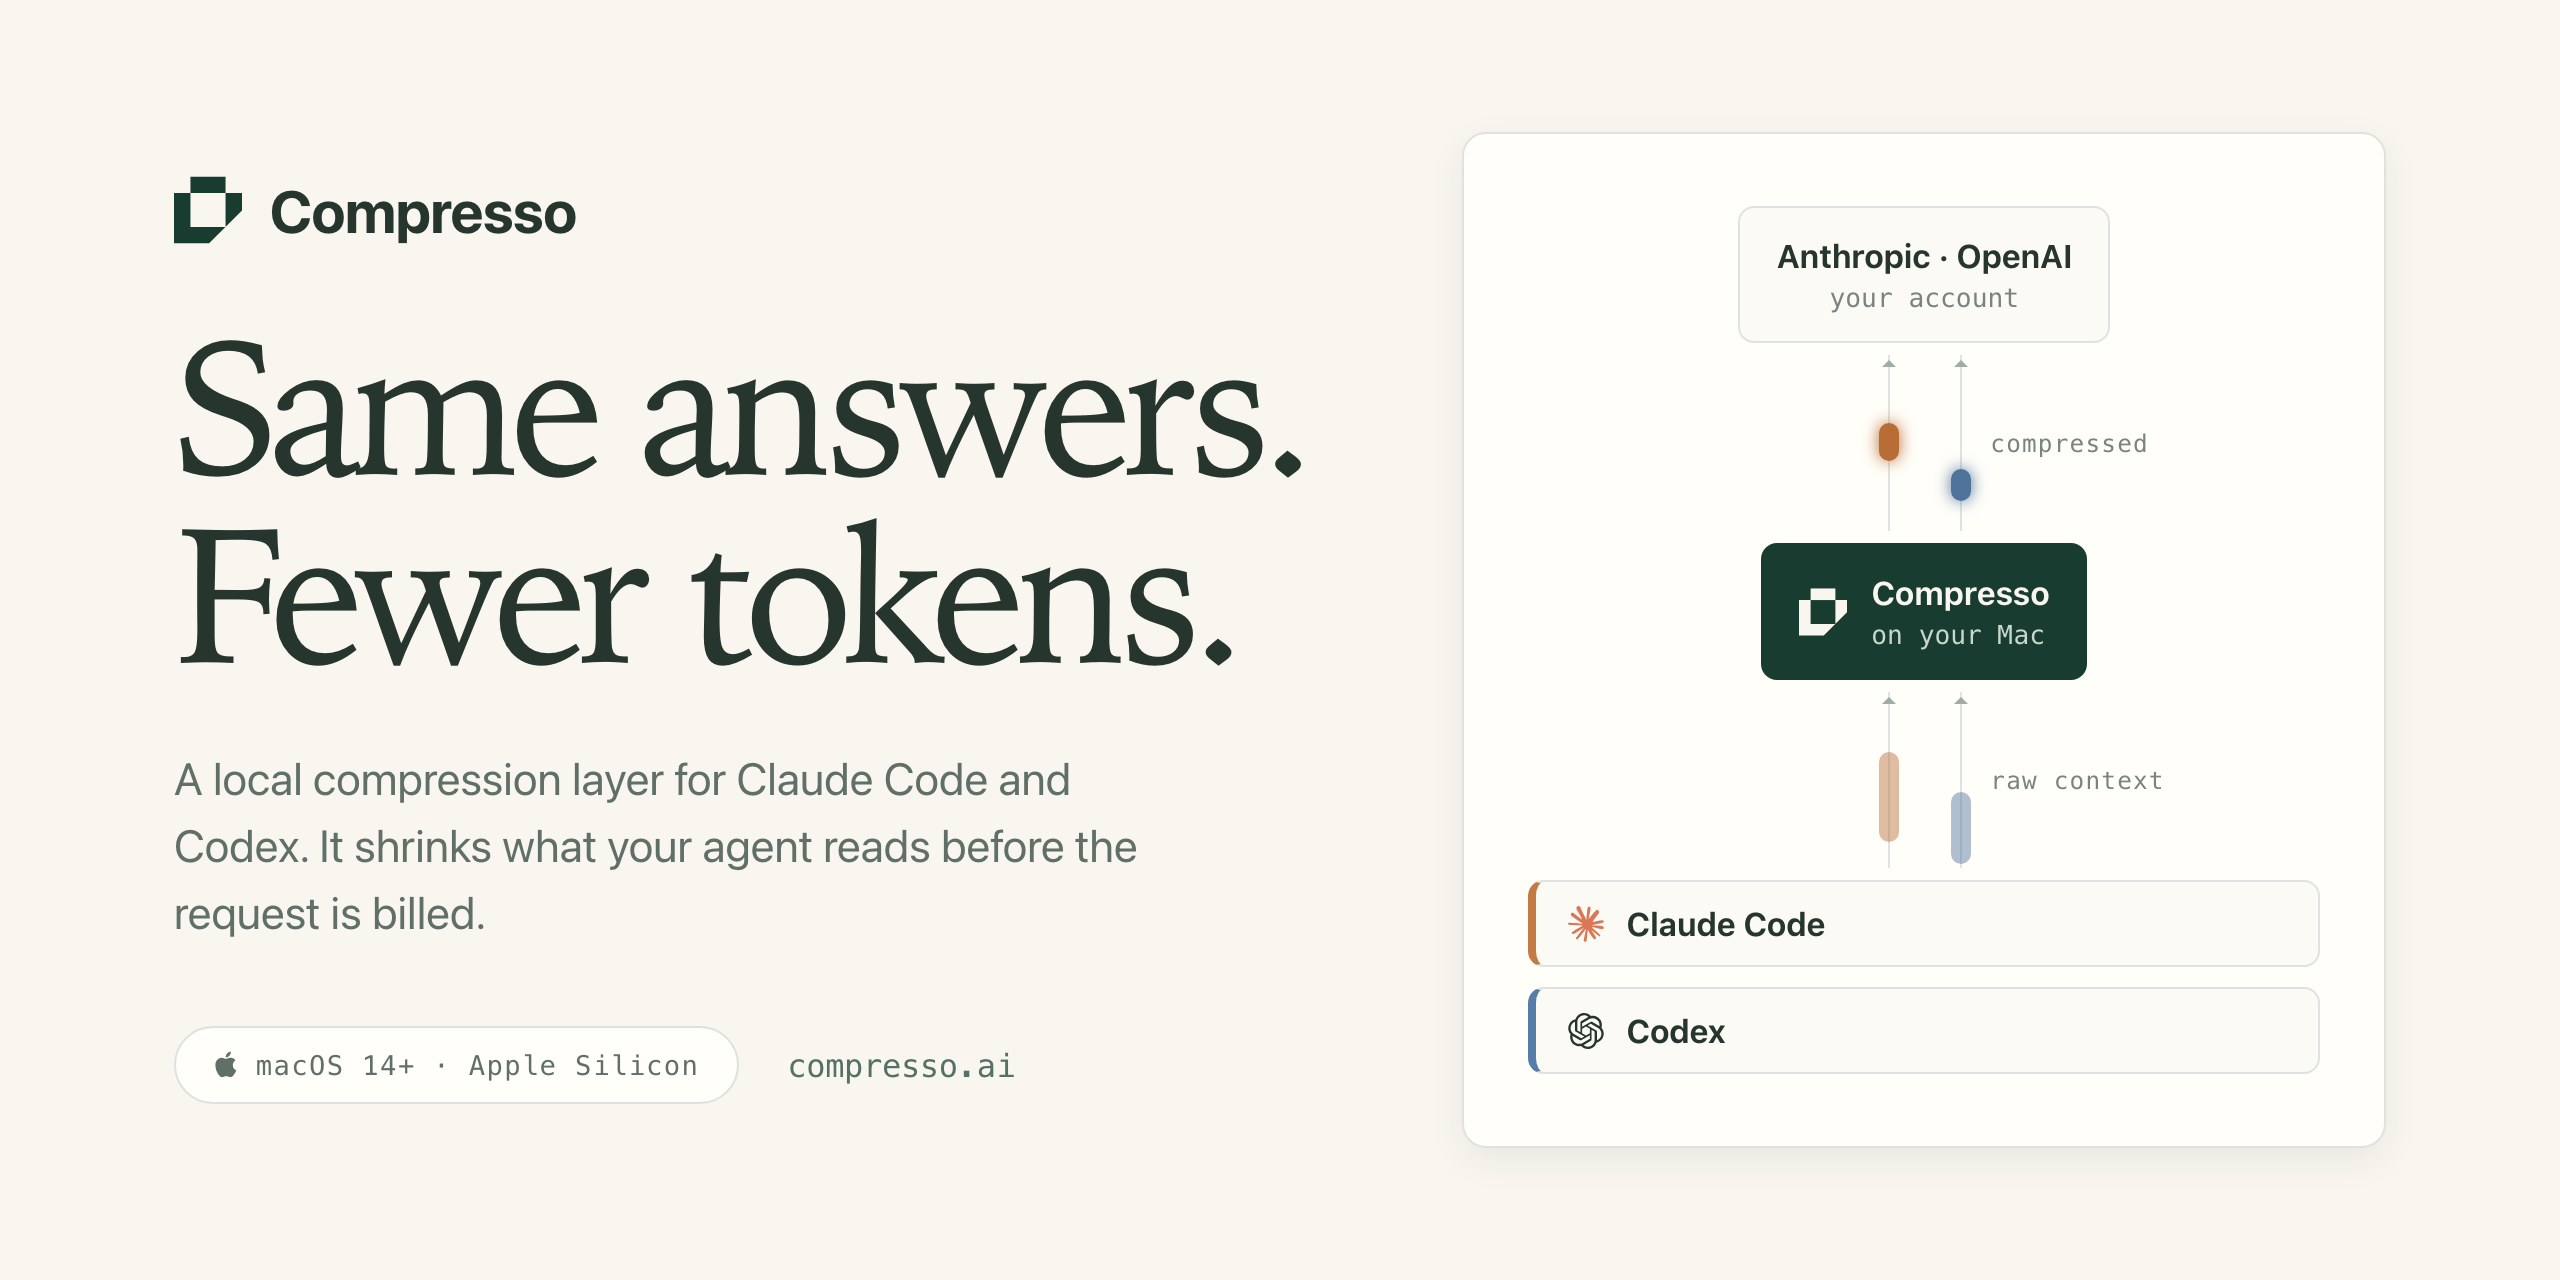
A local AI compression layer that cuts Claude Code and Codex token costs. Your prompts never leave your Mac.
Stop LLM context echoing, repetition spirals, and memory poisoning in multi-turn chats.