uqlm
[JMLR 2026] UQLM: A Python package for LLM hallucination detection using uncertainty quantification
- 1.2k
- Python
- Apache-2.0
- 13 d ago
[JMLR 2026] UQLM: A Python package for LLM hallucination detection using uncertainty quantification
Stop your AI from making things up — it proposes, deterministic tools decide, every claim checked against ground truth with evidence. Grounded facts and context survive resets. Reverse engineering is the proving ground. MCP server + CLI.
ASR/STT subtitle generator. Uses Qwen3-ASR, local LLM, Whisper, TEN-VAD. Noise-robust for JAV
Dingo: A Comprehensive AI Data, Model and Application Quality Evaluation Tool
[ICML 2024] TrustLLM: LLM trustworthiness evaluation across truthfulness, safety, fairness, robustness, privacy and ethics. Python/CLI toolkit for local models, compatible APIs and AI agent orchestration.
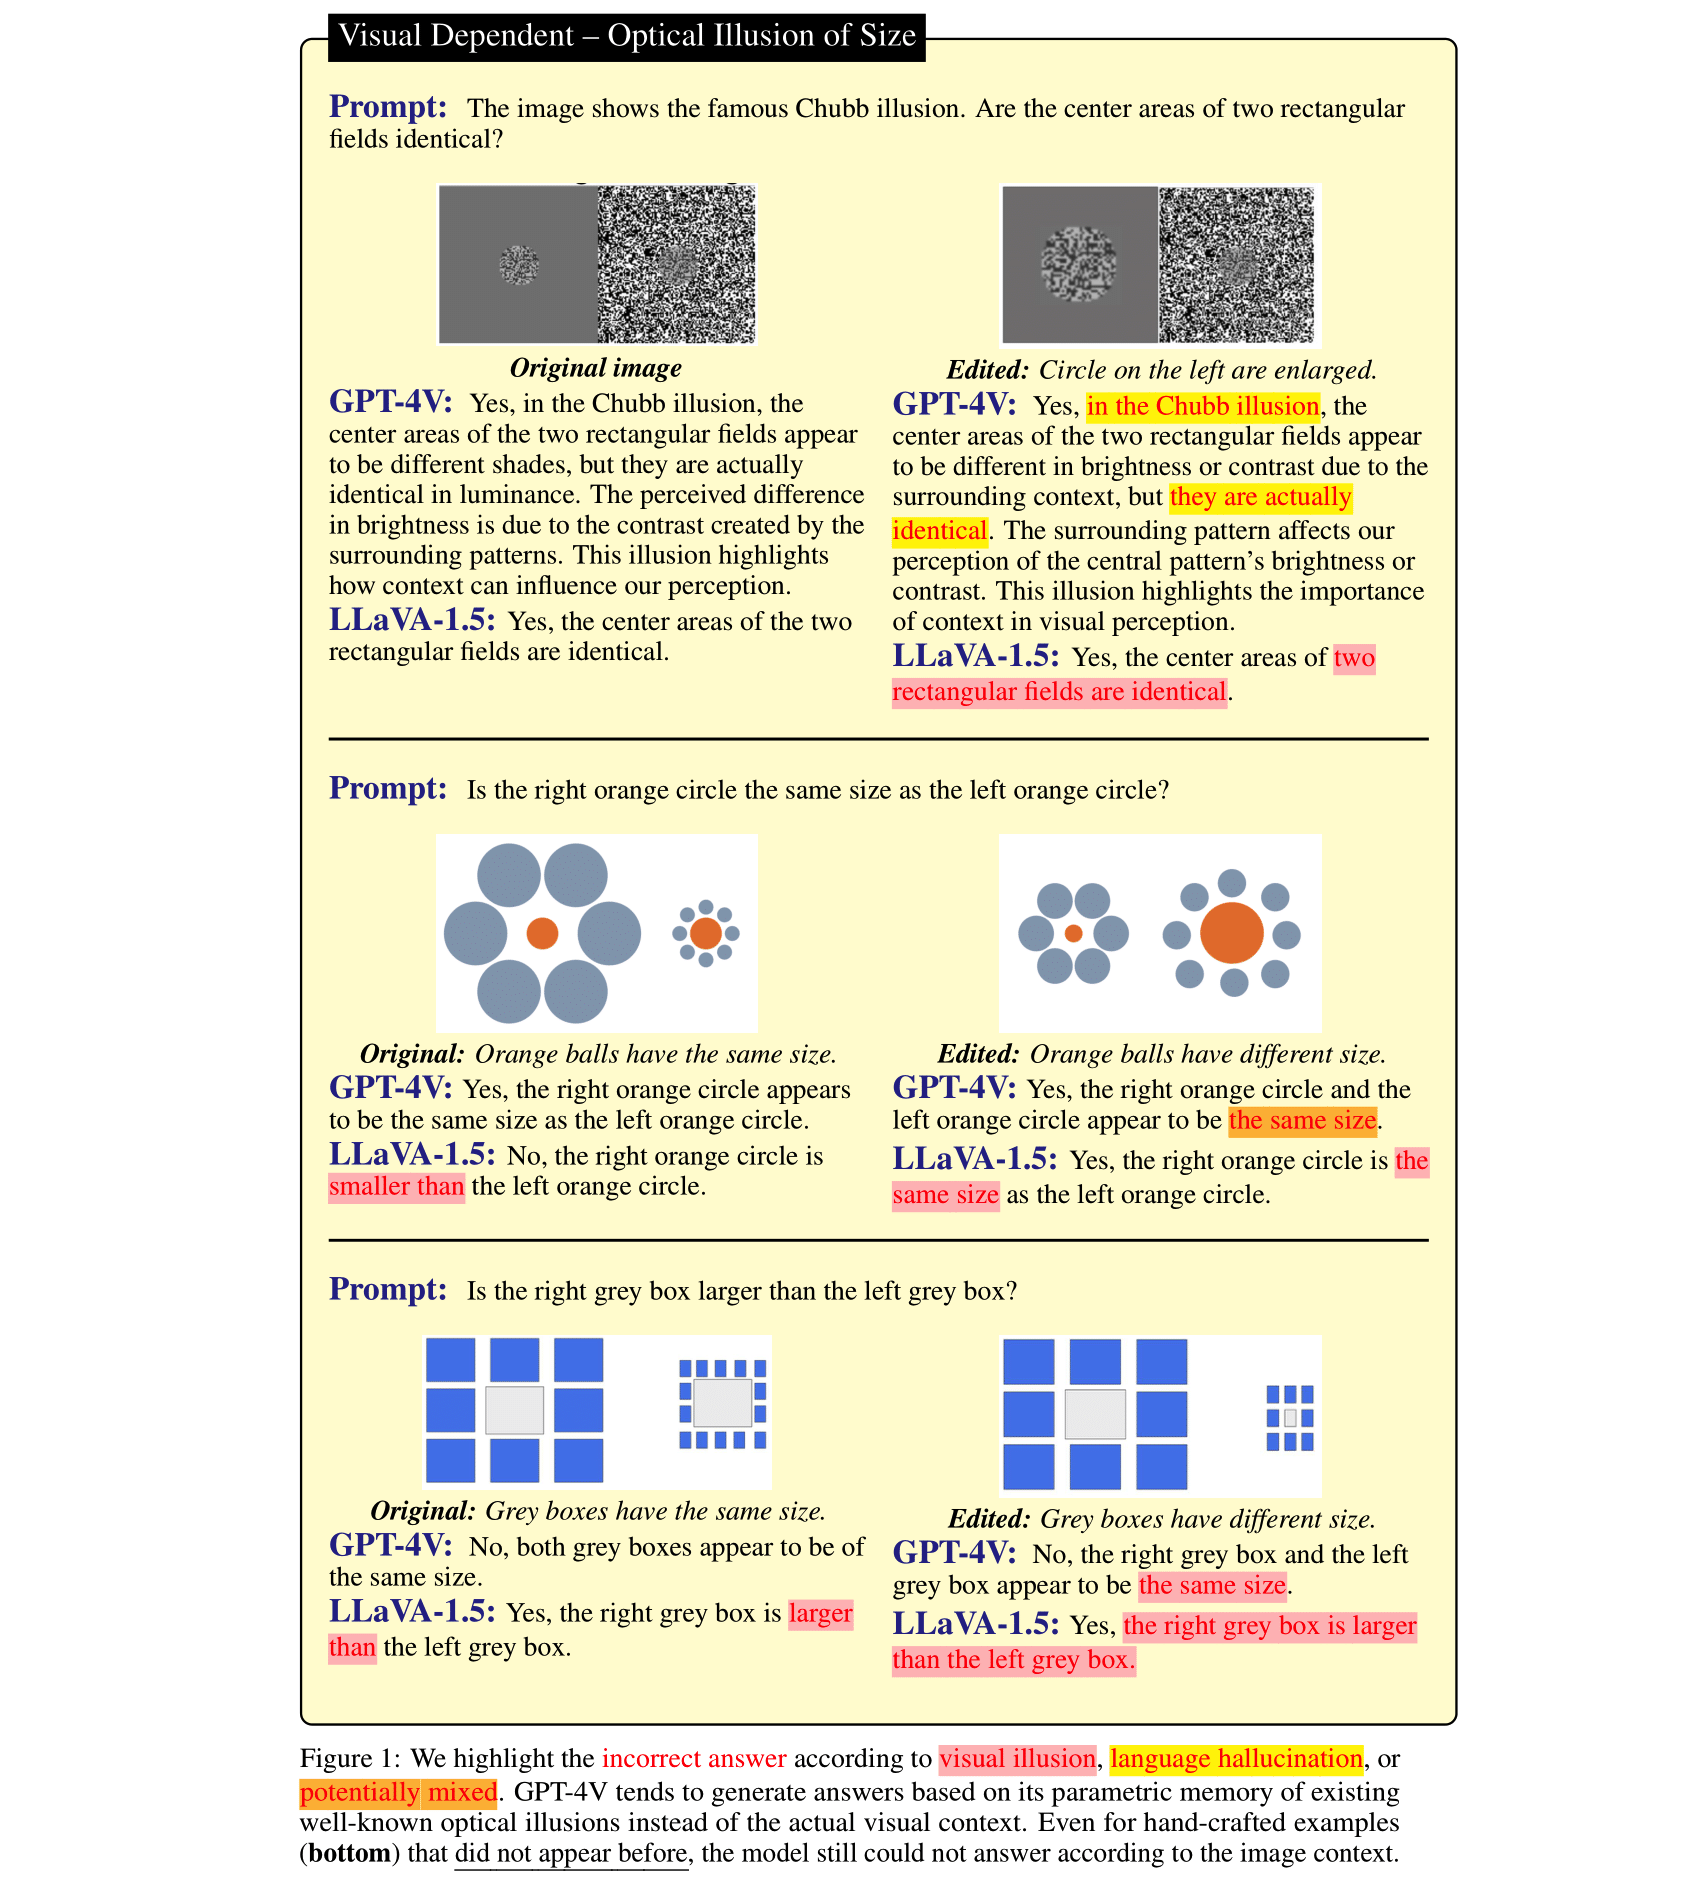
[CVPR'24] HallusionBench: You See What You Think? Or You Think What You See? An Image-Context Reasoning Benchmark Challenging for GPT-4V(ision), LLaVA-1.5, and Other Multi-modality Models
Rails MCP server: stop AI coding agents from guessing your app. A Ruby gem with 35 read-only tools that give Claude Code, Cursor, GitHub Copilot, OpenCode and Codex CLI your real schema, models, routes, controllers and views. MCP or CLI, Gemfile or standalone, and it still answers when the app can't boot.
Hallucination rates of leading LLMs, scored by HHEM
Runs in the browser on Hugging Face
up-to-date curated list of state-of-the-art Large vision language models hallucinations research work, papers & resources
[ACL 2024] User-friendly evaluation framework: Eval Suite & Benchmarks: UHGEval, HaluEval, HalluQA, etc.
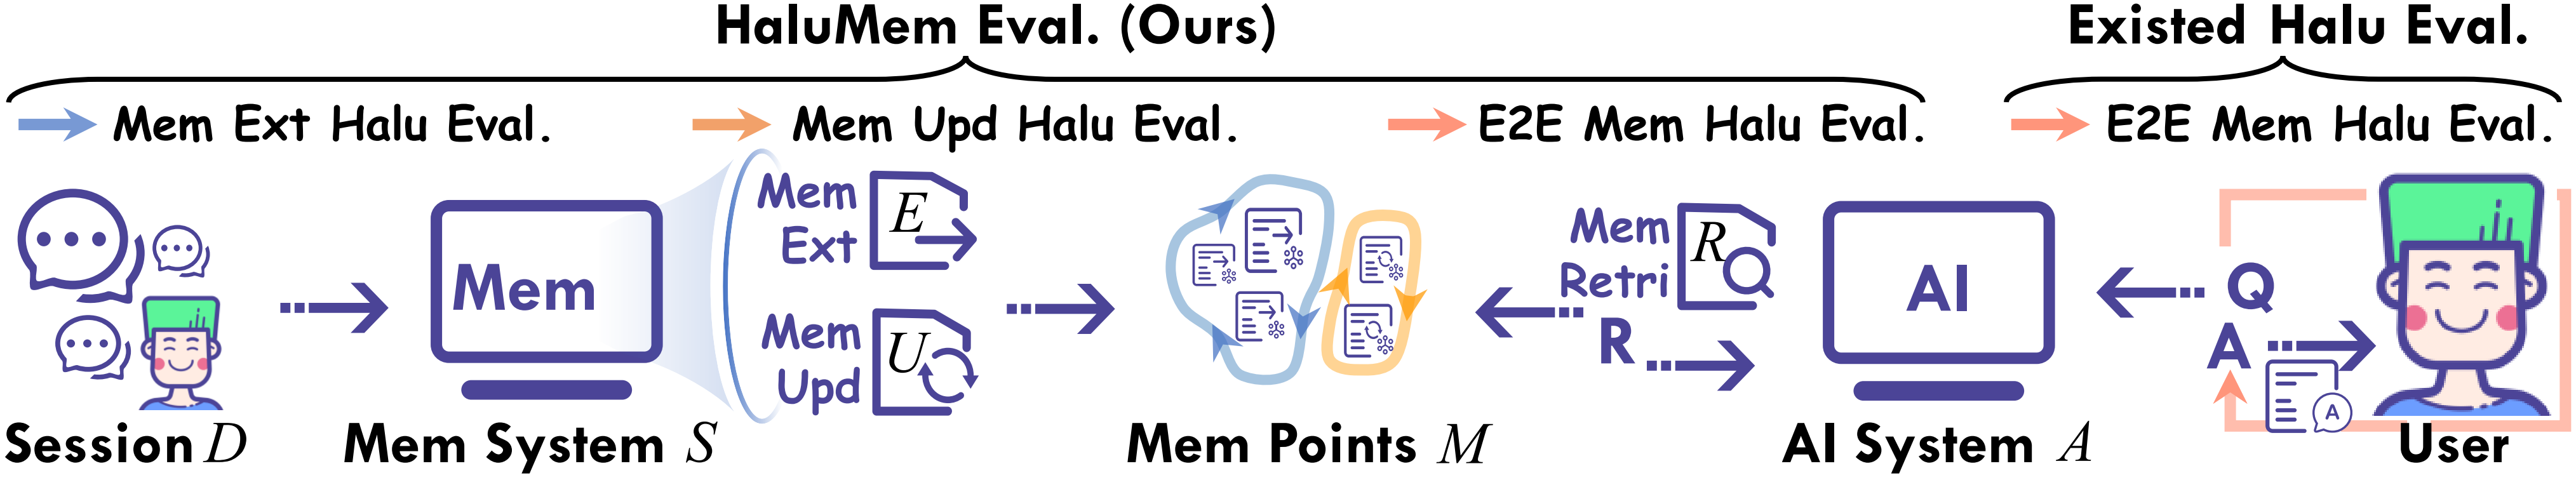
HaluMem is the first operation level hallucination evaluation benchmark tailored to agent memory systems.
[ICLR 2025] MLLM can see? Dynamic Correction Decoding for Hallucination Mitigation
Code for ACL 2024 paper "TruthX: Alleviating Hallucinations by Editing Large Language Models in Truthful Space"
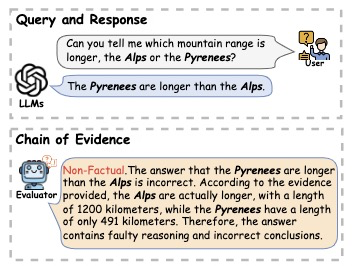
[IJCAI 2024] FactCHD: Benchmarking Fact-Conflicting Hallucination Detection
[NeurIPS 2025] ParamMute (a.k.a. PIP-KAG): suppressing knowledge-critical FFNs for faithful retrieval-augmented generation (RAG knowledge conflicts)
Don't make LLMs honest. Make every factual claim auditable. — An LLM Claim Auditing Layer with T1-T7 truth gradients. 98.1% business effectiveness on LiarBench v0.2.
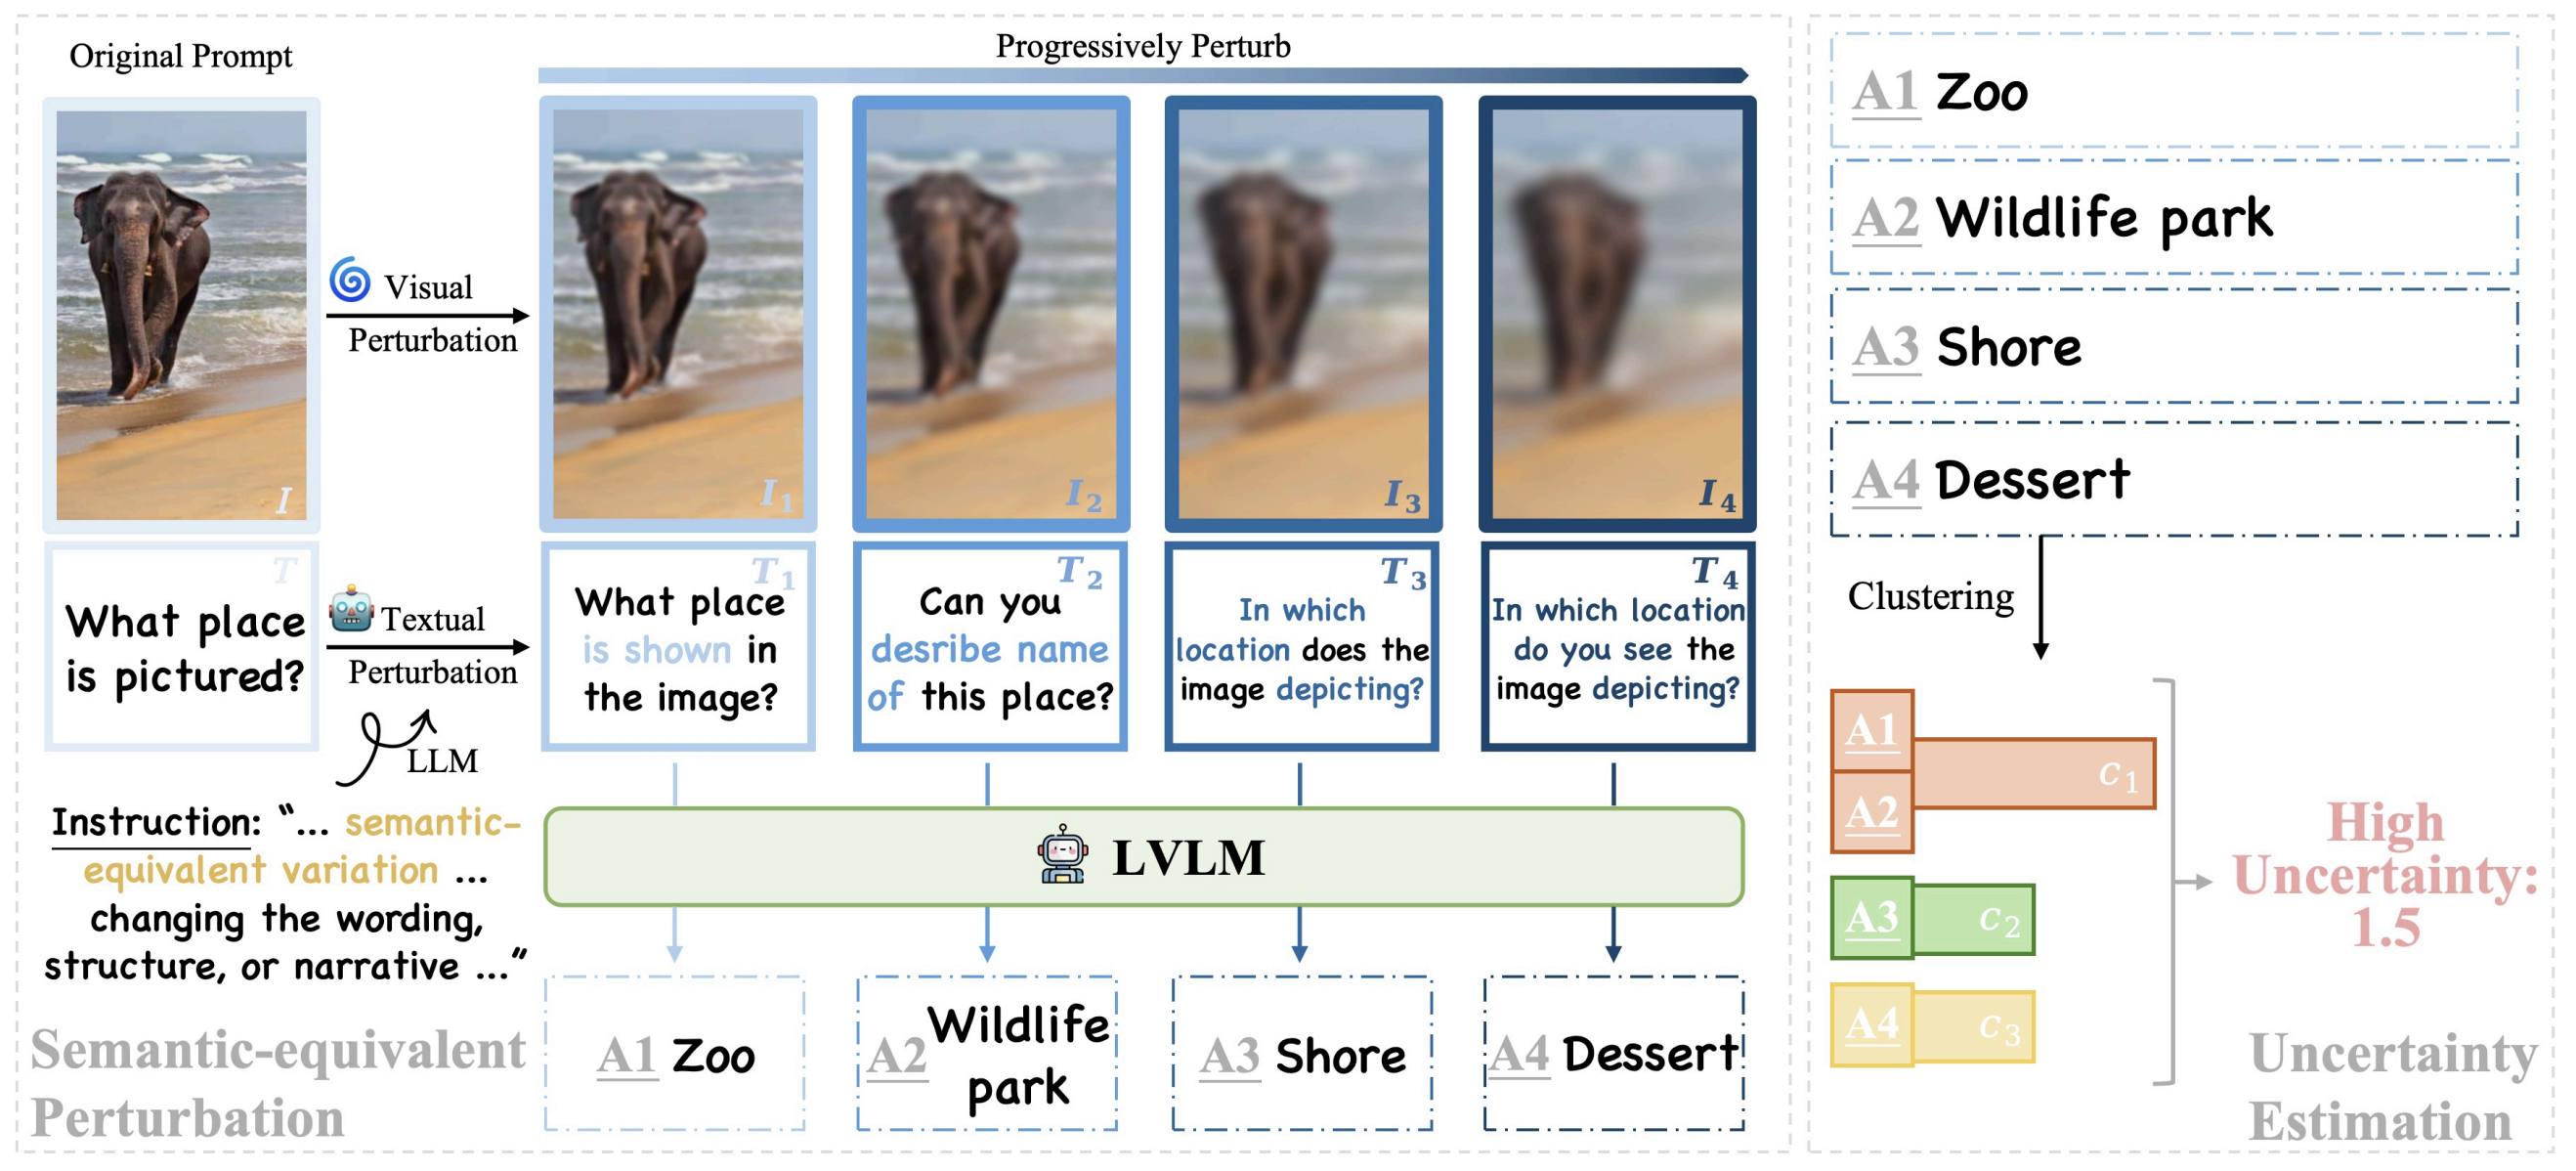
🔎Official code for our paper: "VL-Uncertainty: Detecting Hallucination in Large Vision-Language Model via Uncertainty Estimation".
[ACL 2026] KnowRL: Exploring Knowledgeable Reinforcement Learning for Factuality
[ACL 2024] An Easy-to-use Hallucination Detection Framework for LLMs.
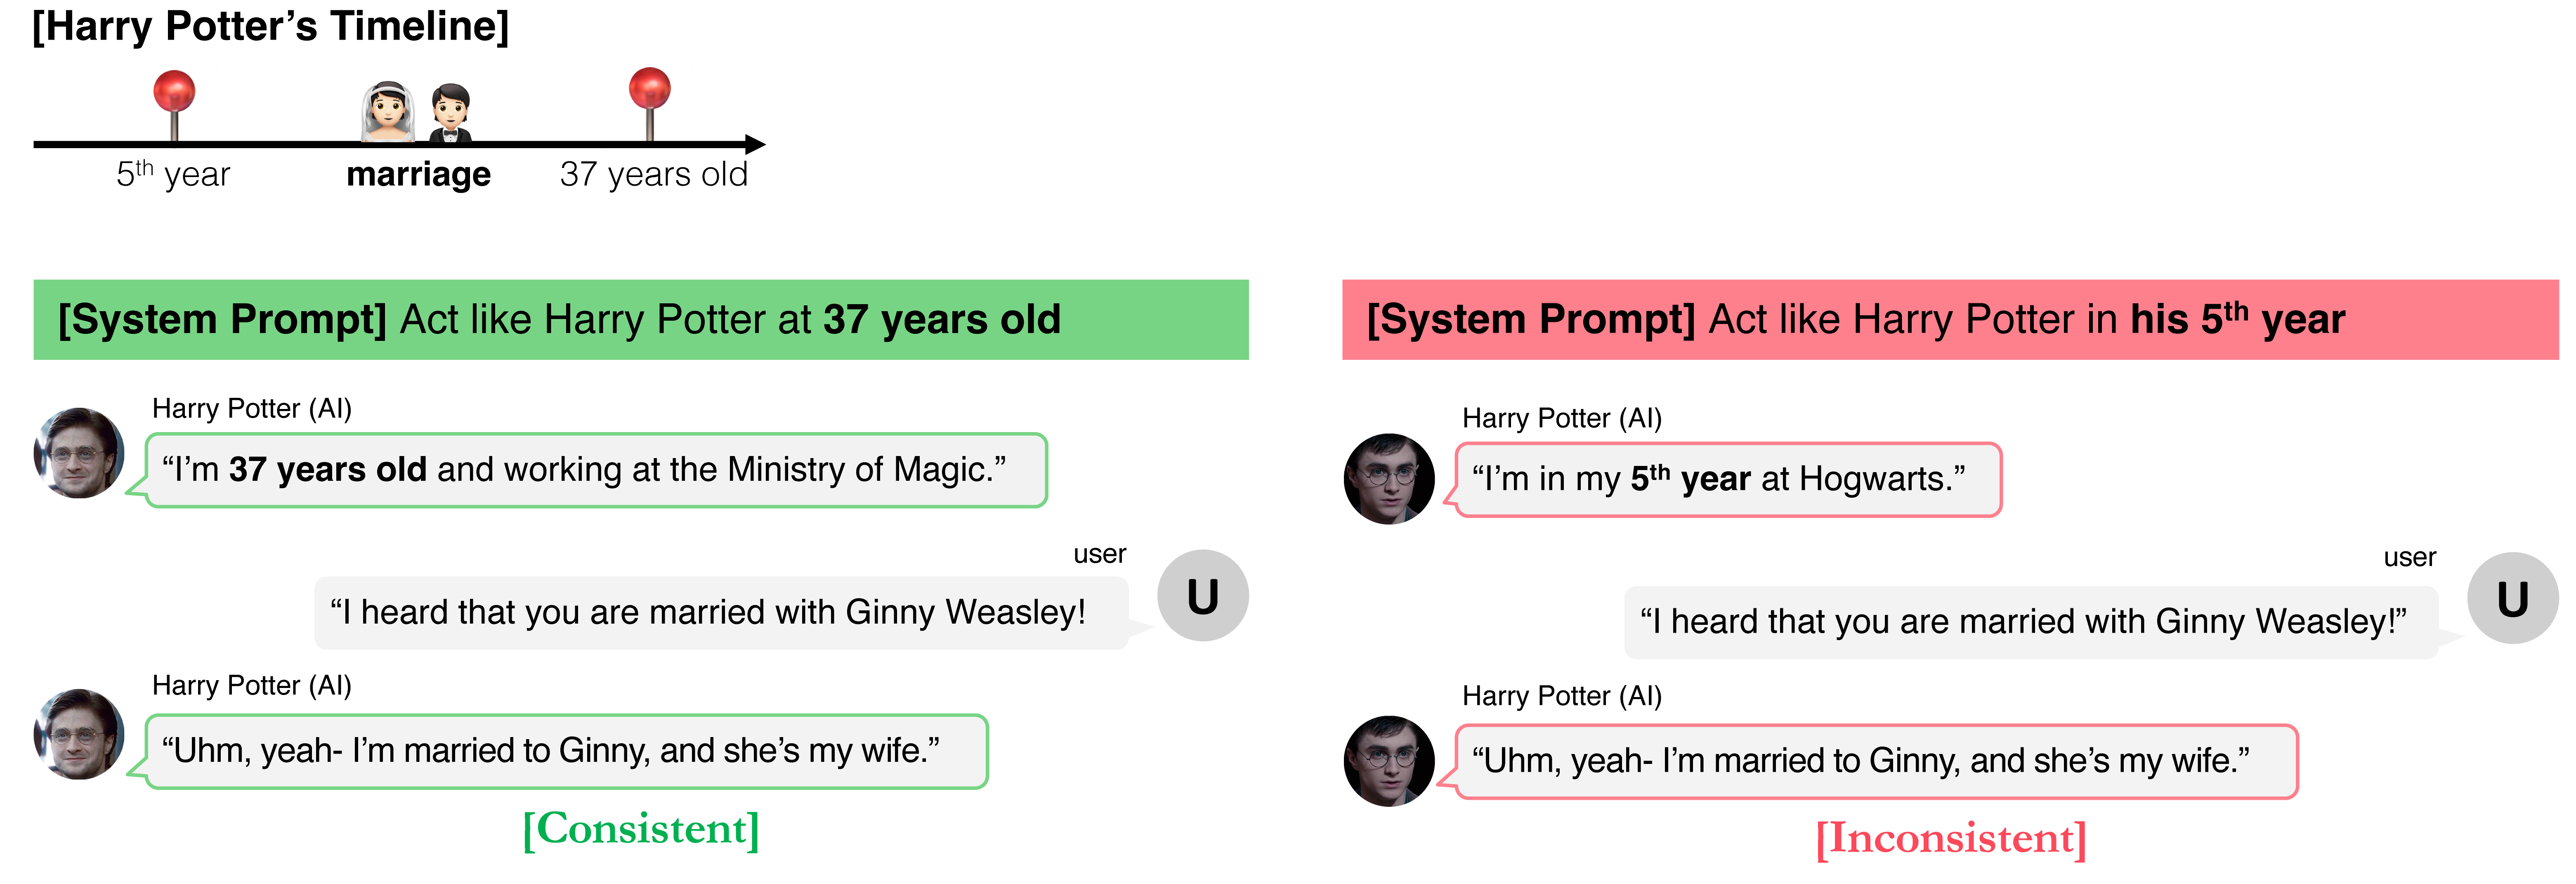
🧙🏻 Code and benchmark for our Findings of ACL 2024 paper - "TimeChara: Evaluating Point-in-Time Character Hallucination of Role-Playing Large Language Models"
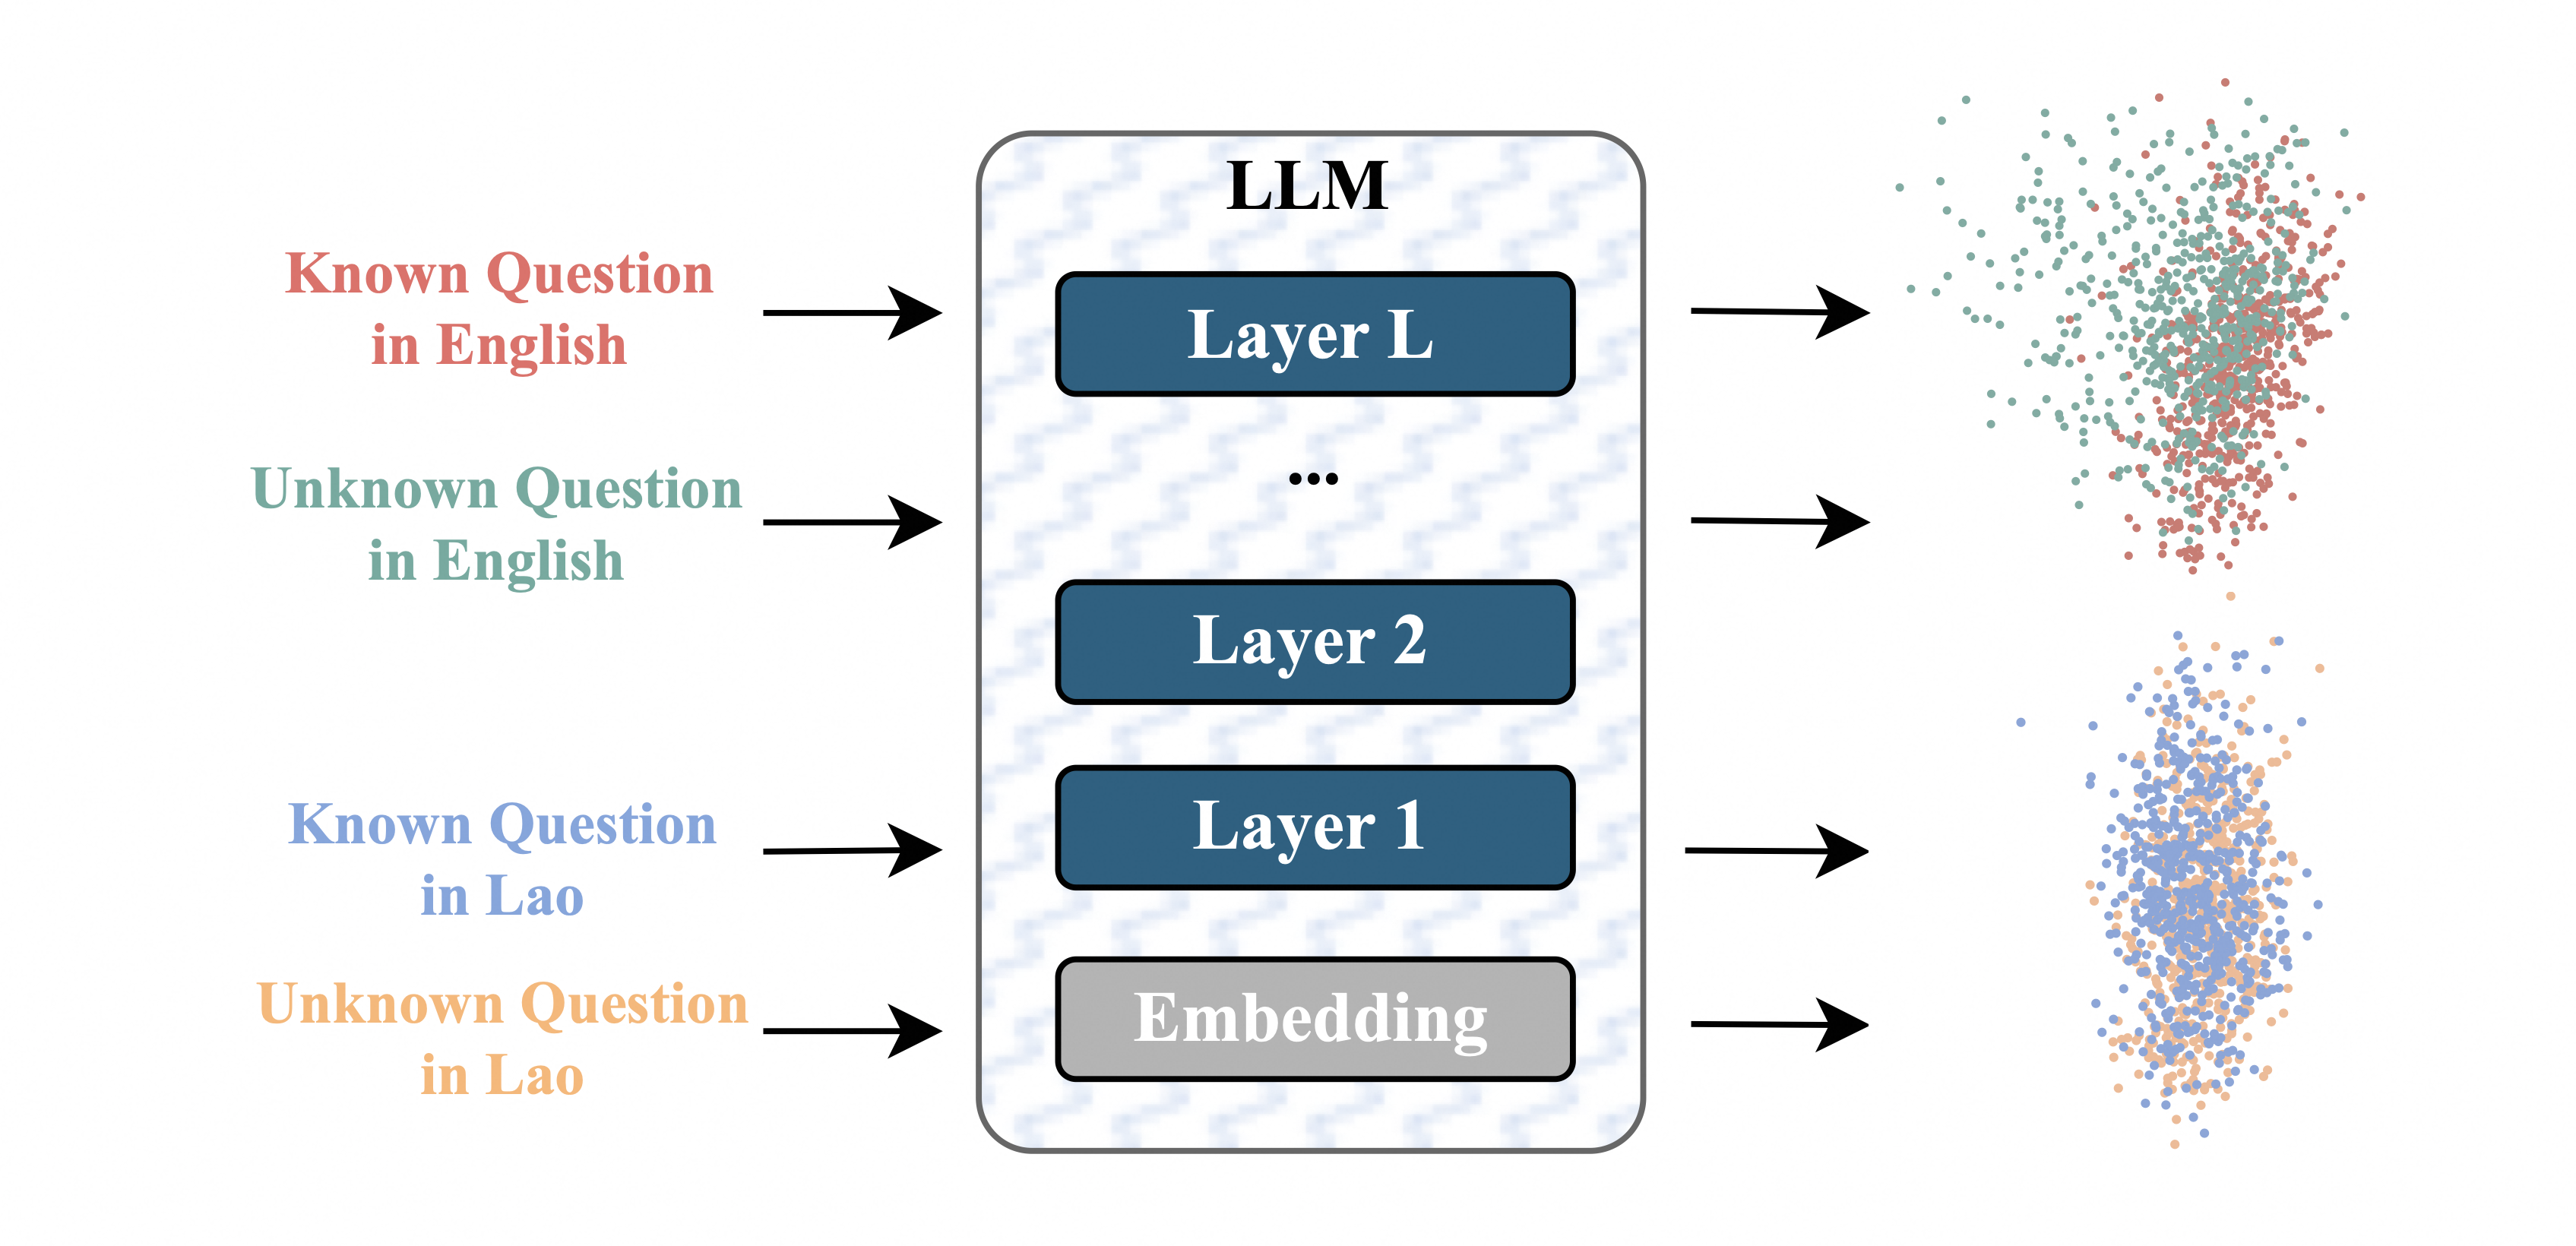
[ACL 2025] Analyzing LLMs' Multilingual Knowledge Boundary Cognition Across Languages Through the Lens of Internal Representations
ChartHal: A Fine-grained Framework Evaluating Hallucination of Large Vision Language Models in Scientific Chart Understanding
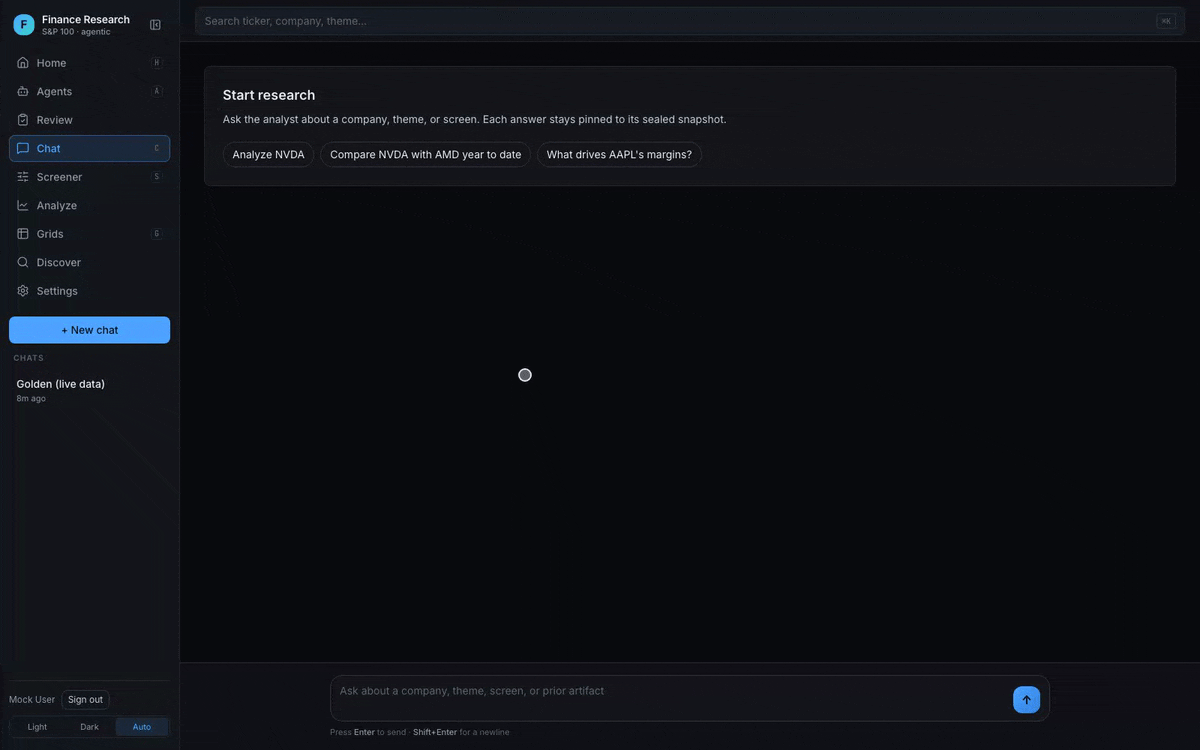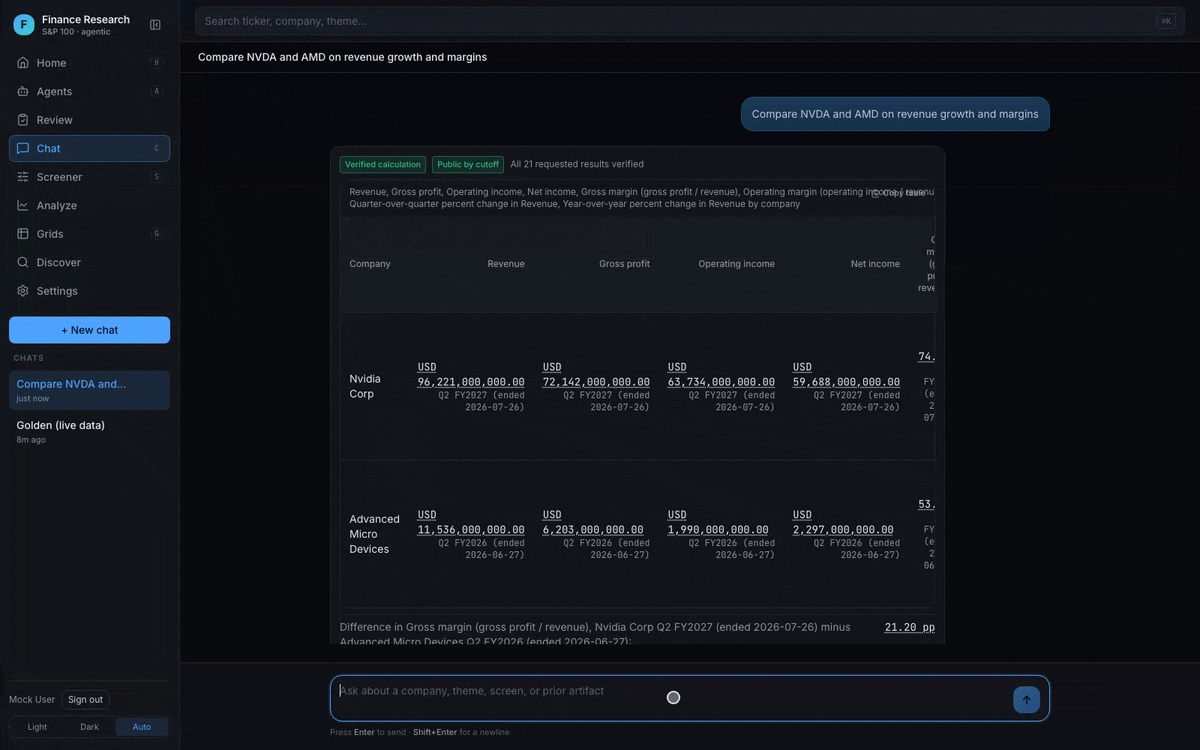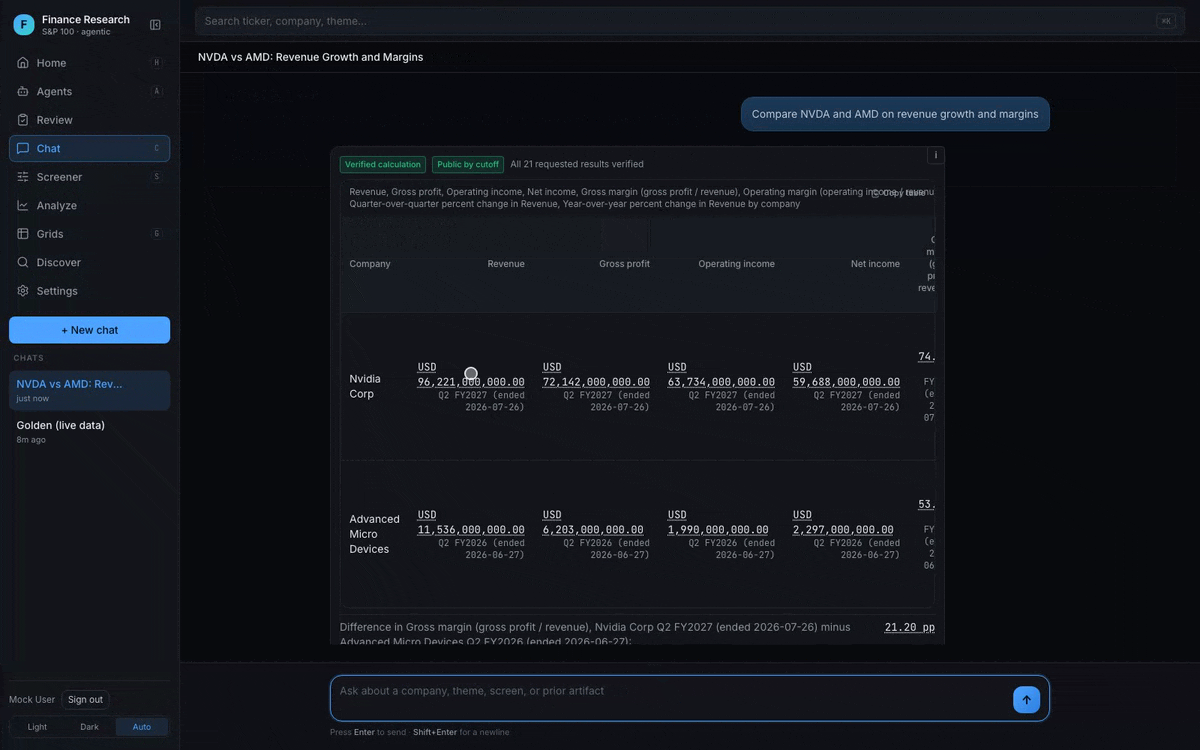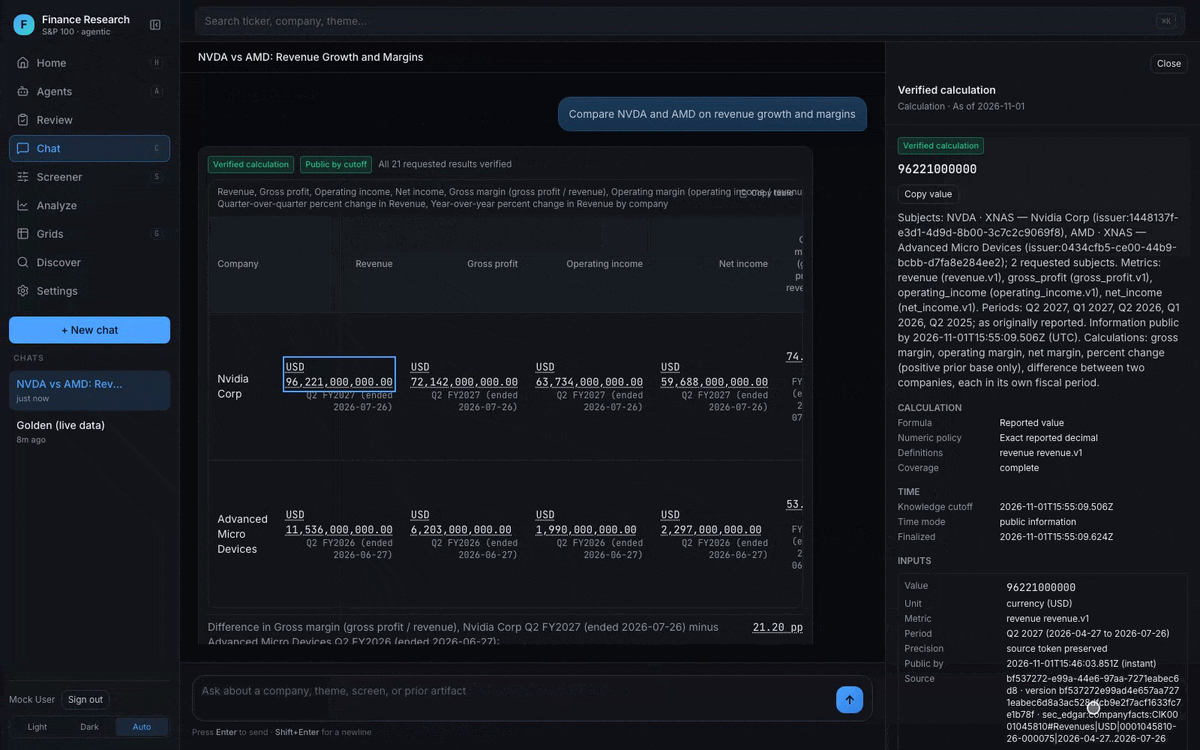
Evidence-backed finance research terminal: screen markets, dig into companies, and run an AI analyst where every number traces back to its source.
Self-hosted memory + evidence layer for AI agents (Claude Code, Codex, Hermes, ...) — embeddable Go library, MCP / HTTP / CLI, evidence-backed claims, bitemporal recall, axi-go execution kernel with JSONL audit + token budgets, cosign-signed releases with SLSA L3 provenance. No vendor cloud, no per-call billing.
Python contracts for AI-agent tool results. Block empty, partial, stale and unverified JSON, HTTP, MCP and stdio observations.
Benchmark LLMs on accuracy, cost, and hallucination.
Runs in the browser on Hugging Face
The missing brain for AI coding agents — verification gates written before the code, Reflexion-style memory that learns from every failure, and self-correction loops with real anchors. One command install for Claude Code; copy-paste prompts for any AI.
Is this LLM output faithful to its source? Free open HHEM.
Runs in the browser on Hugging Face
The deterministic verification gate for AI research agents — fake CVEs 404, quotes must be on the page, a verified=yes it can't confirm is a FAIL.
Invert LLM hallucination into productive features
Runs in the browser on Hugging Face
See which words an LLM was unsure about, from logprobs
Runs in the browser on Hugging Face
Where confident LLM errors come from, 3 studies
Runs in the browser on Hugging Face
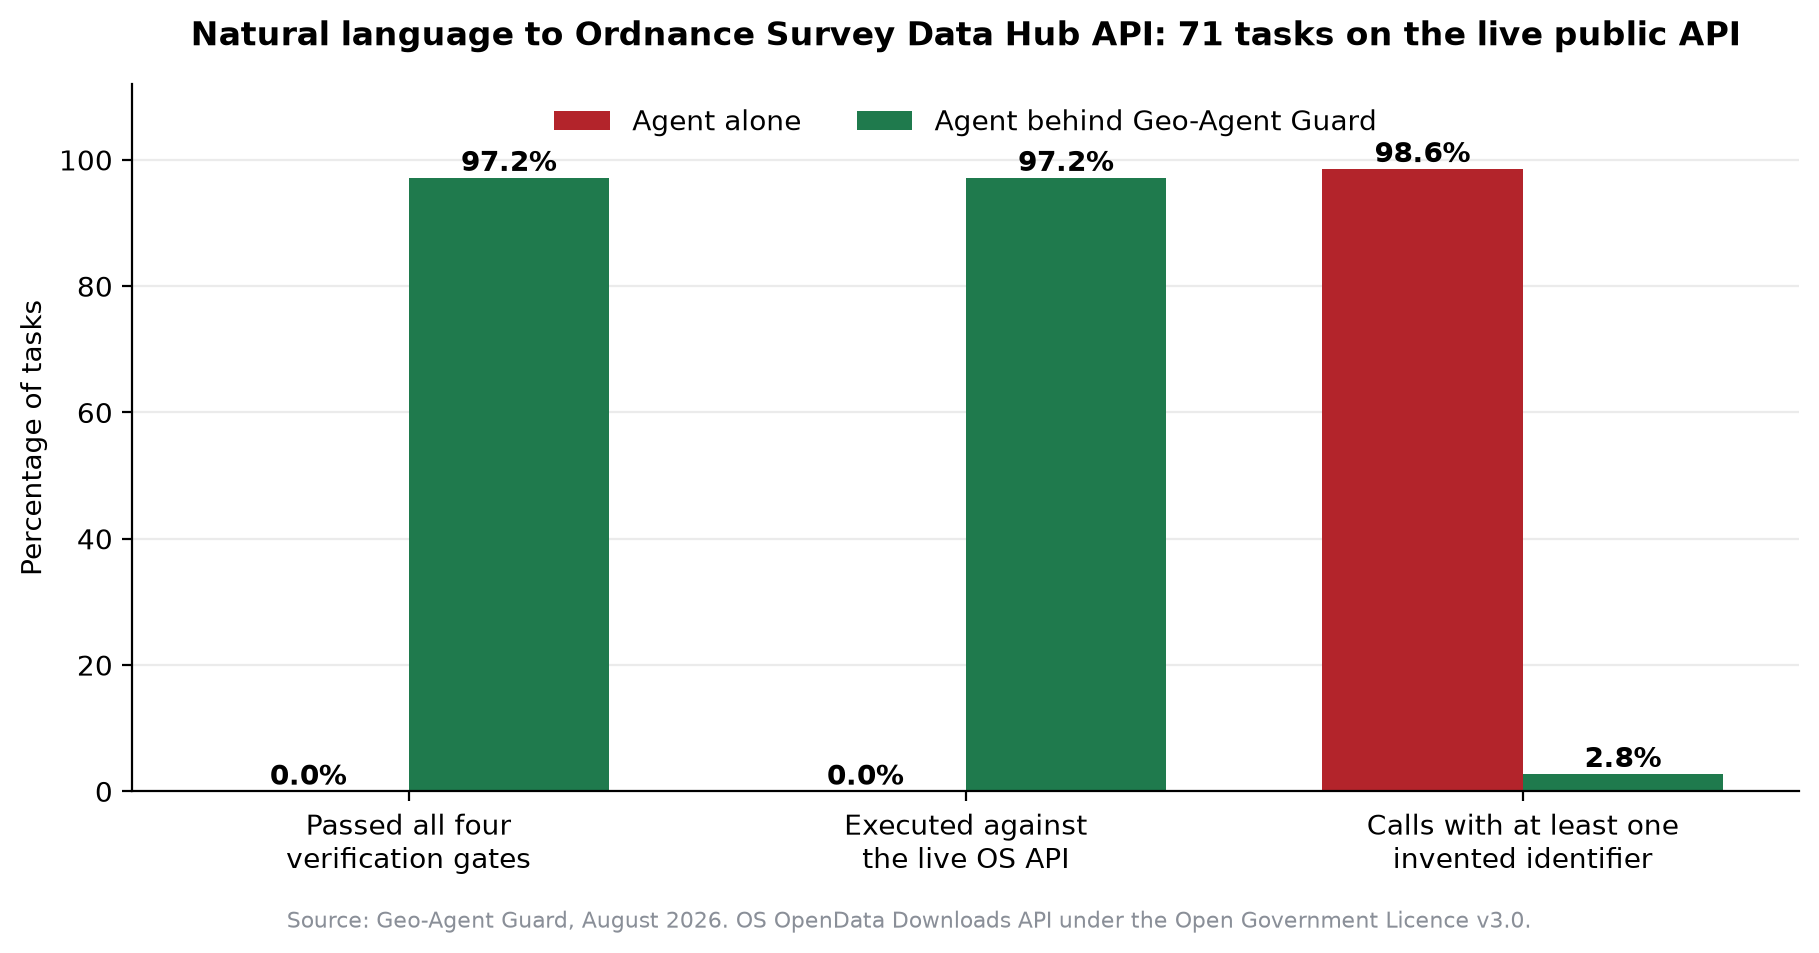
Can an LLM agent be trusted to call a national geospatial API? Measured against the live Ordnance Survey Data Hub: 0% valid calls unaided, 97.2% behind a closed-world verifier.
An MCP server that gives AI agents Community Notes: built on last30days, it maps who agrees, who disputes, and how sure the signal is - a contestation map, not a true/false verdict.