firecrawl
Knowledge infrastructure to make your agents smarter. Search, scrape and 550+ data providers through one API.
- 203k
- TypeScript
- AGPL-3.0
- 32 min ago
Knowledge infrastructure to make your agents smarter. Search, scrape and 550+ data providers through one API.
Official Crawl4AI Cloud: a hosted web scraping, extraction, and search API for AI agents. Free API key, 1,000 credits a month, no card. Fully open source: this repo is the Apache-2.0 crawler that powers it, and you can self-host it.
Create agents that monitor and act on your behalf. Your agents are standing by!
The fast, flexible, and elegant library for parsing and manipulating HTML and XML.
Crawlee—A web scraping and browser automation library for Node.js to build reliable crawlers. In JavaScript and TypeScript. Extract data for AI, LLMs, RAG, or GPTs. Download HTML, PDF, JPG, PNG, and other files from websites. Works with Puppeteer, Playwright, Cheerio, JSDOM, and raw HTTP. Both headful and headless mode. With proxy rotation.
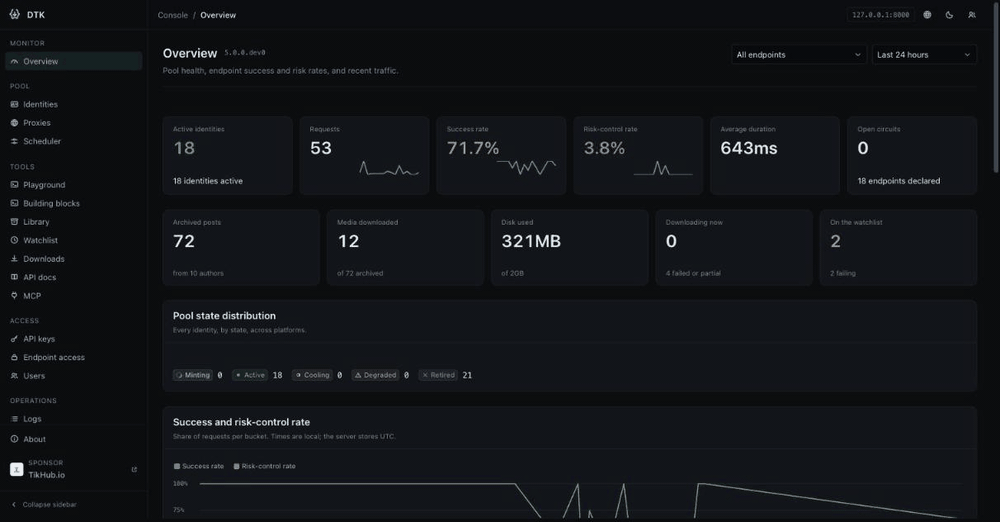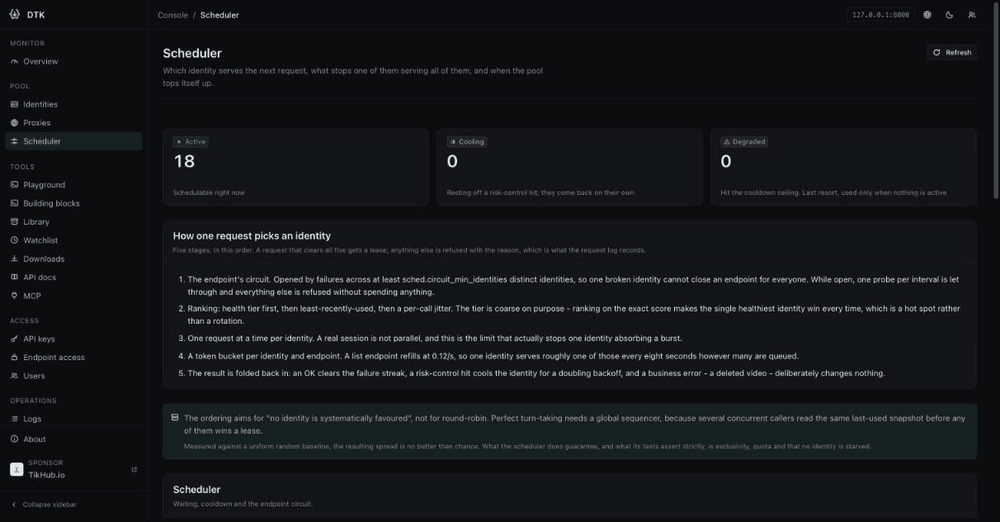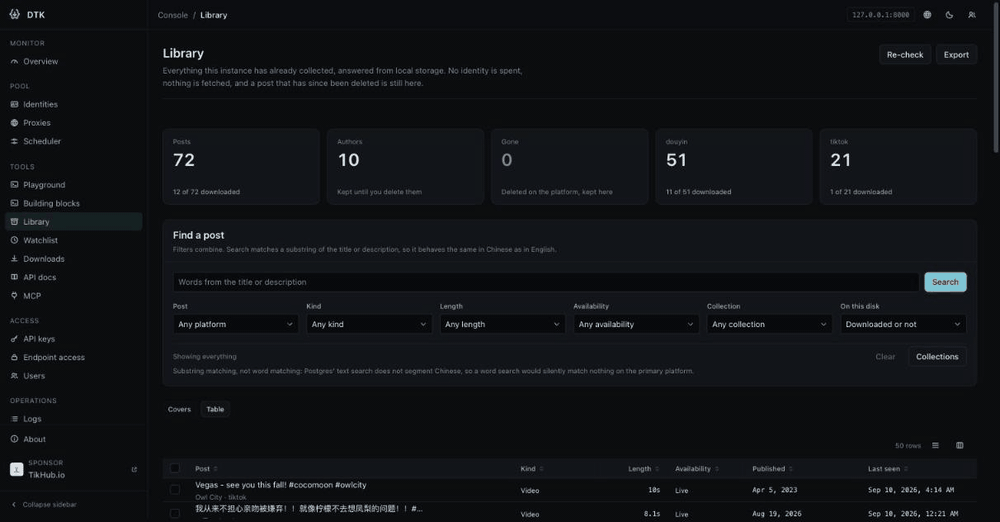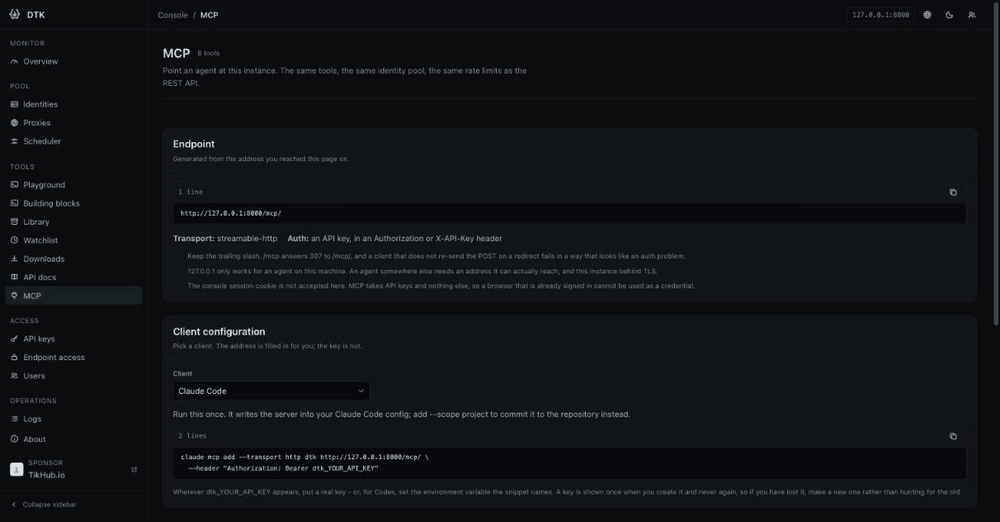
🚀 自托管的抖音、TikTok、B 站数据采集与无水印视频下载 API,支持 AI agent 通过 MCP 调用与离线语音转文字,Docker 一键部署。| Self-hosted TikTok, Douyin & Bilibili scraper and no-watermark video downloader — async REST API, MCP server for AI agents, CLI and web console, plus offline speech-to-text for downloaded videos. Self-healing identity pool, PostgreSQL archive, one docker compose up.
Turn any website into a structured API. Extract, automate, search and monitor the web.
newspaper3k is a news, full-text, and article metadata extraction in Python 3. Advanced docs:
Automated CAPTCHA solver for your browser. Works with Selenium, Puppeteer, Playwright, and more.
Crawlee—A web scraping and browser automation library for Python to build reliable crawlers. Extract structured data with LLMs via Pydantic AI, or control the browser in natural language with Stagehand. Works with BeautifulSoup, Parsel, Playwright, and raw HTTP. Download HTML, PDF, images, and other files. Proxy rotation included.
💡 Download the complete source code of any website (including all assets). [ Javascripts, Stylesheets, Images ] using Node.js
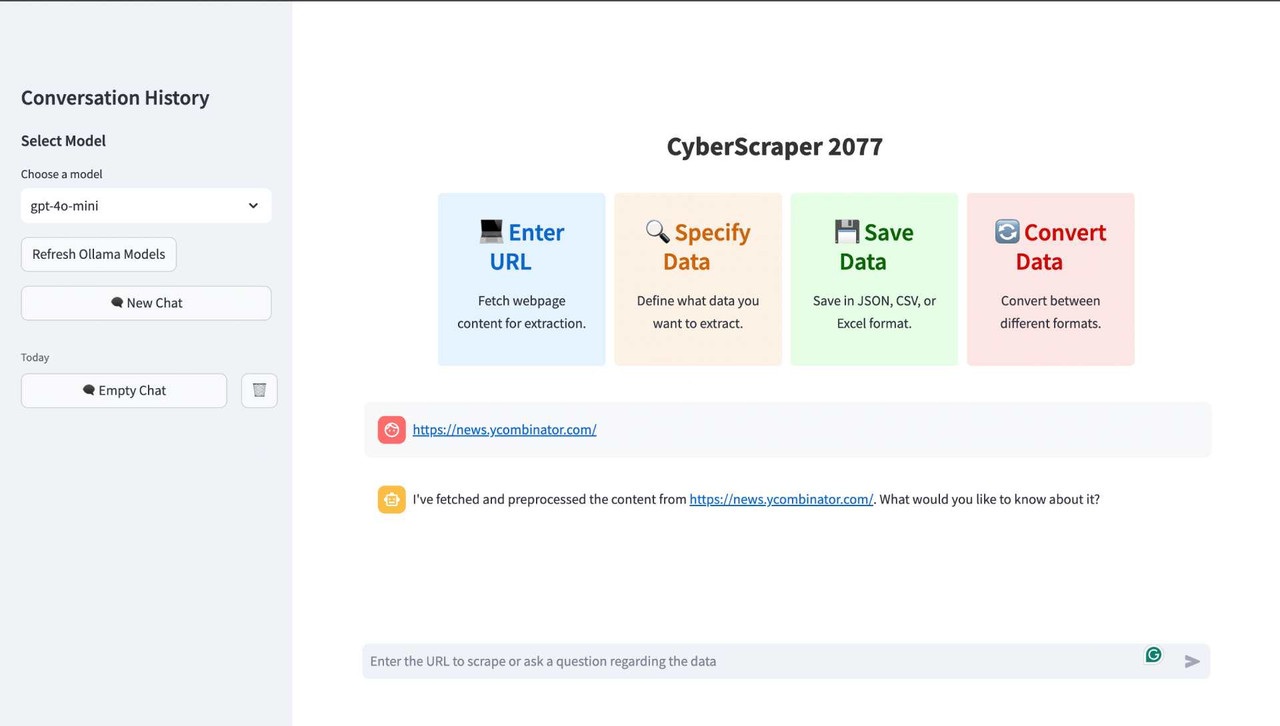
A Powerful web scraper powered by LLM | OpenAI, Gemini & Ollama
TikTok LIVE API for Node.js: An unofficial library to receive live stream events (comments, gifts, etc.) in realtime from TikTok LIVE.
Completely free, private, UI based Tech Documentation MCP server. Designed for coders and software developers in mind. Easily integrate into Cursor, Windsurf, Cline, Roo Code, Claude Desktop App
Download website to local directory (including all css, images, js, etc.)
Self-hosted scraping engine — bypasses any JS challenge & captcha: Cloudflare, Turnstile, reCAPTCHA, hCaptcha, GeeTest. FlareSolverr & Byparr alternative and drop-in replacement for your *arr stack.
A Kotlin-based testing/scraping/parsing library providing the ability to analyze and extract data from HTML (server & client-side rendered). It places particular emphasis on ease of use and a high level of readability by providing an intuitive DSL. It aims to be a testing lib, but can also be used to scrape websites in a convenient fashion.
A Multi-User Selfhosted price tracker for Amazon, Aliexpress, ebay and many more along with custom stores. Get notified when price matches one or more criterias set by the user
Web scraper for scraping, tracking and visualizing prices of products on various websites.
Quickly reads webpages and converts to markdown for fast, token efficient web scraping
Job Search Bot: Community-Driven Job Alerts with Tailored Resumes and Cover Letters
Nodejs web scraper. Contains a command line, docker container, terraform module and ansible roles for distributed cloud scraping. Supported databases: SQLite, MySQL, PostgreSQL. Supported headless clients: Puppeteer, Playwright, Cheerio, JSdom.
Google Play scraper for Node.js with a fully typed TypeScript API. App details, search, top charts, reviews, permissions and data safety. A modern replacement for the unmaintained google-play-scraper.
RAG Web Browser is an Apify Actor to feed your LLM applications and RAG pipelines with up-to-date text content scraped from the web.
🎬 A beautiful Rust TUI client for JavBus — search, browse, preview images in terminal (Kitty protocol), manage favorites & push magnets to 115 cloud. Catppuccin Frappé theme.
Self-hosted Github Repo Analytics Platform - Track Git Clones, Stars & More over time!
Simple web scrapping app made using Spring Boot + Thymeleaf + Jsoup + Java 8 Lambdas & Streams
🚀 mcp-web-scrape — Clean, cache-aware web content fetcher for AI agents. Fetch any URL → extract readable content → return Markdown/JSON with citations. ⚡ Fast caching, 🤝 robots.txt compliant, 📝 Markdown-ready output, �� works with ChatGPT/Claude Desktop.