redash
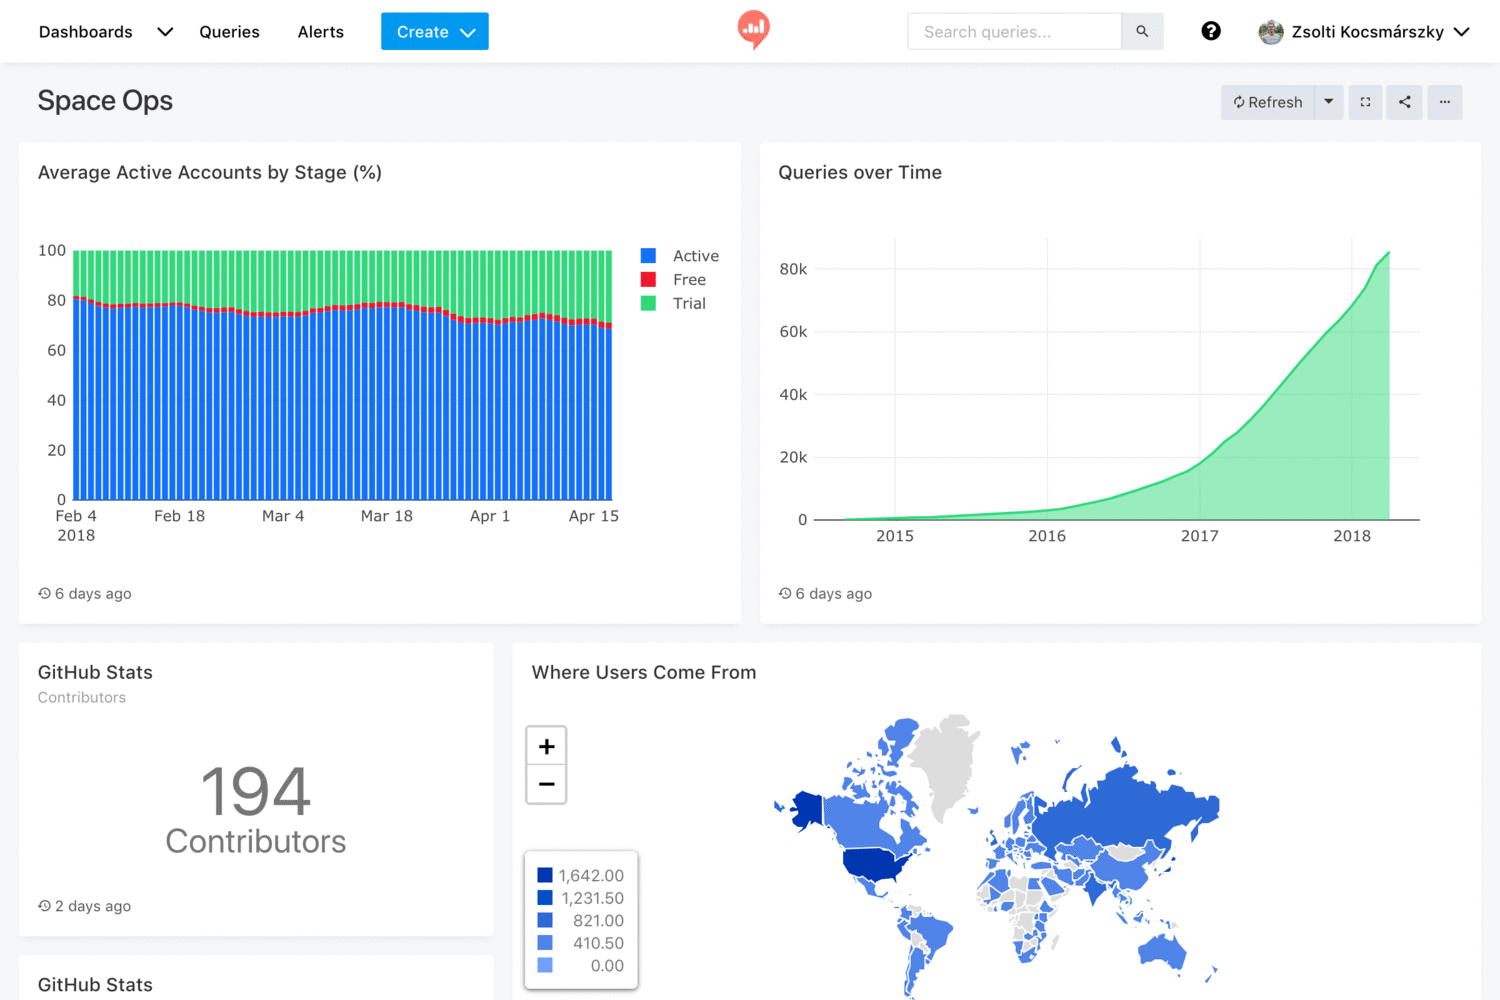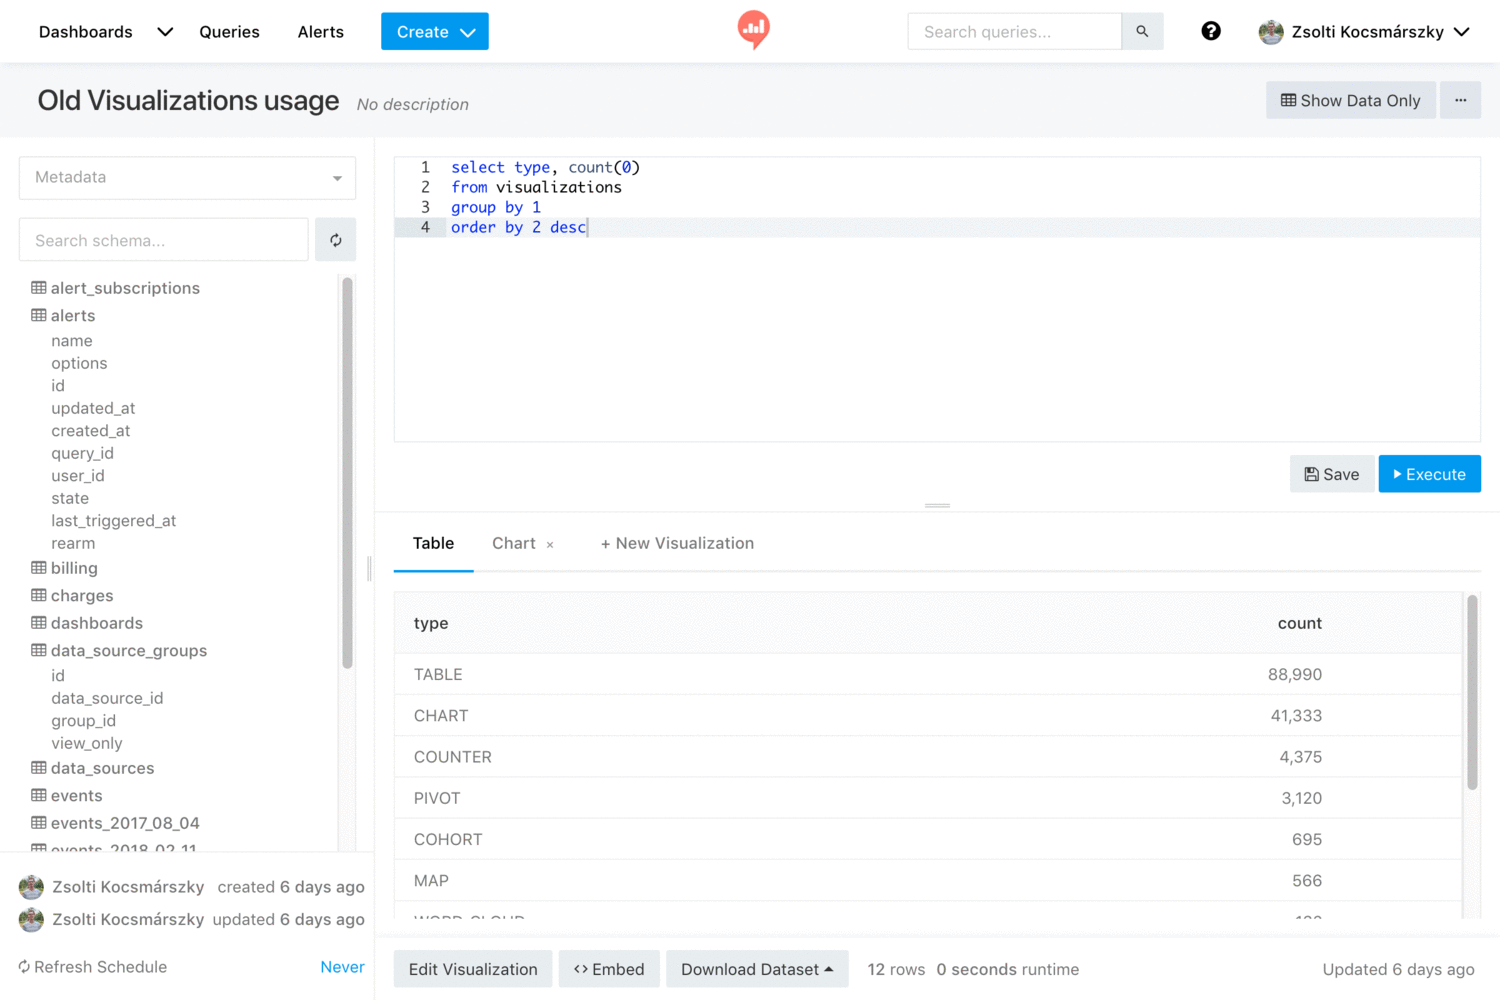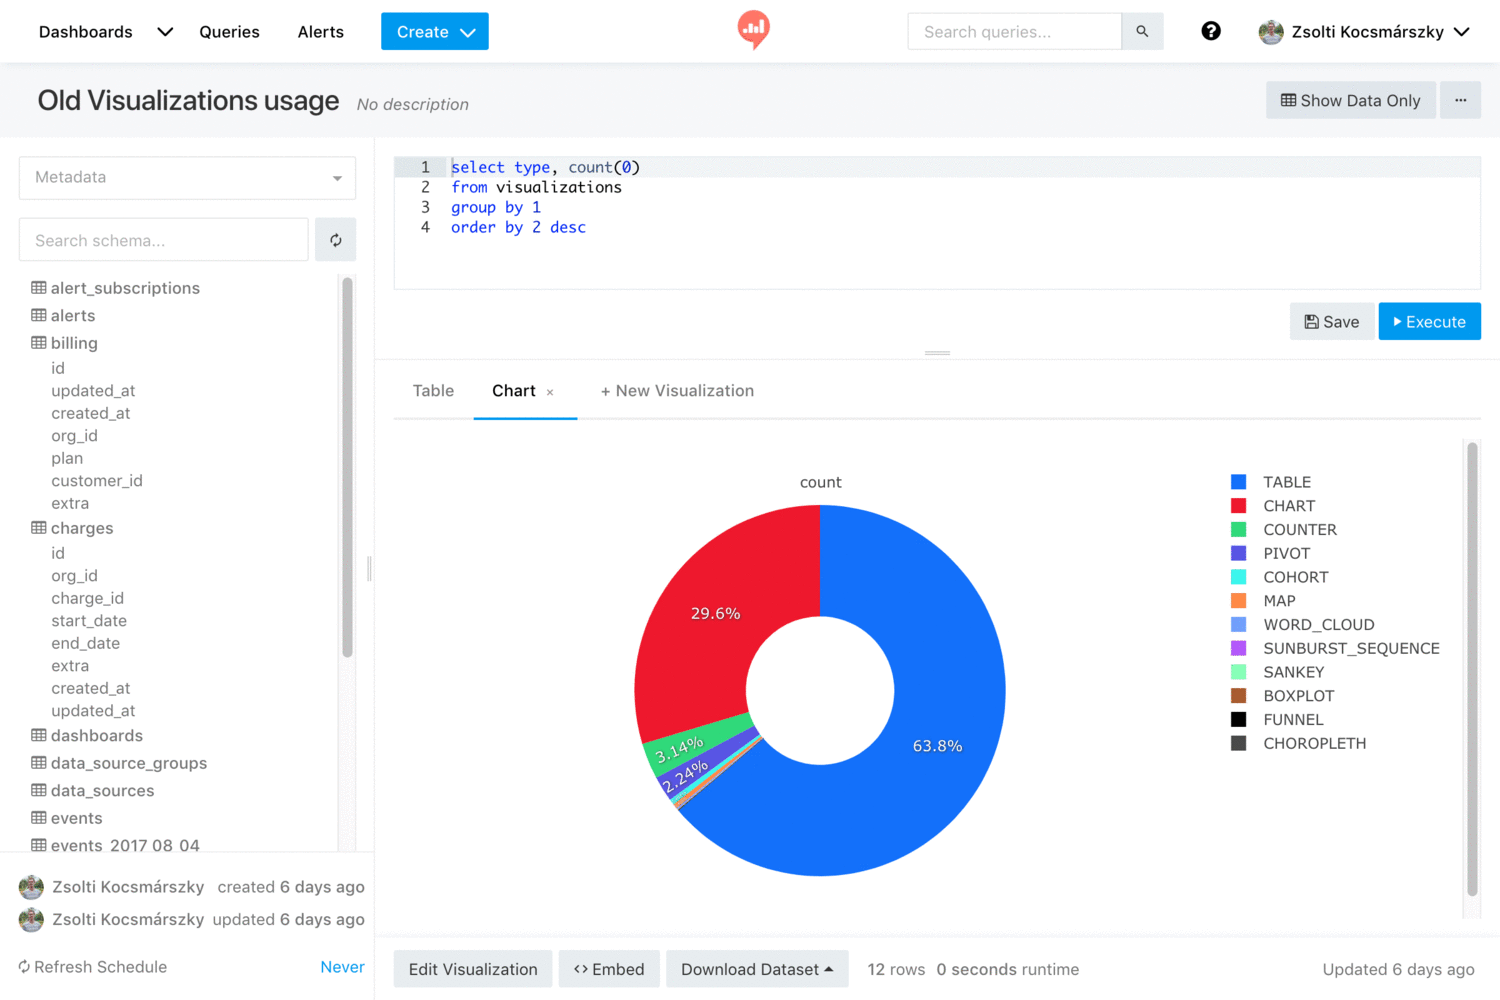
Make Your Company Data Driven. Connect to any data source, easily visualize, dashboard and share your data.
- 29k
- TypeScript
- BSD-2-Clause
- 6 d ago
Make Your Company Data Driven. Connect to any data source, easily visualize, dashboard and share your data.
Apache Kyuubi is a distributed and multi-tenant gateway to provide serverless SQL on data warehouses and lakehouses.
.NET for Apache® Spark™ makes Apache Spark™ easily accessible to .NET developers.
This is the github repo for Learning Spark: Lightning-Fast Data Analytics [2nd Edition]
A complete example of a big data application using : Kubernetes (kops/aws), Apache Spark SQL/Streaming/MLib, Apache Flink, Scala, Python, Apache Kafka, Apache Hbase, Apache Parquet, Apache Avro, Apache Storm, Twitter Api, MongoDB, NodeJS, Angular, GraphQL
A data lakehouse on Databricks with the medallion architecture: PySpark, Spark SQL, Delta Lake and Unity Catalog. The project of the free Databricks bootcamp.
Real-time Data Warehouse with Apache Flink & Apache Kafka & Apache Hudi
This repository will help you to learn about databricks concept with the help of examples. It will include all the important topics which we need in our real life experience as a data engineer. We will be using pyspark & sparksql for the development. At the end of the course we also cover few case studies.
Data cleaning, pre-processing, and Analytics on a million movies using Spark and Scala.
Big Data essentials: Hadoop, MapReduce, Spark. Explore tutorials and demos in Jupyter notebooks—most are self-contained and live, ready to run with a click.
Simplified ETL process in Hadoop using Apache Spark. Has complete ETL pipeline for datalake. SparkSession extensions, DataFrame validation, Column extensions, SQL functions, and DataFrame transformations
applications for risk management through computational portfolio construction methods
Interactive Apache Iceberg debugger for exploring production tables and tracing metadata evolution through AI and real time graph visualization.
This repo contains my learnings and practice notebooks on Spark using PySpark (Python Language API on Spark). All the notebooks in the repo can be used as template code for most of the ML algorithms and can be built upon it for more complex problems.
A Kafka and Spark Streaming Integration project : SF Crime Statistics with Spark Streaming
This is a simple Java program to illustrate the use of User Defined Functions (UDFs) in Apache SparkSql.
First lab for Data-Intensive Computing course at KTH where we are introduced to Apache Spark MLlib and Spark SQL, Hadoop, and HBase.
Your client, a Portuguese banking institution, ran a marketing campaign to convince potential customers to invest in a bank term deposit scheme. The marketing campaigns were based on phone calls. Often, the same customer was contacted more than once through phone, in order to assess if they would want to subscribe to the bank term deposit or not. You have to perform the marketing analysis of the
Python package for Spark programming and its powerful, higher-level libraries such as SparkSQL and MLlib (for Machine Learning), very useful for general Big Data analysis.