spark
.NET for Apache® Spark™ makes Apache Spark™ easily accessible to .NET developers.
- 2.1k
- C#
- MIT
- 2 wk ago
.NET for Apache® Spark™ makes Apache Spark™ easily accessible to .NET developers.
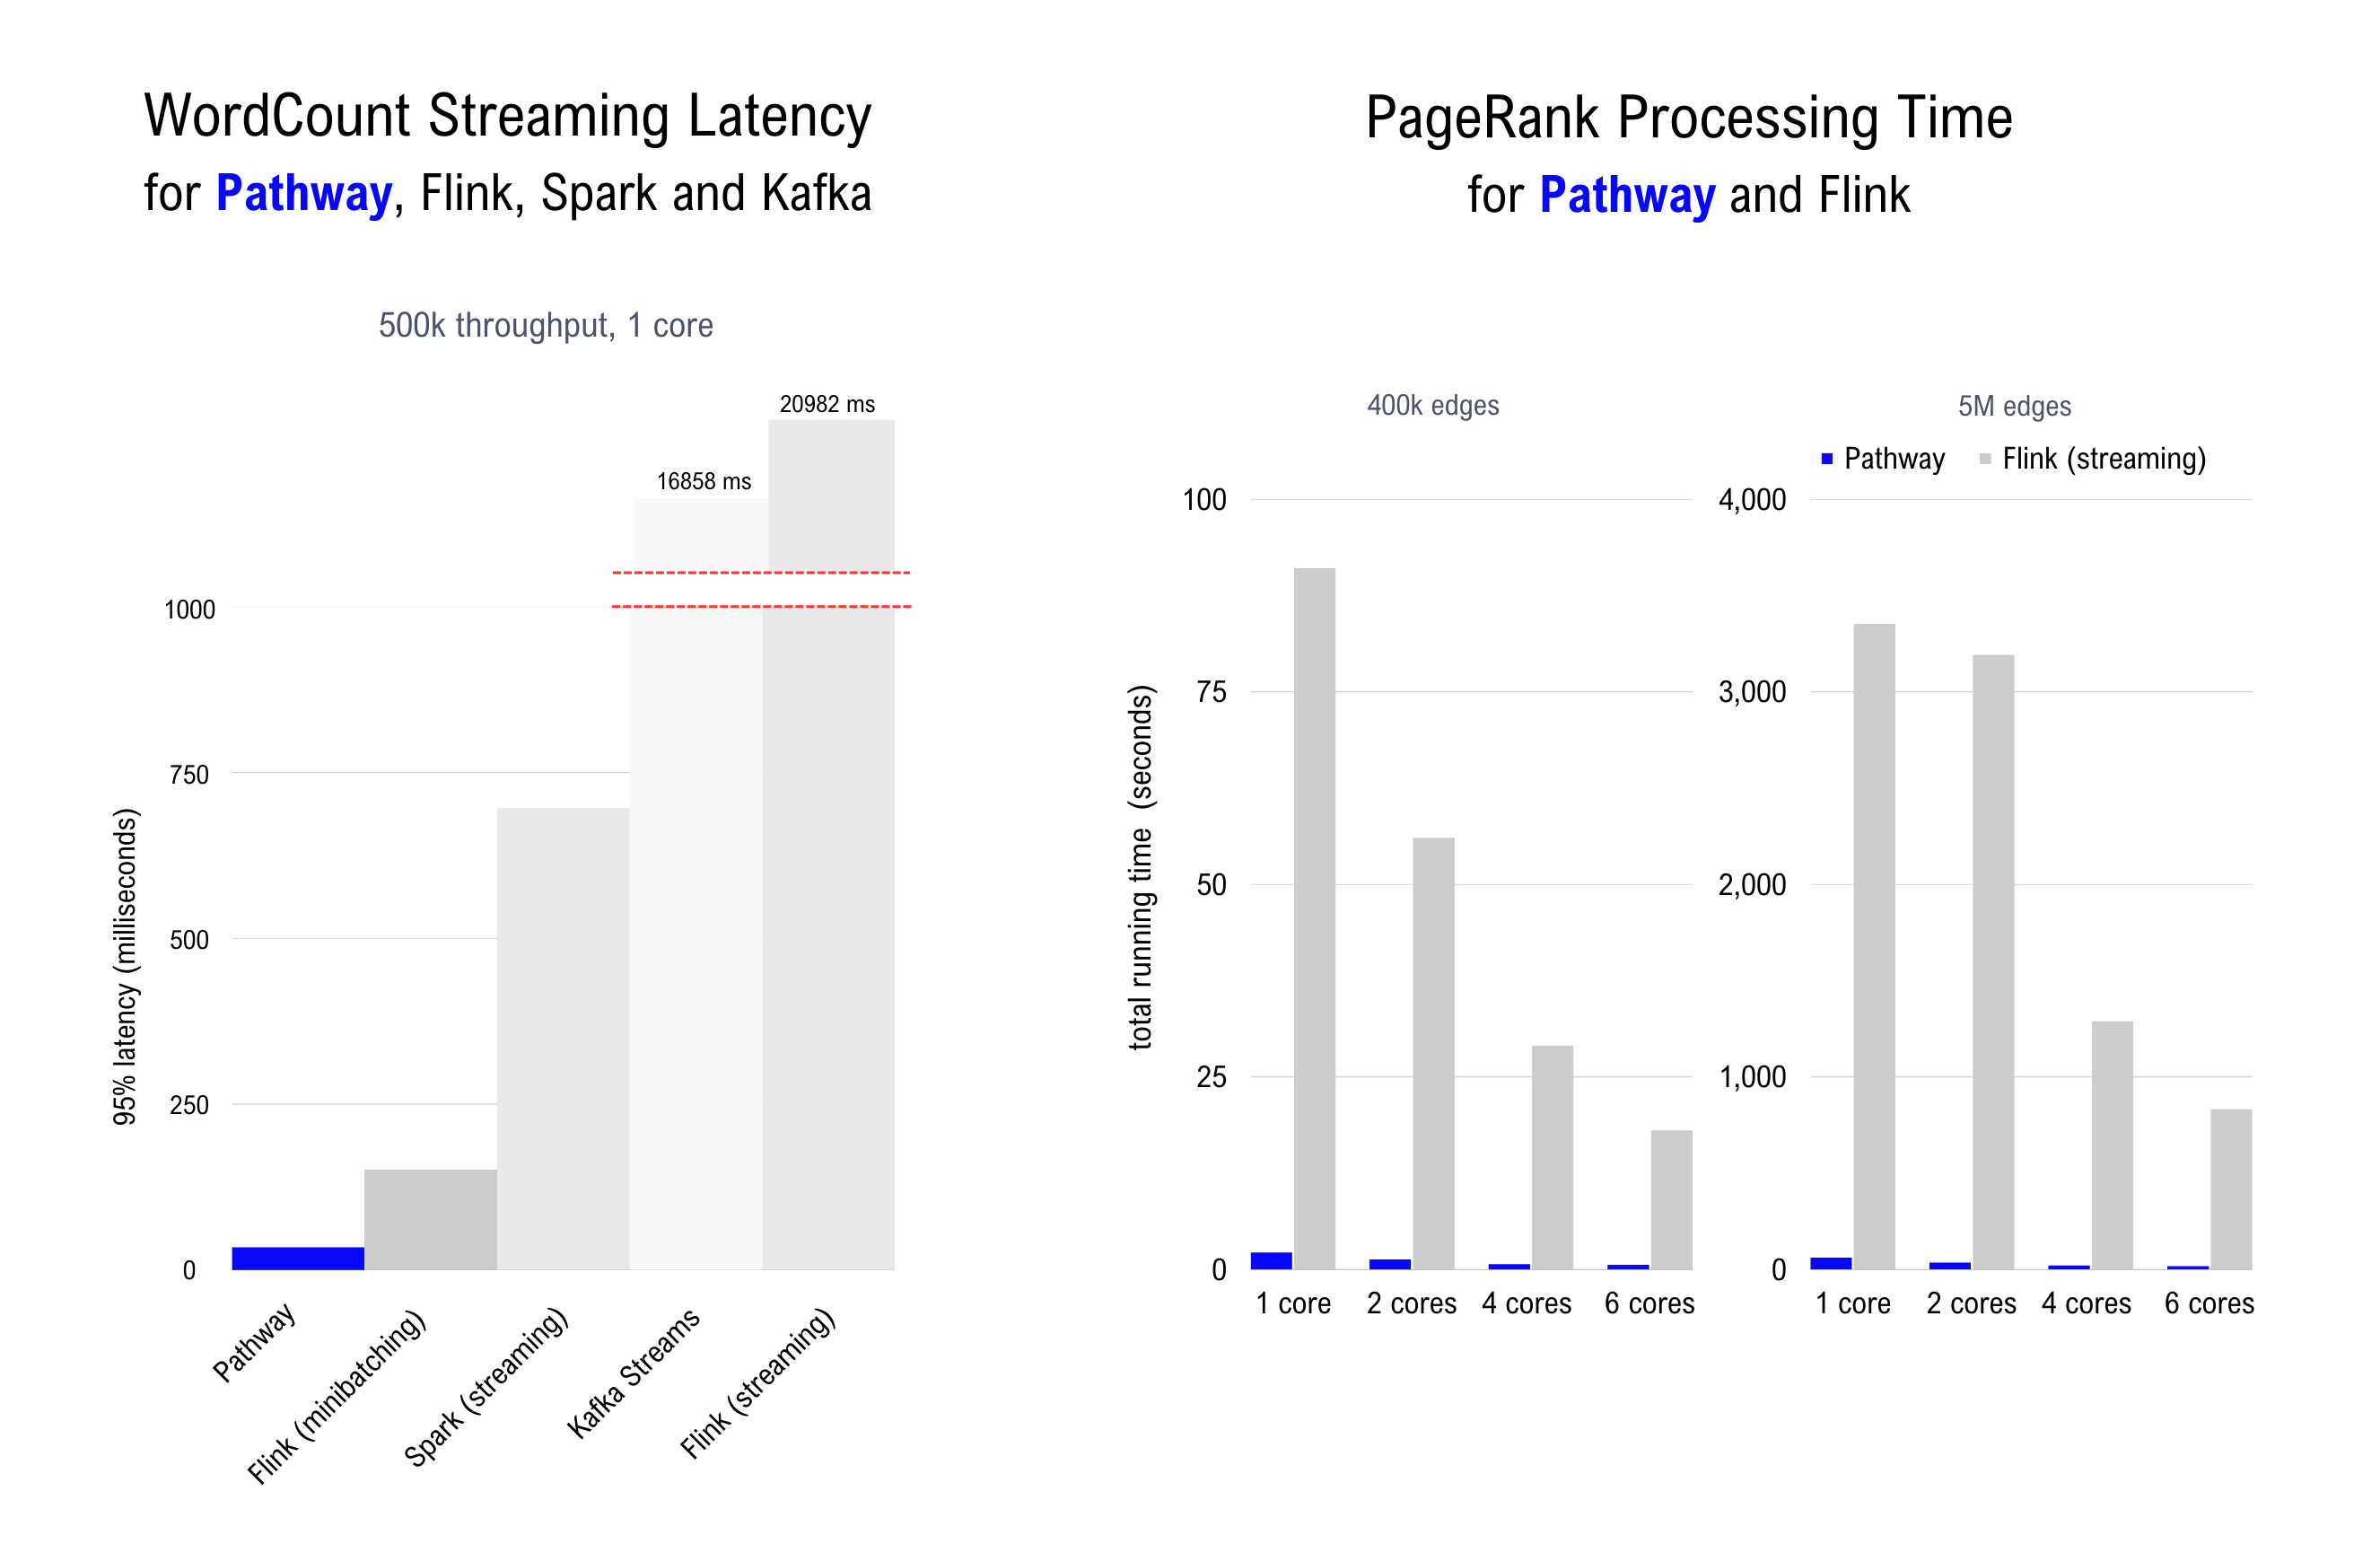
Benchmarks for data processing systems: Pathway Live Data Framework, Spark, Flink, Kafka Streams
A complete example of a big data application using : Kubernetes (kops/aws), Apache Spark SQL/Streaming/MLib, Apache Flink, Scala, Python, Apache Kafka, Apache Hbase, Apache Parquet, Apache Avro, Apache Storm, Twitter Api, MongoDB, NodeJS, Angular, GraphQL
This repository will help you to learn about databricks concept with the help of examples. It will include all the important topics which we need in our real life experience as a data engineer. We will be using pyspark & sparksql for the development. At the end of the course we also cover few case studies.
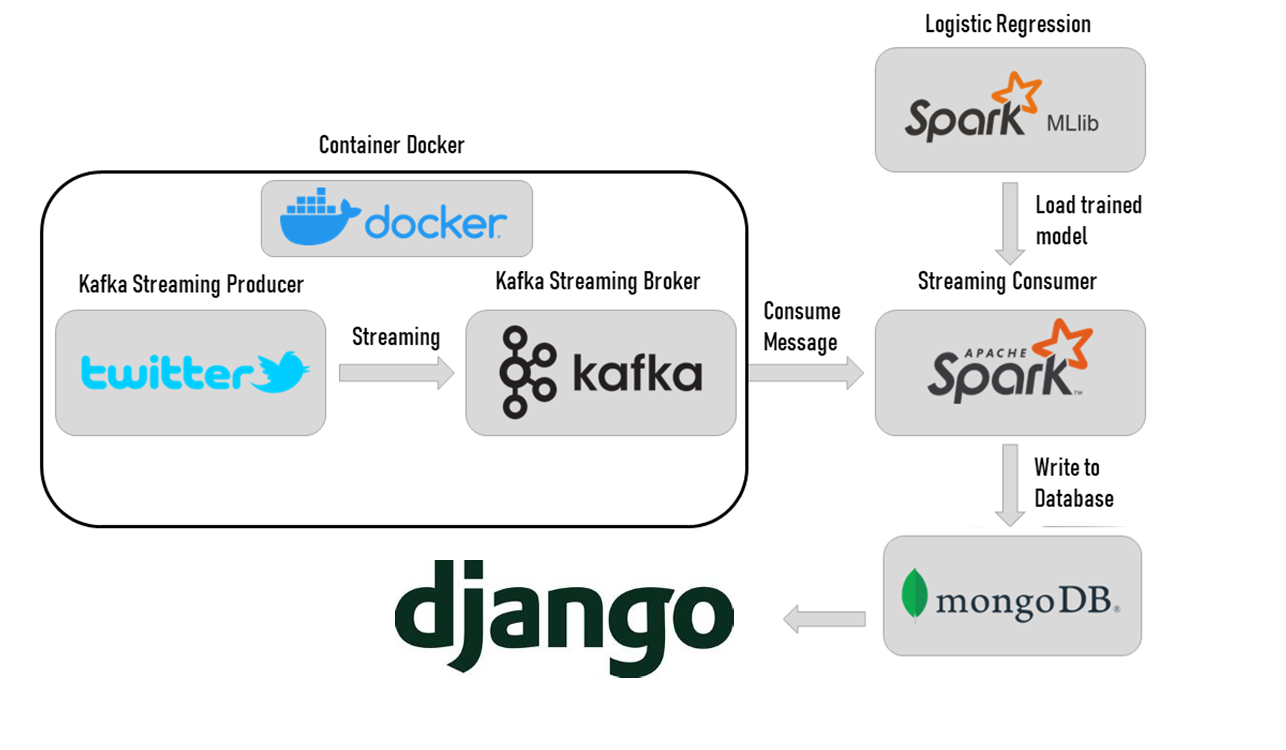
This repo contains Big Data Project, its about "Real Time Twitter Sentiment Analysis via Kafka, Spark Streaming, MongoDB and Django Dashboard".
A data and analytics engineering platform designed for real-time sports betting analytics.
RealTime StockStream is a streamlined, simulation system for processing live stock market data. It uses Apache Kafka for data input, Apache Spark for data handling, and Apache Cassandra for data storage, making it a powerful yet easy-to-use tool for financial data analysis
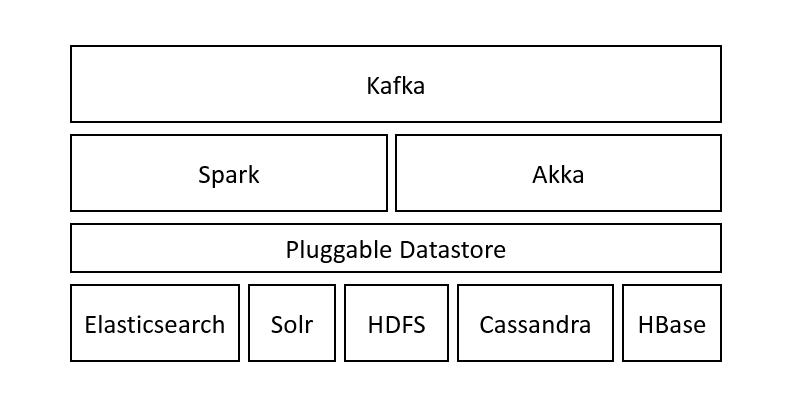
WASP is a framework to build complex real time big data applications. It relies on a kind of Kappa/Lambda architecture mainly leveraging Kafka and Spark. If you need to ingest huge amount of heterogeneous data and analyze them through complex pipelines, this is the framework for you.
Source code for the examples in the book Cloud Computing Solutions Architect: A Hands-On Approach by Arshdeep Bahga and Vijay Madisetti
Cardio Monitor is a web app that helps you to find out whether you are at risk of developing heart disease. the model used for prediction has an accuracy of 92%. This is the course project of subject Big Data Analytics (BCSE0158).
Example project for consuming AWS Kinesis streamming and save data on Amazon Redshift using Apache Spark
Проекты курса Инженер данных на платформе Yandex Practicum
Application built on Spark Streaming, Kafka and Cassandra.
A Real-Time Tweet Streaming Pipeline (Using Flume, Kafka & Spark-Streaming) with Deep Learning Sentiment Analysis Model for instant scoring.
Built a Real-Time Dashboard with Spark, Grafana, and InfluxDB
A Kafka and Spark Streaming Integration project : SF Crime Statistics with Spark Streaming
This repo contains my learnings and practice notebooks on Spark using PySpark (Python Language API on Spark). All the notebooks in the repo can be used as template code for most of the ML algorithms and can be built upon it for more complex problems.
A data pipeline built using Apache Kafka and Apache Spark, implemented in Scala.
Let's be honest - most data pipeline frameworks treat types as suggestions. Config files are strings. Schemas are "validated" at runtime. Data quality is an afterthought. So, let's do differently
This repository demonstrates big data processing, visualization, and machine learning using tools such as Hadoop, Spark, Kafka, and Python.
PySpark is a Python API for support Python with Spark. Whether it is to perform computations on large datasets or to just analyze them
SparkSQL, Spark Streaming and Apache Kafka assignment