FluidAudio
Frontier CoreML audio models in your apps — text-to-speech, speech-to-text, voice activity detection, and speaker diarization. In Swift, powered by SOTA open source.
- 3.3k
- Swift
- Apache-2.0
- 1 d ago
Frontier CoreML audio models in your apps — text-to-speech, speech-to-text, voice activity detection, and speaker diarization. In Swift, powered by SOTA open source.
Offline speech recognition API for Android, iOS, Raspberry Pi and servers with Python, Java, C# and Node
very fast speech-to-text, diarization, streaming (even in CPU) with NVIDIA Parakeet in Rust
The SpeechBrain project aims to build a novel speech toolkit fully based on PyTorch. With SpeechBrain users can easily create speech processing systems, ranging from speech recognition (both HMM/DNN and end-to-end), speaker recognition, speech enhancement, speech separation, multi-microphone speech processing, and many others.
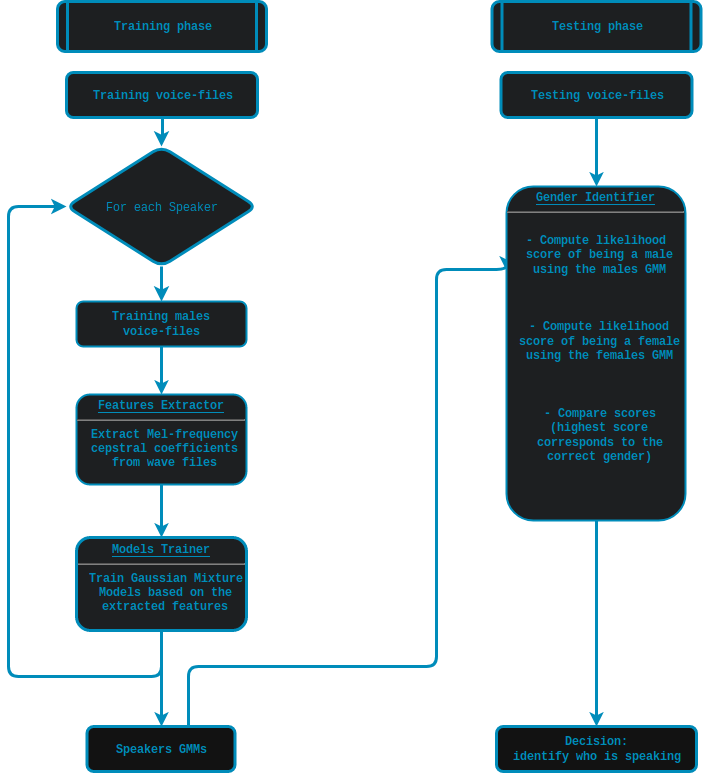
:sound: :boy: :girl: :woman: :man: Speaker identification using voice MFCCs and GMM
Speaker embedding for VI-SVC and VI-SVS, alse for VITS; Use this to replace the ID to implement voice clone.
Ensemble speaker verification achieving 97% accuracy - Intelligent fusion of MFCC+DTW (92%) and Resemblyzer CNN (94%) for voice authentication
Implementation of a speaker identification and a speaker verification system based on Gaussian Mixture Models (GMM) in combination with and Universal Background Model (UBM) on the YOHO dataset in MATLAB.
speaker recognition / speaker verification models in pytorch implementation
Pure-Rust streaming speech-to-text + speaker diarization — whisper-rs · sherpa-onnx · tokio async