s3prl
Self-Supervised Speech Pre-training and Representation Learning Toolkit
- 2.6k
- Python
- Apache-2.0
- 8 mo ago
Self-Supervised Speech Pre-training and Representation Learning Toolkit
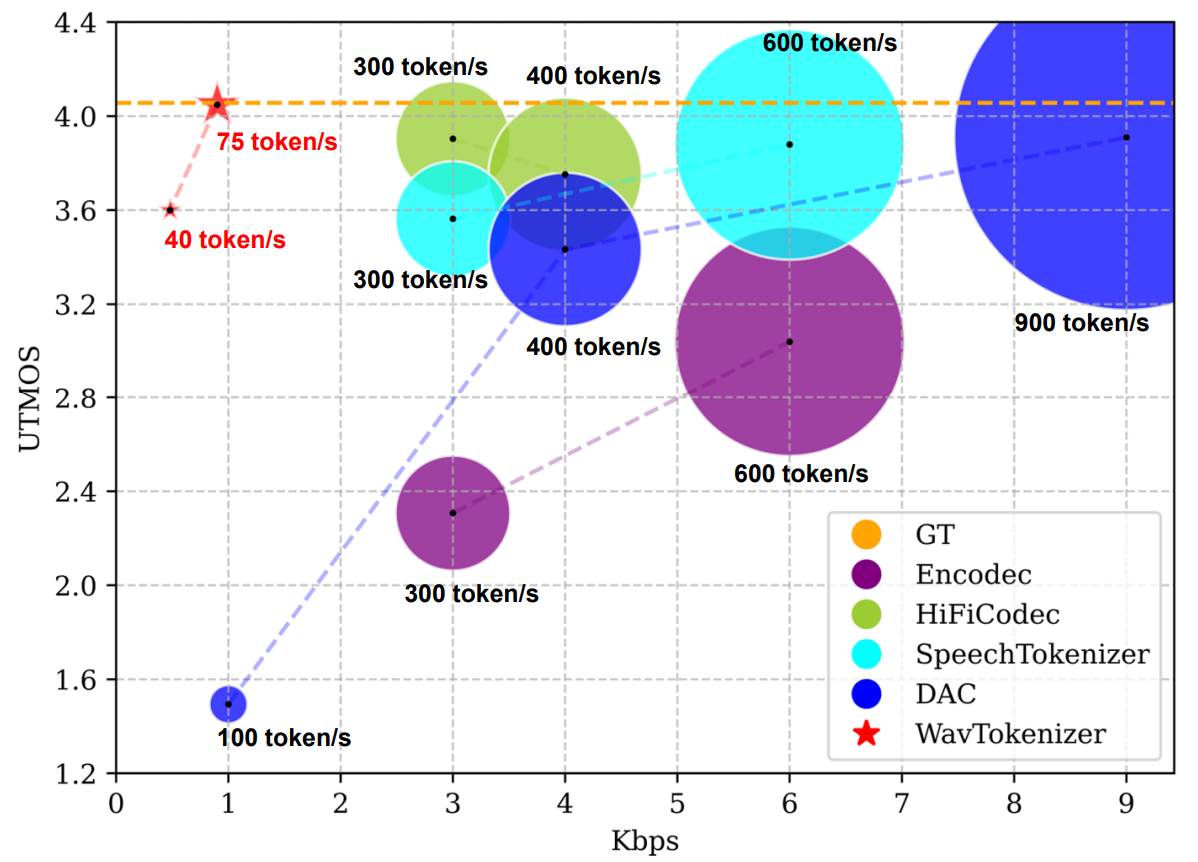
[ICLR 2025] SOTA discrete acoustic codec models with 40/75 tokens per second for audio language modeling