strata


DeepSeek-V4.1-Flash-1017-Uncensored-GSQ-RCO-GGUF
Text generation model, used with gguf.
- 739
- 225k
- mit
- 3 wk ago
Xolotl
Xolotl: run DeepSeek-V4.1-Flash, all 552B, as a local coding agent on one gaming PC (RTX 4090 + 110 GB RAM): ~33 tok/s on agent tasks, ~41 in fast mode, 512K context. Plus GLM-5.3-Flash, Qwen3.8 and LFM3-Omni. MoE experts tiered across VRAM, pinned RAM and NVMe, with Xolotl Direct NVMe->VRAM. OpenAI + Anthropic API.
- 545
- C++
- MIT
- 12 h ago

ML-gfx906
ML software (llama.cpp, ComfyUI, Strata, Maya, ...) builds for AMD gfx906 GPUs, e.g. Radeon VII / MI50 / MI60
- 390
- C++
- MIT
- 1 d ago

Huihui-DeepSeek-V4.1-Flash-1017-abliterated-GGUF
Image text to text model, used with transformers.
- 230
- 134k
- mit
- 12 d ago
Speedy
Qwen3.8-Flash-Next (125B MoE) up to 1M context on one or two RTX cards (tuned on 3080 10gb). A measured, tuned and benchmarked fork of Strata.
- 101
- C++
- 13 h ago

DeepSeek-V4.1-Flash-1017-XQ-Uncensored
- 62
- 30k
- mit
- 5 wk ago
local-ai-harness
Local AI harness for coding agents: detects your GPU and RAM, recommends an engine and model, sizes limits to your context. Any OpenAI-compatible engine or cloud model. Tuned for AMD Strix Halo.
- 38
- Python
- MIT
- 6 h ago

DeepSeek-V4.1-Flash-1017-Uncensored-GSQ-RCO-Coder-GGUF
Text generation model, used with gguf.
- 38
- 45k
- mit
- 2 wk ago
qwen3.8-flash-next-5090-24gb-strata-vs-basalt
Qwen3.8-Flash-Next 177B MoE on RTX 5090 Laptop 24GB — Strata vs Basalt: 96.1 → 143.3 tok/s single (+49%), 67.5 → 163.9 dual (+143%), 3 quant tiers, cold vs hot measurement, spec 2-12 sweep, 8-lane 128K capacity. 中英双语实测实录
- 33
- Python
- MIT
- 6 d ago

DeepSeek-V4.1-Flash-GSQ-Uncensored
- 23
- 4.1k
- mit
- 6 wk ago
OrcaRouter-Qwen3.8-Flash-Next-Uncensored-NVFP4-GPTQ-Strata
Text generation model, used with strata.
- 10
- 34k
- other
- 6 wk ago
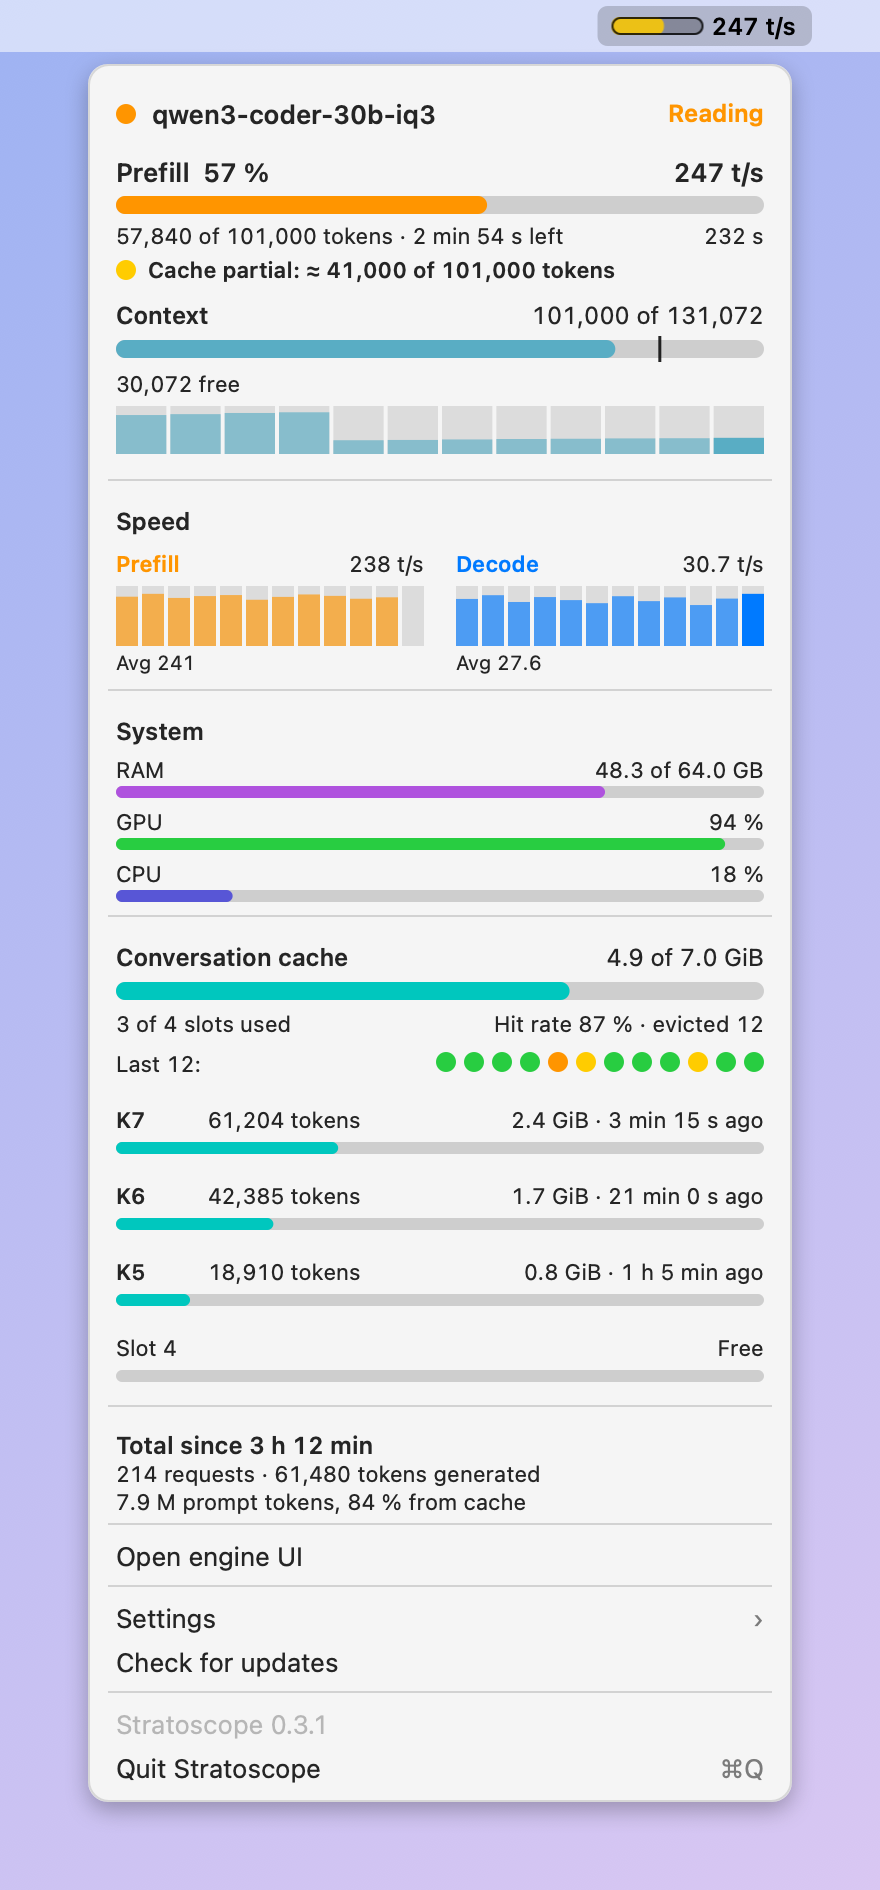
stratoscope
A live gauge for your local LLM inference engine in the menu bar: prefill and decode speed, prompt-cache hits, context, RAM and GPU. Works with Strata.
- 9
- C#
- MIT
- 10 d ago

vram-lend
Allow inference engines to lend then reclaim VRAM resources. Lend to other models without losing your session.
- 5
- Python
- MIT
- 6 d ago

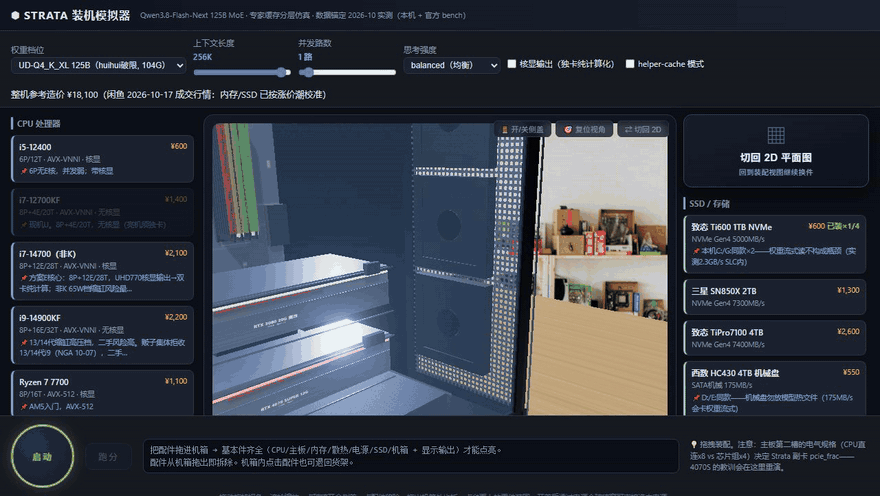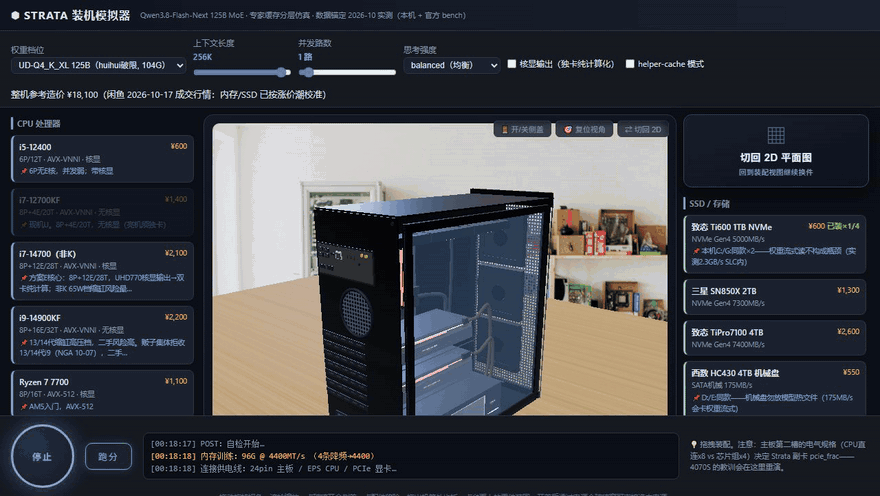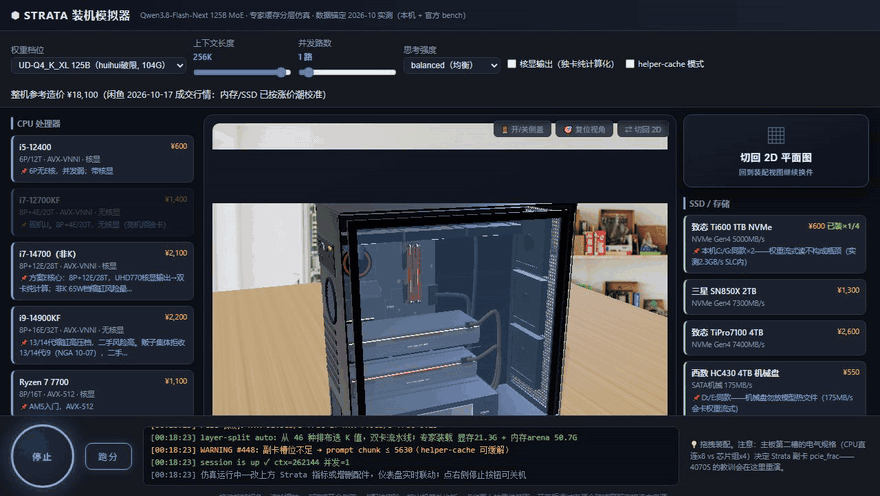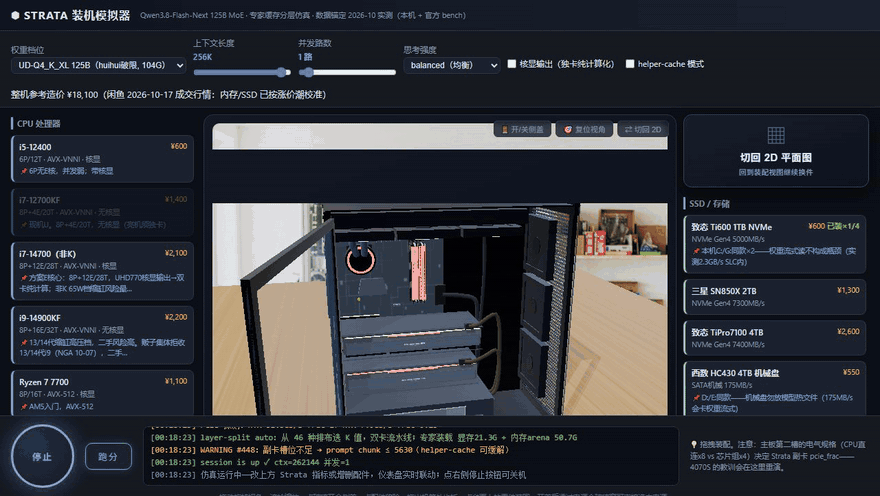
strata-pc-simulator
3D PC-building simulator for local MoE LLM inference — drag real parts, press power, see decode/prefill/TTFT respond. Vanilla JS + Three.js, calibrated against real measurements.
- 3
- JavaScript
- MIT
- 2 wk ago


ShaetherLm
Run 125B locally (exp_Qwen4) on a 16 GB VRAM GPU
Runs in the browser on Hugging Face
- 1
- other
- 2 d ago
mixed-gpu-llm-lab
Measured Qwen3.8 Flash Next and GLM5.3 Maya-M configurations, agent benchmarks, and reproduction guides on RTX 3090 + RTX 3060 + dual V100 GPUs.
- 2
- Python
- MIT
- 5 wk ago

