yolov8-live
A short script showing how to build simple real-time video analytics apps using YOLOv8 and Supervision. Try it out, and most importantly have fun! 🤪
- 90
- Python
- 3 y ago
A short script showing how to build simple real-time video analytics apps using YOLOv8 and Supervision. Try it out, and most importantly have fun! 🤪
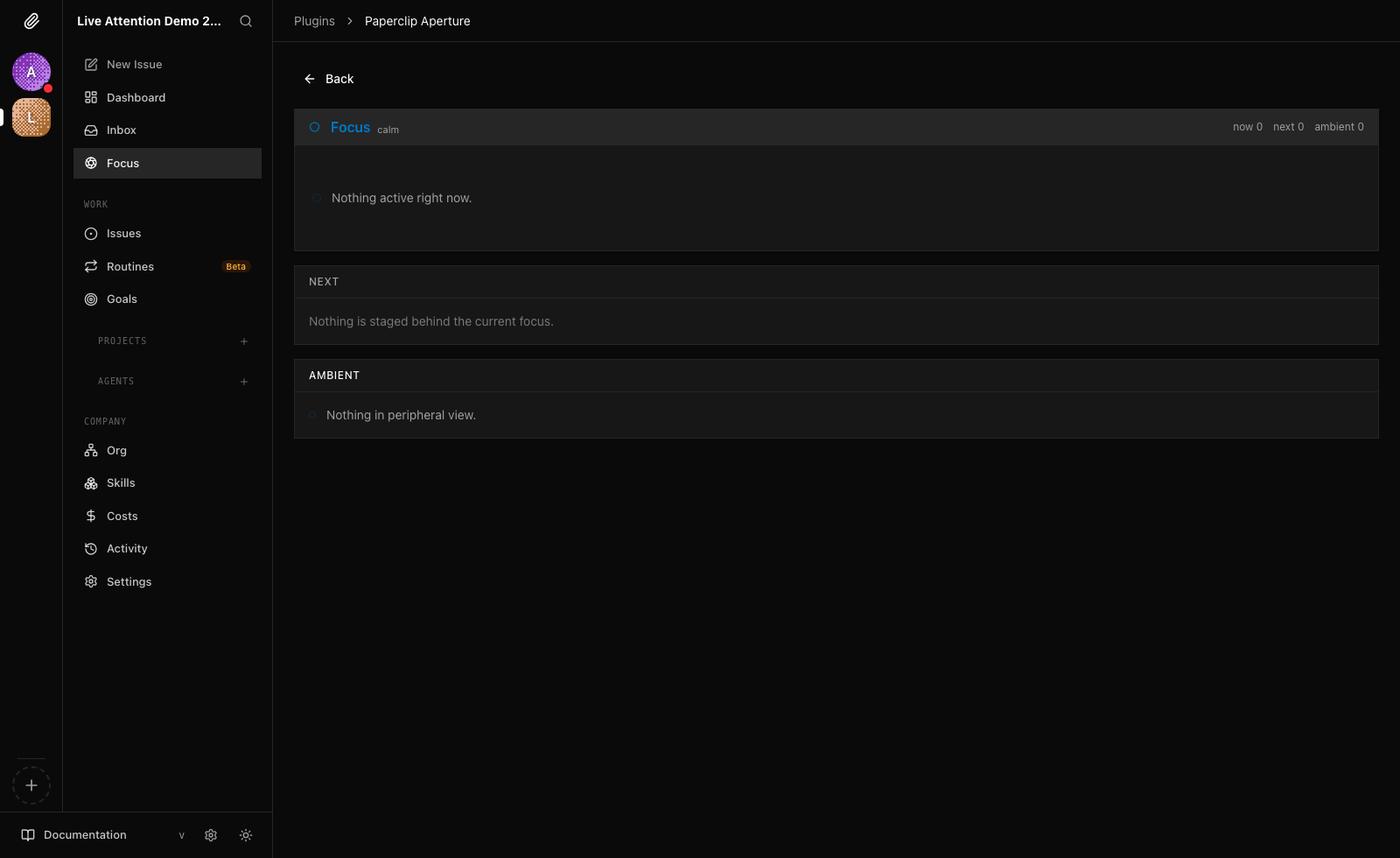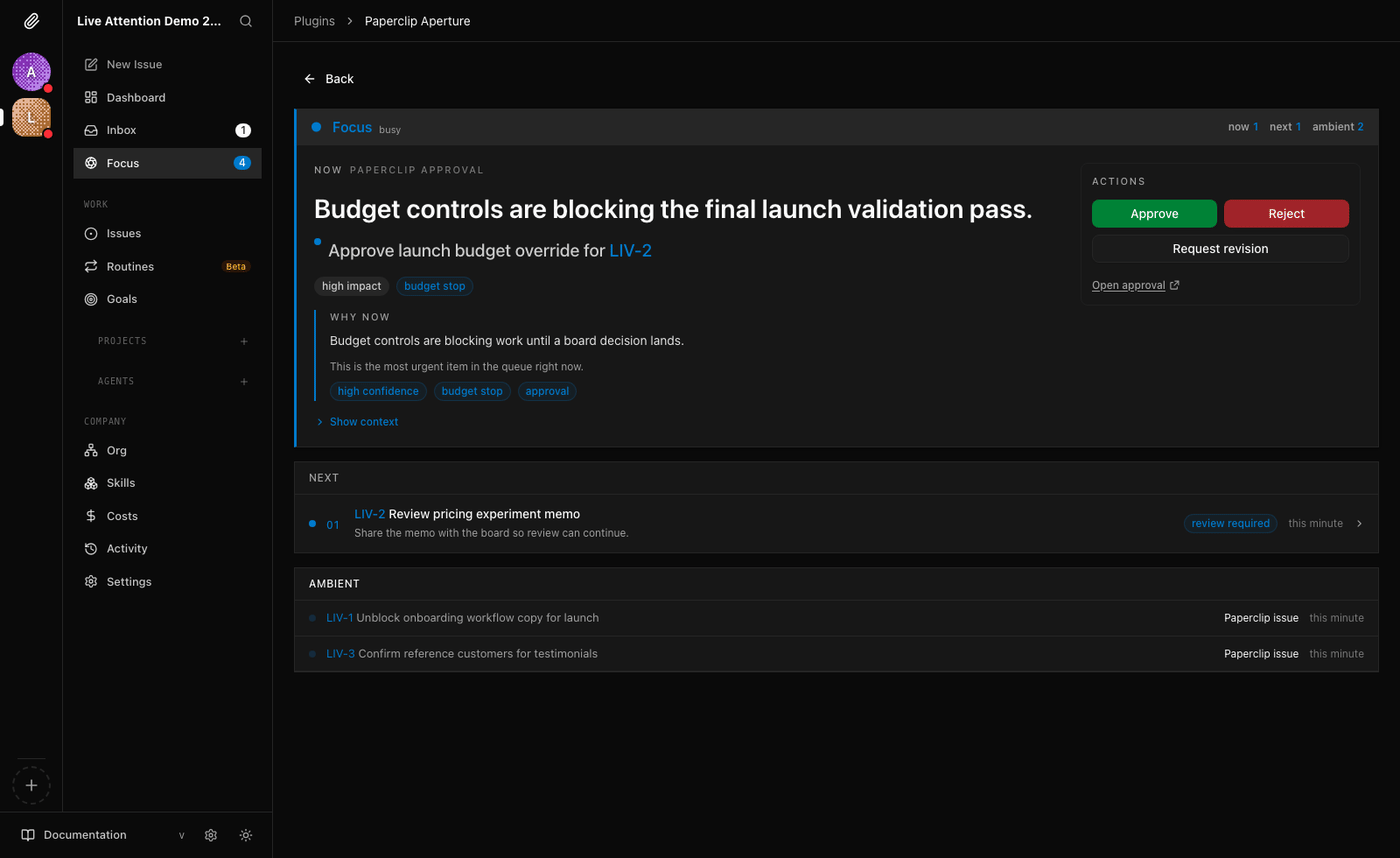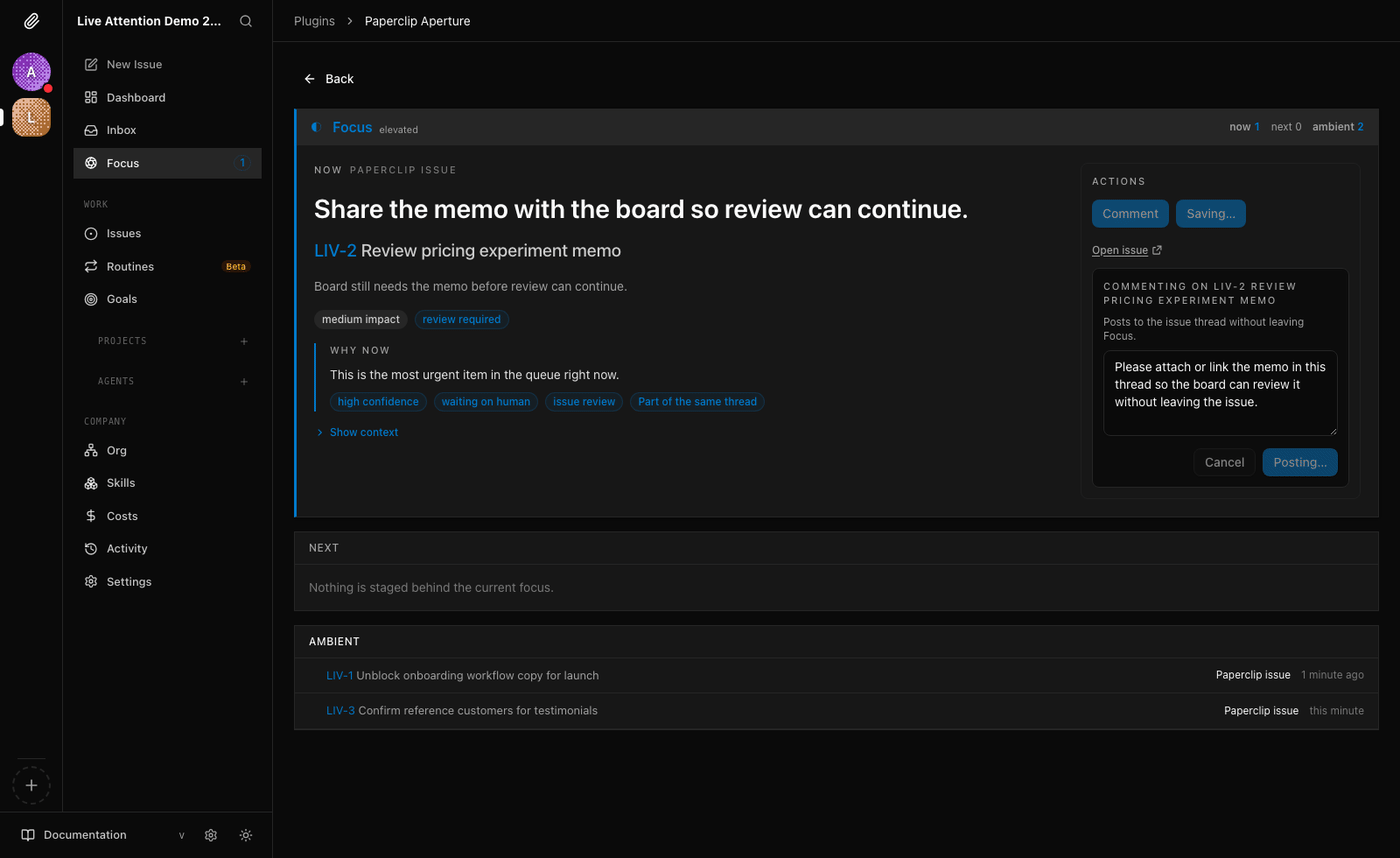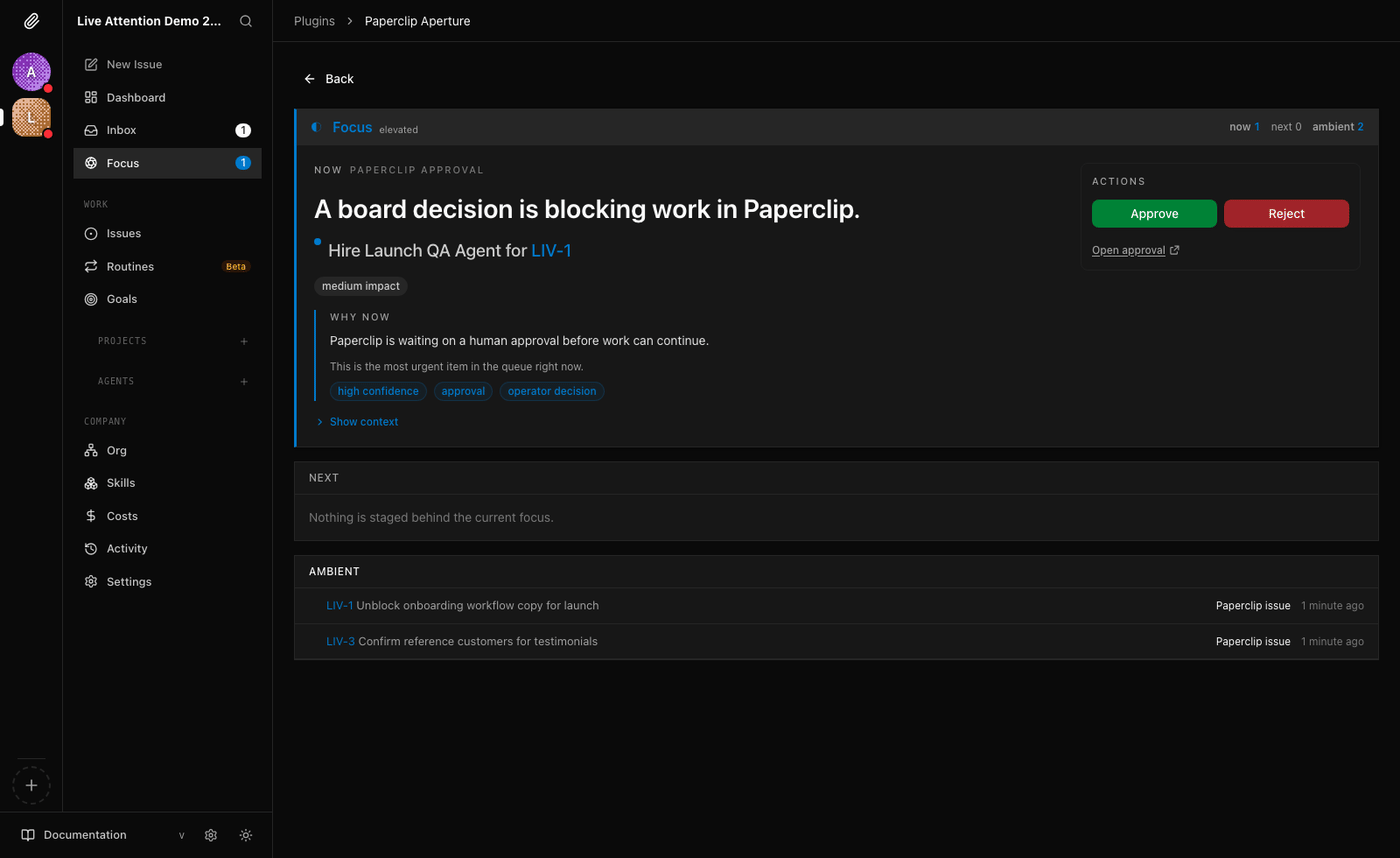
The live attention layer for Paperclip. Re-stacks approvals, issues, and agent signals into now, next, and ambient.
A Gradio-based demo application for comparing state-of-the-art OCR models: DeepSeek-OCR, Dots.OCR, HunyuanOCR, and Nanonets-OCR2-3B.
SAM3-Gemma4-CUDA is an experimental computer vision and multimodal reasoning application that combines Facebook's Segment Anything Model 3 (SAM3) with Gemma 4 multimodal model. This suite offers a comprehensive interactive web interface for high-precision image object detection, video segmentation, and interactive click-based tracking.
Qwen3-VL-HF-Demo is an experimental visual reasoning, spatial grounding, and object detection workspace built around Alibaba's state-of-the-art Qwen/Qwen3-VL-8B-Instruct multimodal foundation model.
Qwen3-VL-4B-Instruct model from Alibaba's Qwen series for multimodal tasks involving images and text. It enables users to upload an image and perform various vision-language tasks, such as querying details, generating captions, detecting points of interest.
SAM3-Plus-Qwen3.5 is an advanced, experimental computer vision suite that seamlessly integrates Facebook's Segment Anything Model 3 (SAM3) with the Qwen3.5 multimodal reasoning engine.
Qwen-3.5-HF-Demo is an experimental, advanced multimodal intelligence interface built on top of Alibaba Cloud's state-of-the-art Qwen/Qwen3.5-2B foundation model. Designed as a flexible multi-modal sandbox, this application unifies four complex spatial and temporal reasoning workflows: Image Understanding, Video Question Answering.
Visual-Grounding-Anything is a comprehensive suite of applications designed for precise object detection, pointing, and tracking in both images and videos. Leveraging the Polaris-VGA-4B model, the system provides high-accuracy spatial reasoning and temporal association across various visual tasks.