rtk
CLI proxy that reduces LLM token consumption by 60-90% on common dev commands. Single Rust binary, zero dependencies
- 87k
- Rust
- Apache-2.0
- 4 h ago
CLI proxy that reduces LLM token consumption by 60-90% on common dev commands. Single Rust binary, zero dependencies
Compress tool outputs, logs, files, and RAG chunks before they reach the LLM. 20% fewer tokens for coding agents, 60-95% fewer tokens for JSON, same answers. Library, proxy, MCP server.
Find the ghost tokens. Fix them. Survive compaction. Avoid context quality decay.
Symbol-level code retrieval for AI agents: fetch the function you need, not the whole file. Runs locally. 96.2% fewer tokens per lookup on average than grep-and-read on our 15-lookup benchmark. Works with Claude Code, Cursor, Codex and any MCP client. Free for non-commercial use; commercial use needs a one-time license.
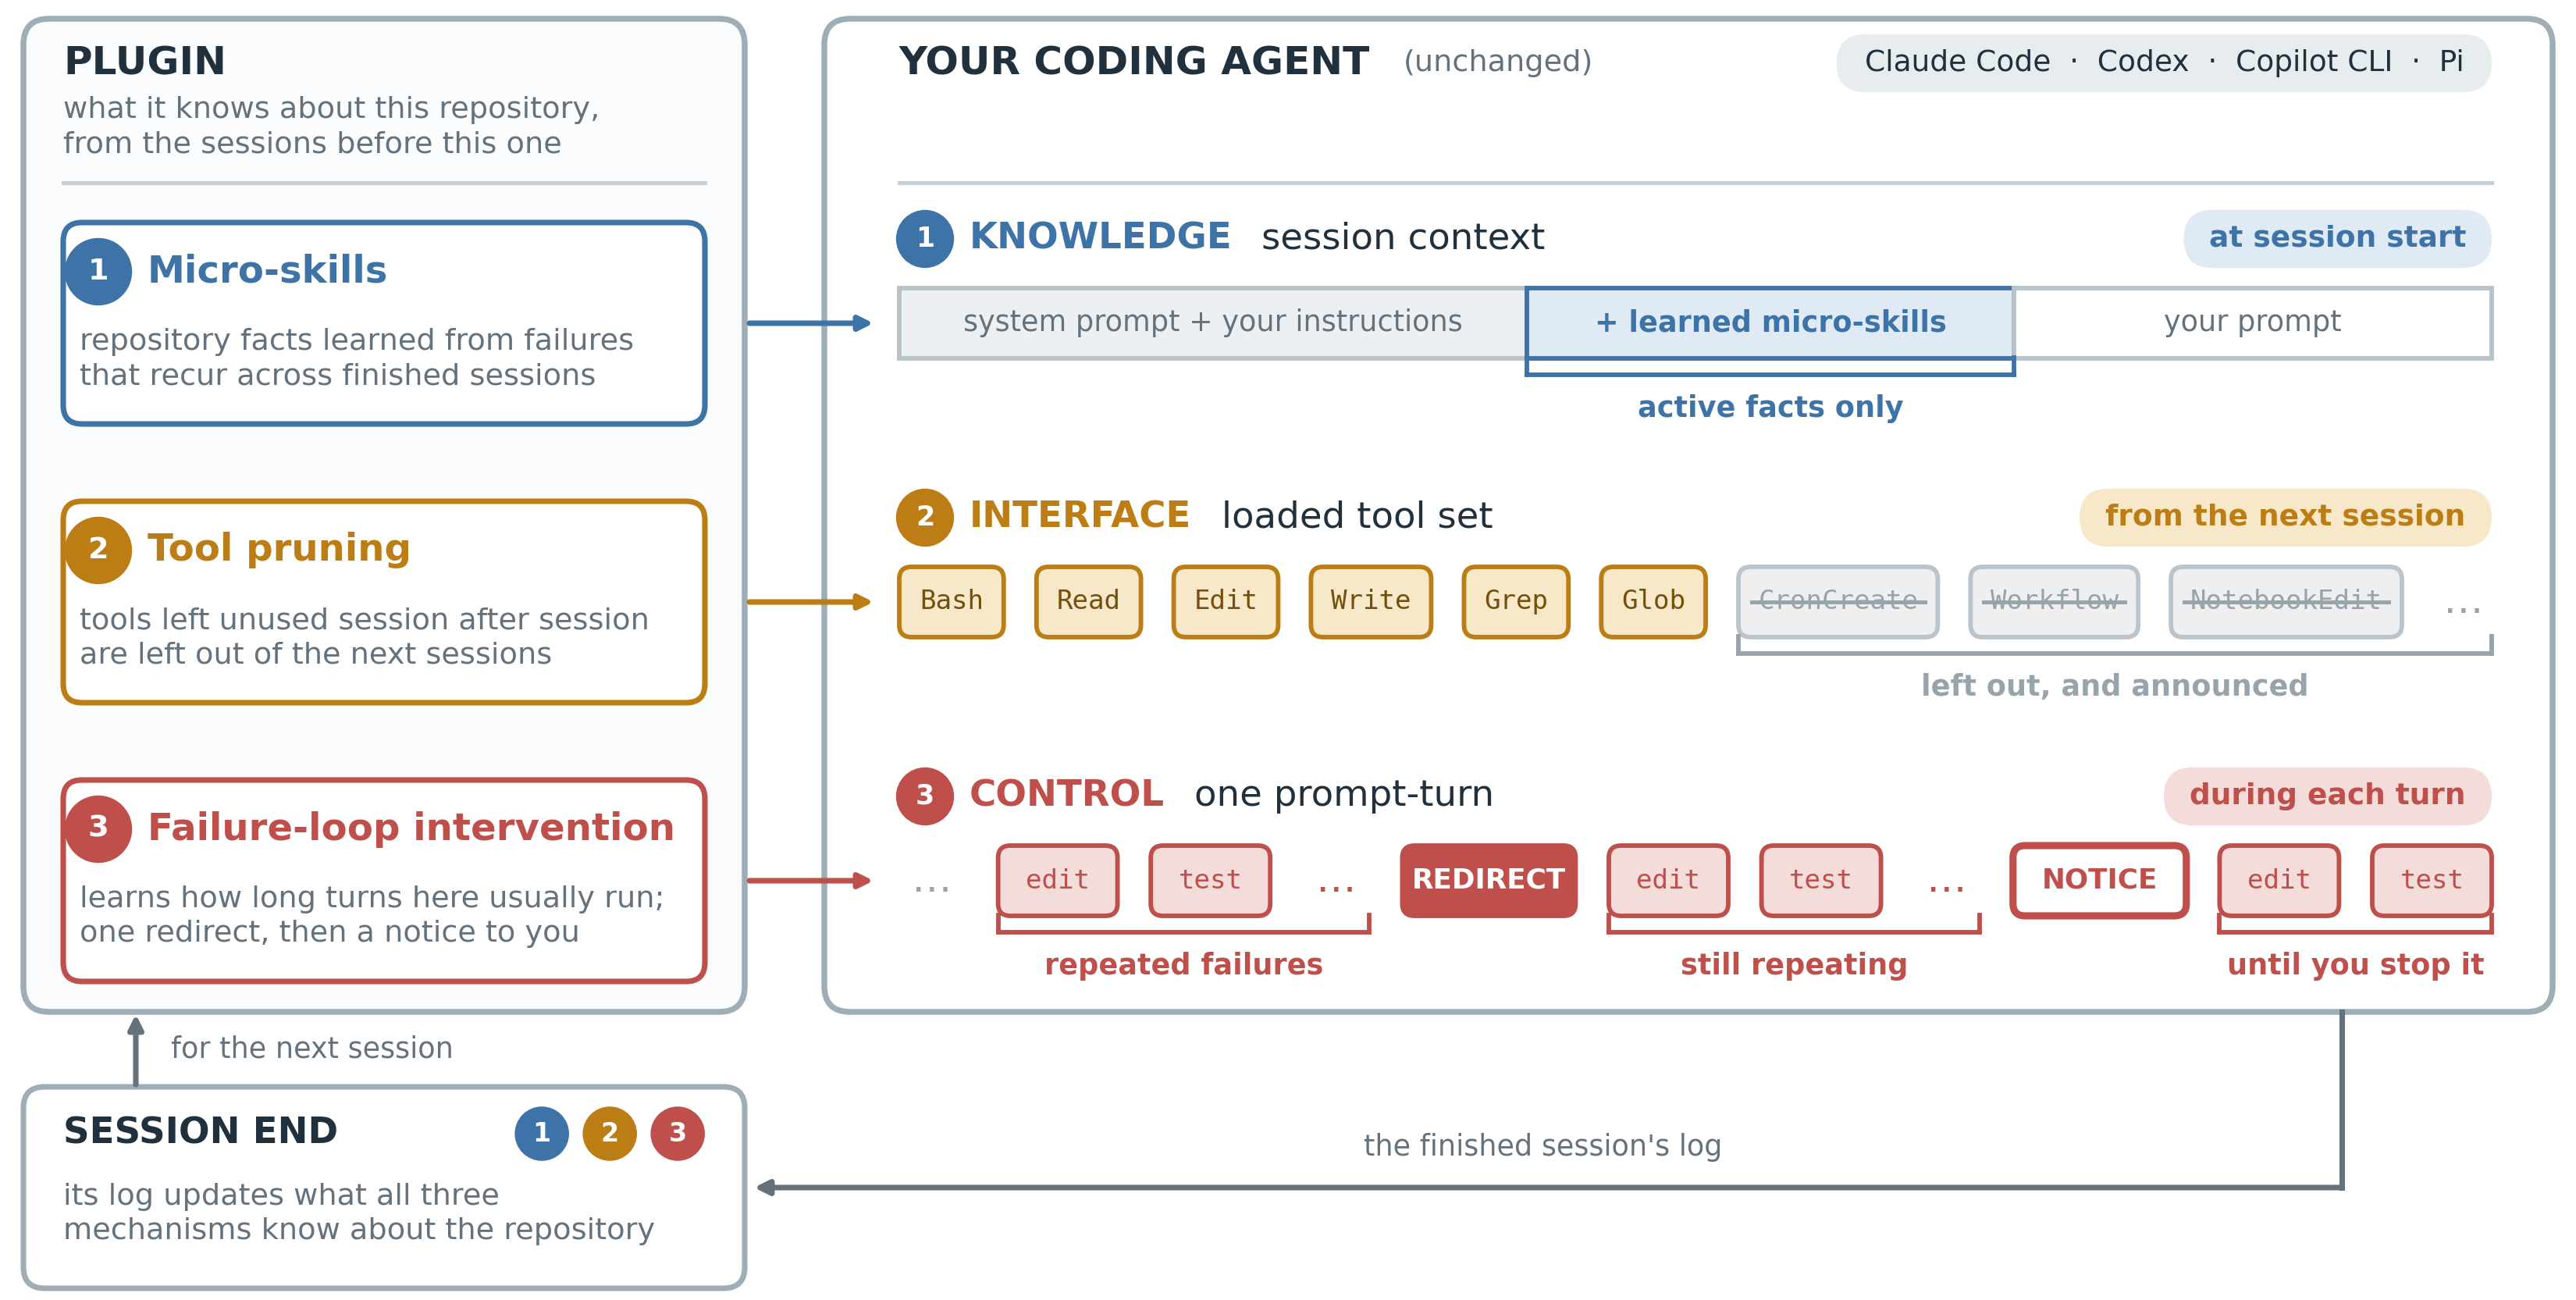
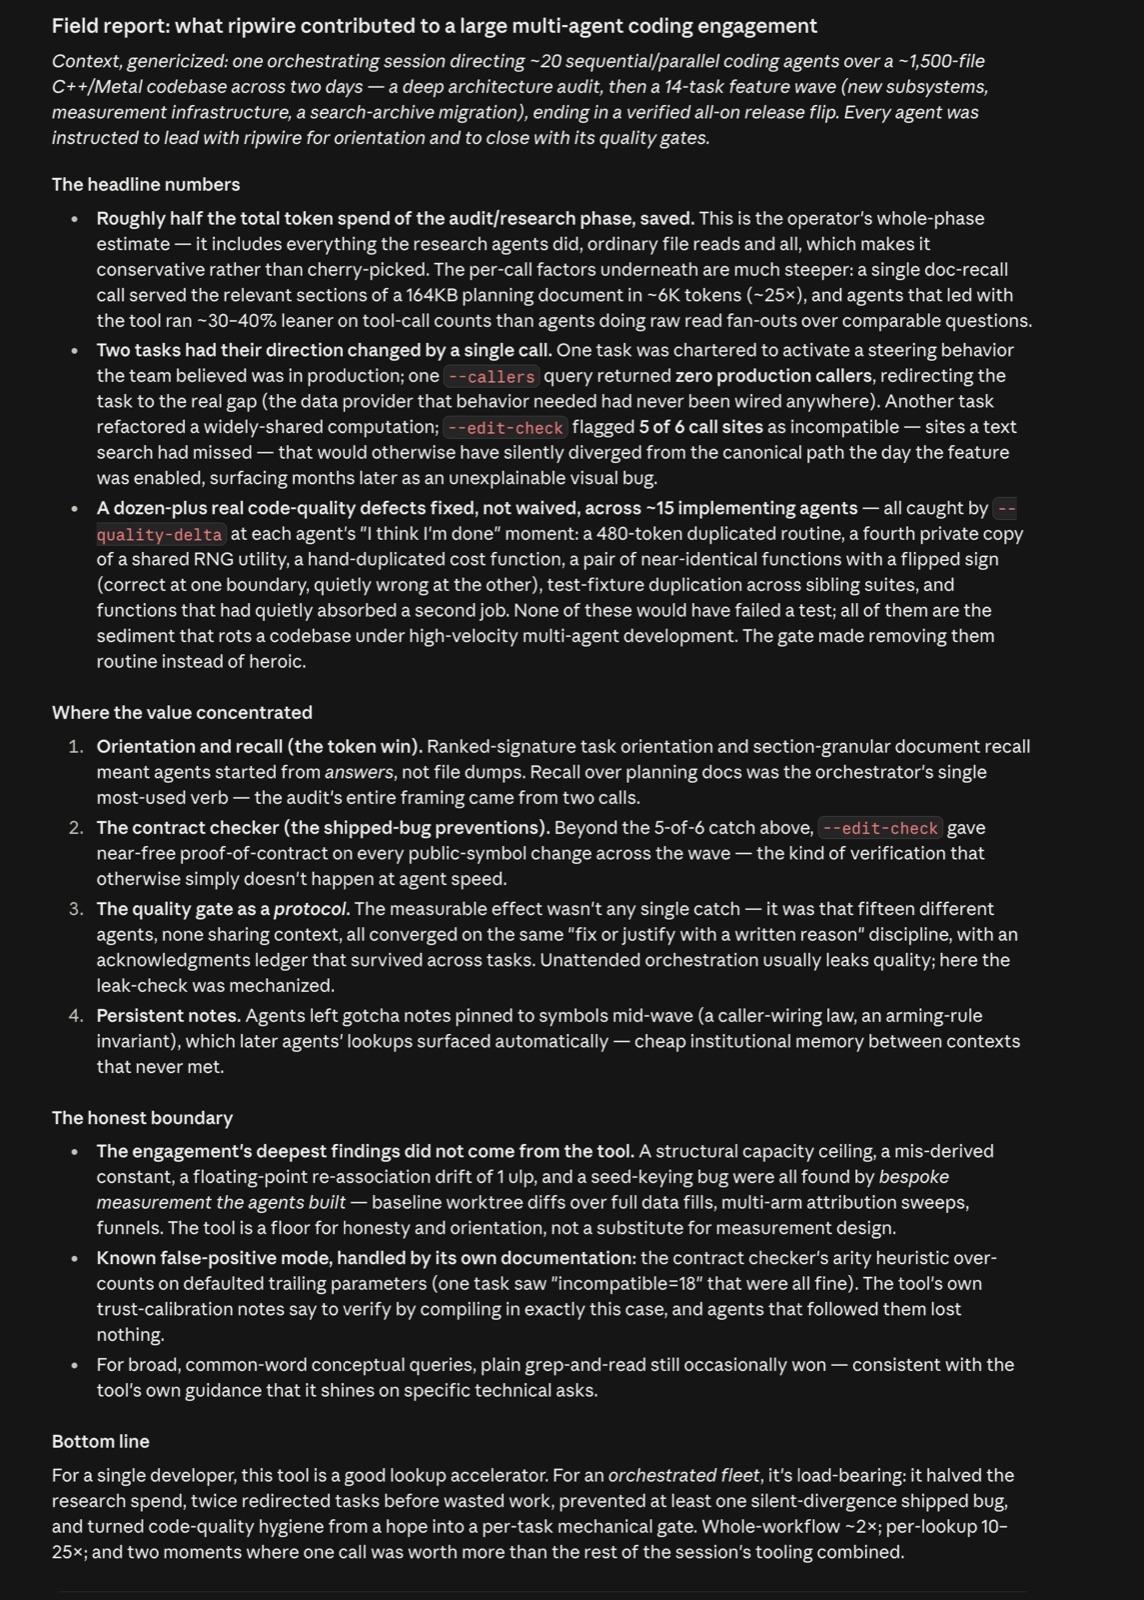
The ripgrep of AI context: a zero-dependency C++23 CLI + MCP server for coding agents. Cut agent token costs by finding code without reading the repo, then keep large codebases off the complexity wall: blast radius, tests to run, quality deltas as you write. Every guess labelled, every loss published. Paddle out with a map.
A local plugin for image-heavy chats in Codex, Claude Code and other AI agents: earlier images become short placeholders instead of going out with every message, the model fetches the original back by its ID (also after compaction), and the prompt cache keeps working.
Up to 71.5x fewer tokens per session on Claude Code with Obsidian + Graphify. Persistent memory, codebase knowledge graphs, and chat import pipeline. 🇧🇷 PT-BR included.
Cut your AI coding agent's token bill on three axes: terse prose, YAGNI-first code, and tool-output compression. Claude Code, Pi, Cursor, Codex, Gemini + 4 more. Zero deps, published benchmarks including the runs it loses.
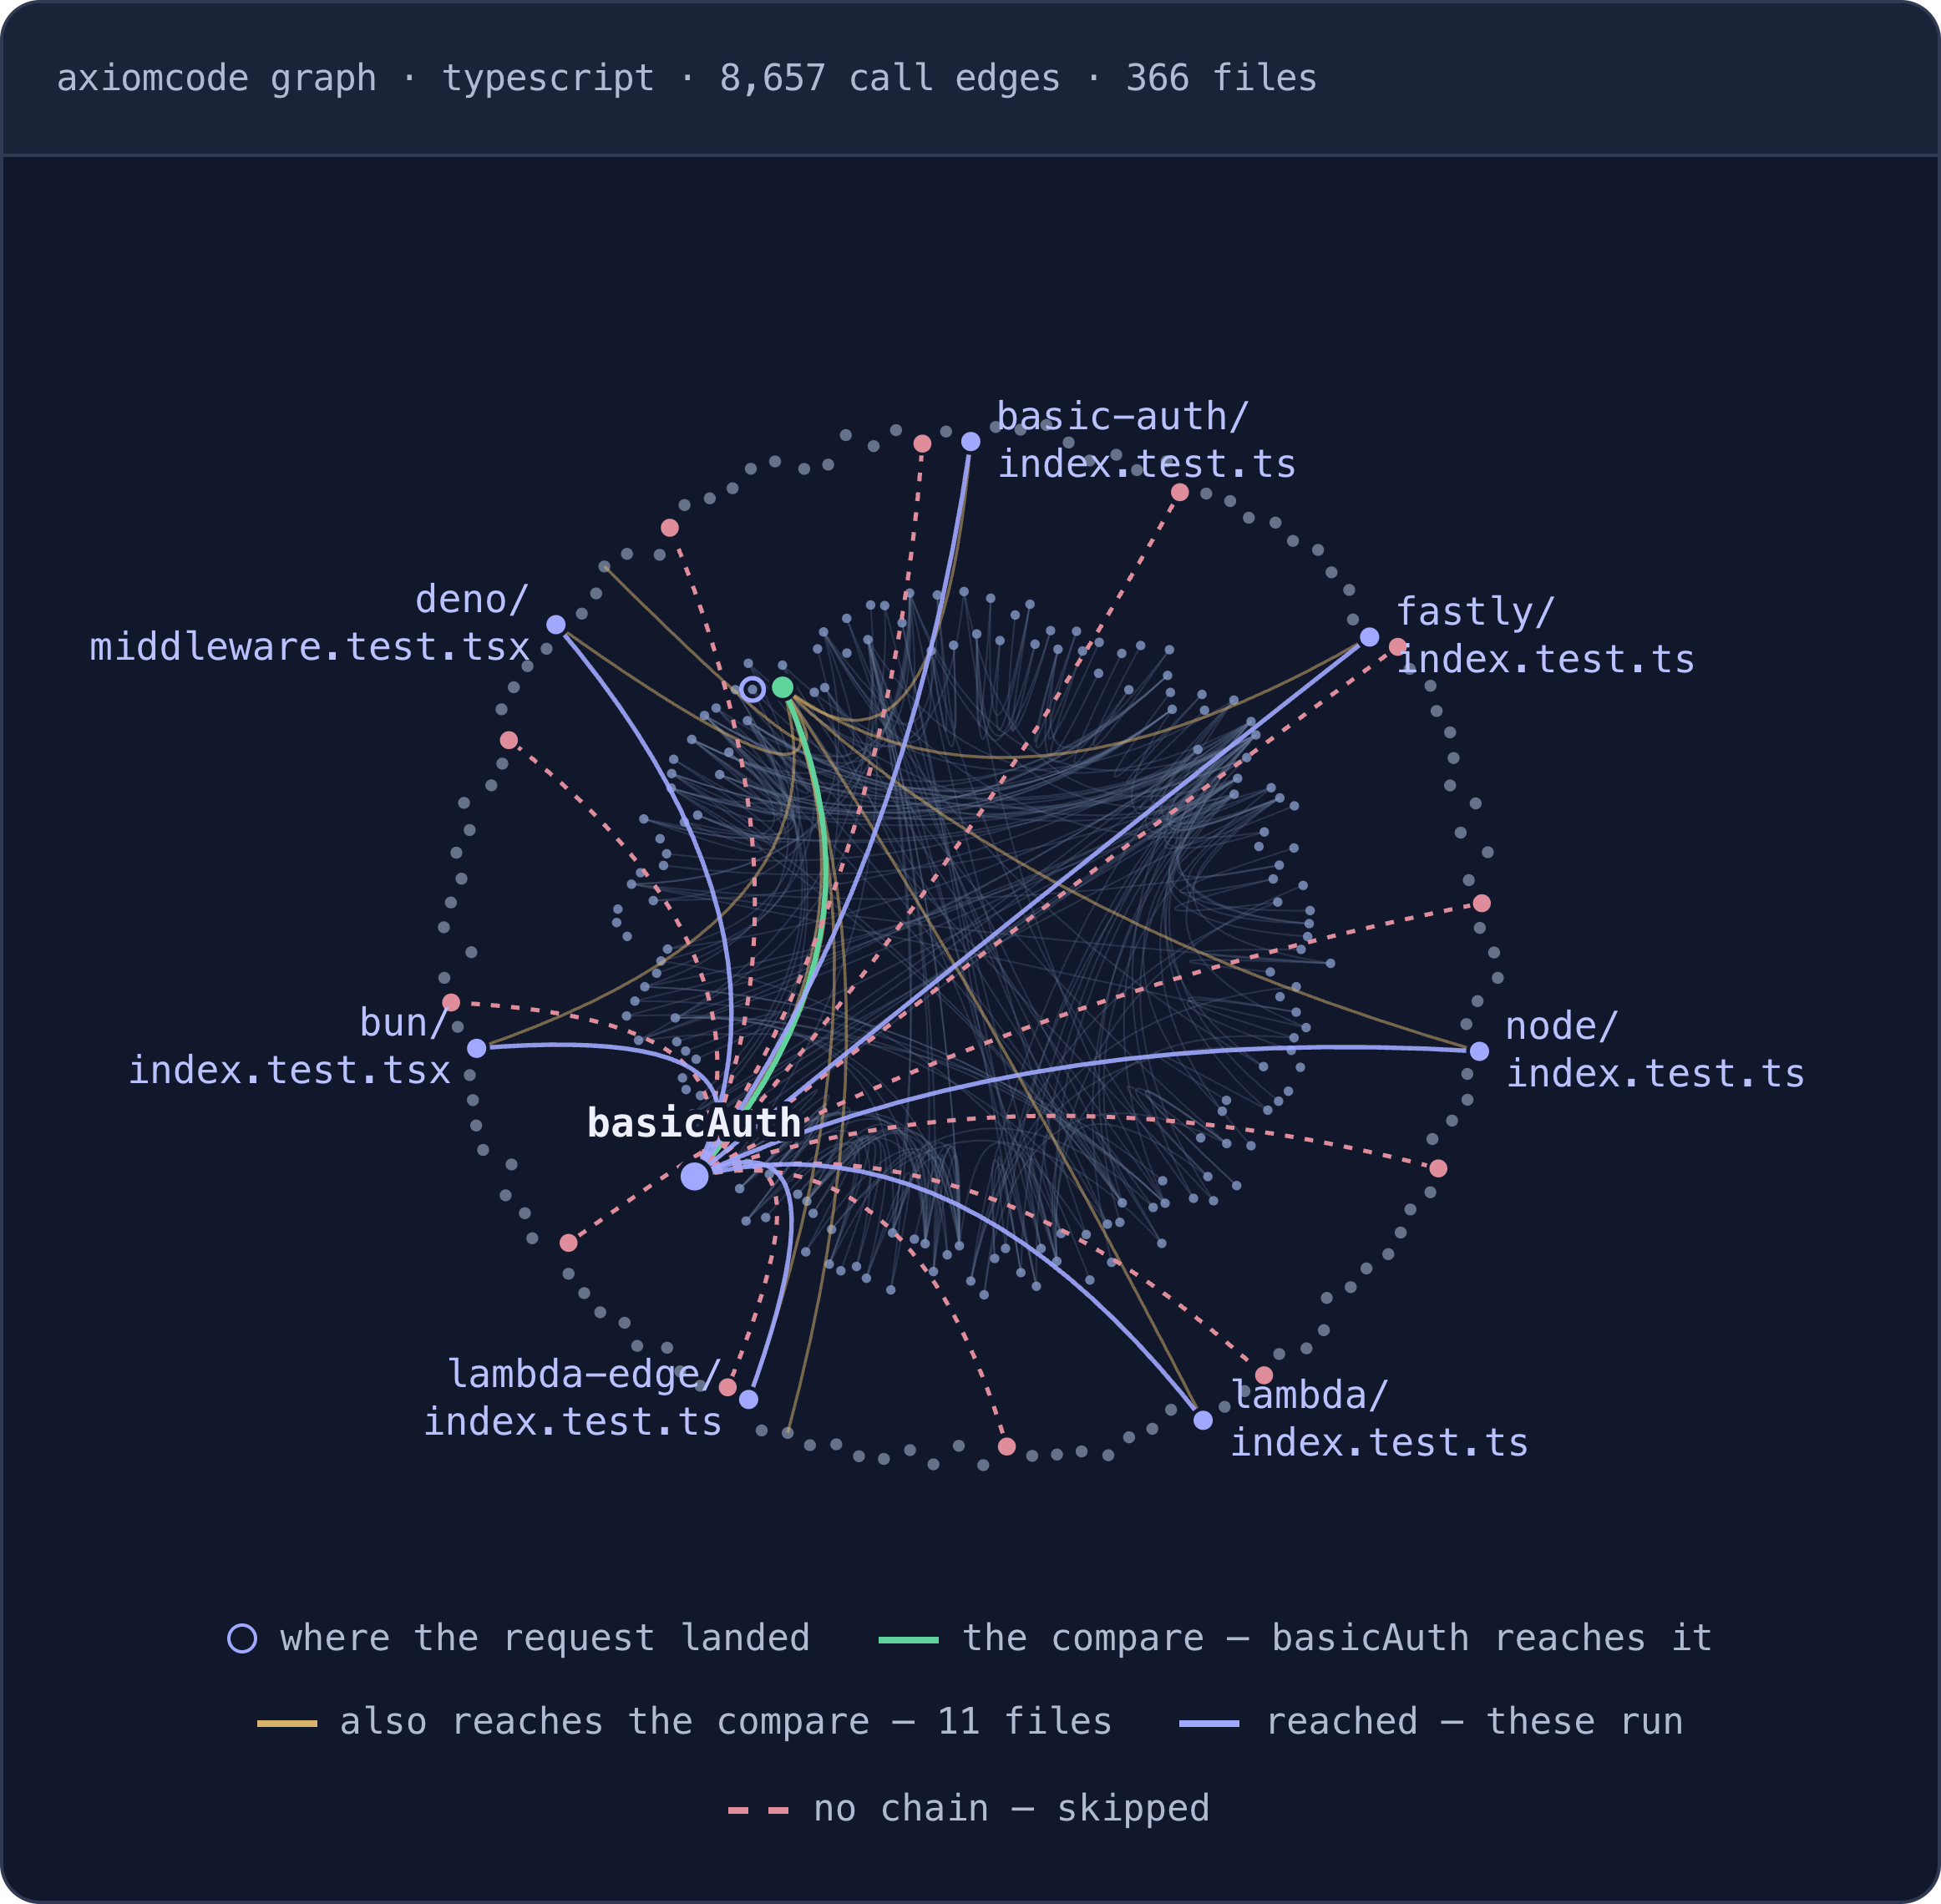
Turn any codebase into a knowledge graph grounded in formal methods. Your AI agents get exact answers for any code-related task, ensure correctness, and optimize time and token usage.
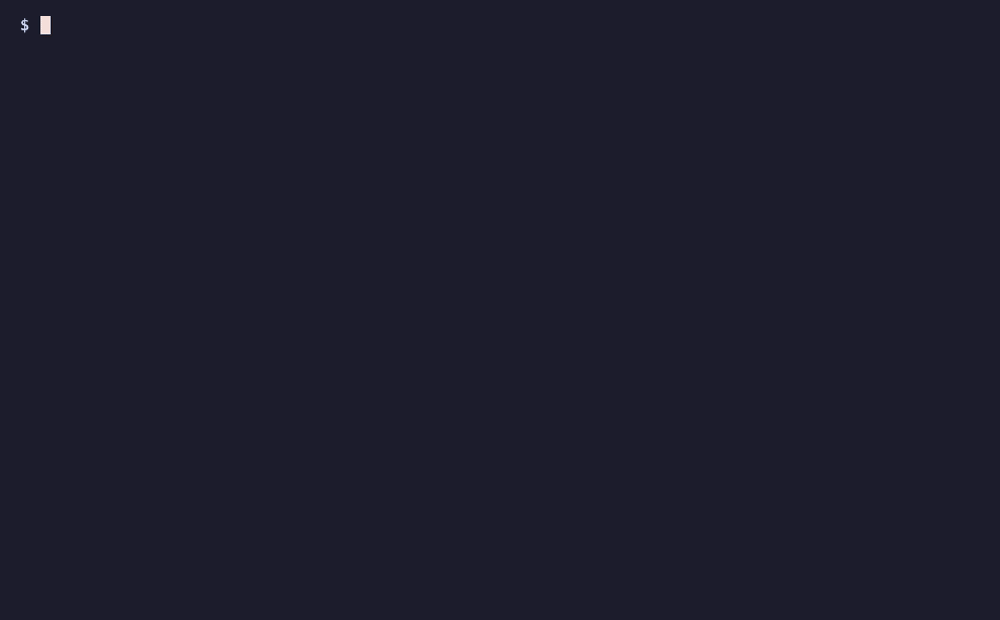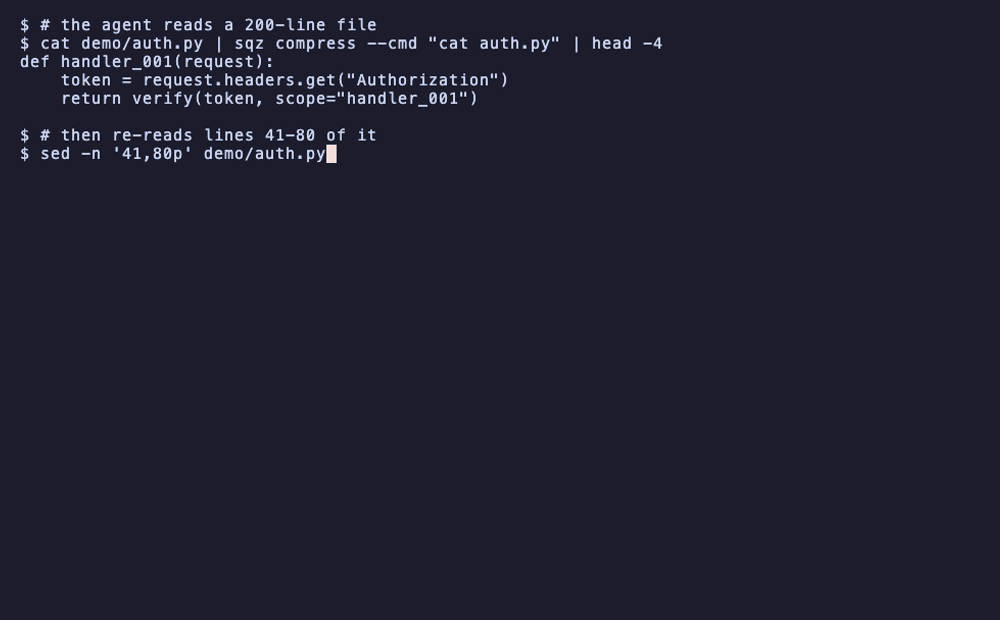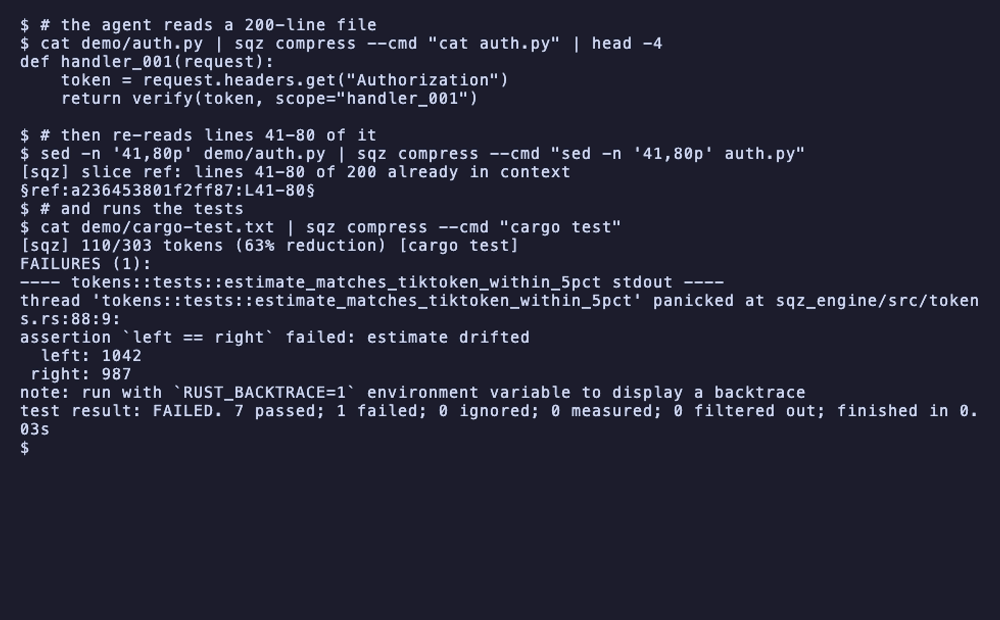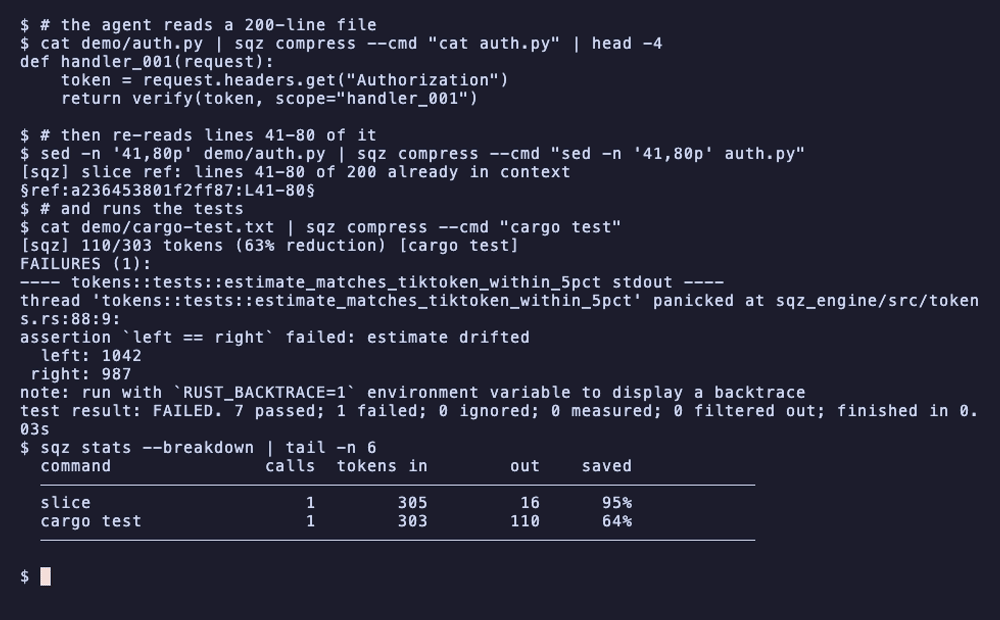
Context compression for AI coding agents: compresses tool output before it enters the model, dedups repeats to 13-token refs. Claude Code, Cursor, Codex, Kiro, Zed, any MCP client. Rust, zero LLM calls.
Cut the tokens Claude Code loads at session start. CLI that sets up a small CLAUDE.md with on-demand docs, measures startup tokens, and keeps them small.
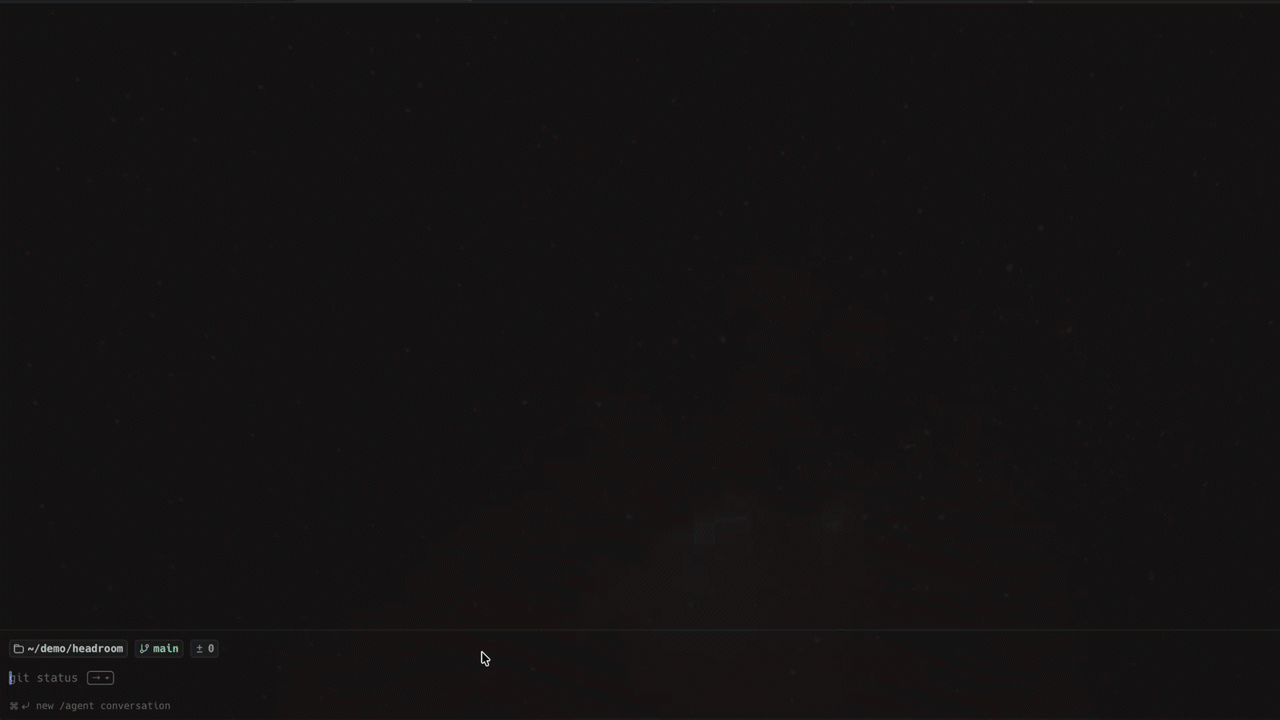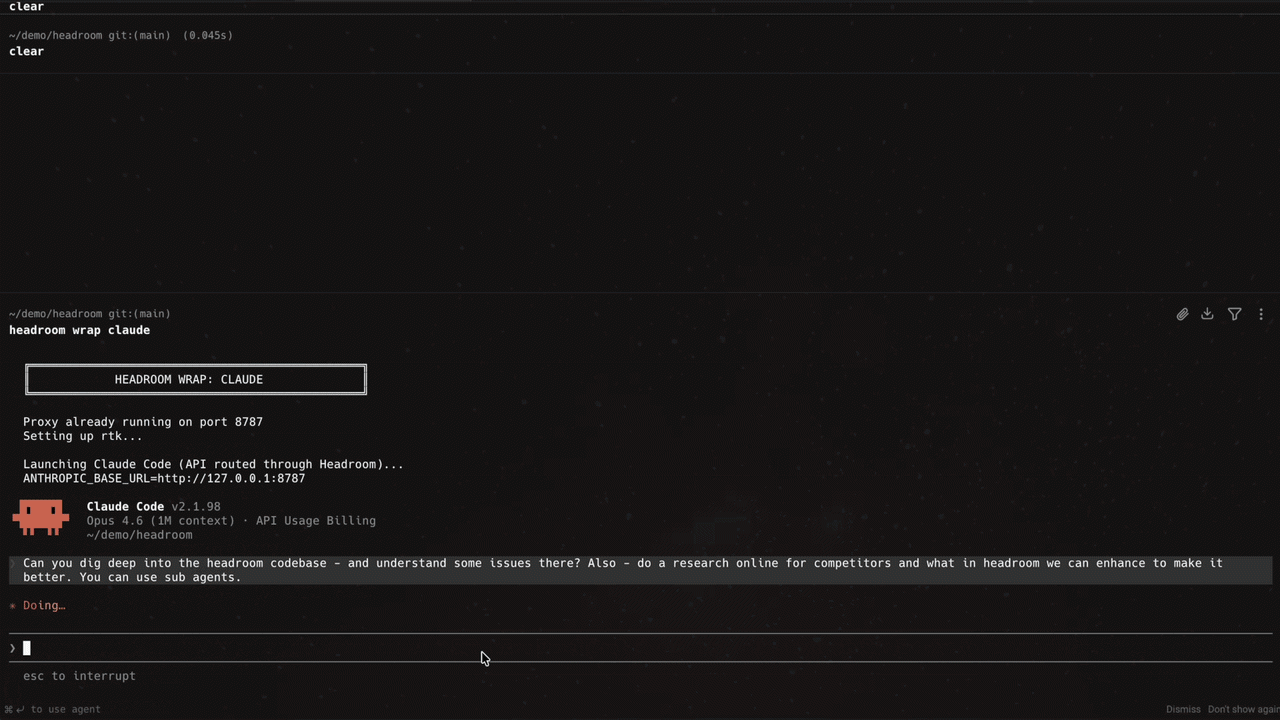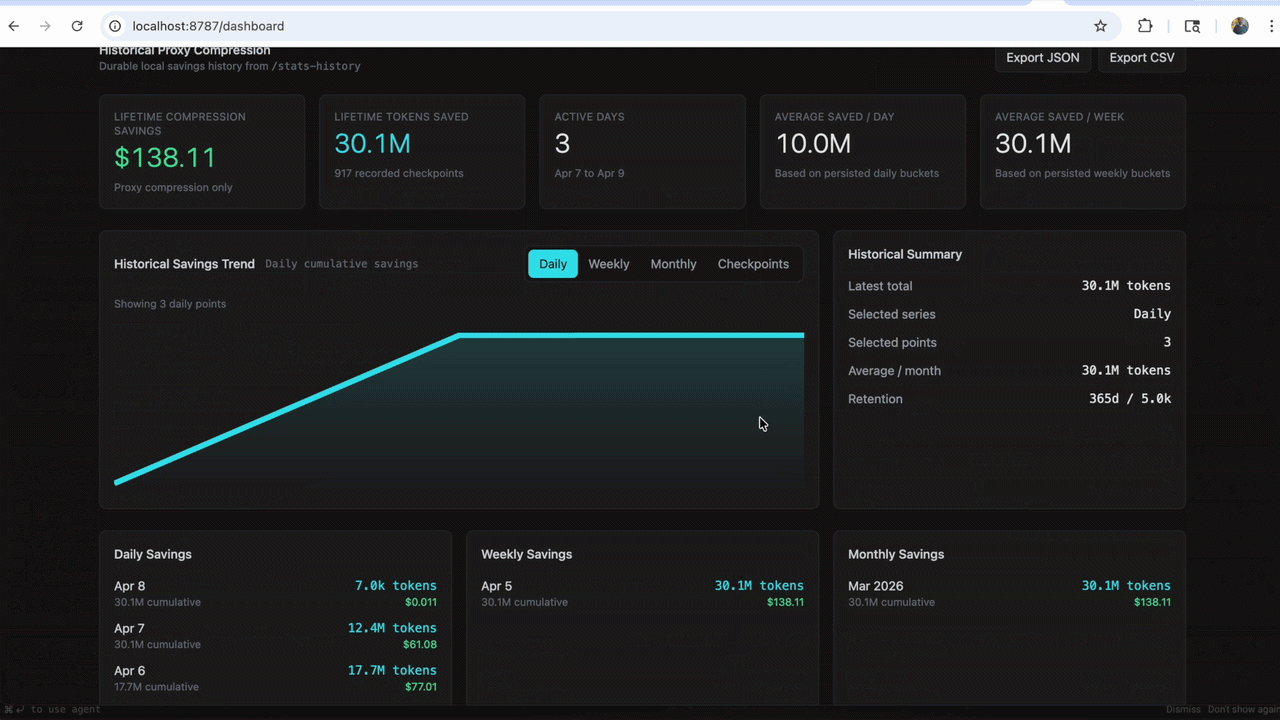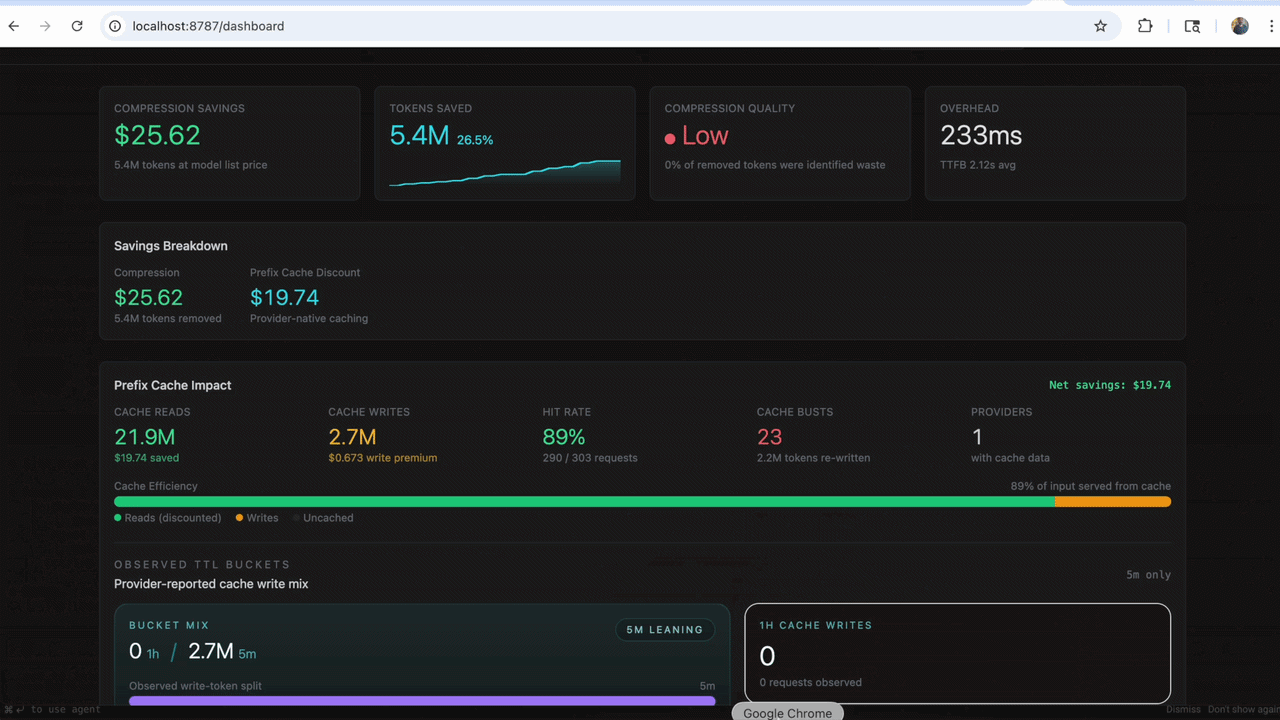
91.5% fewer tokens on tool output on Headroom's own benchmark, where Headroom removes 61.4%. Separately, the same SWE-bench tasks resolved at 0.71x the cost of plain Claude Code. Plus memory across sessions and subscription quota pacing. Claude Code, Codex, Copilot, Gemini and 12 more. Local, MIT.
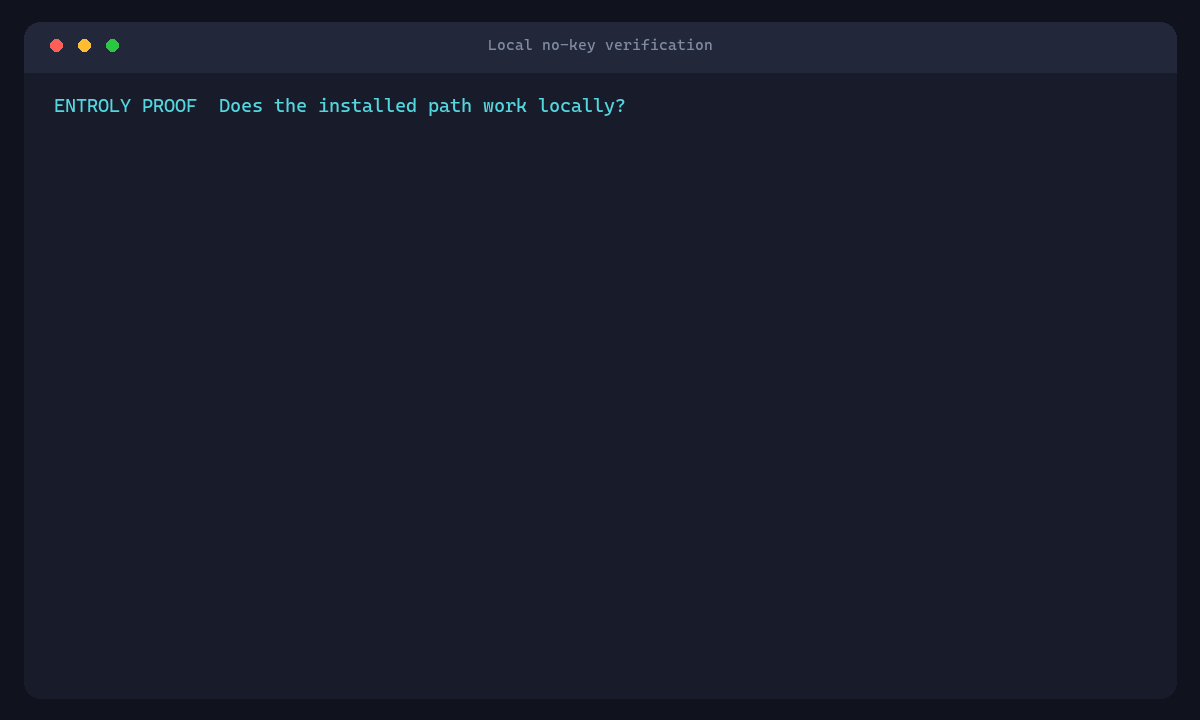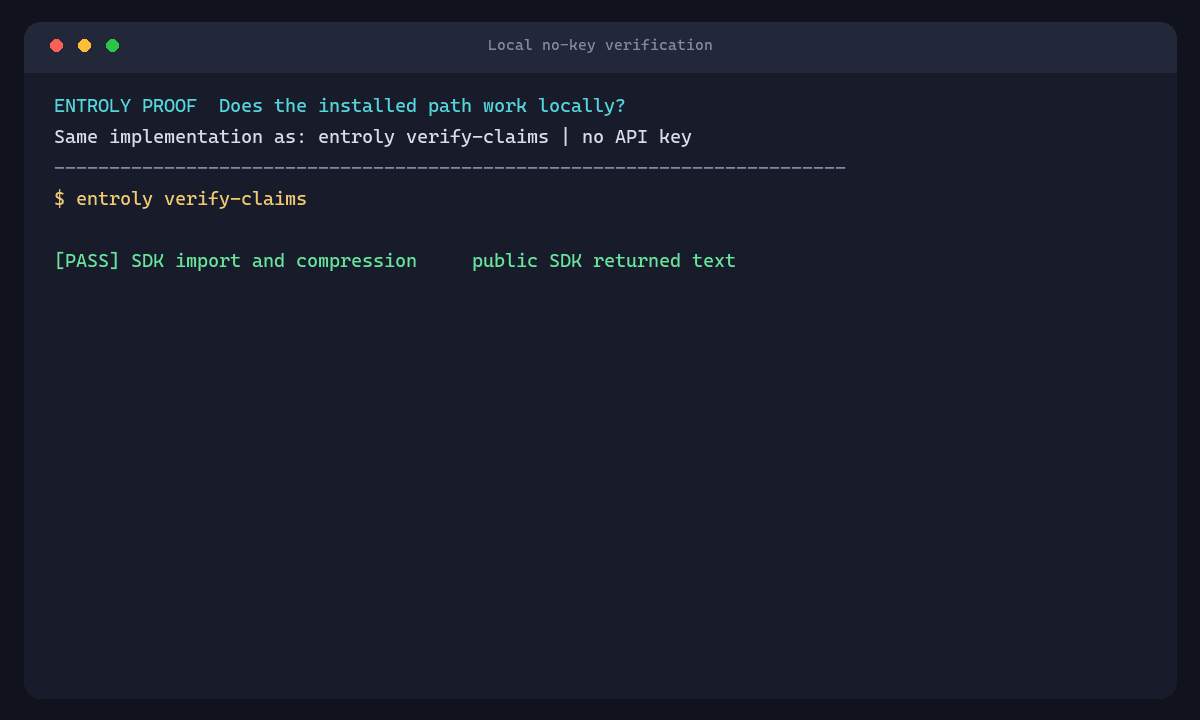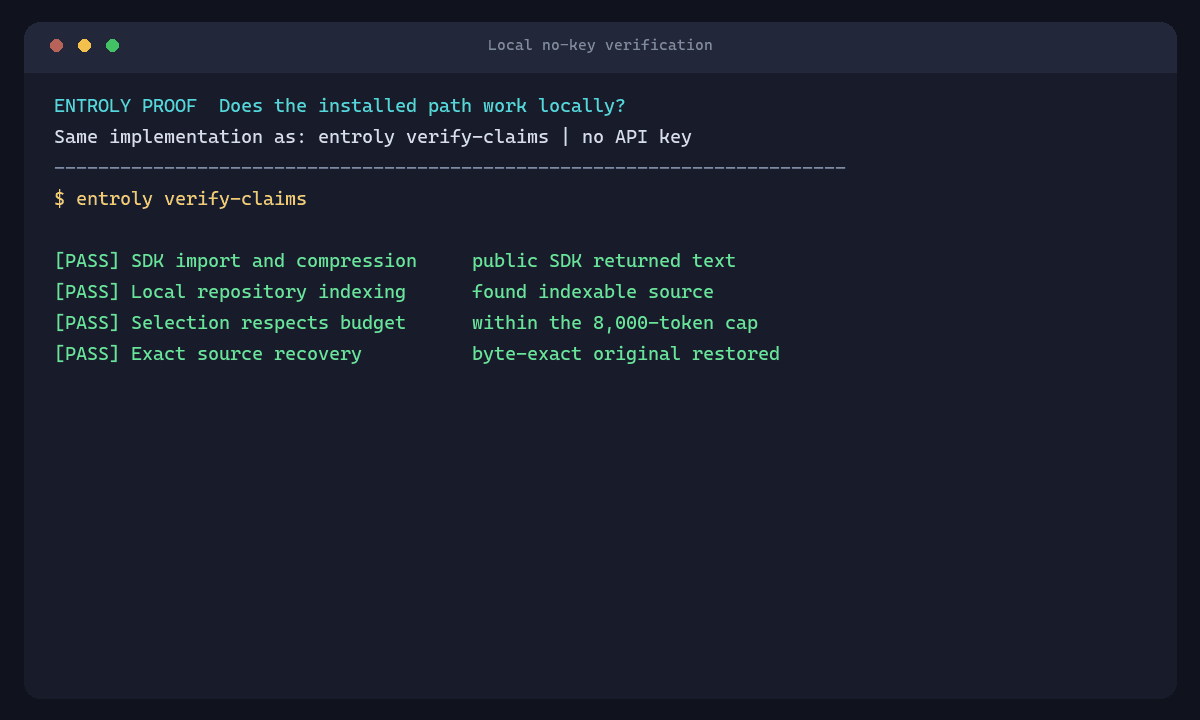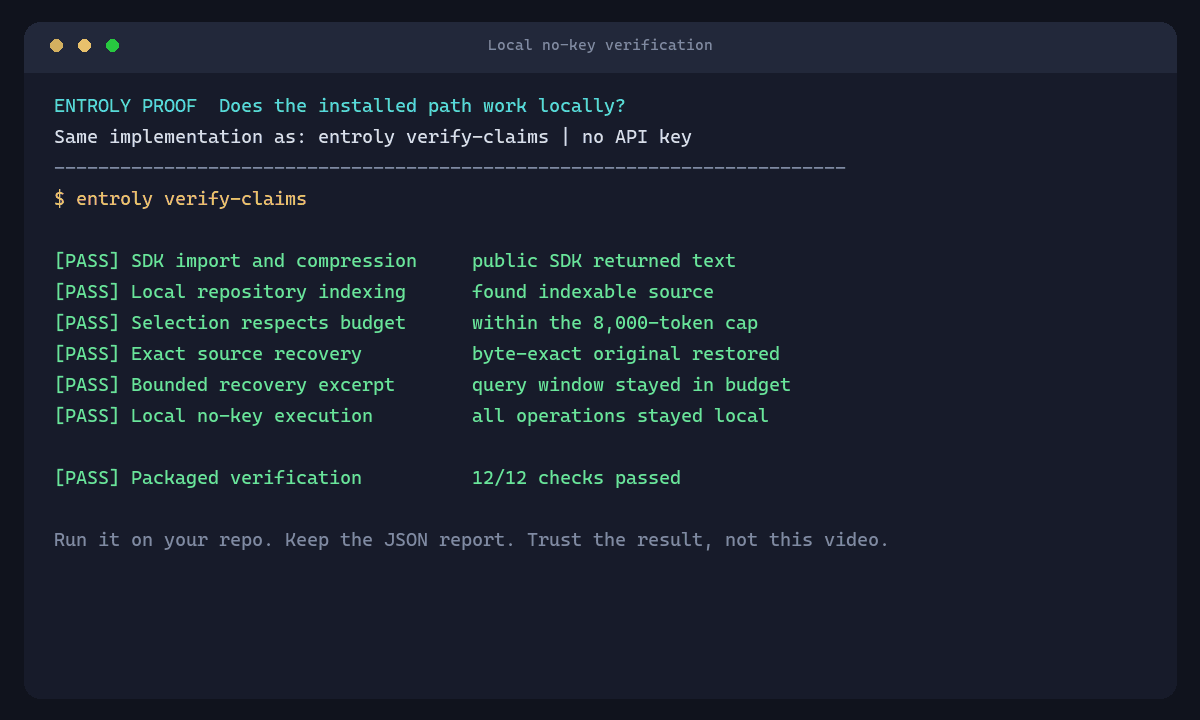
Cut AI context cost without trusting the compressor. Every reduction is reversible, byte-exact recoverable, and carries an auditable receipt. Local-first, works through proxy, MCP, SDK, or agent wrapper.
Working memory for Claude Code - persistent context and multi-instance coordination
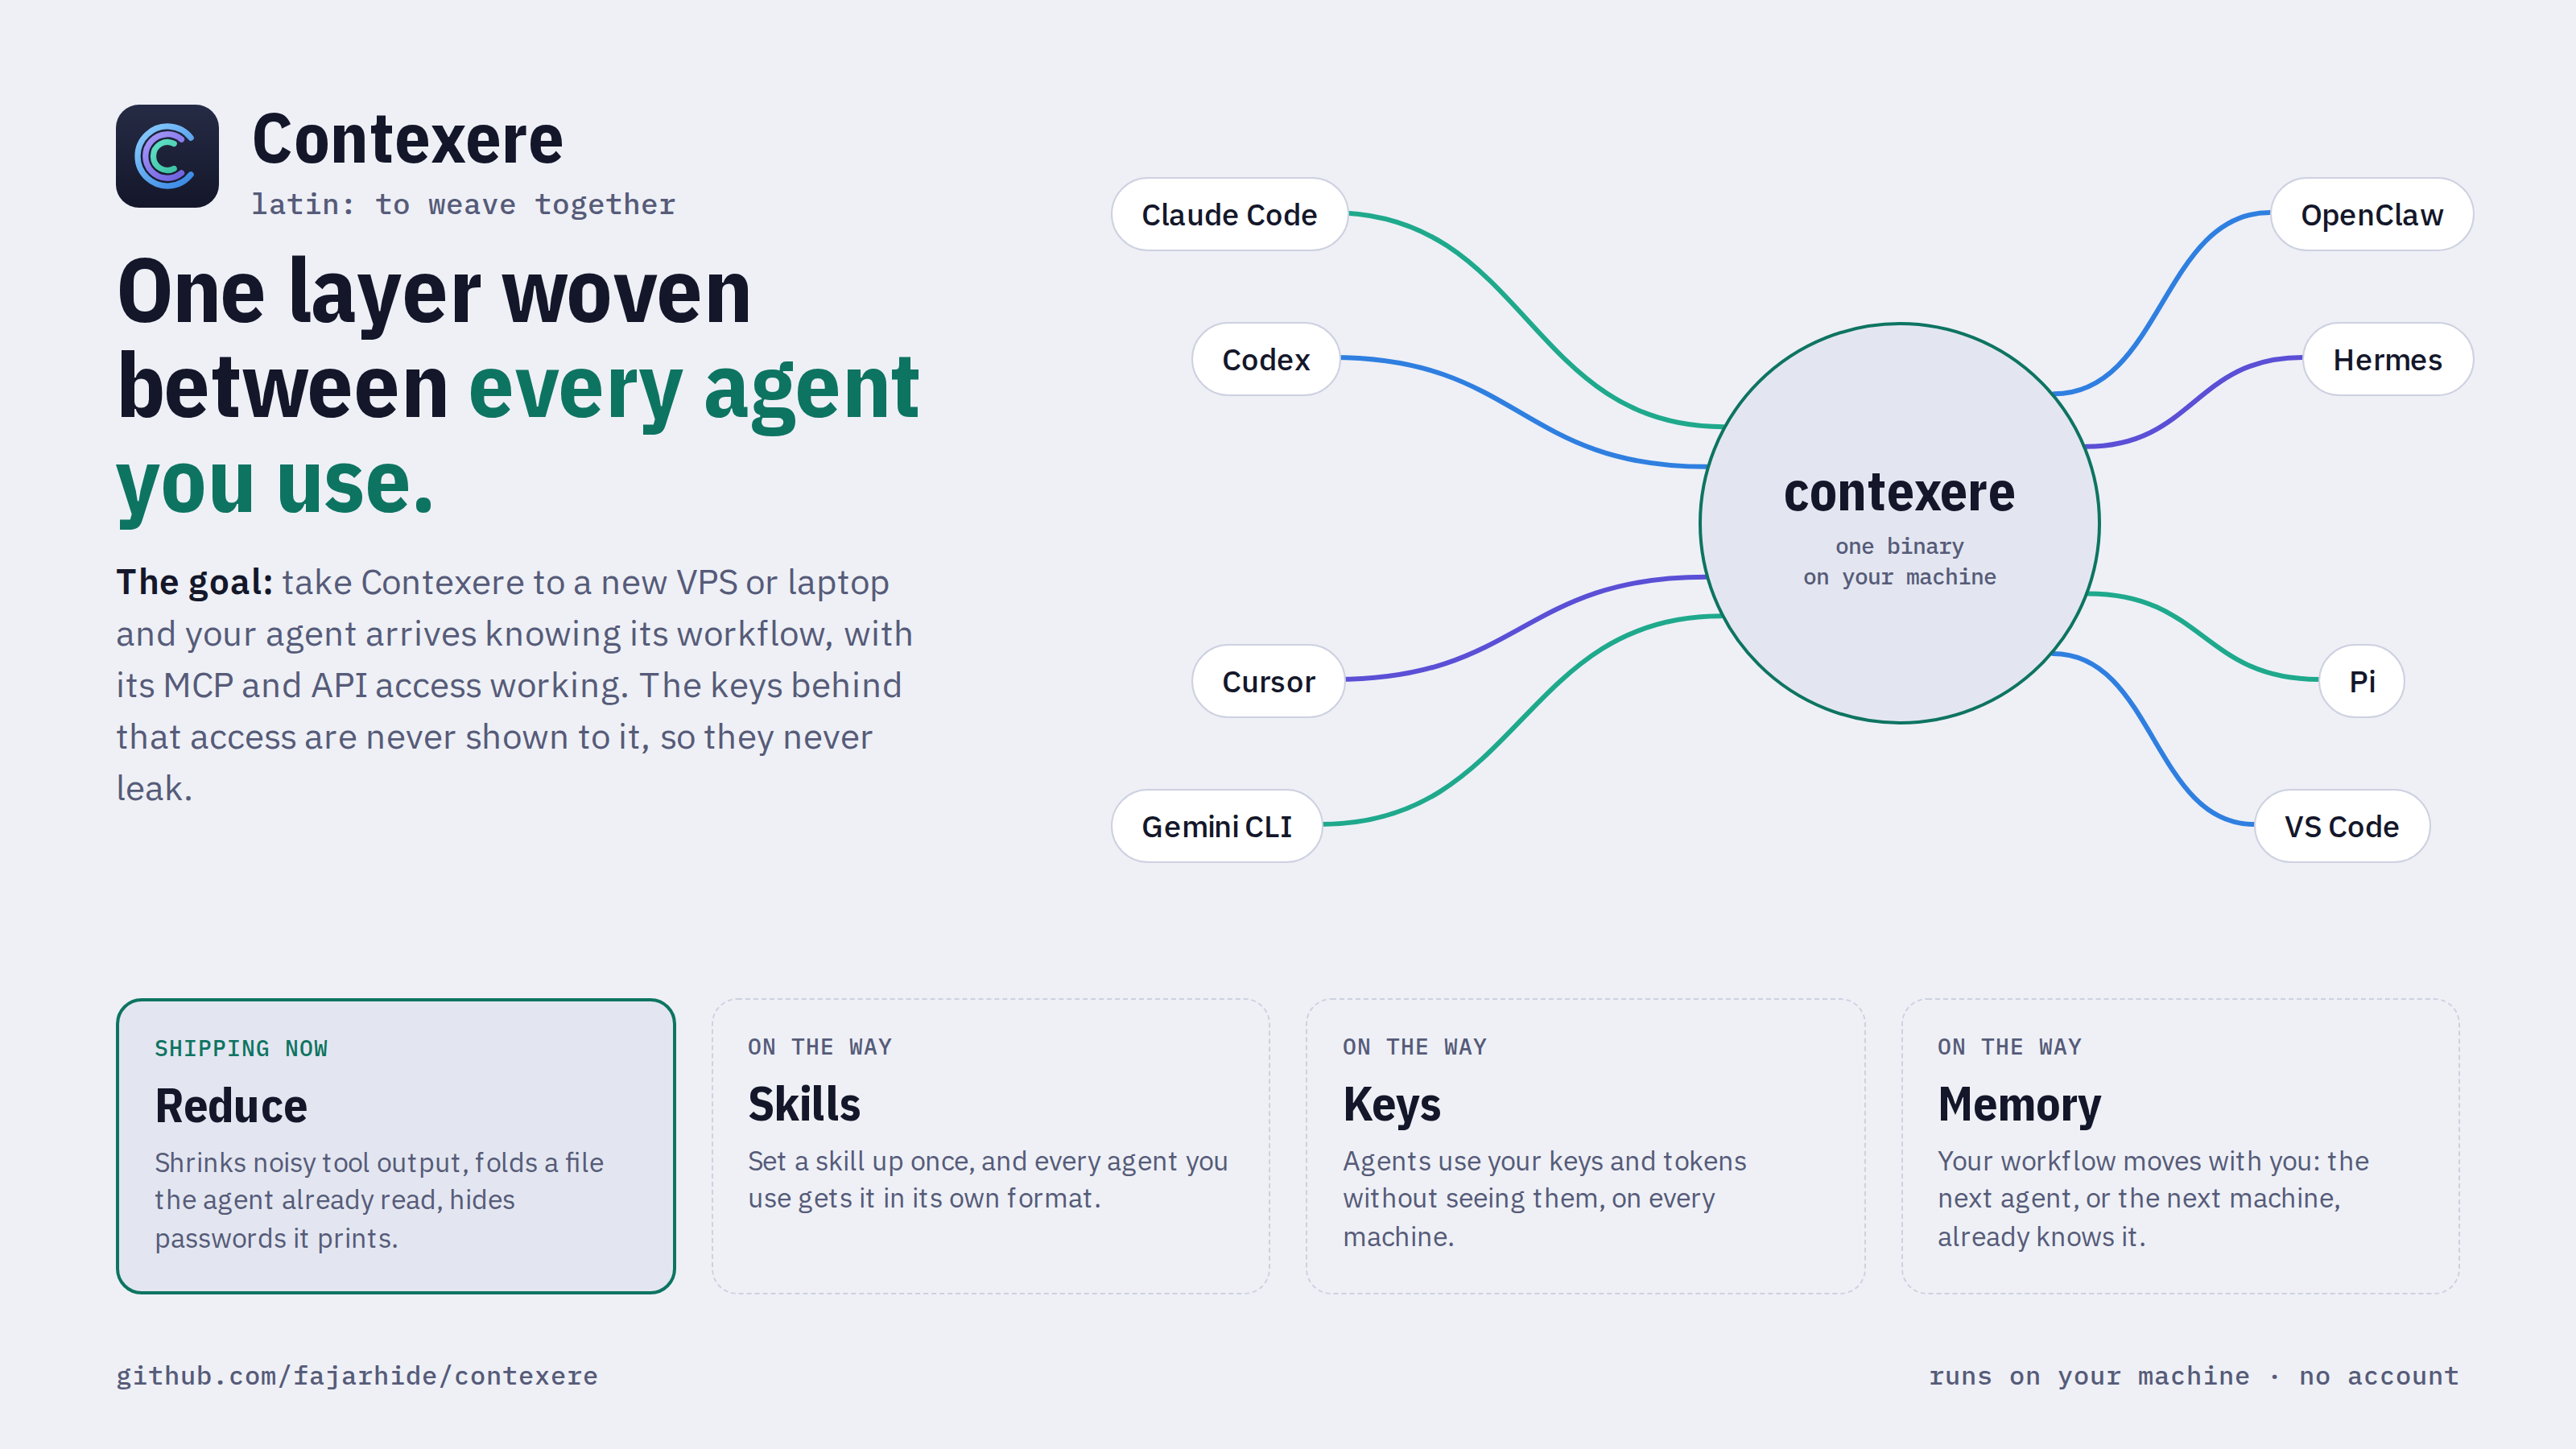
The one place for the skills, keys and memory of every agent you use. Formerly OMNI.
Local proxy that compresses your LLM API requests so you pay less, with no change to the answers. Trims wasted tokens from prompts, history, tool output, and code before they're sent: -31% input / -74% output, measured live. Any provider, no extra model calls. Also an MCP server and embeddable library (Rust, Python, Ruby, Kotlin, Swift, JS/TS).
TOMC Memory: CPU context compression and task memory for Codex, Claude Code, Cursor, TRAE, WorkBuddy and other MCP clients.
Spend fewer tokens on the same work. A local CLI that finds wasted tokens in Claude Code, Codex, opencode and your own API calls.
A curated list on AI token economics: what tokens cost, where they get wasted, and how to cut the bill. Tools, benchmarks, papers, and copy-paste configs for the token economy of LLMs and coding agents.
Make your AI agents work as a team. You keep working in 1 session while it orchestrates models via your other subscriptions, local models and more. Run a Software Factory: long plans, proven steps, safe merges. Carries your setup, tracks every cost.
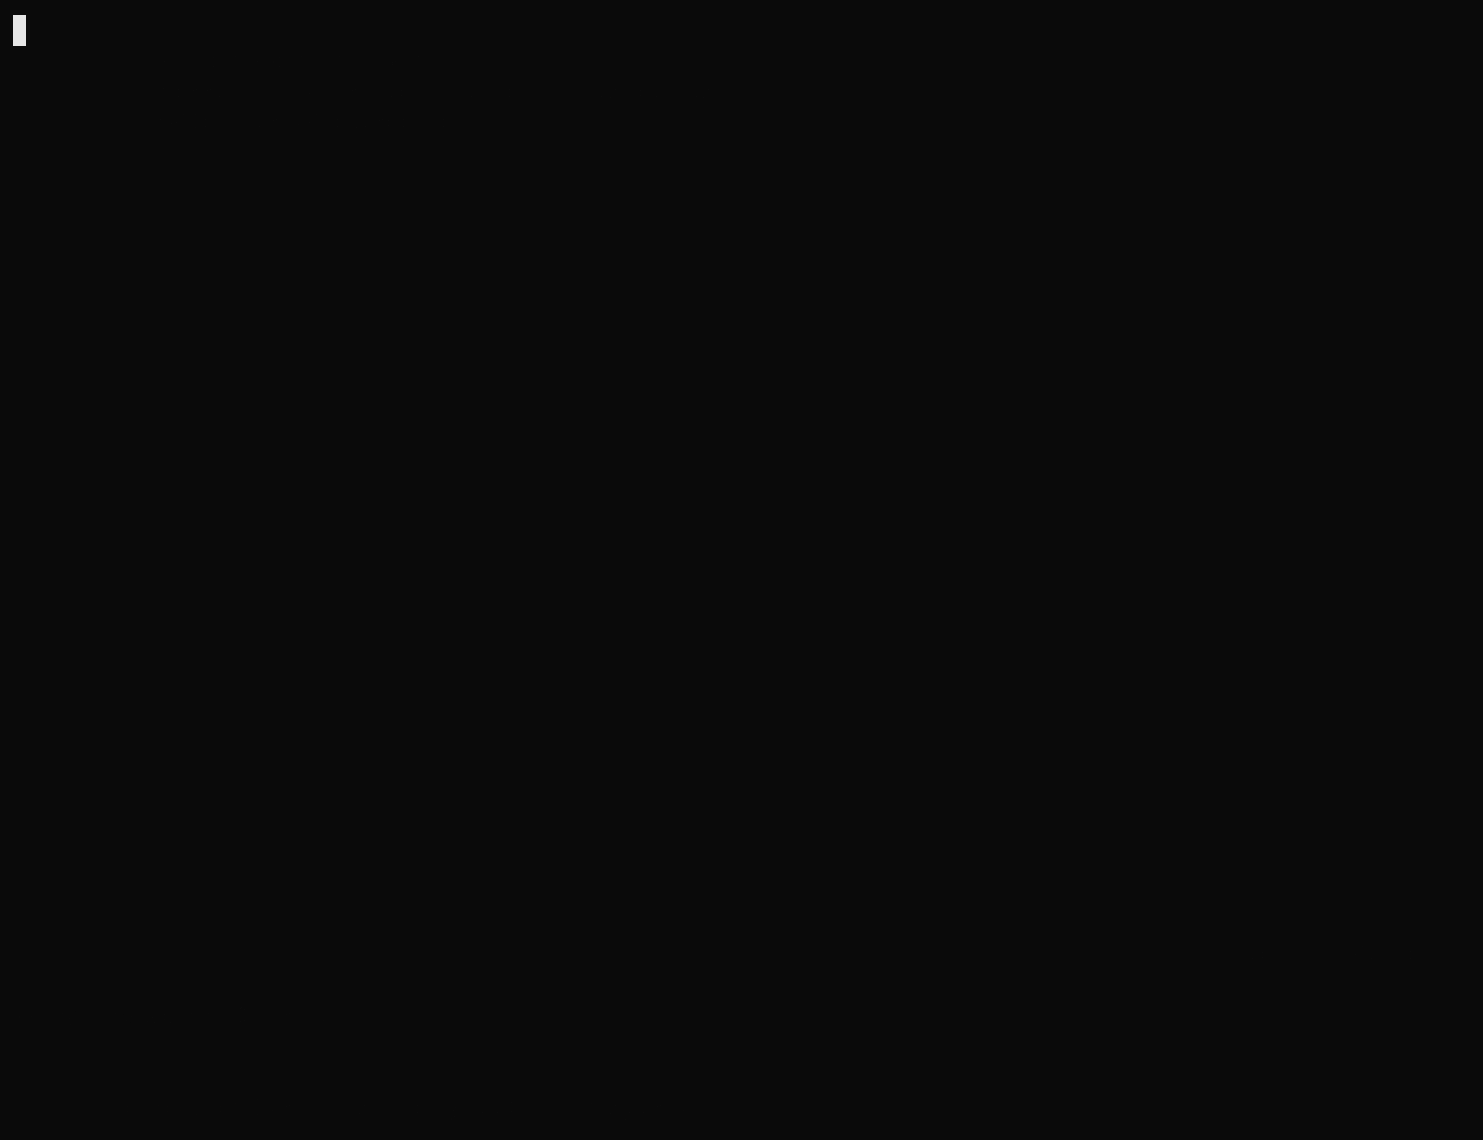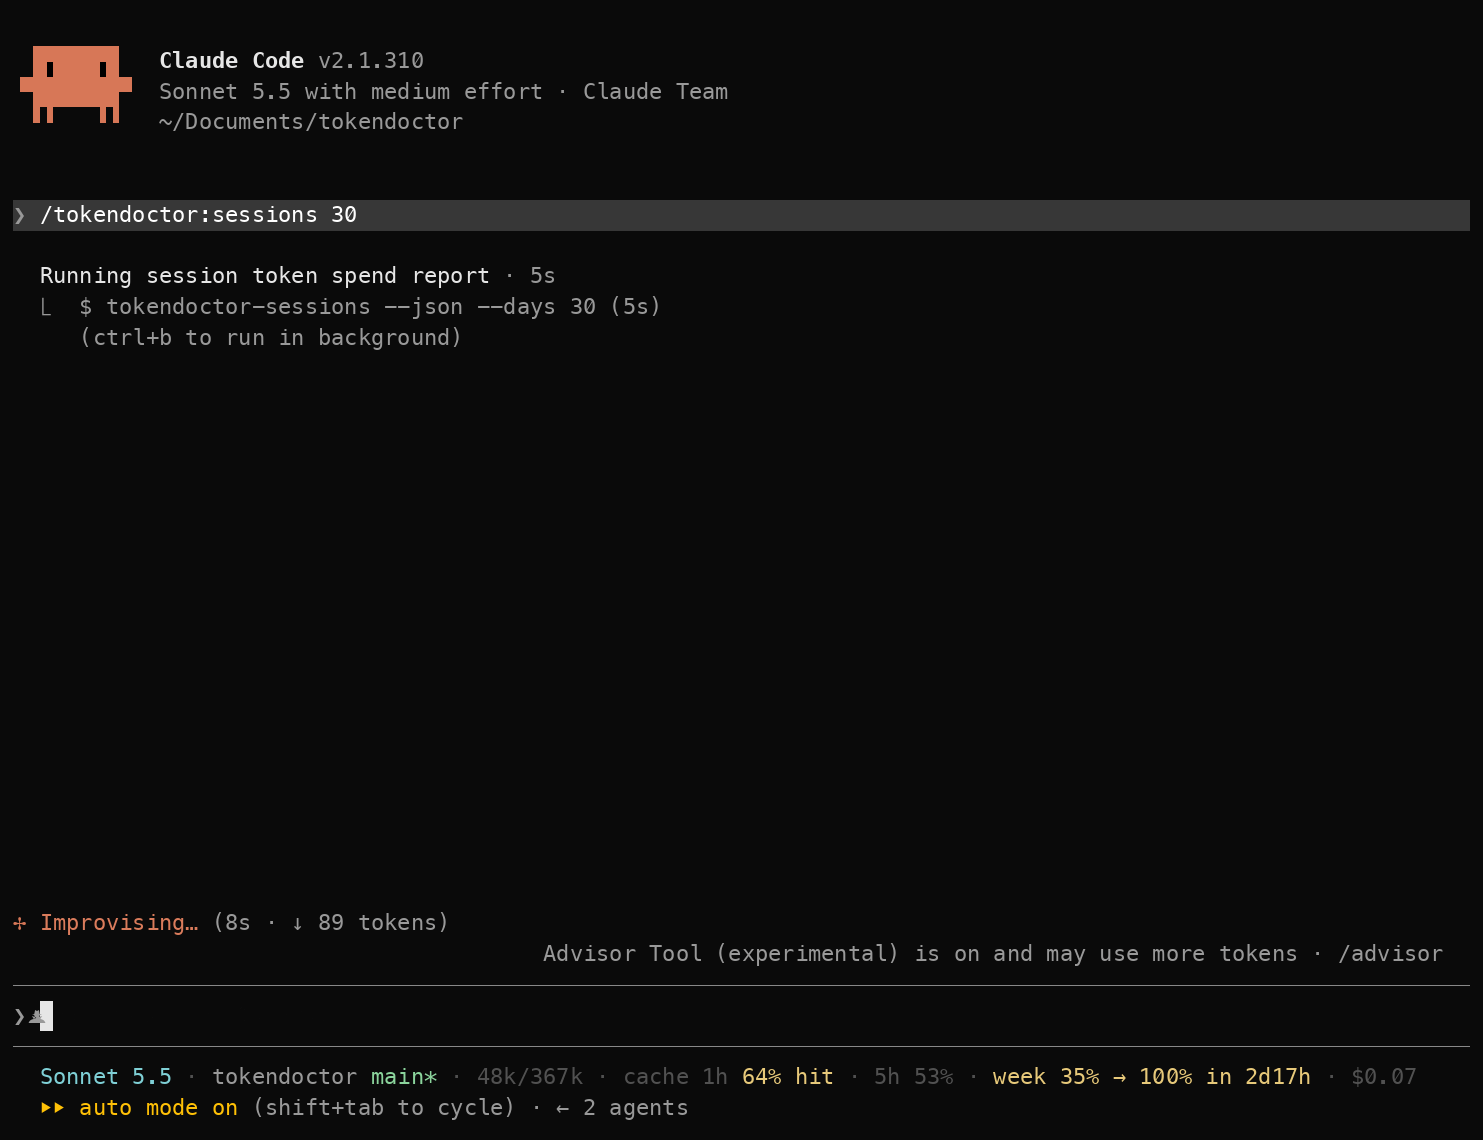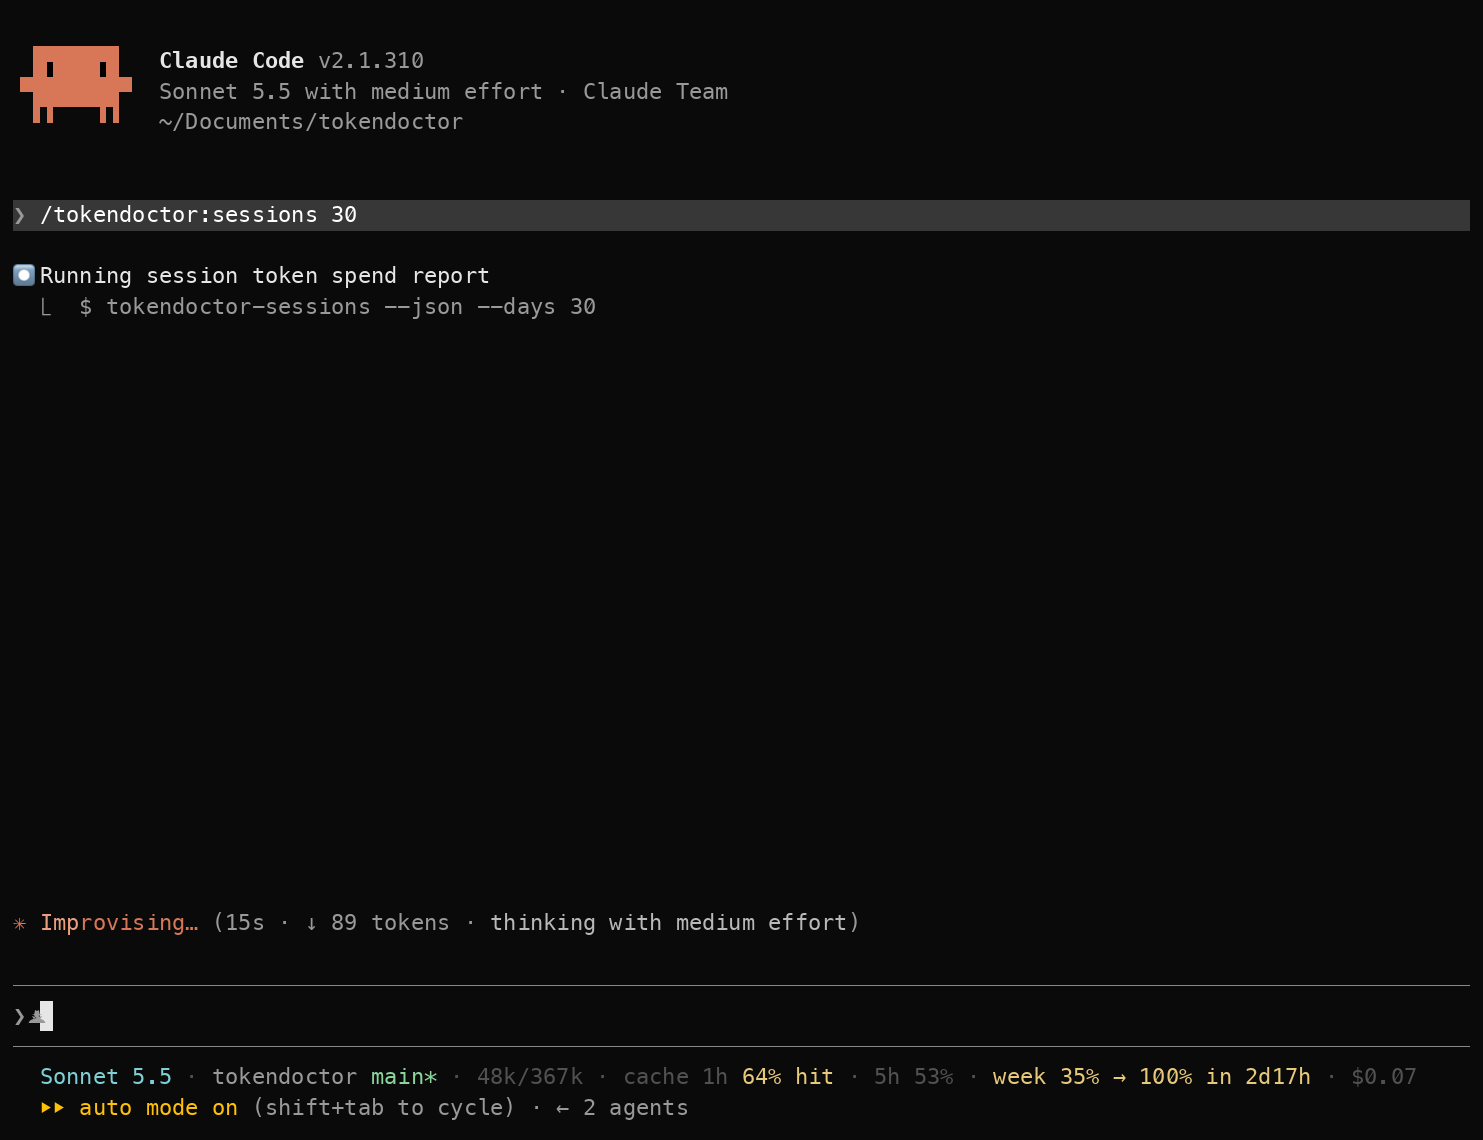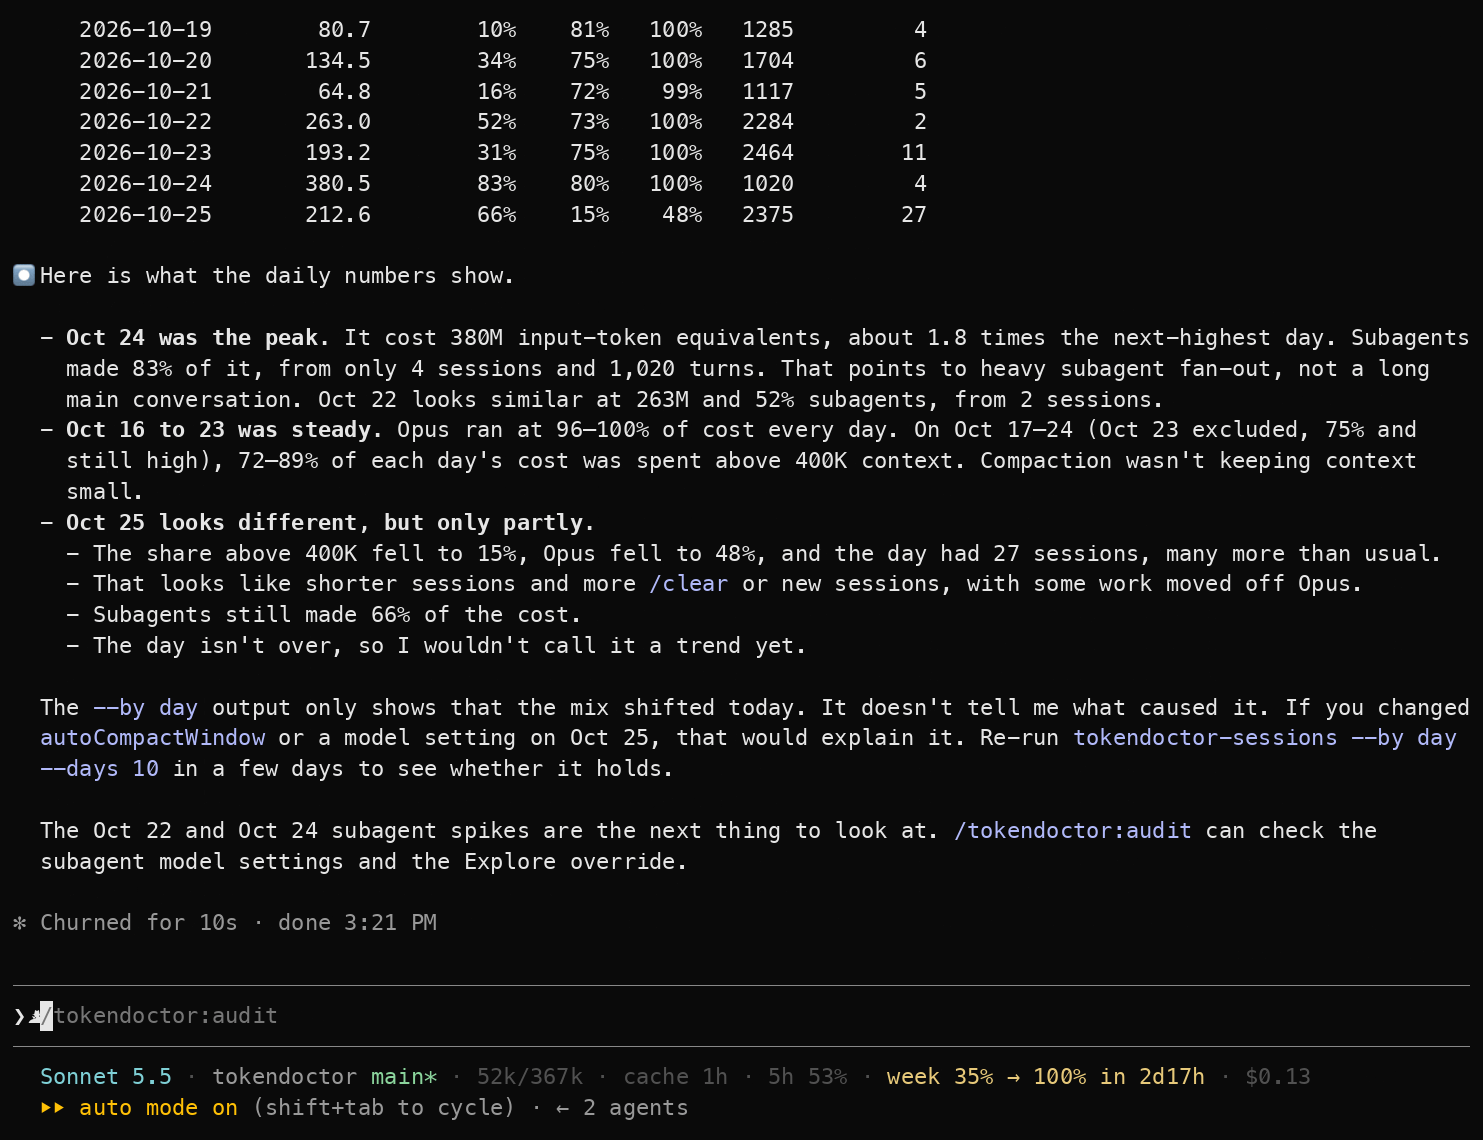
tokendoctor: the same Claude Code for up to 38% less. Replays your own past sessions to show what each change would have saved, then changes only what you pick
Independent research on Claude Code internals, Claude Agent SDK, and related tooling.
A curated list of strategies, tools, papers, and resources for reducing LLM token costs and improving efficiency in production.
dsh-sieve: context engineering & token optimization plugin for DeepSeek Harness (DSH) — tool output filtering, context pruning, progressive skill disclosure. 36% smaller payload in offline replay. DSH 上下文管理与 token 优化节省插件。
⚡ Cut 60-80% token cost for DeepSeek V4 Pro on Codex CLI. token-saver + memory skills with prefix-cache optimization.
Structured plan/execute/verify coding workflow for Claude Code: atomic commits, MCP-backed state, ~92% lower per-turn token overhead, native convention + drift-detection safeguards, and an ASD-STE100 (Simplified Technical English) anti-slop docs gate. A Claude Code-native evolution of GSD and VibeDrift.
A high-performance, ergonomic web framework for Rust with native AI/LLM support.
The AI-native wire format for structured data. 100% comprehension on every frontier model. 50-92% fewer tokens than JSON. 43B+ lossless round-trips across 17 formats. Spec v3.5.1 Stable.
Your AI agent is smart enough to code all day. Now it actually can. Local runtime firewall & zero-loss context optimizer for AI coding agents.
Make every Claude token count. rightsize picks the right model and effort for each prompt, while keeping cache and context costs low. It learns how you work and gets better over time.
Claude Code and Codex CLI skill: an LLM router that delegates bulk, already-decided coding tasks to another model you already pay for (GPT via Codex, Gemini via agy, a Claude Opus subagent), on another subscription first. Benchmark-checked routes, cost per task measured on a bench, cross-model review. The host verifies every diff.
Universal AI router — save 20-40% tokens with RTK and never stop coding. Connect Claude Code, Cursor, Antigravity, Kiro, Copilot, Codex, Cline & any OpenAI-compatible client to 40+ providers & 100+ models via one local endpoint. Zenith sub-1ms failover, MITM, multi-account.
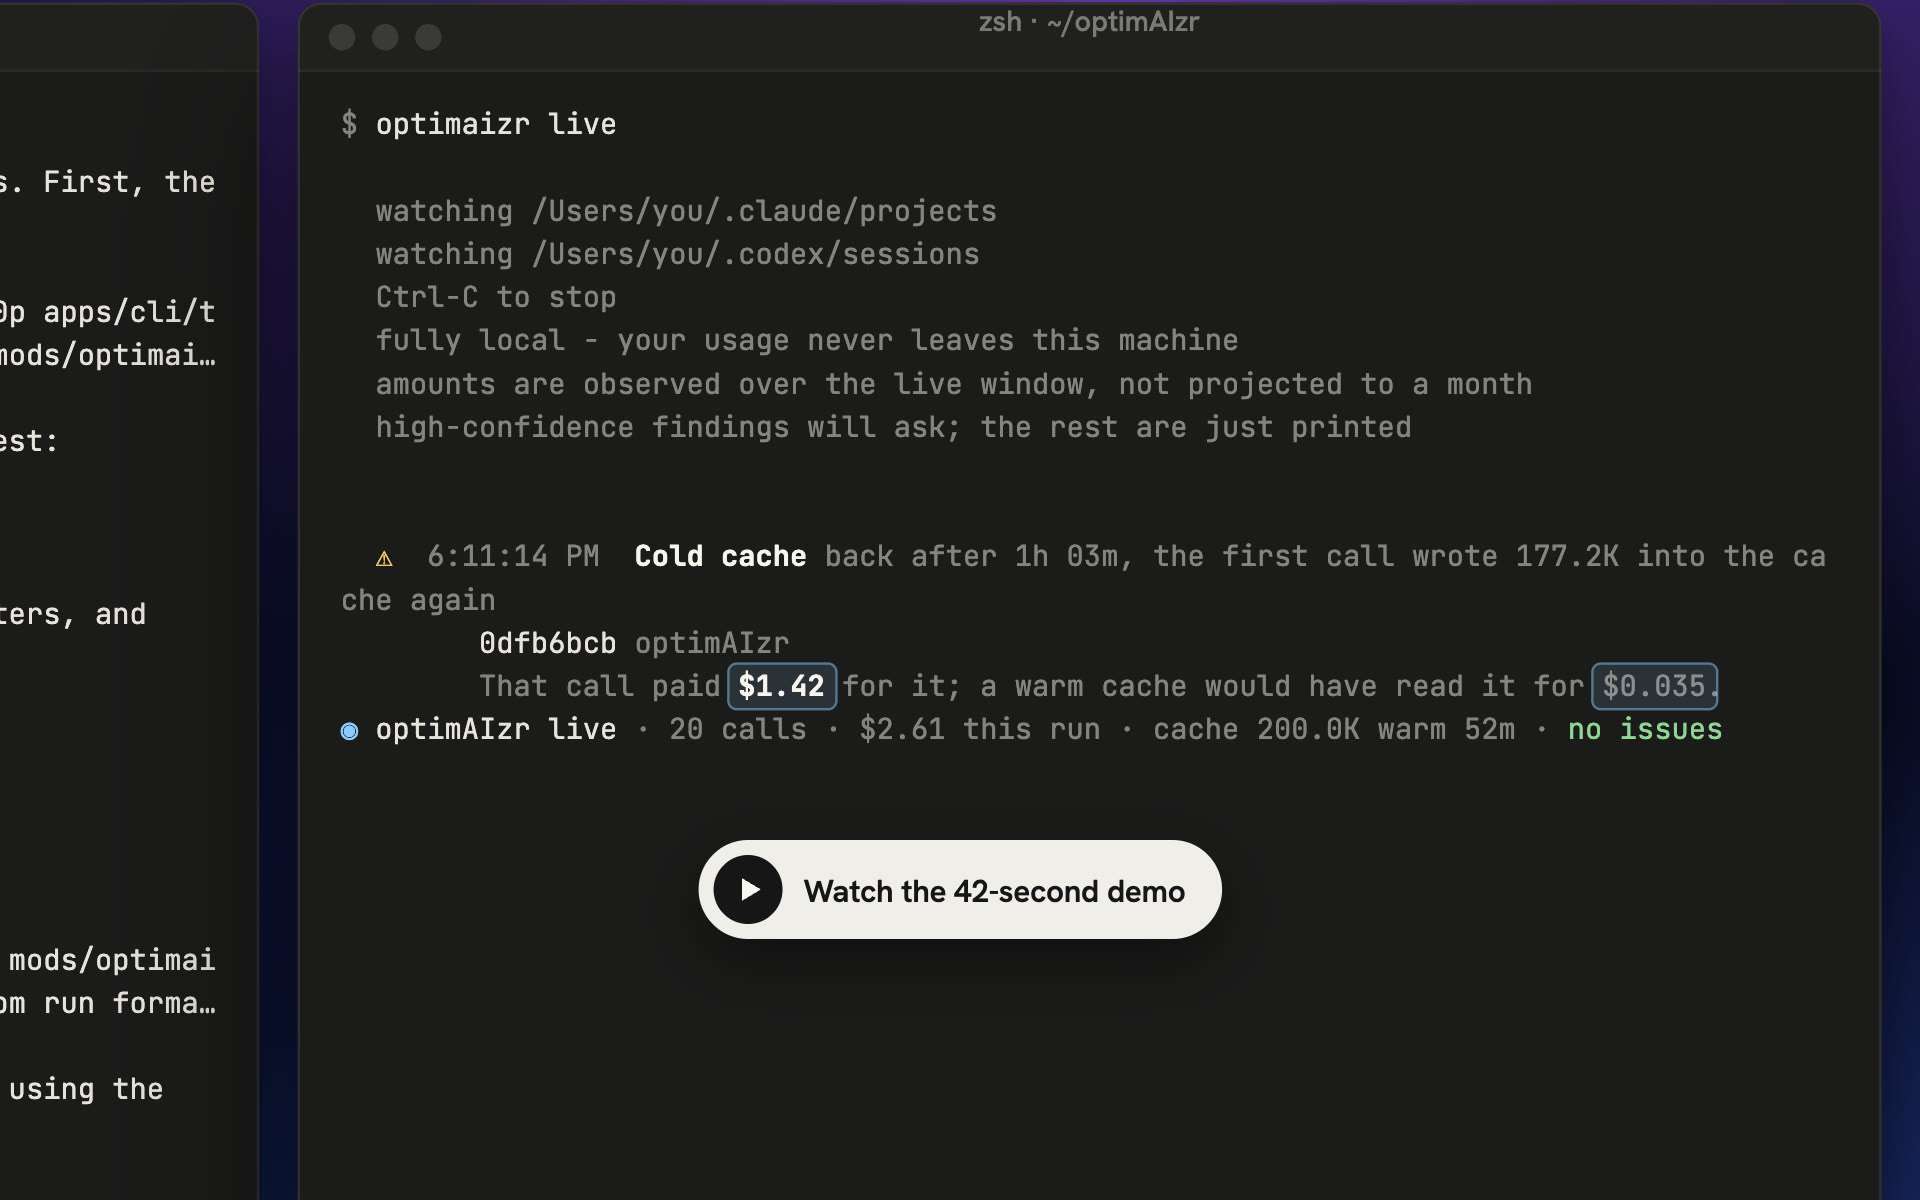
⚡ Terminal HUD, hard budget breakers & prompt-cache leak alerts for AI coding agents (Claude Code, Cursor, Codex)