transformers-models

InternEvo
InternEvo is an open-sourced lightweight training framework aims to support model pre-training without the need for extensive dependencies.
- 420
- Python
- Apache-2.0
- 15 mo ago


ShallowFF
Zeta implemantion of "Rethinking Attention: Exploring Shallow Feed-Forward Neural Networks as an Alternative to Attention Layers in Transformers"
- 12
- Python
- MIT
- 4 d ago
DifferentialTransformer
An open source community implementation of the model from "DIFFERENTIAL TRANSFORMER" paper by Microsoft.
- 41
- Python
- MIT
- 4 wk ago
Stock-Market-News-Sentiment-Analysis-and-Summarization
NLP pipeline for classifying sentiment in financial news and generating weekly summaries of market-moving events. Supports sentiment-informed investment analysis.
- 6
- Jupyter Notebook
- MIT
- 9 mo ago


titans-transformer
This repository contains an experimental implementation of the Titans Transformer architecture for sequence modeling tasks. The code is a personal exploration and may include errors or inefficiencies as I am currently in the learning stage. It is inspired by the ideas presented in the original
- 4
- Jupyter Notebook
- 22 mo ago

JaraConverse-TransformersBased
This JaraConverse model is a cutting-edge Transformer-based supervised Language Model (LLM) specifically designed for generating Python code snippets.
- 3
- Python
- MIT
- 2 y ago

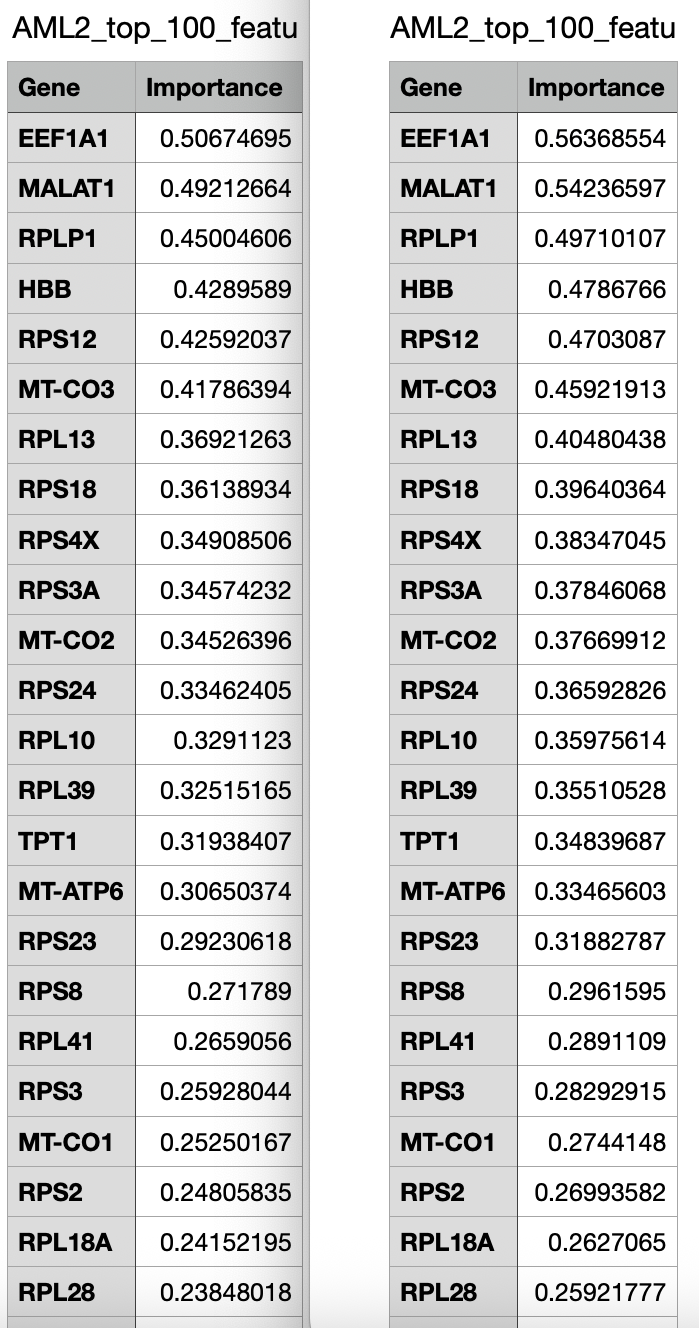
Longitudinal-AML-in-PyTorch
Porting of the "Neurosymbolic Learning for Predicting Cell Fate Decisions from Longitudinal Single-Cell Transcriptomics in Paediatric Acute Myeloid Leukemia" paper code to PyTorch.
- 2
- Python
- GPL-3.0
- 10 mo ago

LLM-LoRA-Finetuning-with-Code
A practical Large Language Model (LLM) fine-tuning repository focused on Low-Rank Adaptation (LoRA) and Parameter-Efficient Fine-Tuning (PEFT). Covers LoRA architecture, adapter configuration, dataset preparation, supervised fine-tuning, model evaluation, and efficient LLM customization using Python, PyTorch, and Hugging Face Transformers.
- 1
- Jupyter Notebook
- MIT
- 5 d ago


QwenSum-LoRA
A LoRA adapter that teaches Qwen2.5-1.5B-Instruct to summarise conversations. 18.5M trainable parameters — 1.20% of the base model — tuned on DialogSum, lifting ROUGE-1 from 0.2822 to 0.4185 over prompting the same weights. Loads on top of the base model with PEFT in two lines.
- 1
- Jinja
- MIT
- 4 wk ago

liar-roberta
RoBERTa-base fine-tuned on the LIAR dataset for binary fake-news detection — 64.5% accuracy, 0.635 macro-F1, beating a TF-IDF + LogReg baseline (0.603). Includes class-weighted training, calibration analysis (ECE 0.042), per-class error breakdown, threshold selection, ONNX export, and a live Spaces demo. Reproducible from one Colab notebook.
- 1
- MIT
- 4 wk ago

bangla-summarizer-pro
QLoRA fine-tune of Qwen3.5-0.8B on Bangla instruction data that did not work, published as a post-mortem. Four failure causes diagnosed, with benchmarks shown against the random-chance floor.
- 1
- Jinja
- 3 wk ago
DragonBridge-Translator-API-Optimized-Chinese-English-Translation-Server-via-CTranslate2
High-performance, asynchronous translation service leveraging the Helsinki-NLP OPUS-MT zh-en model optimized via CTranslate2. The solution provides a RESTful API endpoint that accepts Chinese text input and returns English translations with sub-second latency. Development supported by DeepSeek.
- 1
- HTML
- GPL-3.0
- 2 mo ago

transformer
transformer :robot::dna::hugs: : HuggingFace # Transformer # AWS Sagemaker Studio Lab
- 0
- Jupyter Notebook
- 2 mo ago

Transformers
The Transformers repository provides a comprehensive implementation of the Transformer architecture, a groundbreaking model that has revolutionized both Natural Language Processing (NLP) and Computer Vision tasks. Introduced in the seminal paper "Attention is All You Need" by Vaswani et al.
- 0
- Jupyter Notebook
- MIT
- 19 mo ago