Qwen
The official repo of Qwen (通义千问) chat & pretrained large language model proposed by Alibaba Cloud.
- 22k
- Python
- Apache-2.0
- 9 mo ago
The official repo of Qwen (通义千问) chat & pretrained large language model proposed by Alibaba Cloud.
An Open-source book with Modern CUDA learning Notes for Beginners - BF16/FP8/FP4, HGEMM, CuTe, Flash-Attention, etc.
Official release of InternLM series (InternLM, InternLM2, InternLM2.5, InternLM3).
中文LLaMA-2 & Alpaca-2大模型二期项目 + 64K超长上下文模型 (Chinese LLaMA-2 & Alpaca-2 LLMs with 64K long context models)
📚A curated list of Awesome LLM/VLM Inference Papers with Codes: Flash-Attention, Paged-Attention, WINT8/4, Parallelism, etc.🎉
cuDNN Frontend is NVIDIA's modern, open-source entry point to the cuDNN library and a growing collection of high-performance open-source kernels.
Trainable fast and memory-efficient sparse attention
From teacher to tiles — a from-scratch LLM distillation & serving engine: custom Triton/CUDA kernels, FSDP distillation, paged-KV continuous batching, speculative decoding, a Rust gateway, a JAX oracle, and interpretability tooling.
InternEvo is an open-sourced lightweight training framework aims to support model pre-training without the need for extensive dependencies.
Kernel Library for Large Headdim Attention (64~1024, BF16/FP8/FP4), 1.5x~15x↑ vs PyTorch SDPA.
[CVPR 2025 Highlight] The official CLIP training codebase of Inf-CL: "Breaking the Memory Barrier: Near Infinite Batch Size Scaling for Contrastive Loss". A super memory-efficiency CLIP training scheme.
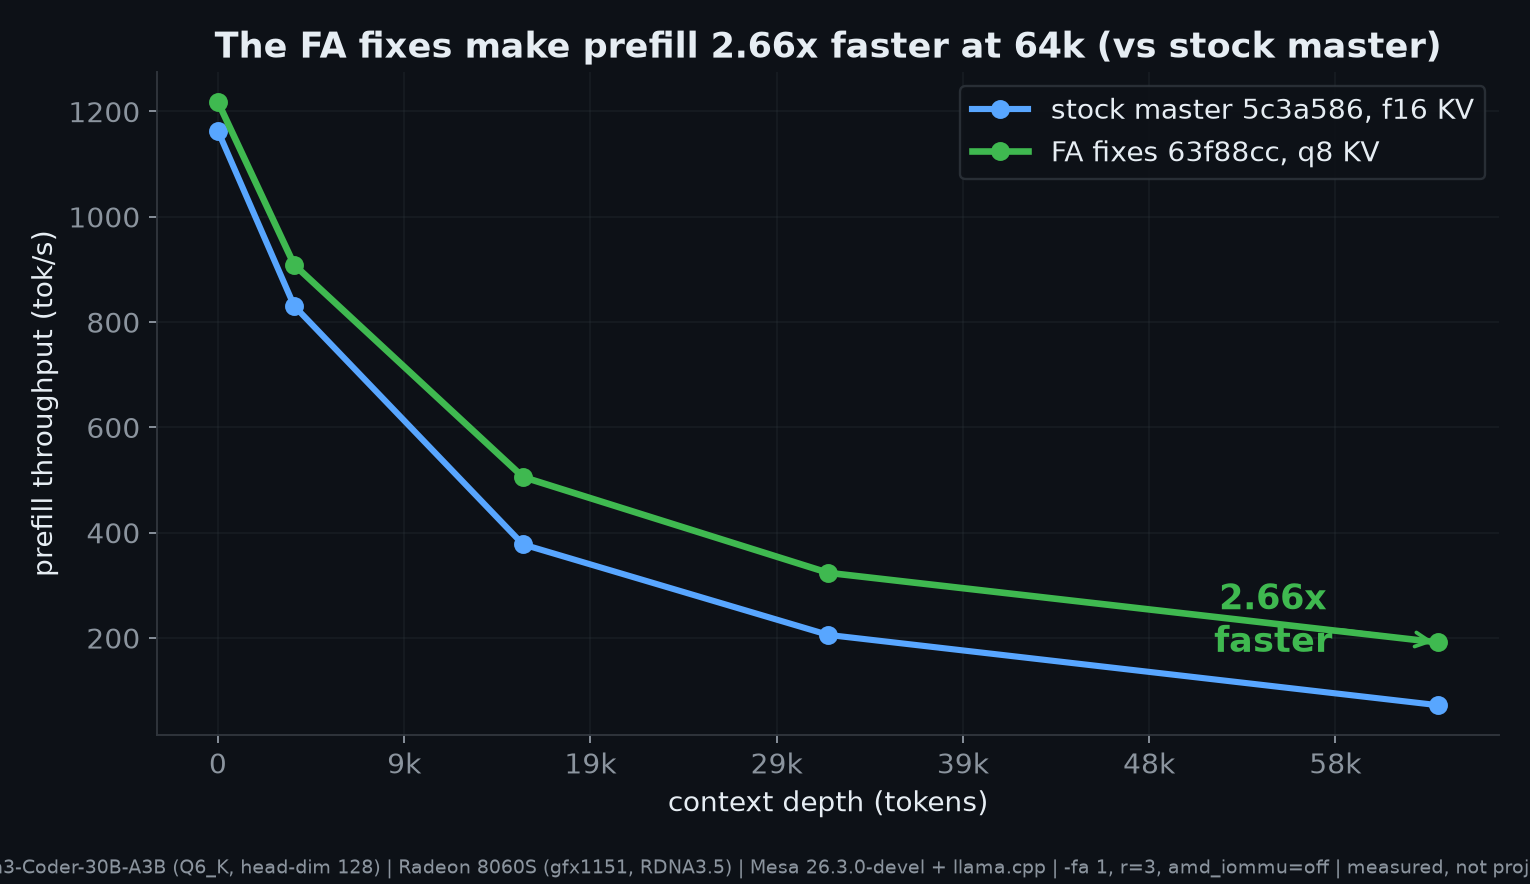
Performance-tuned llama.cpp for AMD Strix Halo (gfx1151): FA + MoE-prefill fixes with a bundled current Mesa driver. Vulkan and HIP; portable dir, Docker, and distrobox.
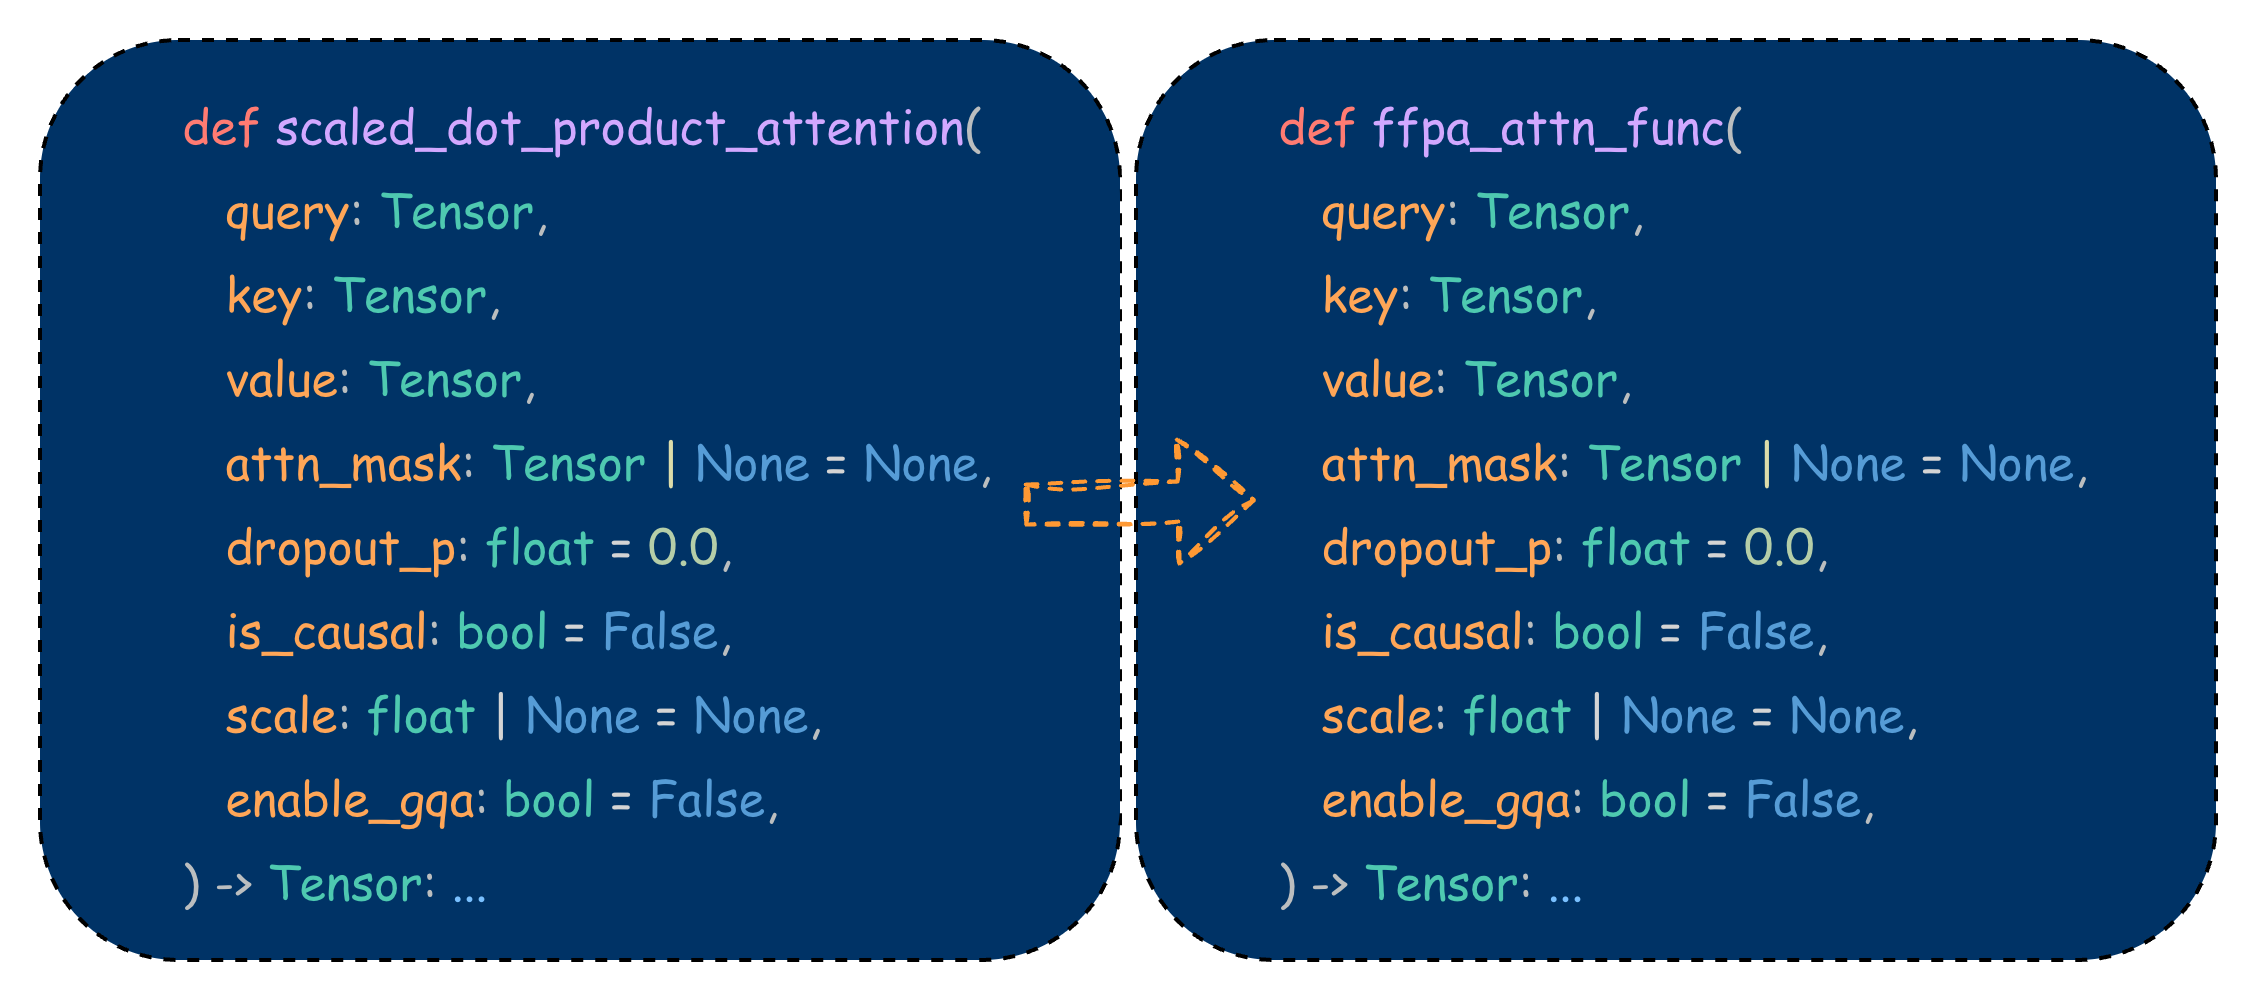
Implementation of FlashAttention (FA1-FA4) in PyTorch for educational and algorithmic clarity
Implementation of FlashAttention-2 for Nvidia Tesla V100 / Titan V
🪟 为 Windows AI 开发者提供预编译 wheel 文件的集中仓库 | 自动抓取并整理 PyTorch、Flash Attention、xformers、SageAttention 等常用库的最新版本 | 免编译,开箱即用 | 特别适合 ComfyUI 和 Stable Diffusion 用户
Qwen4-Exp (Qwen3.8-Flash-Next) SWA + MTP + PLE-on-iswa — bounded deep-context decode w/ long-range recall, TBQ4 4.25 bpv KV, DSpark + RotorQuant. Main (master) = Qwen4-Exp build; the Qwen35 SWA hybrid lives on the qwen35 branch. RTX 4090.
CUDA编程练习项目-Hands-on CUDA kernels and performance optimization, covering GEMM, FlashAttention, Tensor Cores, CUTLASS, quantization, KV cache, NCCL, and profiling.
Emotion text classification using Llama3-8b with LoRA and FlashAttention. Based on LLaMA-Factory.
Native Windows vLLM 0.33.0 (Python 3.13/CUDA 13.0), plus a Python 3.14/CUDA 13.2 build; older versions on the Releases page. PyTorch 2.14, FlashAttention/Rust, OpenAI serving, 10 KV formats, Multi-TurboQuant, experimental CPU/NVMe KV offload. No WSL or Docker.
Automatically benchmark and optimize attention in diffusion models. 1.5-2x speedup on RTX 4090.
Cross-platform FlashAttention-2 Triton implementation for Turing+ GPUs with custom configuration mode
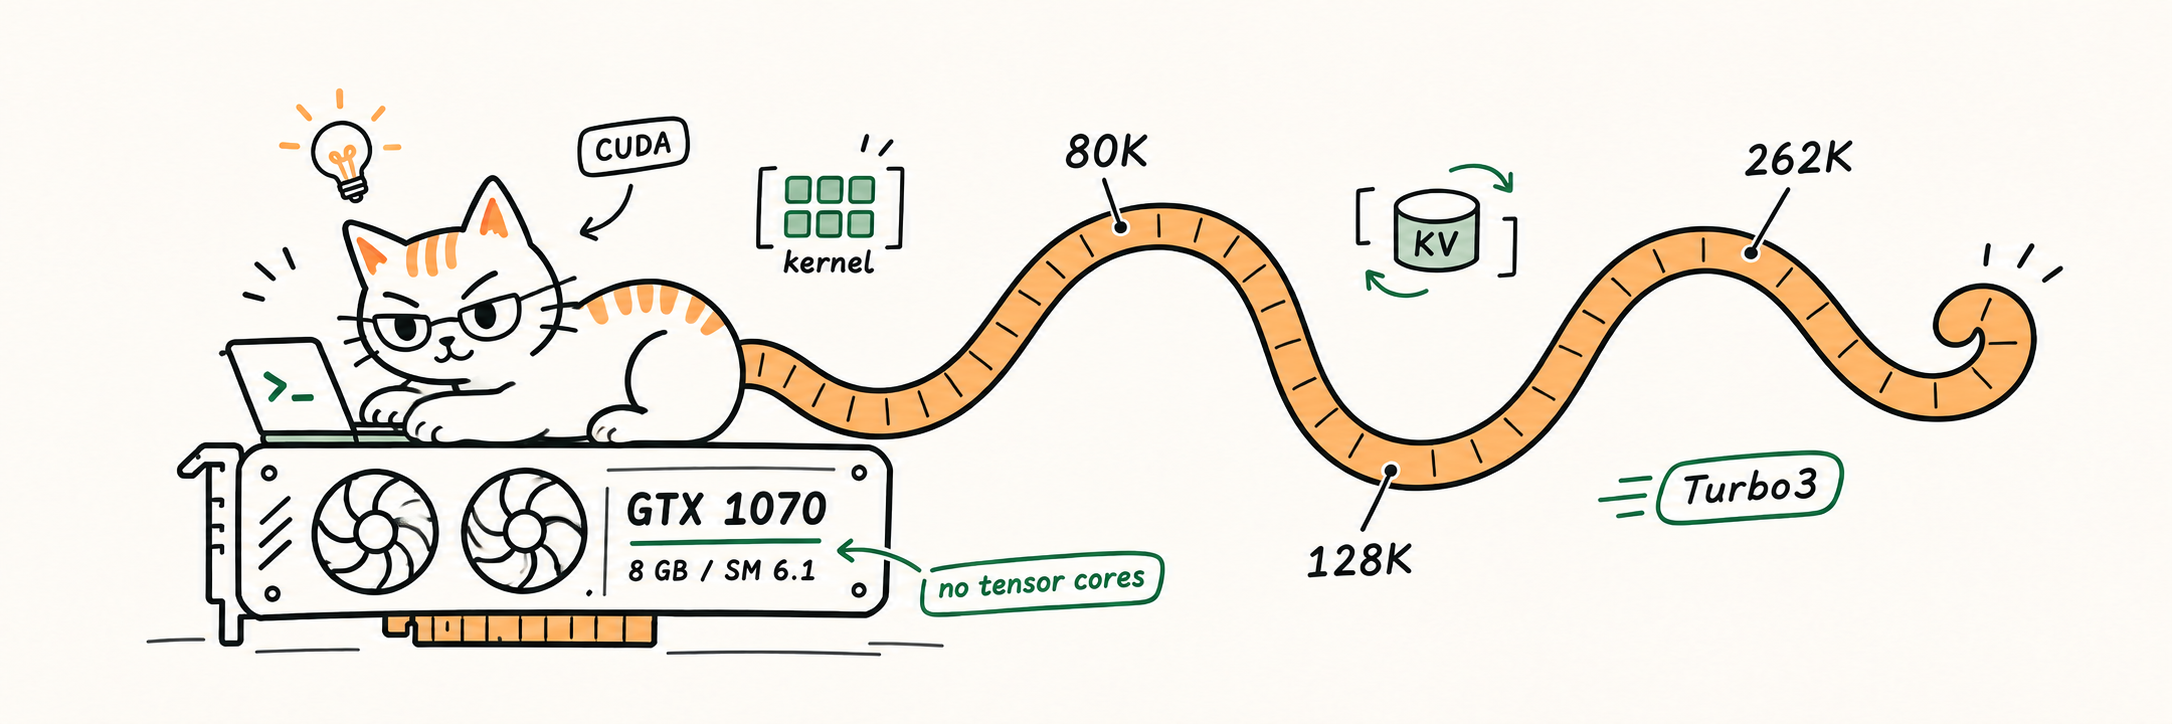
Pre-tensor-core (Pascal GTX 1070) inference optimizations for llama.cpp: native Turbo3 compressed-KV flash attention, PTQ1 ternary DP4A matmuls, chunked gated-delta-net, TurboQuant/VBR KV on 80K-262K contexts
FastCuda is a handwritten CUDA operator library featuring progressive GEMM and Reduce kernels, cuBLAS benchmarking, and C/C++/Python interfaces for learning, profiling, and performance optimization.
纯 CUDA 实现 GPT2 推理,逐步优化算子与架构,最终在单请求下推理速度领先 vLLM 约 1.5 倍。逐算子、逐迭代的进行:NCU 视察、性能解析与记录报告。
AI Agent plugin for Autoresearch with AI (Claude, OpenClaw, etc) to improve anything!
Native K-quant support for MLX, with a quantization and fine-tuning toolchain for Apple Silicon
Explainable compatibility resolution for torch, CUDA, and native GPU extensions.
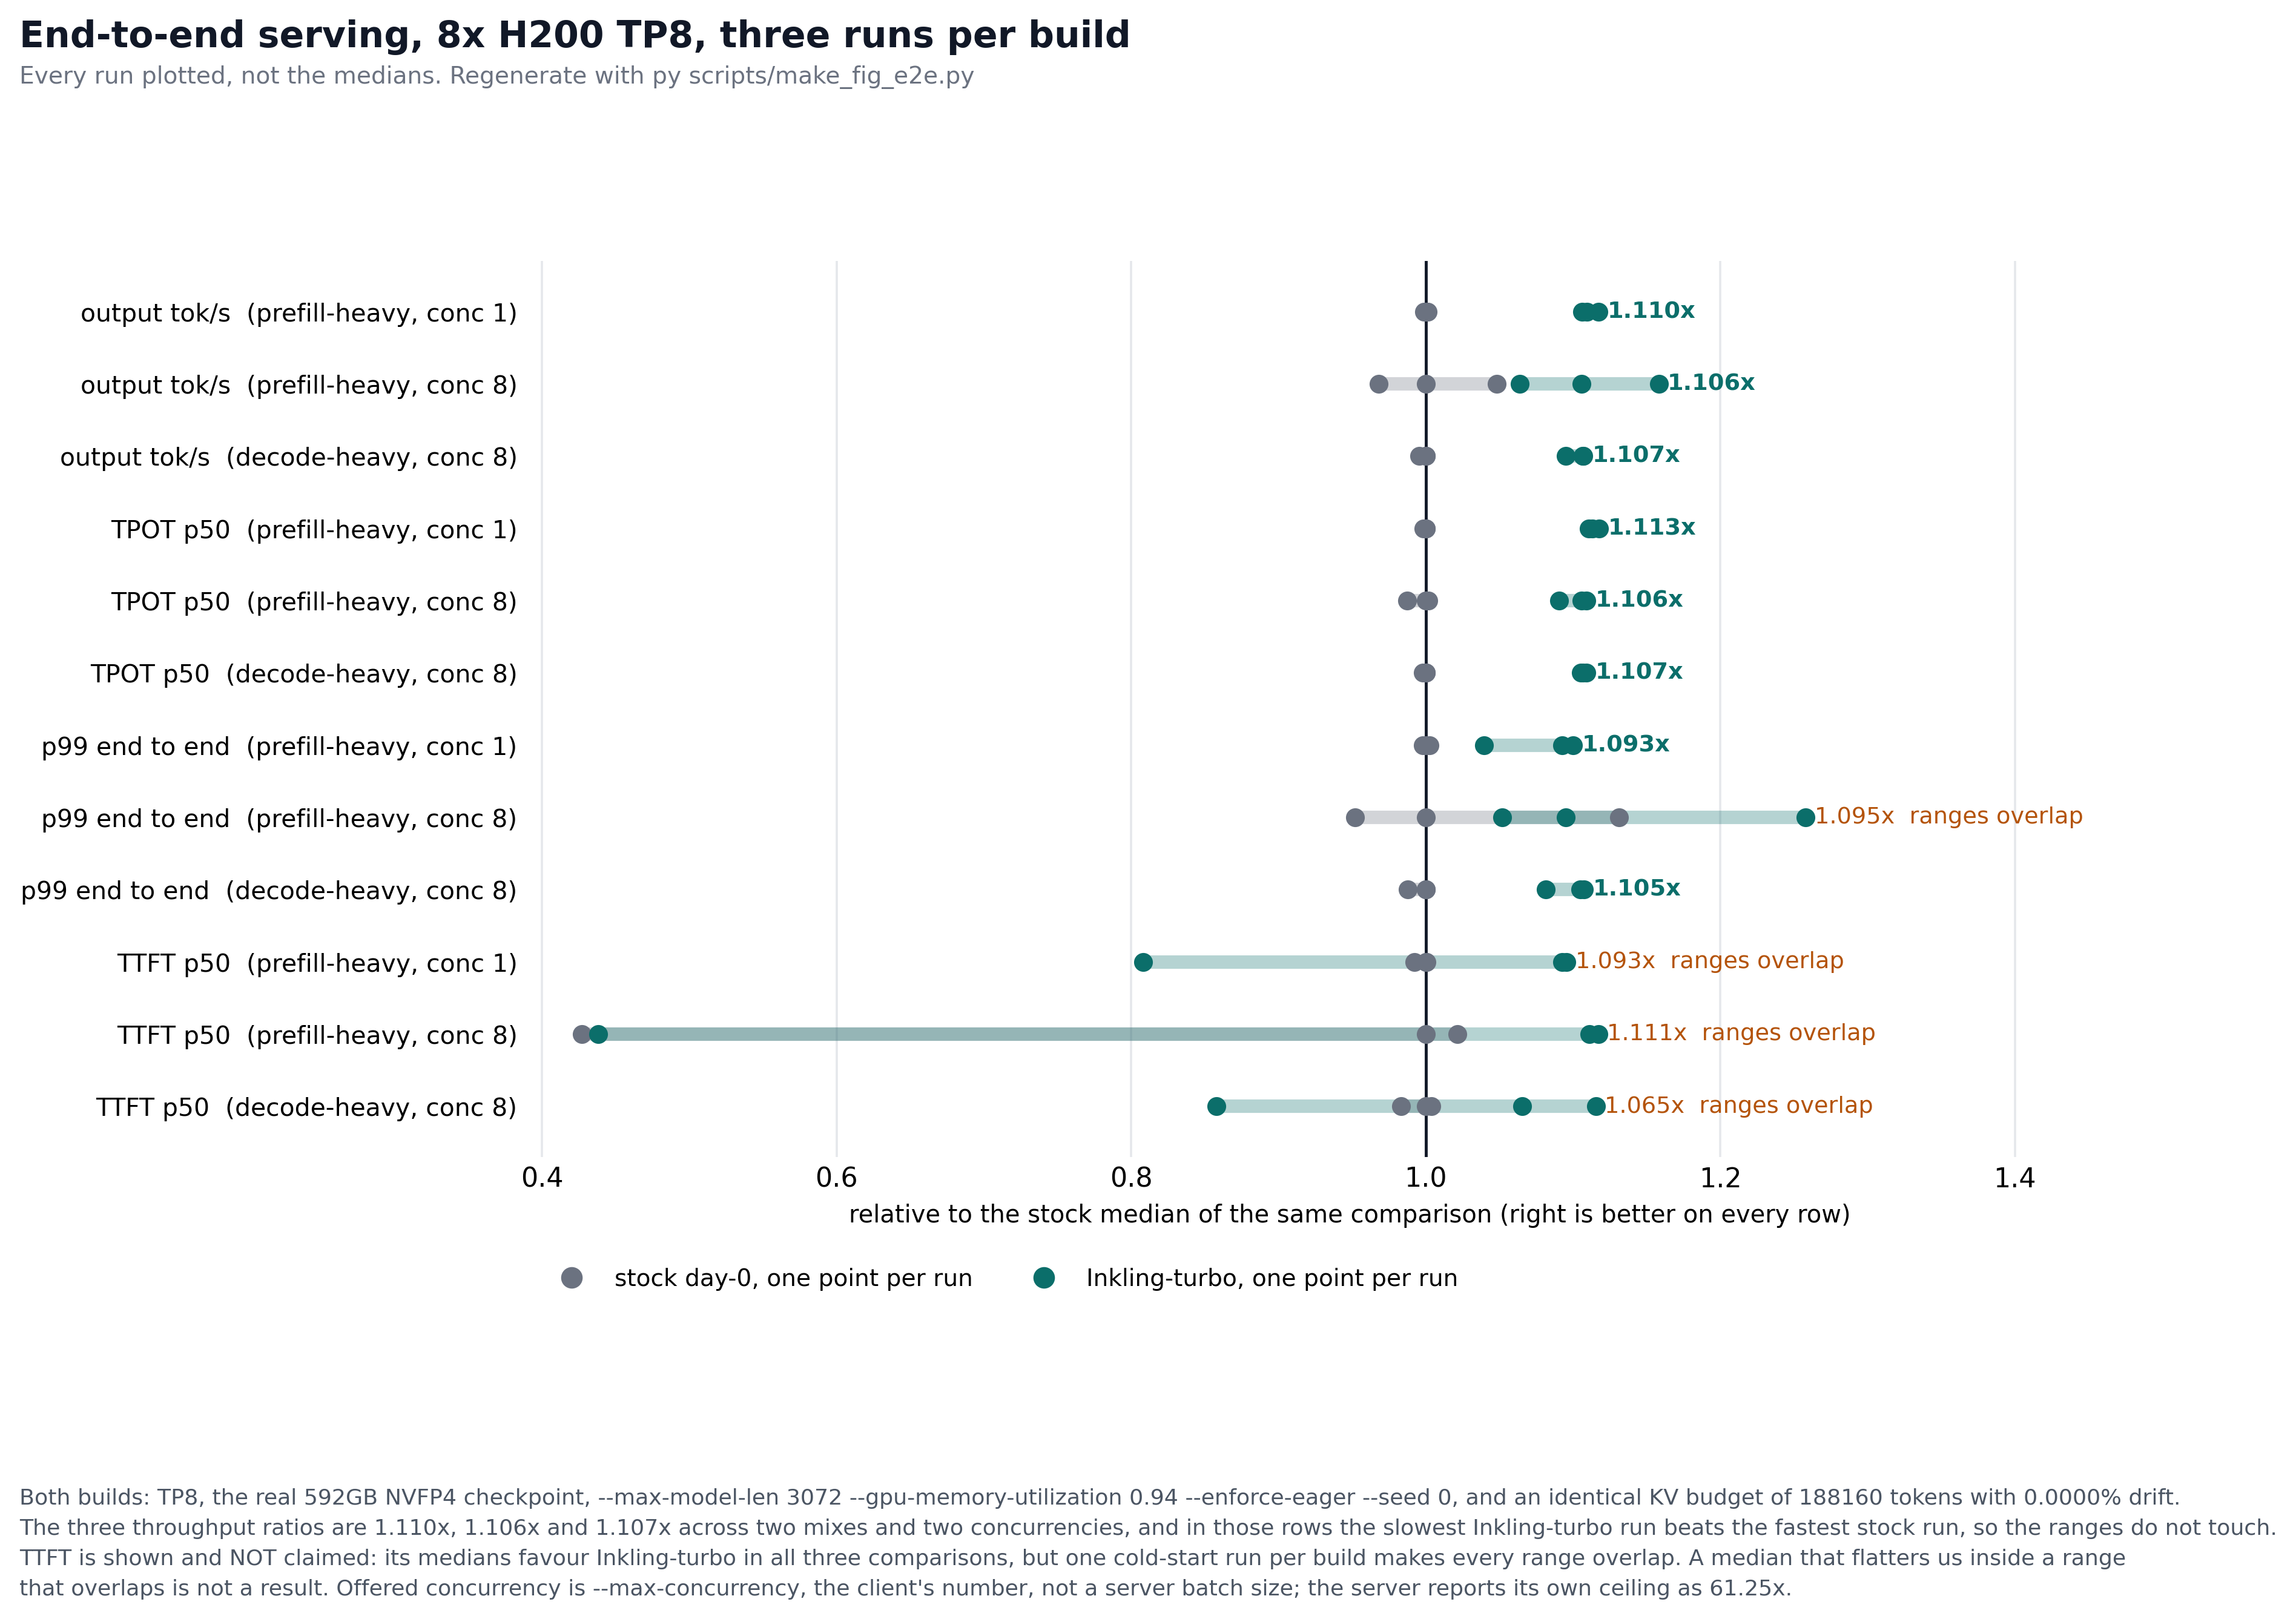
Faster attention kernels for serving TML's Inkling model on vLLM. 2.7x over the shipping path on H100, and the only implementation that runs on A100.
Hardware-aware Ollama fork with legacy NVIDIA support, controllable runtime tuning, Q4/Q8 KV cache, Flash Attention, CUDA Graphs and optimized multi-GPU inference.
FlashAttention-style CUDA kernel that reads vLLM's int8 per-token-head paged KV cache in place (sm80/86/89), with a vLLM attention-backend plugin.
HY-World-2.0-Demo is a powerful, experimental 3D reconstruction and Gaussian Splatting suite powered by the Tencent HY-World-2.0 model (WorldMirror).
Deep-learning library in pure Rust: from XOR to a 300M-param transformer on one GPU. NVRTC CUDA, flash attention, MoE, ties or beats PyTorch torch.compile.
Single-file, detectron2-free PyTorch reimplementation of HADM's EVA-02 ViT backbone for feature extraction. Runs on Blackwell/sm_120 via SDPA (FlashAttention), ~0.999 cosine parity.