VibeVoice-ComfyUI
A comprehensive ComfyUI integration for Microsoft's VibeVoice text-to-speech model, enabling high-quality single and multi-speaker voice synthesis directly within your ComfyUI workflows.
- 1.6k
- Python
- MIT
- 9 mo ago
A comprehensive ComfyUI integration for Microsoft's VibeVoice text-to-speech model, enabling high-quality single and multi-speaker voice synthesis directly within your ComfyUI workflows.
A ComfyUI custom node integration for local multi-engine multi-language Text-to-Speech and Voice Conversion. Supports: RVC, Echo-TTS, Qwen3-TTS, Cozy Voice 3, Step Audio EditX, IndexTTS-2, Chatterbox (classic and multilingual), F5-TTS, Higgs Audio 2, 3, and VibeVoice with unlimited text length, SRT timing, Character support, and many audio tools
ComfyUI custom node for the VibeVoice TTS. Expressive, long-form, multi-speaker conversational audio
Automatic speech recognition model, used with transformers.
Beautiful voice app: record or upload to train a voice, generate speech from text or files, save & download voices.
A Gradio-based demo for end-to-end vision-to-speech inference: Extract text or descriptions from images using Qwen2.5-VL-7B-Instruct, then convert to natural speech audio via Microsoft VibeVoice-Realtime-0.5B.
WASA is an AI-powered transcription, translation and synthesis tool for voiceovers with independent channel control.
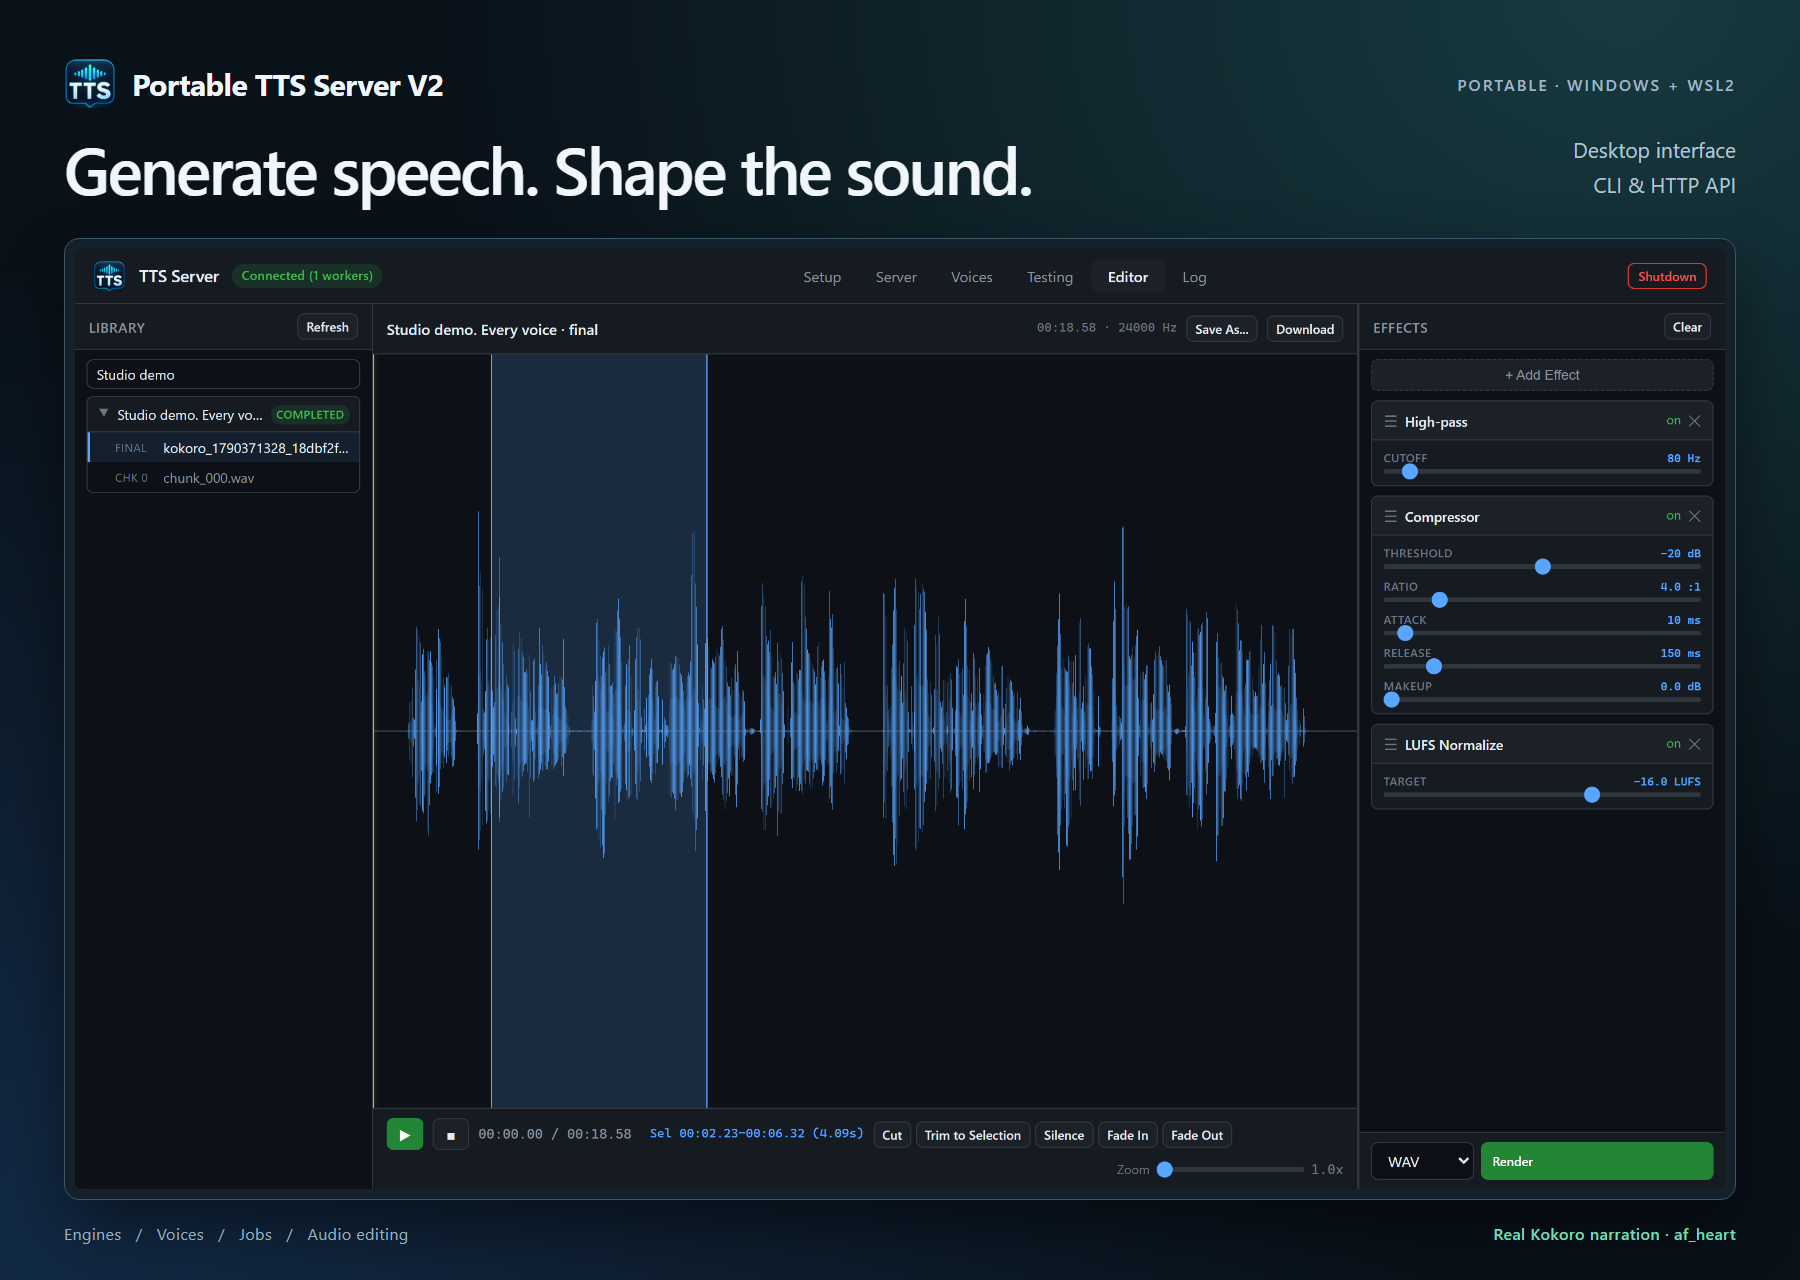
19 speech engines + Whisper: Kokoro, XTTS v2, F5-TTS, Chatterbox, Fish Speech, Bark, Dia, Higgs Audio, Qwen Omni, VibeVoice, SpeechT5, Parler, OuteTTS, VITS, Edge, Voxtral, VoxCPM2, CSM and Orpheus. Voice cloning, SRT, audio editor, CLI/API. Offline Kokoro included. From portable-linux-in-a-box.