mlx-vlm
MLX-VLM is a package for inference and fine-tuning of Vision Language Models (VLMs) on your Mac using MLX.
- 5.9k
- Python
- MIT
- 12 h ago
MLX-VLM is a package for inference and fine-tuning of Vision Language Models (VLMs) on your Mac using MLX.
Open-source evaluation toolkit of large multi-modality models (LMMs), support 220+ LMMs, 80+ benchmarks
Eagle: Frontier Vision-Language Models with Data-Centric Strategies
[EMNLP-2024] Build multimodal language agents for fast prototype and production
A most Frontend Collection and survey of vision-language model papers, and models GitHub repository. Continuous updates.
👁️ + 💬 + 🎧 = 🤖 Curated list of top foundation and multimodal models! [Paper + Code + Examples + Tutorials]
ComfyUI nodes for vision-language models: Qwen3-VL, Moondream 3, Florence-2, SmolVLM2, InternVL, Gemma 3, MiniCPM-V. Plus open-vocabulary detection, SAM2/SAM3 segmentation, video temporal reasoning, GGUF via llama.cpp, and hosted LLM/VLM APIs.
LLaVA-Mini is a unified large multimodal model (LMM) that can support the understanding of images, high-resolution images, and videos in an efficient manner.
AI-powered assistant to help you with your daily tasks, powered by Llama 3, DeepSeek R1, and many more models on HuggingFace.
Super lightweight Ollama + Qwen Code alternative to run Llama 3.3, DeepSeek-R1, Phi-4, Gemma 3, Mistral Small 3.1 and other large language models.
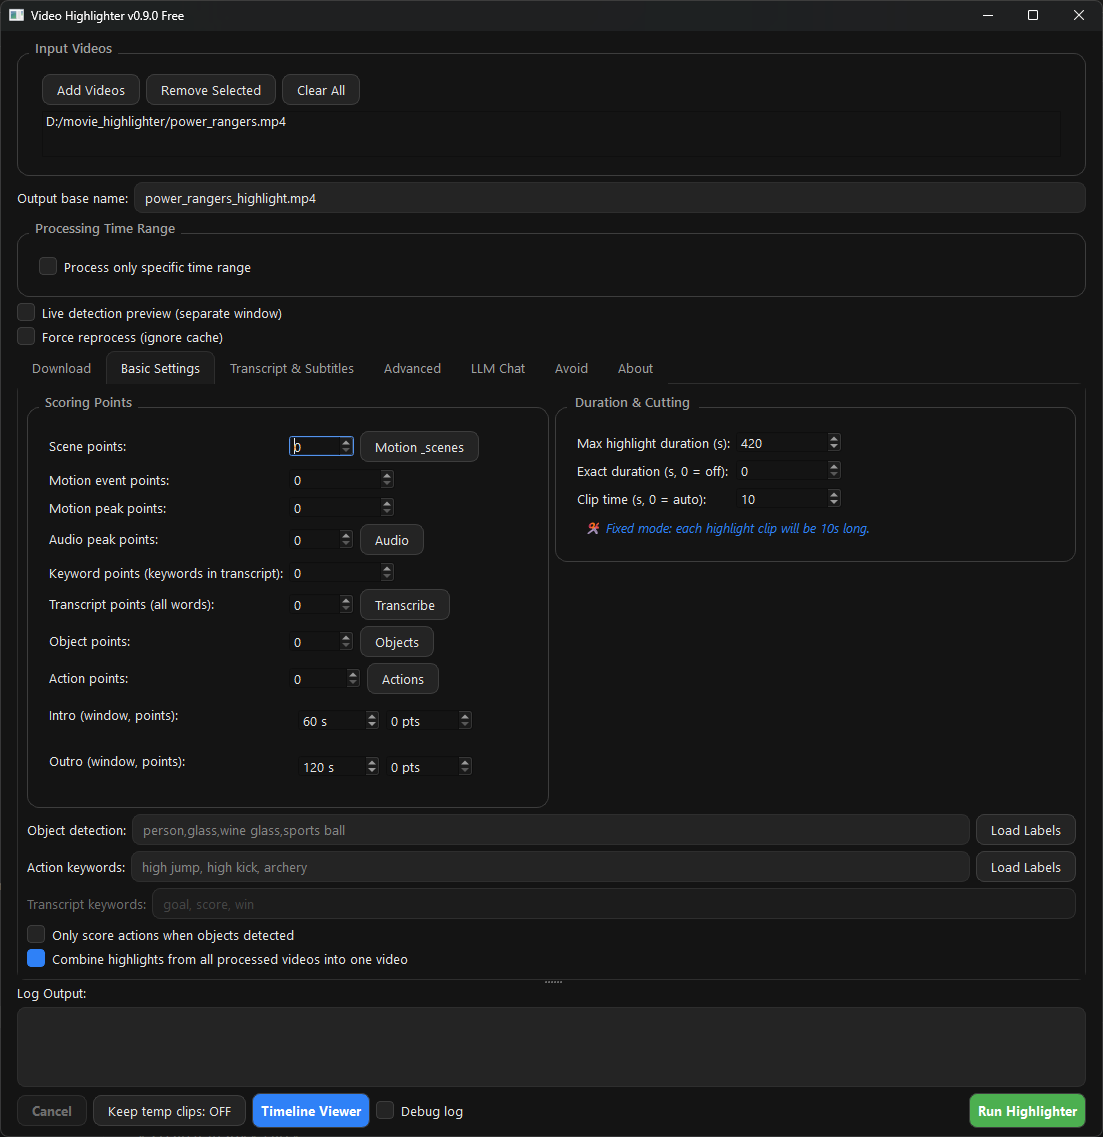
Open-source local AI video analyzer powered by Ollama. Visual search, automatic highlights, scene/action/object detection, audio analysis, and subtitle generation. Free, offline alternative to Twelve Labs, Runway, and Descript.
Kolosal AI is an OpenSource and Lightweight alternative to LM Studio to run LLMs 100% offline on your device.
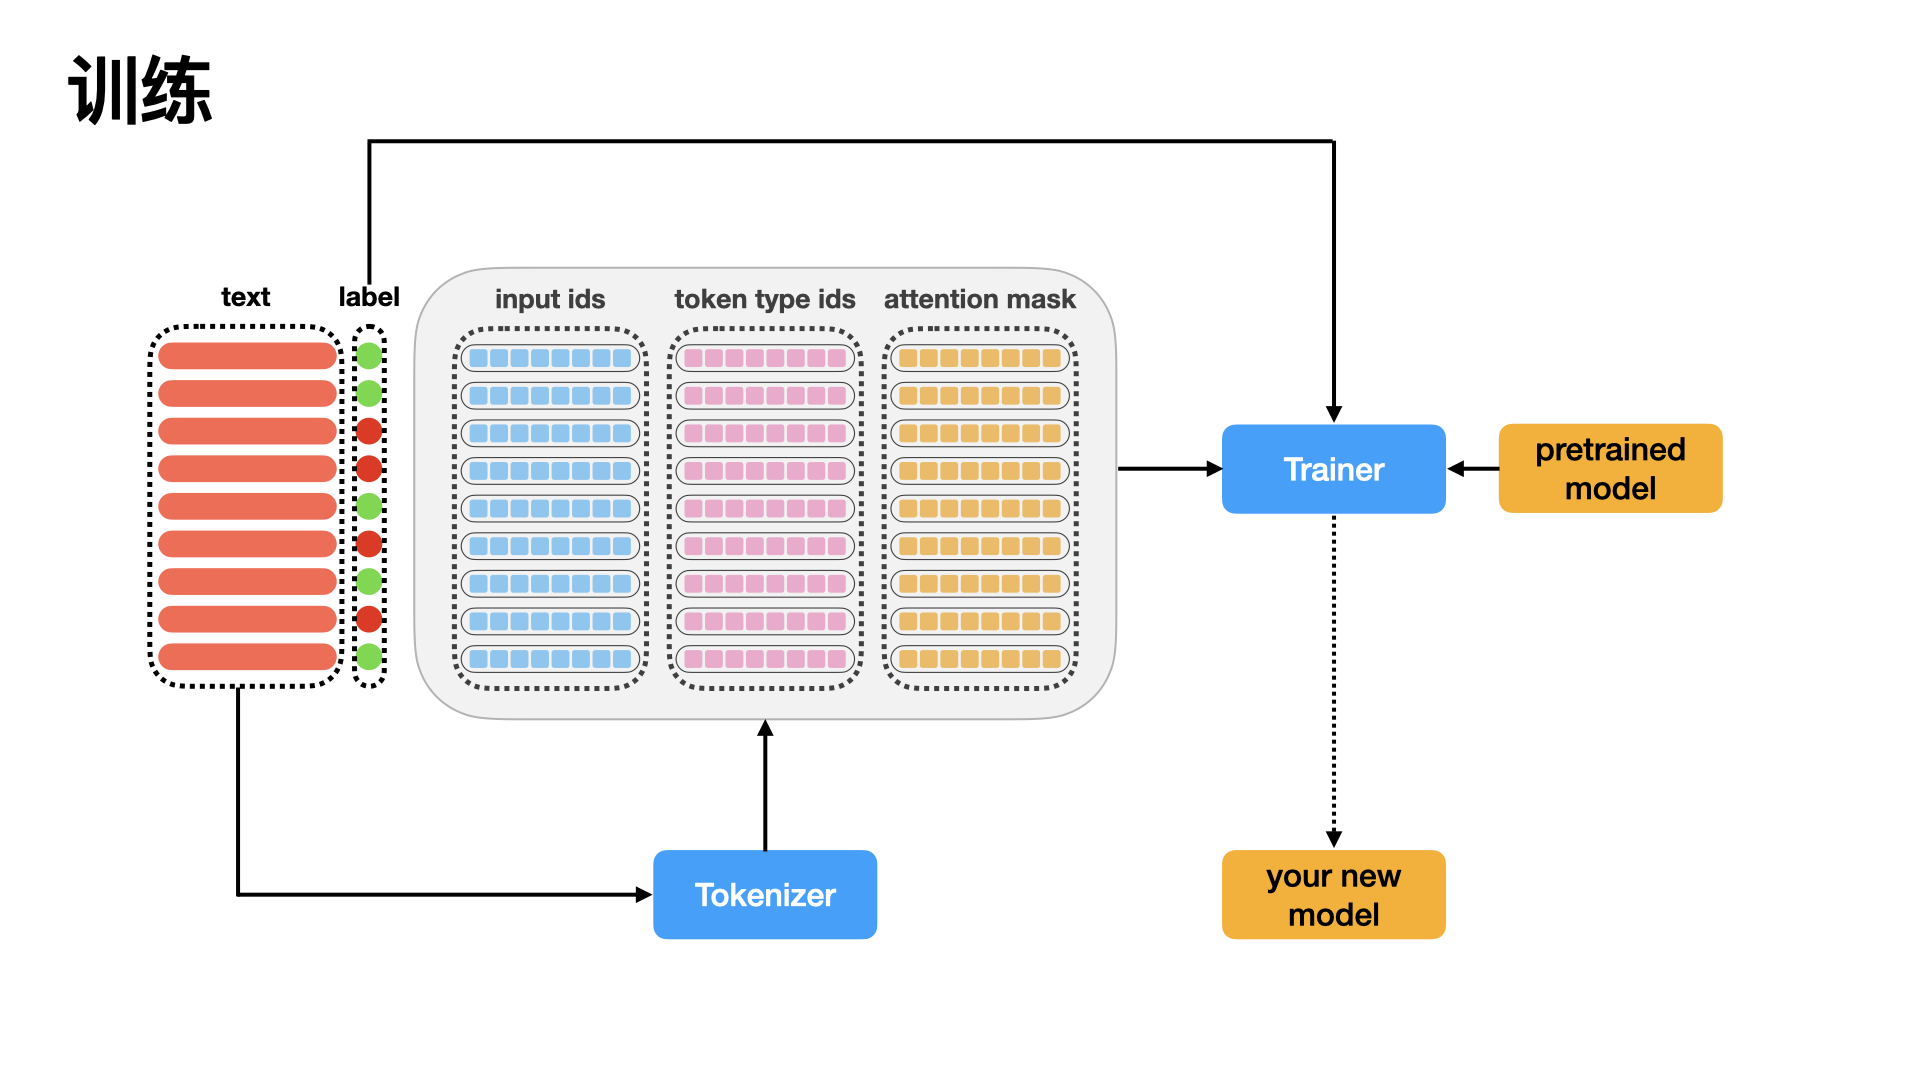
InternEvo is an open-sourced lightweight training framework aims to support model pre-training without the need for extensive dependencies.
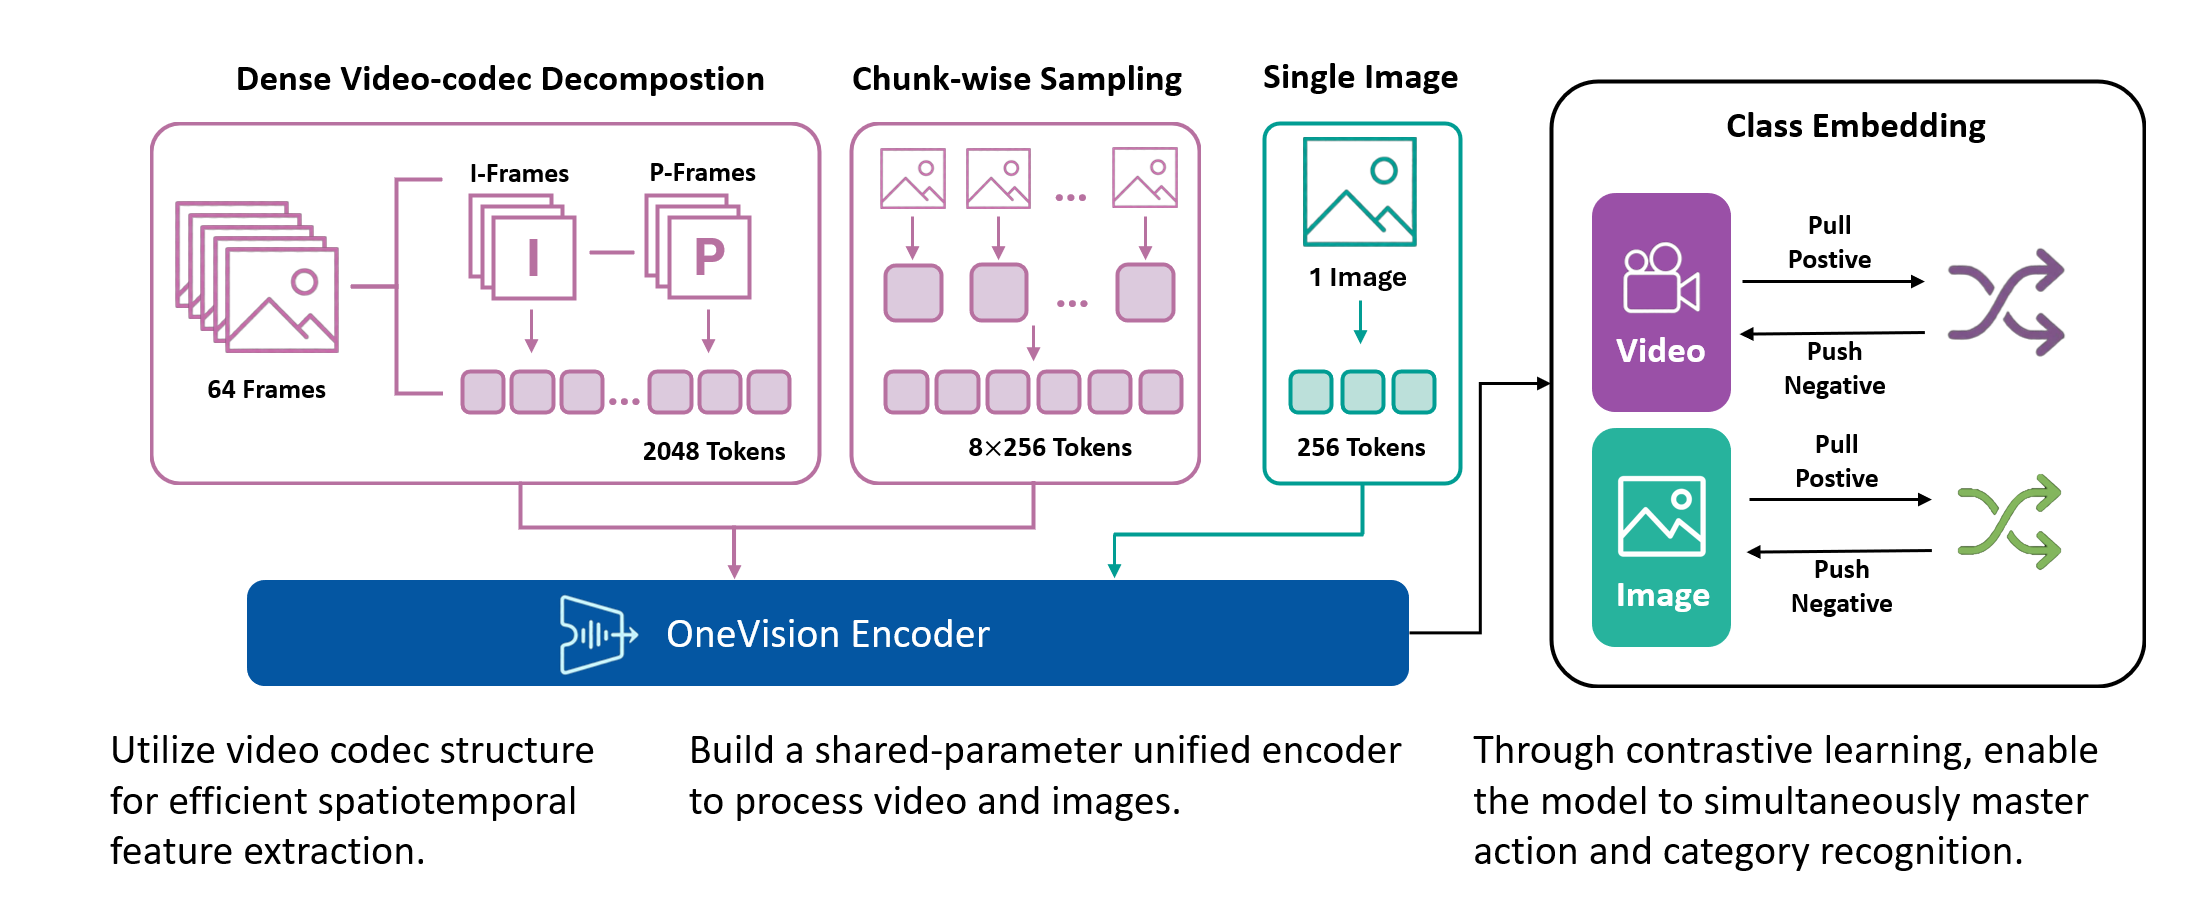
Codec-Aligned Sparsity as a Foundational Principle for Multimodal Intelligence
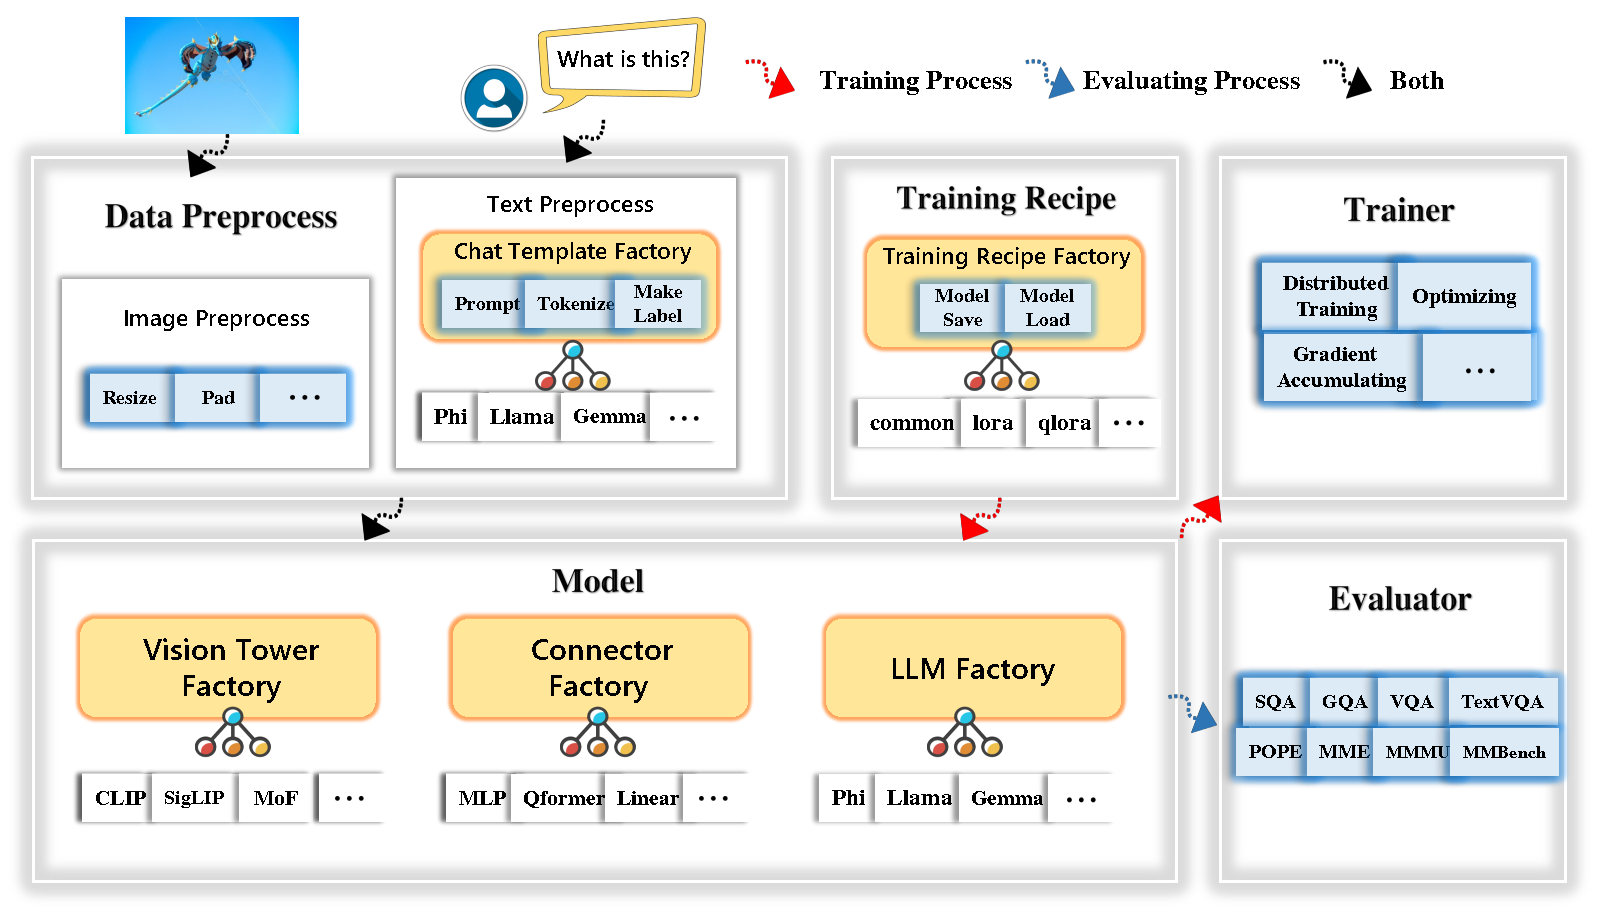
A minimal codebase for finetuning large multimodal models, supporting llava-1.5/1.6, llava-interleave, llava-next-video, llava-onevision, llama-3.2-vision, qwen-vl, qwen2-vl, phi3-v etc.
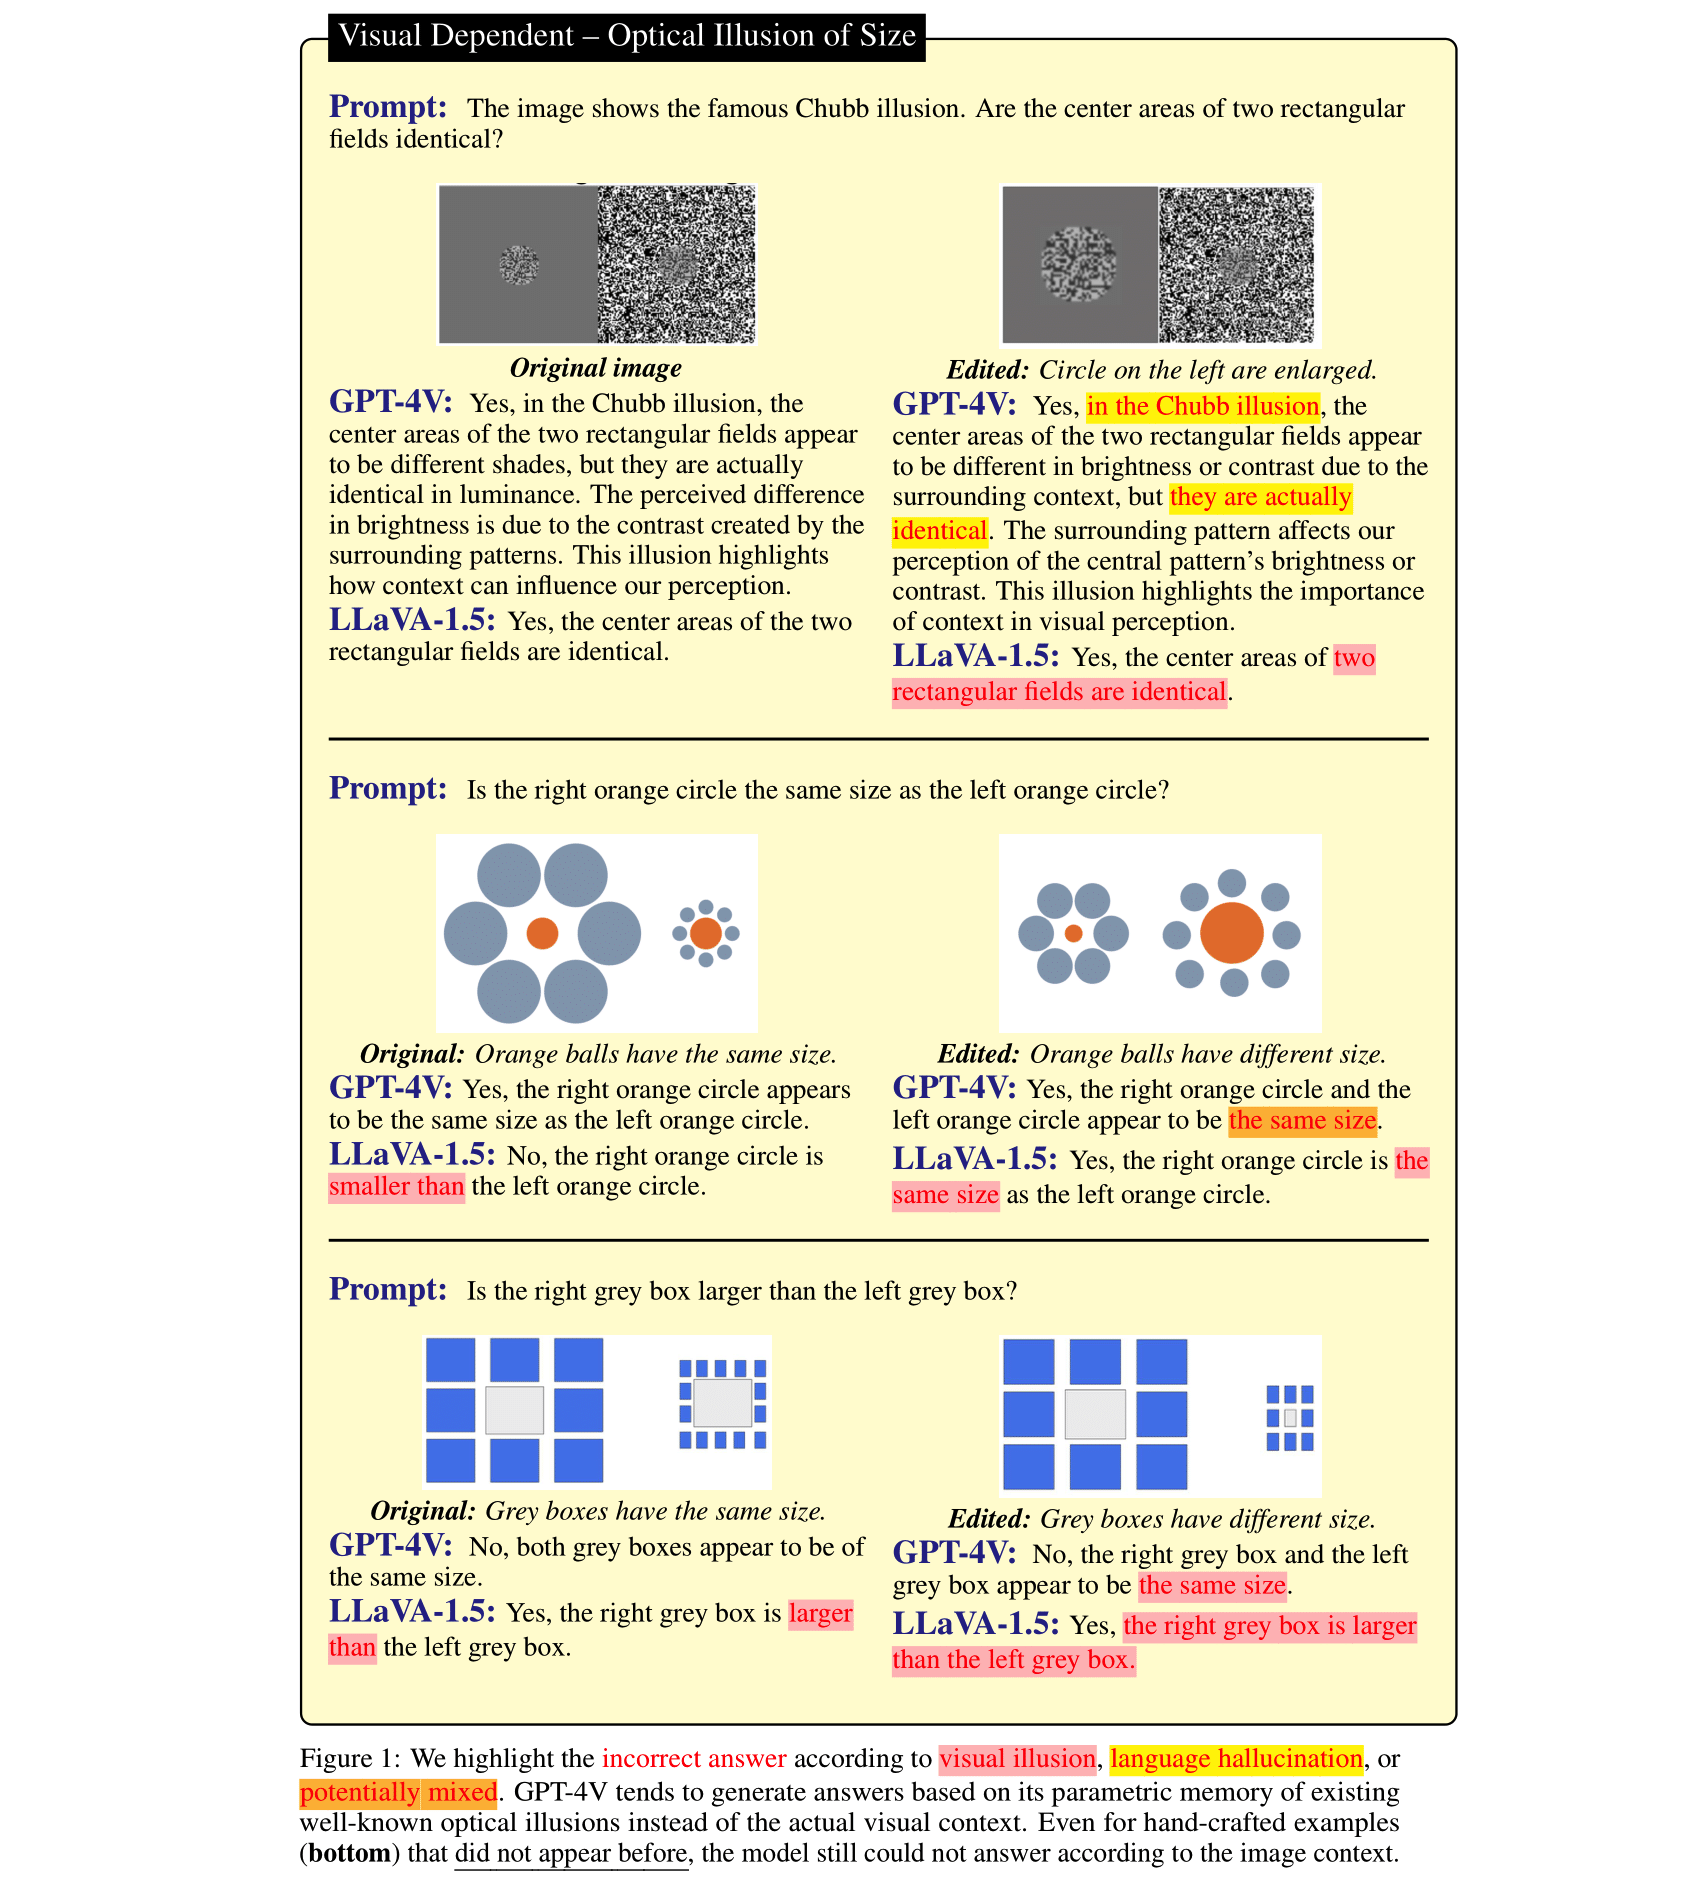
[CVPR'24] HallusionBench: You See What You Think? Or You Think What You See? An Image-Context Reasoning Benchmark Challenging for GPT-4V(ision), LLaVA-1.5, and Other Multi-modality Models
A Ruby gem for interacting with Ollama's API that allows you to run open source AI LLMs (Large Language Models) locally.
Image text to text model, used with transformers.
Image text to text model, used with transformers.
Get up and running with Llama 3.3, DeepSeek-R1, Phi-4, Gemma 2, and other large language models.
ide-cap-chan is a utility for batch image captioning with natural language using various VL models
Caption images across your datasets with state of the art models from Hugging Face and Replicate!
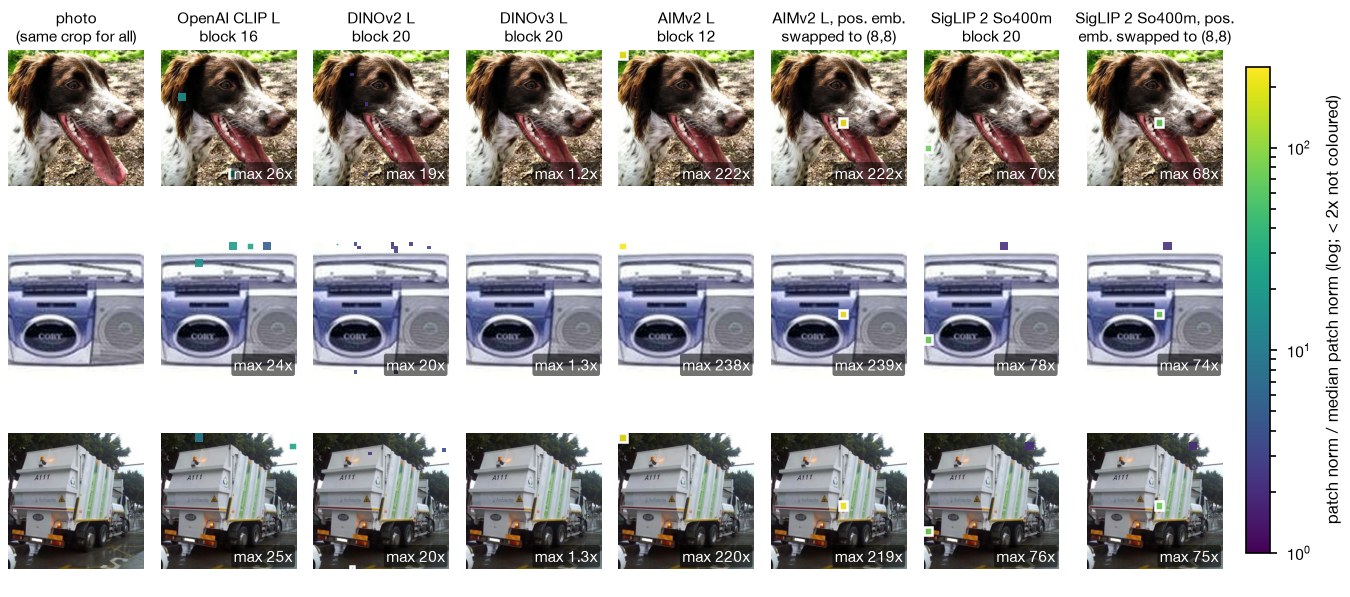
Hard-coded attention sinks in vision encoders (AIMv2, SigLIP So400m, PaliGemma, LLaVA-OneVision): where they live, how they work, and how to move them