firecrawl
Knowledge infrastructure to make your agents smarter. Search, scrape and 550+ data providers through one API.
- 204k
- TypeScript
- AGPL-3.0
- 2 h ago
Knowledge infrastructure to make your agents smarter. Search, scrape and 550+ data providers through one API.
🕷️ The BEST Web Scraping framework that handles everything from a single request to a full-scale crawl! Don't be shy, join here: https://discord.gg/EMgGbDceNQ and follow here for daily tips and tricks: https://x.com/Scrapling_dev
Create agents that monitor and act on your behalf. Your agents are standing by!
Stealth Chromium that passes every bot detection test. Drop-in Playwright replacement with source-level fingerprint patches. 50+ tests passed.
An autonomous agent that conducts deep research on any data using any LLM providers
Turn any website into a structured API. Extract, automate, search and monitor the web.
List of libraries, tools and APIs for web scraping and data processing.
Analysis of Bot Protection systems with available countermeasures 🚿. How to defeat anti-bot system 👻 and get around browser fingerprinting scripts 🕵️♂️ when scraping the web?
A Powerful web scraper powered by LLM | OpenAI, Gemini & Ollama
invisible playwright: Playwright that anti-bots cannot see, so no captchas: same API, anti-detect stealth headless Firefox, undetected fingerprint, bypass bot detection, Python web scraping and browser automation.
This code is used to perform web scraping and data extraction from Google Maps. It is particularly designed for obtaining information about businesses, including their name, address, website, phone number, reviews, and more.
A blazing fast, async-first, undetectable webscraping/web automation framework based on ultrafunkamsterdam/nodriver. Now with Docker support!
Creating Scrapy scrapers via the Django admin interface
invisible playwright mcp: Playwright MCP server undetected by anti-bots and captchas: AI agent browses the web on anti-detect stealth Firefox, Python, undetected browser automation, scraping, computer use.
Undetected NodeJS version of the Playwright testing and automation library.
Stealth Chromium engine that stops scrapers and browser agents from getting blocked, with one line of code change.
🤖 AI-powered web scraping editor with visual workflow builder. Build, test & deploy web scrapers using natural language. Powered by ScrapeGraphAI & LangGraph.
In this Python Web Scraping Tutorial, we will outline everything needed to get started with web scraping. We will begin with simple examples and move on to relatively more complex.
Web data extraction tool implemented as chrome extension
invisible selenium: Selenium that anti-bots cannot see, so no captchas: same API, anti-detect stealth headless Firefox, undetected fingerprint, bypass bot detection, Python web scraping and browser automation.
Open-source stealth Chromium with engine-level fingerprint spoofing - de-Googled, drop-in Playwright, fully buildable and verifiable from source.
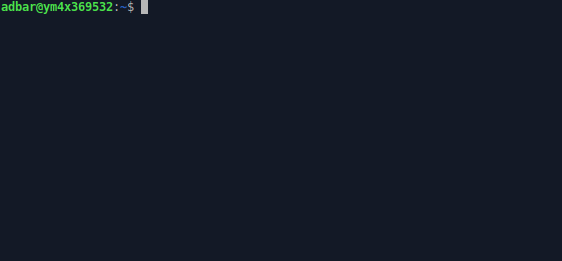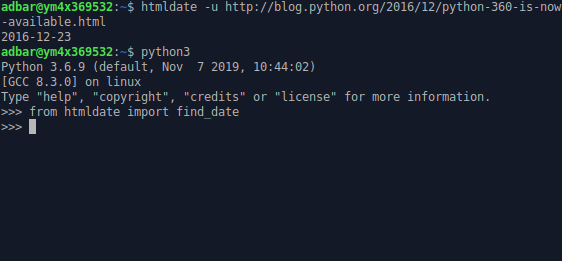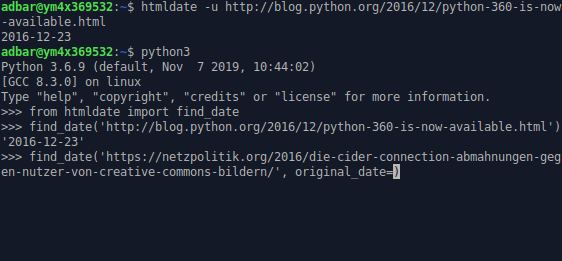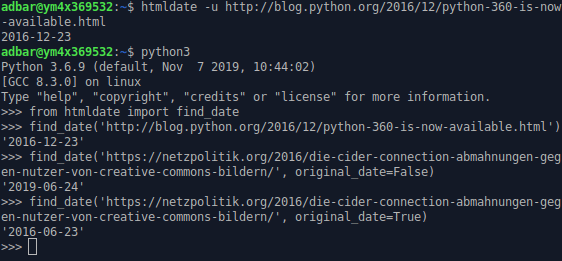
Fast and robust date extraction from web pages, with Python or on the command-line
Concurrent Go web crawler with first-class Tor SOCKS5 support, a CLI, versioned JSON reports, and a job-controlled HTTP API.
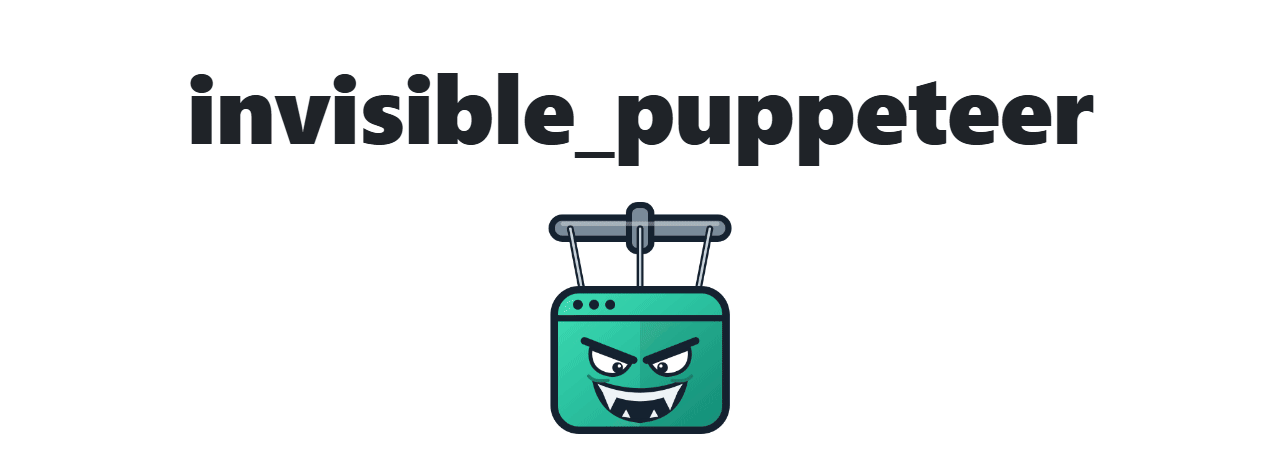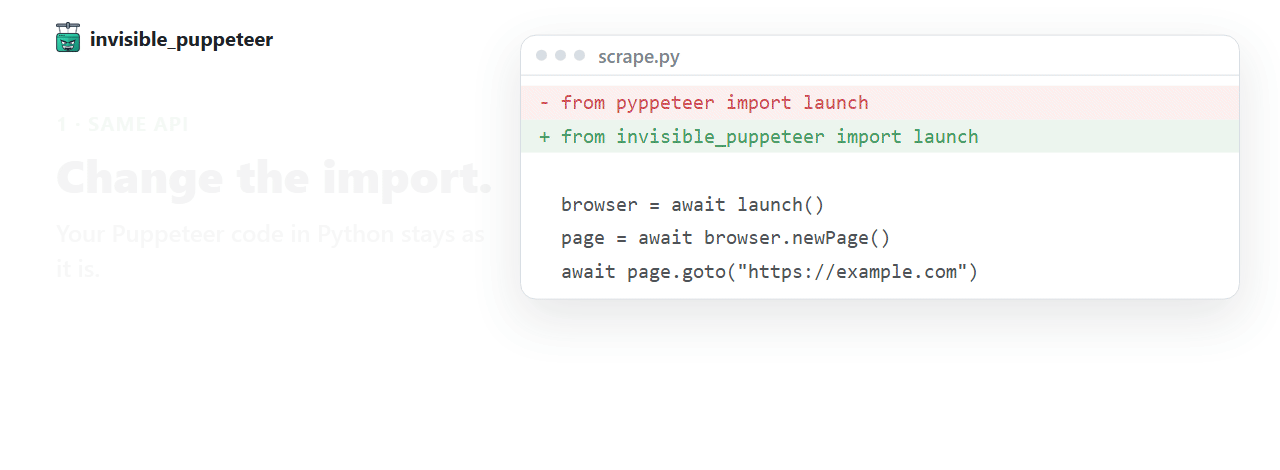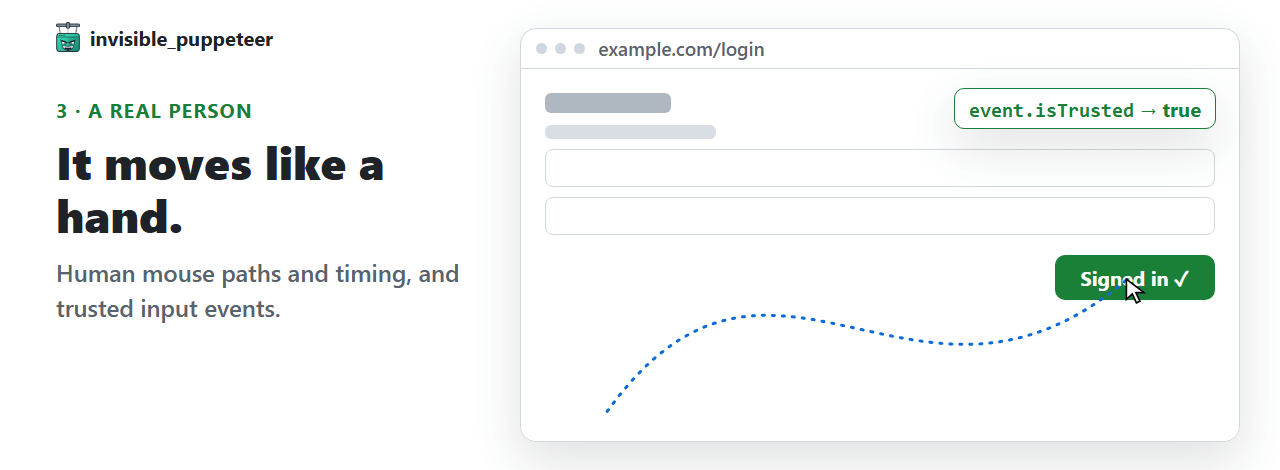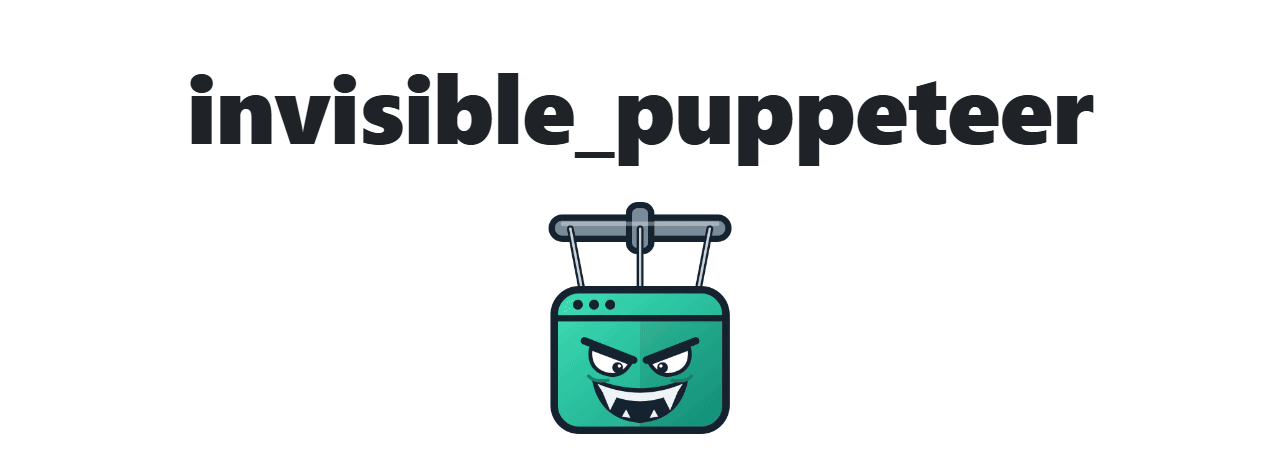
invisible puppeteer: Puppeteer for Python that anti-bots cannot see, so no captchas: same API, anti-detect stealth headless Firefox, undetected fingerprint, bypass bot detection, web scraping and browser automation.
A VS code Extension to accelerate the process of solving problems on Codeforces.
This repository contains data and code used to get and clean data from https://github.com/CSSEGISandData/COVID-19 and https://www.worldometers.info/coronavirus/