html2rss-web
🕸 Turn almost any website into an RSS feed and serve it instantly. Automatic scraping. Start fast with Docker.
- 200
- Ruby
- MIT
- 2 d ago
🕸 Turn almost any website into an RSS feed and serve it instantly. Automatic scraping. Start fast with Docker.
Plugin for website-scraper which returns html for dynamic websites using puppeteer
Download website to local directory (including all css, images, js, etc.)
Python-based web crawling script with randomized intervals, user-agent rotation, and proxy server IP rotation to outsmart website bots and prevent blocking.
ScrapeGPT is a RAG-based Telegram bot designed to scrape and analyze websites, then answer questions based on the scraped content. The bot utilizes Retrieval Augmented Generation and webscraping to return natural language answers to the user's queries.
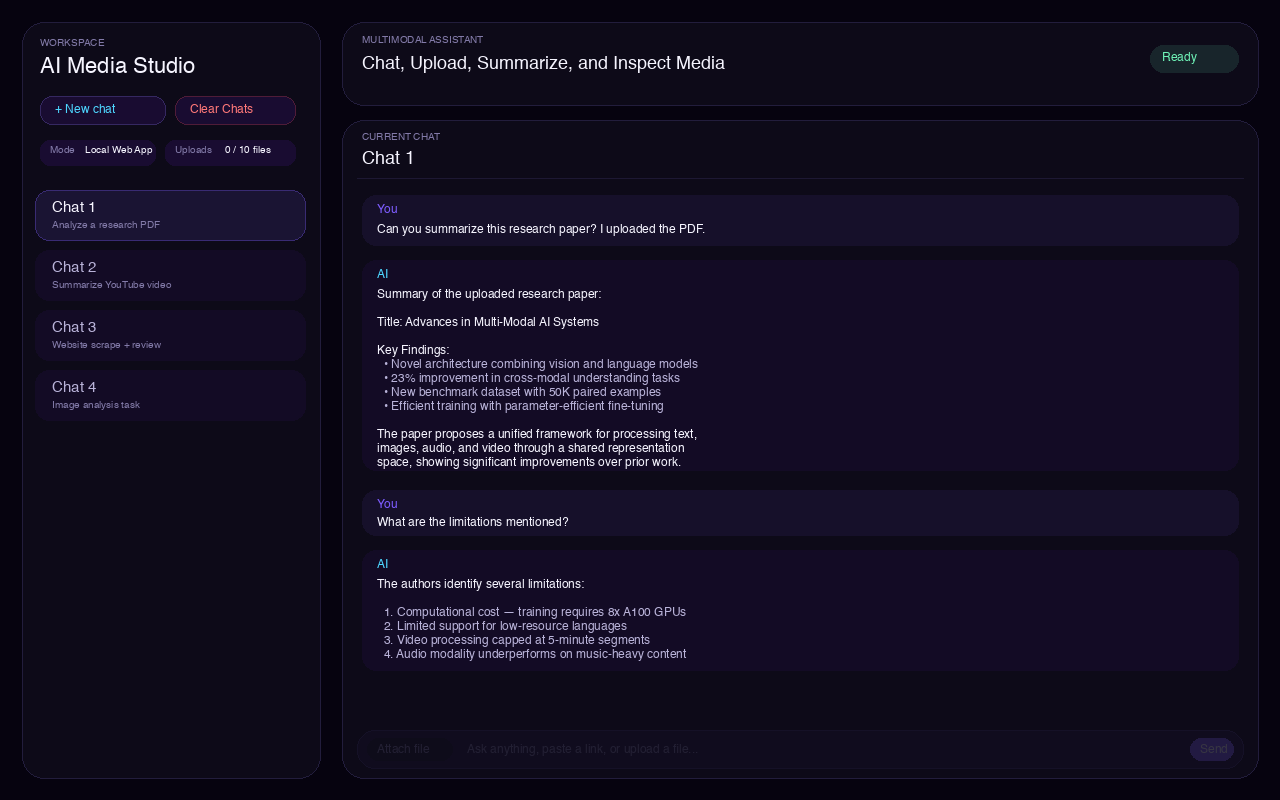
AI Media Studio summarizes websites, YouTube videos, documents, images, audio, and video through a desktop/web AI workspace.
Plugin for website-scraper which allows to save resources to existing directory
🕷️ | ReconX is a Live-Website Crawler made to gather critical information with an option to take a picture of each site crawled!
YouTube Scraper — free, open-source YouTube scraper. Unlimited videos, channels, comments & transcripts as clean JSON, no API key, no proxies.
Snapchat Scraper — free, open-source Snapchat scraper. Unlimited profiles, Spotlight videos, stories and lenses as clean JSON, no API key, no proxies.
Lowe's Scraper — free, open-source Lowe's scraper. Unlimited prices, store stock, aisle & bay, specs, reviews & deals as clean JSON, no API key, no proxies.
Wrapper for website-scraper-puppeteer package to allow use latest versions of puppeteer module