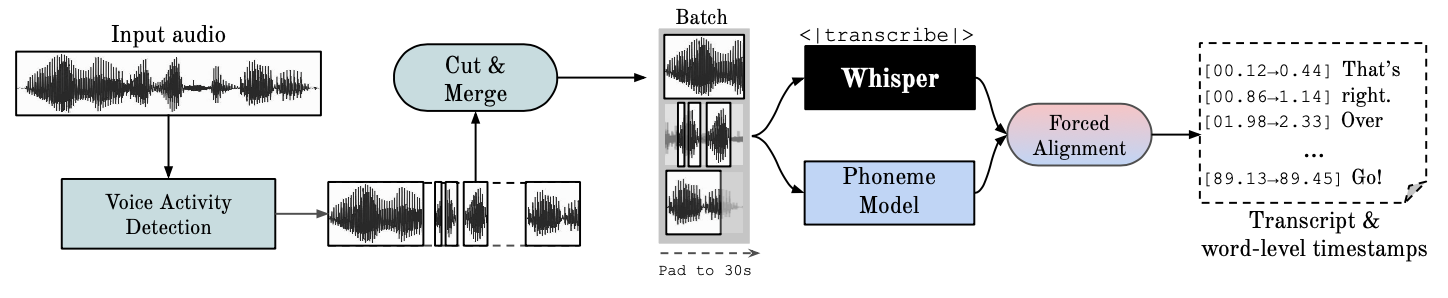
whisperX
WhisperX: Automatic Speech Recognition with Word-level Timestamps (& Diarization)
- 26k
- Python
- BSD-2-Clause
- 8 d ago

Open-source industrial-grade ASR models supporting Mandarin, Chinese dialects and English, achieving a new SOTA on public Mandarin ASR benchmarks, while also offering outstanding singing lyrics recognition capability.
Repo FireRedTeam/FireRedASR, read from GitHub 20 h ago. FireRedTeam has not joined Take My Repo.
FireRedTeam/FireRedASR is a public repo on GitHub by FireRedTeam. Open-source industrial-grade ASR models supporting Mandarin, Chinese dialects and English, achieving a new SOTA on public Mandarin ASR benchmarks, while also offering outstanding singing lyrics recognition capability. It declares the Apache-2.0 license on GitHub. It is written mainly in Python, has 2,014 stars and last changed on 2026-02-25. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-20.
GitHub is limiting requests or did not answer. The facts on this page still come from the last successful read.
Open on GitHubFireRedTeam/FireRedASR is a public repo on GitHub by FireRedTeam. Open-source industrial-grade ASR models supporting Mandarin, Chinese dialects and English, achieving a new SOTA on public Mandarin ASR benchmarks, while also offering outstanding singing lyrics recognition capability.
It declares the Apache-2.0 license on GitHub.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Its last change on GitHub was on 2026-02-25. Take My Repo does not judge from that whether it is maintained.
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.
WhisperX: Automatic Speech Recognition with Word-level Timestamps (& Diarization)
Real-time, local speech-to-text with streaming ASR, speaker diarization, translation, and OpenAI/Deepgram-compatible APIs.
Easy-to-use Speech Toolkit including Self-Supervised Learning model, SOTA/Streaming ASR with punctuation, Streaming TTS with text frontend, Speaker Verification System, End-to-End Speech Translation and Keyword Spotting. Won NAACL2022 Best Demo Award.
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
Open-source speech recognition toolkit for training, inference, streaming ASR, VAD, punctuation, speaker diarization pipelines, and OpenAI-compatible/MCP serving.
FireRed-OpenStoryline is an AI video editing agent that transforms manual editing into intention-driven directing through natural language interaction, LLM-powered planning, and precise tool orchestration. It facilitates transparent, human-in-the-loop creation with reusable Style Skills for consistent, professional storytelling.
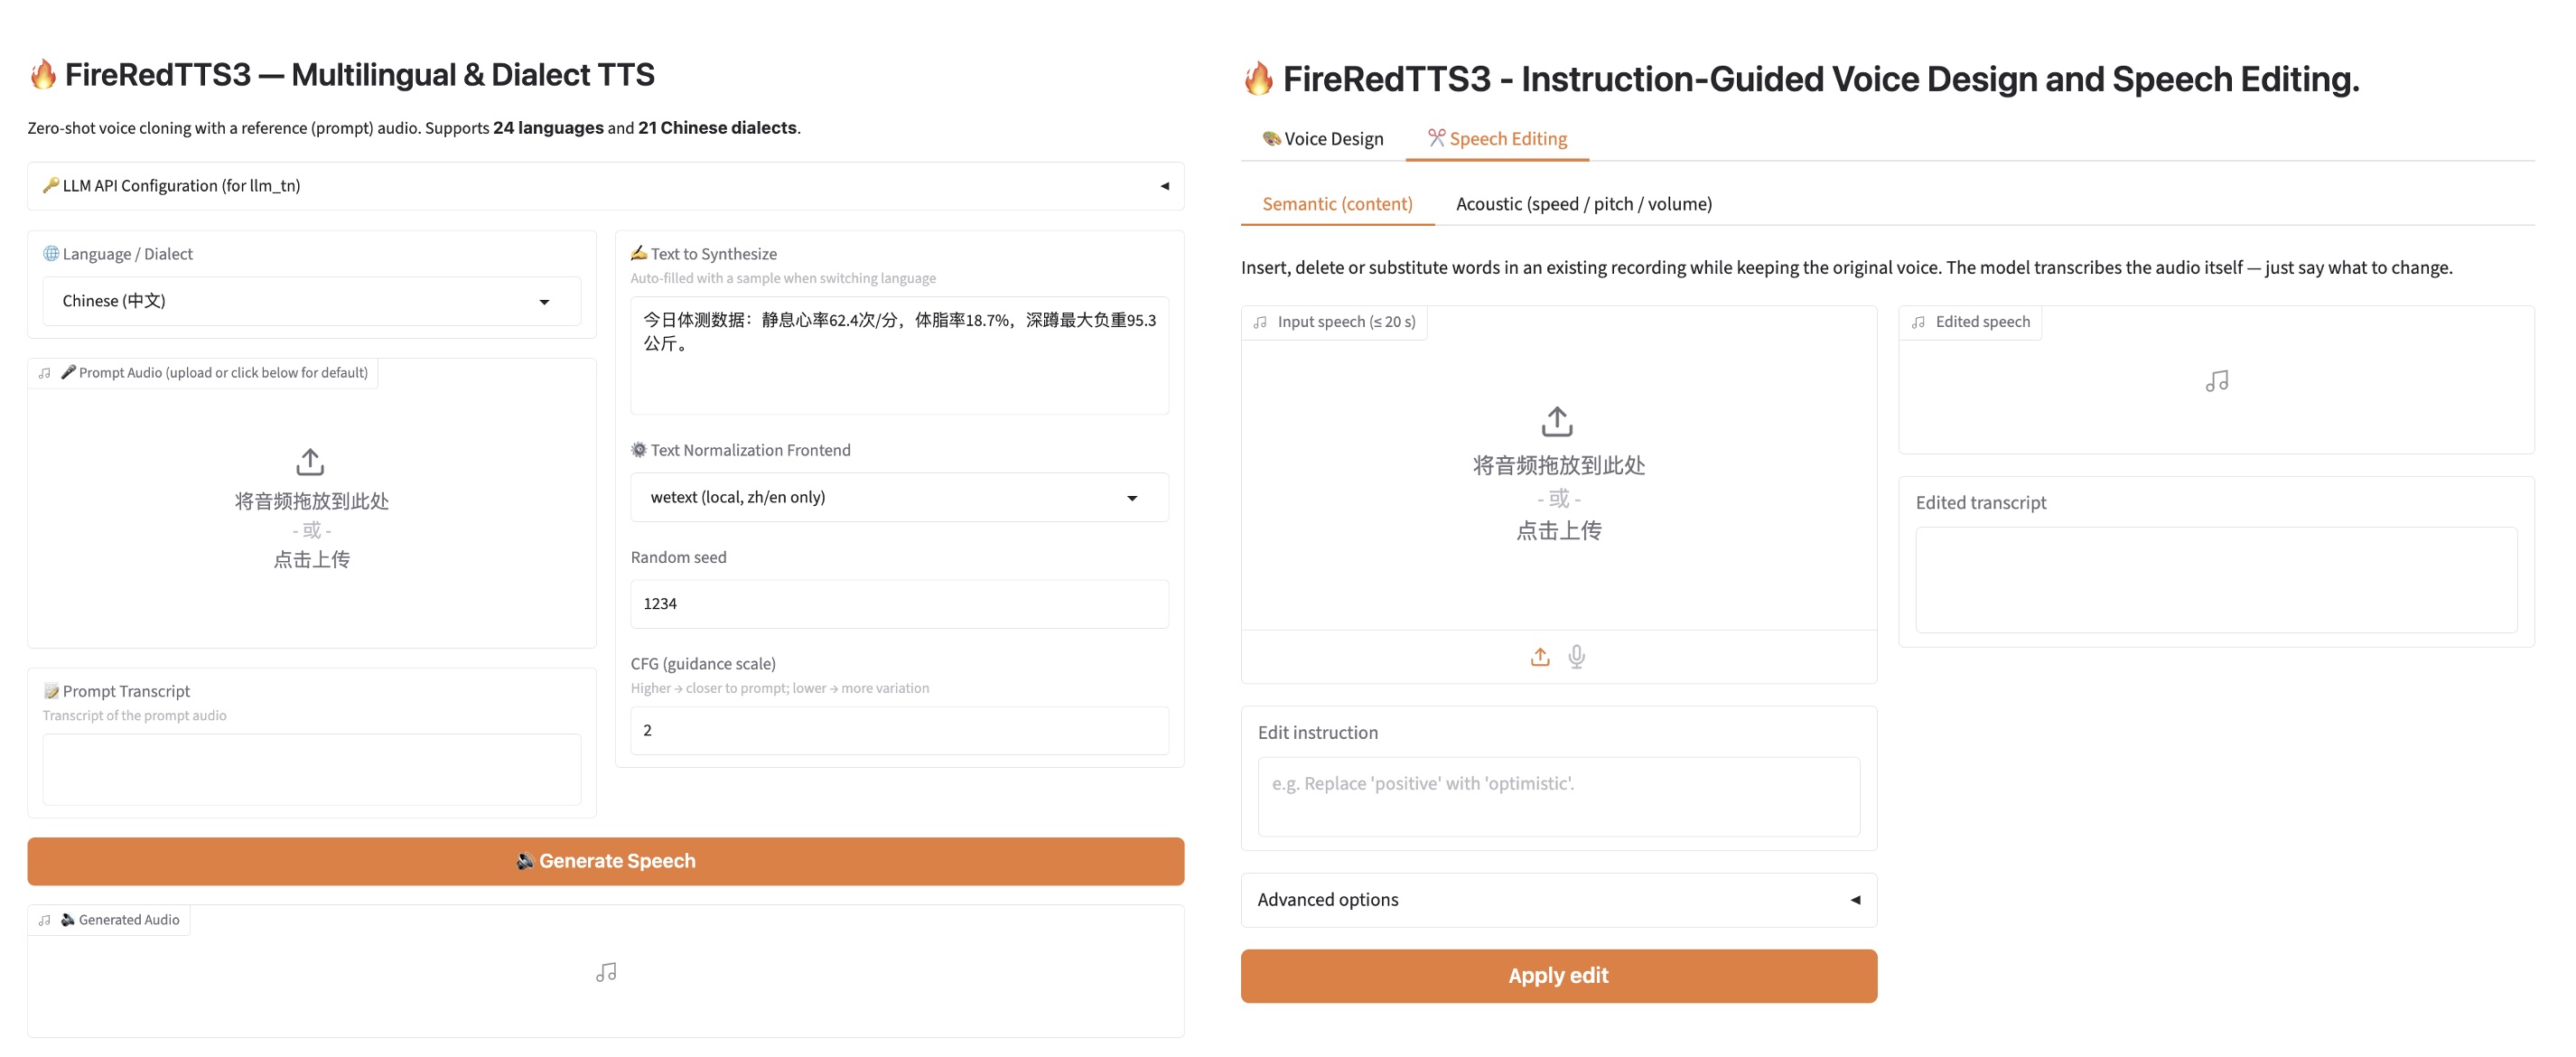
FireRedTTS3: Multilingual and Multi-Dialect Voice Cloning with Instruction-Guided Voice Design and Speech Editing
Long-form streaming TTS system for multi-speaker dialogue generation
FireRed-Image-Edit is a powerful image editing foundation model achieving open-source state-of-the-art performance with precise instruction following, high-fidelity generation, superior identity consistency, and seamless multi-element fusion.