
whisperX
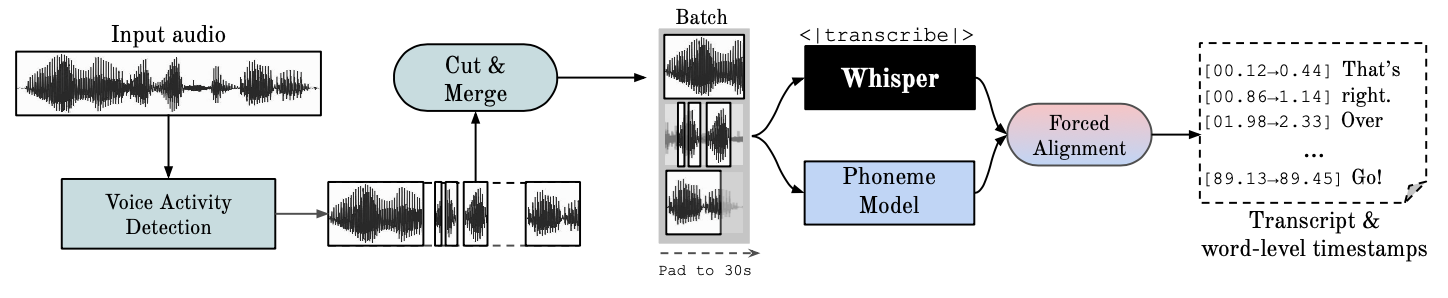
WhisperX: Automatic Speech Recognition with Word-level Timestamps (& Diarization)
- 26k
- Python
- BSD-2-Clause
- 8 d ago
audio.cpp with a full-task WebUI - pure C++ audio-model inference engine powered by ggml. TTS, ASR/STT, VAD, voice conversion, speaker diarization, music generation. No Python dependency.
Repo kigner/audio.cpp-webui, read from GitHub 12 h ago. kigner has not joined Take My Repo.
kigner/audio.cpp-webui is a public repo on GitHub by kigner. audio.cpp with a full-task WebUI - pure C++ audio-model inference engine powered by ggml. TTS, ASR/STT, VAD, voice conversion, speaker diarization, music generation. No Python dependency. It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it. It is written mainly in C++, has 435 stars and last changed on 2026-11-05. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-20.
GitHub is limiting requests or did not answer. The facts on this page still come from the last successful read.
Open on GitHubkigner/audio.cpp-webui is a public repo on GitHub by kigner. audio.cpp with a full-task WebUI - pure C++ audio-model inference engine powered by ggml. TTS, ASR/STT, VAD, voice conversion, speaker diarization, music generation. No Python dependency.
It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Its last change on GitHub was on 2026-11-05. Take My Repo does not judge from that whether it is maintained.
WhisperX: Automatic Speech Recognition with Word-level Timestamps (& Diarization)
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
Reverse engineer anything with agents, from app behavior down to native binaries.
VoiceStudio is the open-source, fully-local ElevenLabs alternative — voice cloning, voice design, video dubbing, dictation, transcription & audiobook creation in 646 languages.
利用 AI 大模型和自动化工作流,根据主题或关键词一键生成高清短视频。Generate HD short videos from a topic or keyword with an automated AI workflow.
Based on Hermes Agent's `llm-wiki` skill and Andrej Karpathy's LLM Wiki pattern; extended with multimodal ingestion and provenance hardening.


