cronboard
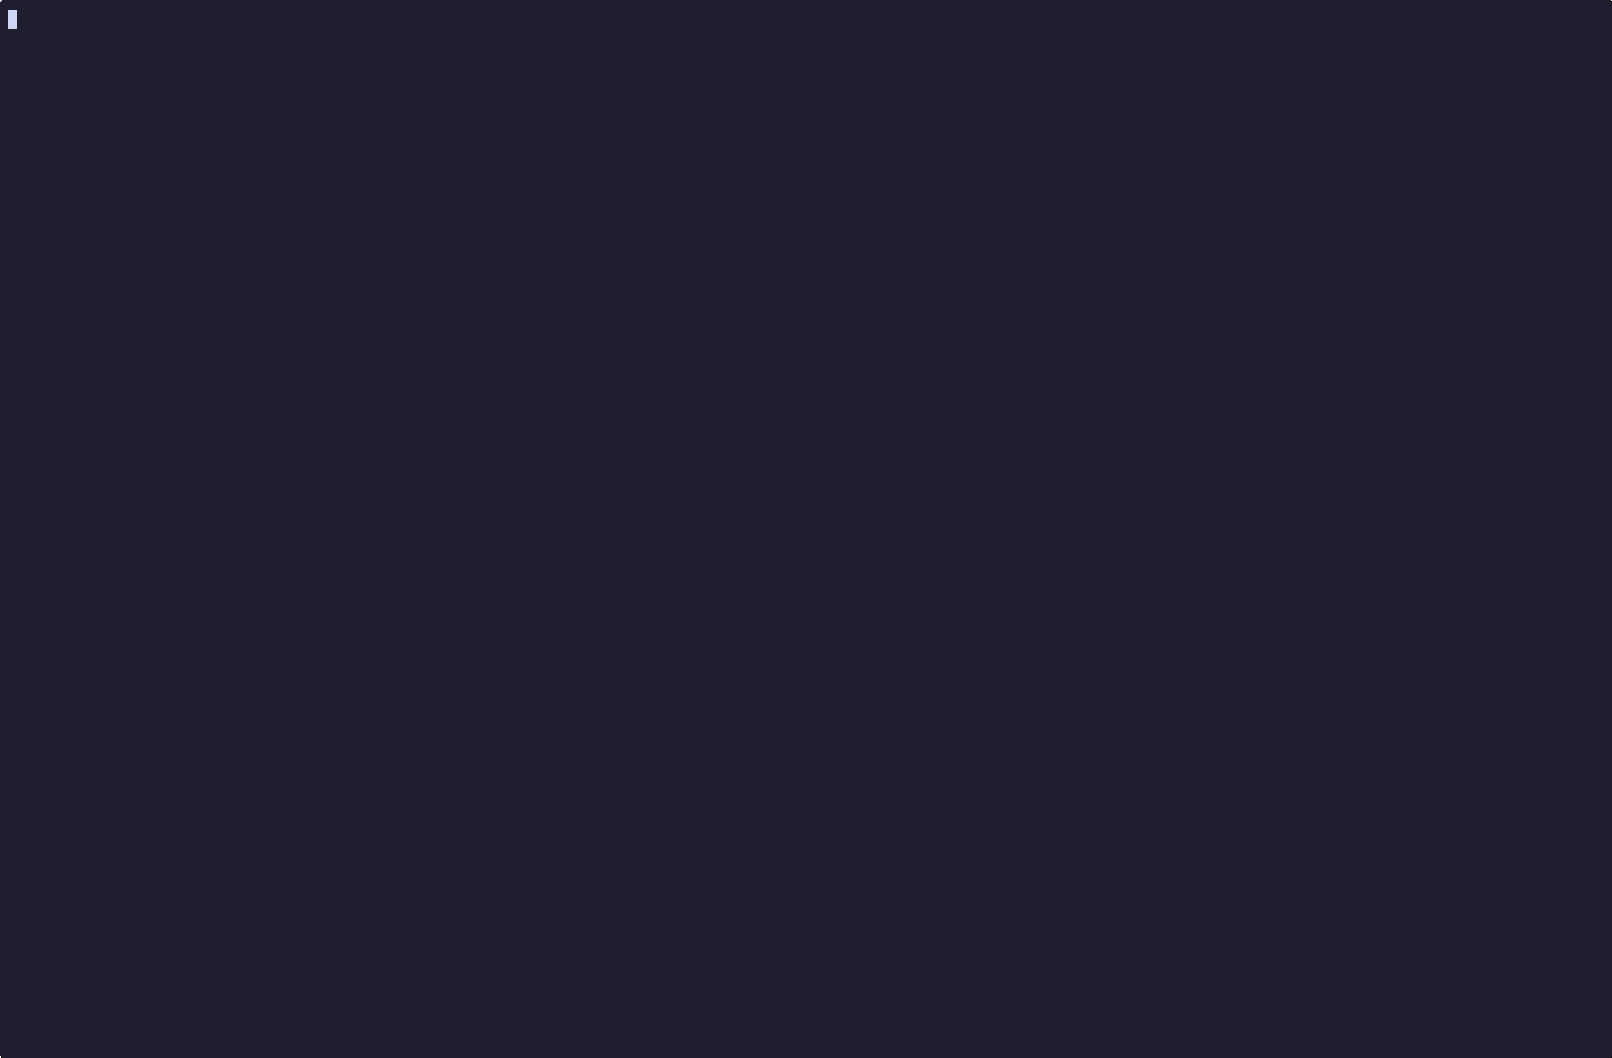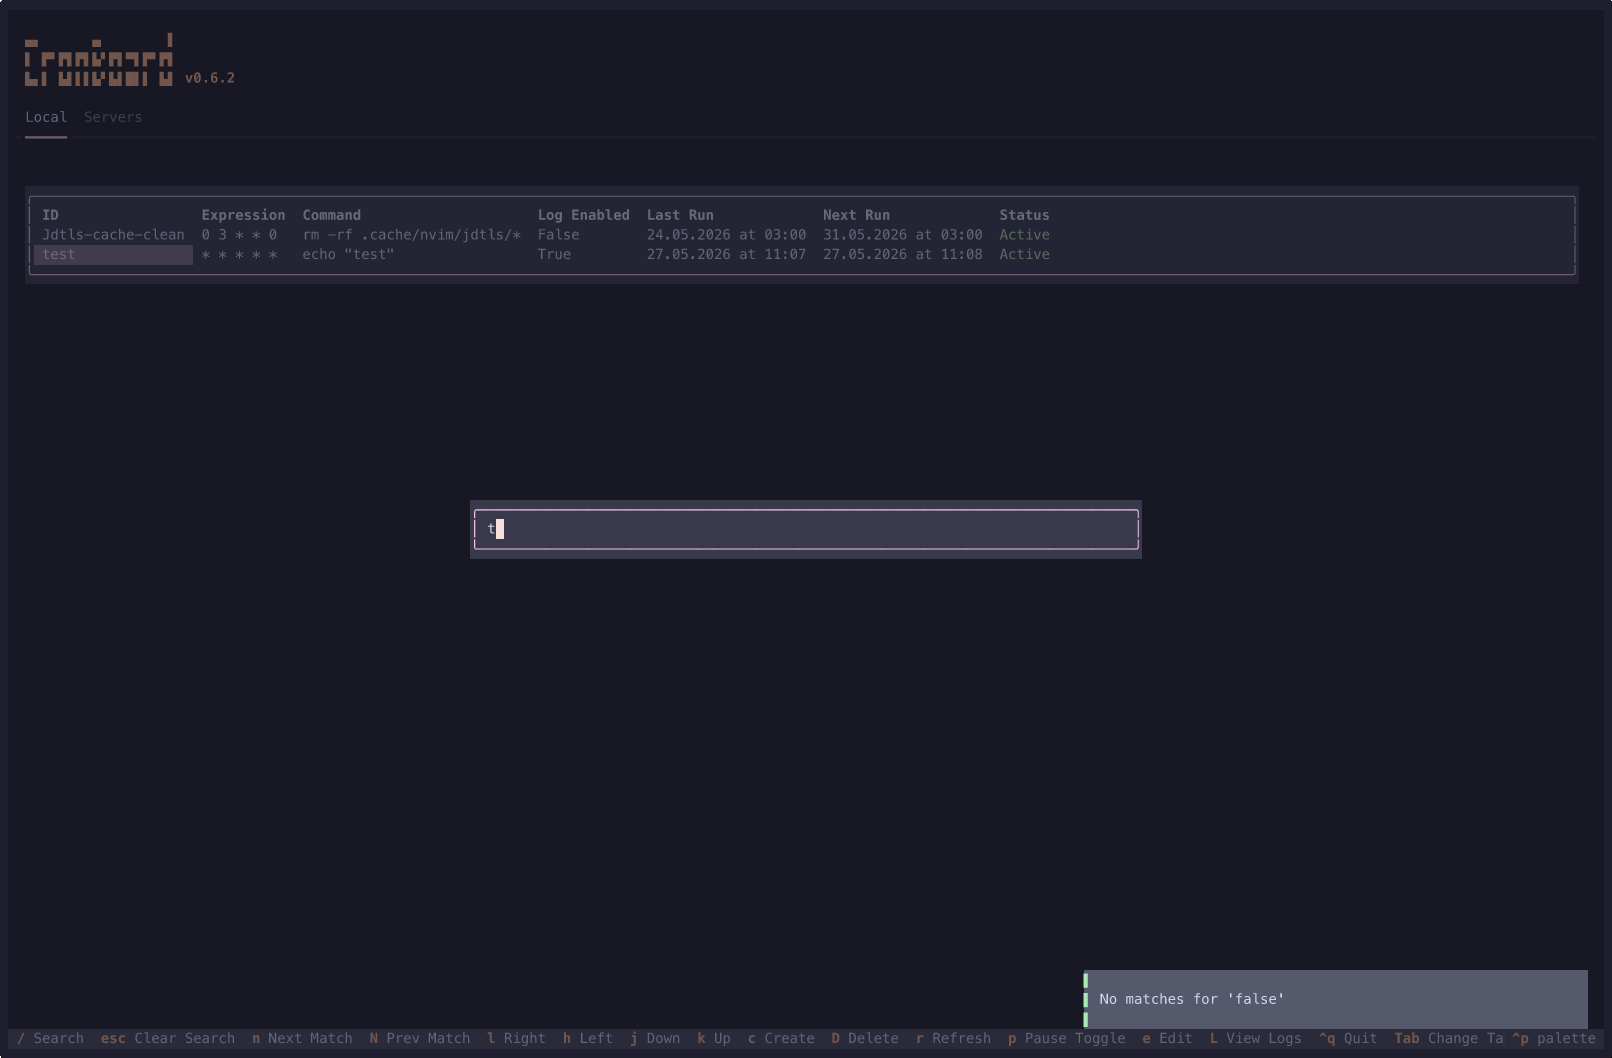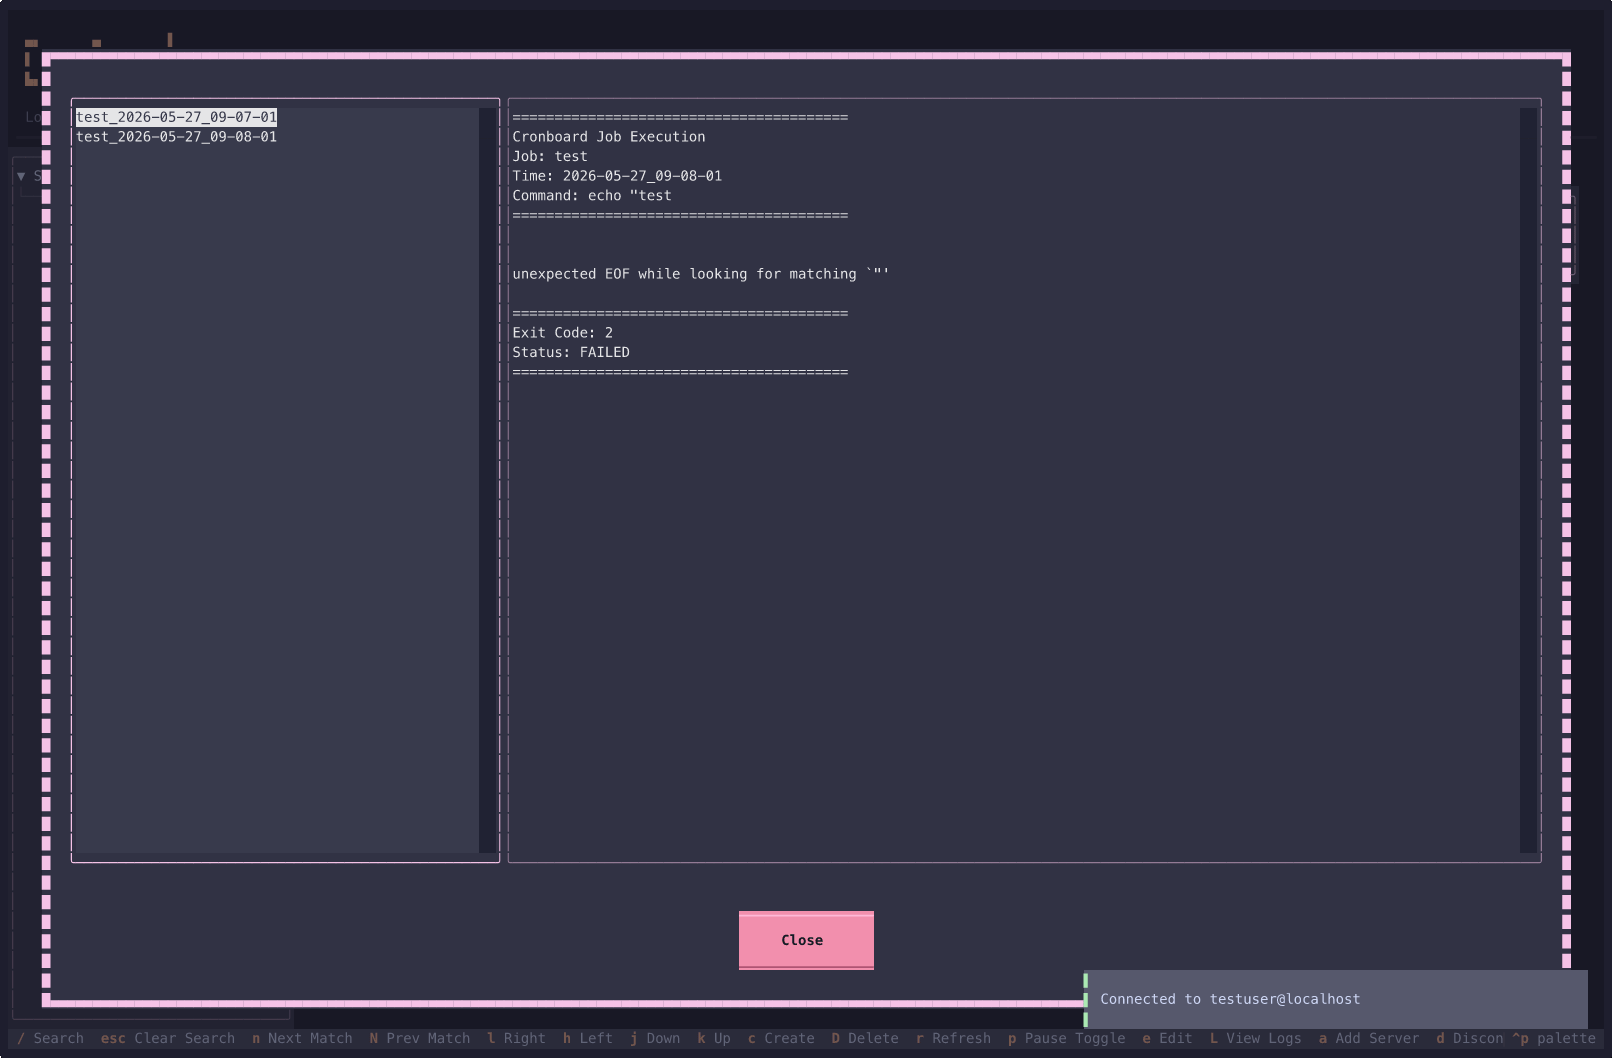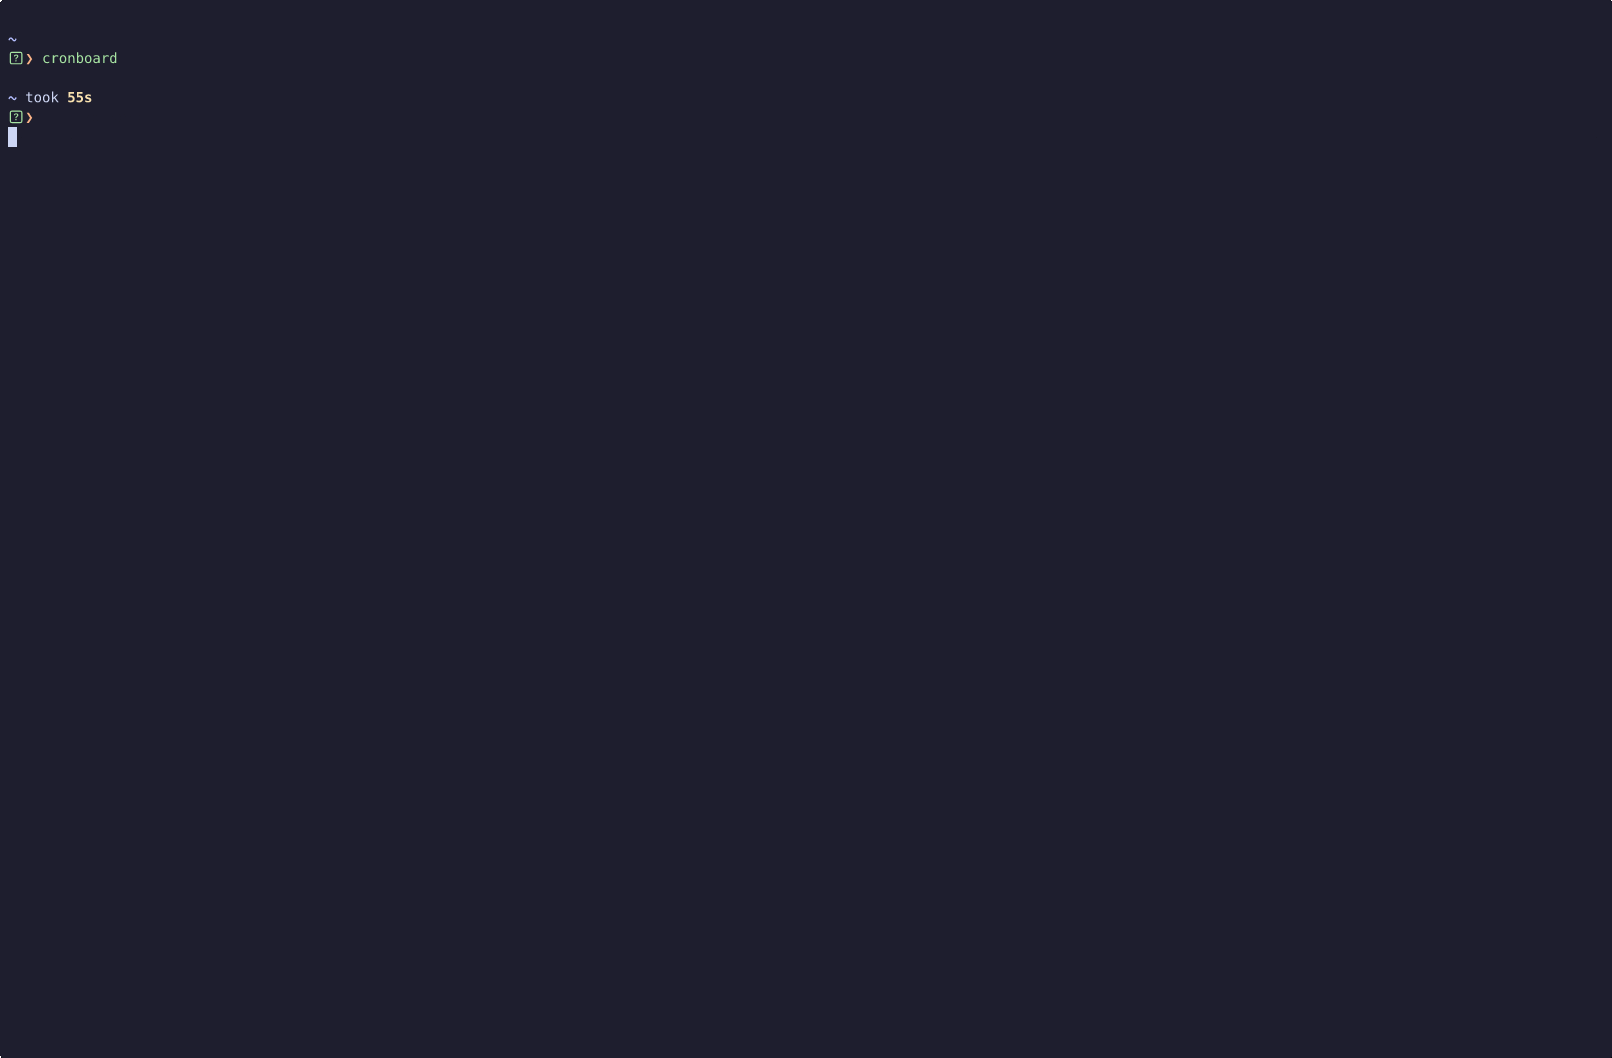
A terminal-based dashboard for managing cron jobs locally and on servers.
- 1.5k
- Python
- Apache-2.0
- 10 d ago
Incremental paginated API to Render Postgres sync with durable checkpoints and idempotent upserts
Repo render-examples/render-postgres-etl, read from GitHub 1 min ago. render-examples has not joined Take My Repo.
render-examples/render-postgres-etl is a public repo on GitHub by render-examples. Incremental paginated API to Render Postgres sync with durable checkpoints and idempotent upserts. It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it. It is written mainly in Python, has 2 stars and last changed on 2026-08-11. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-20.
A production-ready example for syncing a paginated API to Render Postgres on a schedule.
This example demonstrates:
run_sync                                   [orchestrator, no retries]
├─ migrate                                 idempotent DDL
├─ open_run                                claims a DB lease, computes [since, until)
├─ fetch_slice ×8   ── in parallel ──▶     each paginates its own time window,
│                                          checkpointing after every page
├─ load_batch                              staging → target, guarded upsert
└─ advance_watermark                       only after the load commits
Each phase is a registered task and appears separately in the Render Dashboard.
| Service | Type | Role |
|---|---|---|
api-sync |
Workflow (Python) | Task definitions; all sync logic |
sync-db |
Postgres | Destination tables and sync state |
api-sync-trigger |
Cron Job | Starts run_sync on a schedule via the Render API |
Postgres stores both destination rows and sync state. Fetch tasks write directly to staging because task instances do not share a filesystem and task return values should remain small.
Cursor pages are sequential, so parallelism is applied across independent time windows. A Postgres lease prevents Workflow, API, Dashboard, and backfill runs from overlapping for the same connector and stream.
Workflows are not yet supported in Blueprints, so deployment has two parts.
1. Deploy the Blueprint. Point Render at this repo's render.yaml. It creates
sync-db (Postgres) and api-sync-trigger (the cron job).
2. Create the Workflow service. Dashboard → New → Workflow, from the same repo:
| Setting | Value |
|---|---|
| Language | Python |
| Build command | pip install -r requirements.txt |
| Start command | python main.py |
| Region | same as sync-db, so it reaches the database over the private network |
Add DATABASE_URL to the Workflow's environment, using sync-db's internal
connection string.
3. Wire the trigger. On api-sync-trigger, set RENDER_API_KEY and set
WORKFLOW_TASK_SLUG to the slug shown in the Dashboard for run_sync (it looks
like api-sync/run_sync). The task slug is available after the Workflow is
created.
Then trigger the first run manually from the Dashboard with input [].
pip install -r requirements-dev.txt
render workflows dev -- python main.py
render workflows tasks start run_sync --local --input='[]'Trigger run_sync from the Dashboard with input []. The default fake
connector requires no credentials and fans out across eight fetch_slice tasks.
select count(*), min(source_updated_at), max(source_updated_at) from fake_charges;
--  40320 | ...
select * from sync_state;
select slice_index, pages_fetched, rows_staged, cursor, status
  from sync_slice where run_id = (select run_id from sync_run
                                  order by created_at desc limit 1);
Set the following environment variable on the Workflow:
FAKE_FAIL_ON_PAGE=47
Trigger run_sync again. Render retries the failed slice and resumes from its
last committed cursor:
{"event": "slice_resumed", "slice_index": 0, "cursor": "47", "pages_already_fetched": 46}
{"event": "slice_complete", "slice_index": 0, "pages_fetched": 51, "pages_this_attempt": 5, "resumed": true}
The retry fetches pages 47–51 without re-fetching pages 1–46. Remove
FAKE_FAIL_ON_PAGE after testing.
sync_slice stores each slice's time window, cursor, counters, attempts, and
status. Each page commits its staged rows and next cursor in the same transaction.
The final page also commits status = 'complete', so a lost response cannot
restart the slice from page 1.
insert into stg_fake_charges (run_id, id, ..., source_updated_at)
values (...)
on conflict (run_id, id) do update set ...
 where stg_fake_charges.source_updated_at < excluded.source_updated_at;

insert into fake_charges (id, amount, currency, status, source_updated_at)
select id, amount, currency, status, source_updated_at
  from stg_fake_charges
 where run_id = %s
on conflict (id) do update set
    amount            = excluded.amount,
    currency          = excluded.currency,
    status            = excluded.status,
    source_updated_at = excluded.source_updated_at
 where fake_charges.source_updated_at <= excluded.source_updated_at;
The staging guard keeps the newest version fetched during a run. The target guard rejects stale replays from previous runs.
The watermark advances only after load_batch commits. It is derived from
window_end - SYNC_OVERLAP_SECONDS, not from observed rows, so empty windows and
source clock skew do not create gaps. Watermark updates are monotonic and
retry-safe.
The default fake connector generates deterministic records and requires no
credentials.
Set SYNC_CONNECTOR=stripe and provide STRIPE_API_KEY.
The Stripe connector reads /v1/events instead of /v1/charges. Charge list
endpoints filter by creation time and do not capture later refunds, disputes, or
status changes. Event timestamps provide the change-ordering field used by the
sync.
Stripe retains events for 30 days. Backfill older charges separately:
render workflows tasks start backfill --input='{"since": "2025-01-01T00:00:00Z"}'The backfill graph uses the same checkpoints and run lease as incremental sync, but does not modify the incremental watermark.
Add a module under connectors/ that implements the protocol in
connectors/base.py:
class Connector(Protocol):
    name: str
    stream: str
    target_table: str
    primary_key: tuple[str, ...]
    columns: tuple[Column, ...]

    def plan_windows(self, since: datetime, until: datetime) -> list[Window]: ...
    def fetch_page(self, window: Window, cursor: str | None) -> Page: ...
    def normalize(self, record: dict) -> dict: ...
Page contains rows, next_cursor, and has_more. normalize returns the
declared target row shape. Give each connector a unique target table, set
SYNC_CONNECTOR to the module name, and add connector contract tests.
| Env var | Default | Purpose |
|---|---|---|
DATABASE_URL |
— | Set manually on the Workflow from sync-db's internal URL |
SYNC_CONNECTOR |
fake |
Which connector module to load |
SYNC_SLICE_COUNT |
8 |
Fan-out width |
SYNC_OVERLAP_SECONDS |
300 |
Lateness buffer on watermark advance |
SYNC_INITIAL_WATERMARK |
7d |
Cold-start bound; a relative age or an ISO timestamp |
SYNC_PAGE_SIZE |
100 |
Passed to the connector |
SYNC_STATEMENT_TIMEOUT_MS |
120000 |
Per-session Postgres statement timeout |
SYNC_LEASE_SECONDS |
9000 |
Active-run lease; minimum 7500 |
STRIPE_API_KEY |
unset | Only read by the Stripe connector |
STRIPE_EVENT_TYPES |
charge events | Comma-separated event types to sync |
STRIPE_EVENT_RETENTION_DAYS |
30 |
Fail-fast boundary for /v1/events |
STRIPE_REQUEST_TIMEOUT_SECONDS |
30 |
Per-request HTTP timeout |
FAKE_INTERVAL_SECONDS |
15 |
Synthetic record spacing |
FAKE_FAIL_ON_PAGE |
unset | Inject a one-shot failure on this page |
FAKE_FAIL_ON_SLICE |
0 |
Which slice injects it; * for all |
RENDER_API_KEY |
— | Cron trigger only |
WORKFLOW_TASK_SLUG |
— | Cron trigger only, e.g. api-sync/run_sync |
main.py             Workflow tasks and orchestration
config.py           Validated runtime configuration
db.py               Postgres connection helpers
connectors/         Source connectors and protocol
tasks/              Fetch, load, state, migration, and backfill logic
cron/trigger.py     Scheduled Workflow trigger
tests/              Unit and Postgres integration tests
render.yaml         Postgres and cron Blueprint
Implementation logic is plain Python under tasks/ and connectors/; main.py
registers tasks and wires the graph.
pip install -r requirements-dev.txt
pytest
Database-independent tests run by default. To include Postgres integration tests:
createdb api_sync_test
TEST_DATABASE_URL=postgresql:///api_sync_test pytest
GitHub Actions runs the full suite against Postgres 17 and checks Ruff linting and formatting.
SYNC_SLICE_COUNT within your workspace's concurrent task-run limit.fetch_page when required.STRIPE_API_KEY and RENDER_API_KEY in Render environment variables or
an environment group.COPY for staging when Postgres write volume becomes a
bottleneck.source_updated_at field.render-examples/render-postgres-etl is a public repo on GitHub by render-examples. Incremental paginated API to Render Postgres sync with durable checkpoints and idempotent upserts.
It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Its last change on GitHub was on 2026-08-11. Take My Repo does not judge from that whether it is maintained.
A terminal-based dashboard for managing cron jobs locally and on servers.
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.
Open-source data movement for ELT pipelines and AI agents — from APIs, databases & files to warehouses, lakes, and AI applications. Both self-hosted and Cloud.
Jync 捷同 - 开箱即用的异构数据库实时同步工具。单 JAR 启动、浏览器配置,无需 Kafka/ZooKeeper;支持 MySQL、Oracle、PostgreSQL、达梦、金仓等 34 种数据库,内置结构同步、六类日志 CDC、ETL、告警与企业统一认证,内网离线可用。
Python ETL framework for stream processing, real-time analytics, LLM pipelines, and RAG.
The Postgres development platform. Supabase gives you a dedicated Postgres database to build your web, mobile, and AI applications.
Stop renting your intelligence. Own it with AnythingLLM. Everything you need for a powerful local-first agent experience
Provides a render.yaml file for deploying n8n and an accompanying Postgres database on Render.