
rs.cpp
A multi-threaded C++ implementation of random search for locomotion tasks using MuJoCo.
- 7
- MIT
- 2 y ago
Repo thowell/rs.cpp, read from GitHub 1 min ago. thowell has not joined Take My Repo.
In short
thowell/rs.cpp is a public repo on GitHub by thowell. A multi-threaded C++ implementation of random search for locomotion tasks using MuJoCo. It declares the MIT license on GitHub. It is written mainly in C++, has 7 stars and last changed on 2024-07-18. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-20.
Random Search
A simple C++ implementation of random search for locomotion tasks using MuJoCo.
Installation
rs.cpp should work with Ubuntu and macOS.
Prerequisites
Operating system specific dependencies:
macOS
Install Xcode.
Install ninja:
brew install ninja
Ubuntu
sudo apt-get update && sudo apt-get install cmake libgl1-mesa-dev libxinerama-dev libxcursor-dev libxrandr-dev libxi-dev ninja-build clang-12Clone rs.cpp
git clone https://github.com/thowell/rs.cpp
Build and Run
- Change directory:
cd rs.cpp- Create and change to build directory:
mkdir build
cd build- Configure:
macOS
cmake .. -DCMAKE_BUILD_TYPE:STRING=Release -G Ninja
Ubuntu
cmake .. -DCMAKE_BUILD_TYPE:STRING=Release -G Ninja -DCMAKE_C_COMPILER:STRING=clang-12 -DCMAKE_CXX_COMPILER:STRING=clang++-12
- Build
cmake --build . --config=ReleaseBuild and Run rs.cpp using VSCode
VSCode and 2 of its extensions (CMake Tools and C/C++) can simplify the build process.
- Open the cloned directory
rs.cpp. - Configure the project with CMake (a pop-up should appear in VSCode)
- Set compiler to
clang-12. - Build and run the
rstarget in "release" mode (VSCode defaults to "debug").
Train cheetah
Train cheetah in ~10 seconds using 20 threads with Intel Core i9-14900K CPU and Ubuntu 22.04.4 LTS (~20 seconds using 10 threads on Apple M1 Pro).

From the build/ directory, run:
./rs --env cheetah --search --visualize --checkpoint cheetah
The saved policy can be visualized:
./rs --env cheetah --load cheetah --visualize
Environments
Environments available:
- Ant
- based on ant_v5
- modified solver settings
- only contact between feet and floor
- no rewards or observations dependent on contact forces
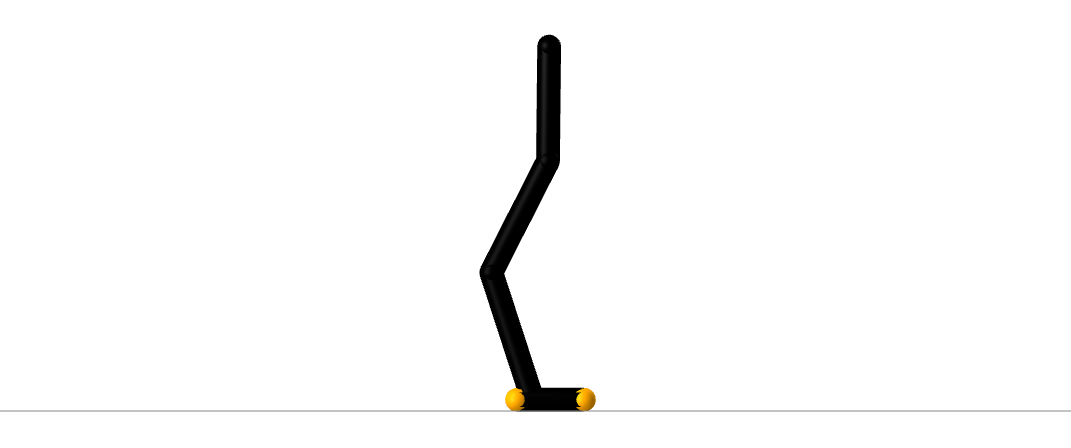
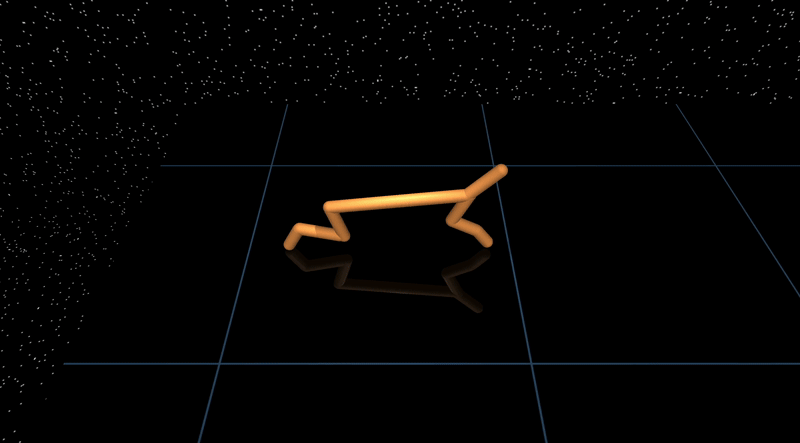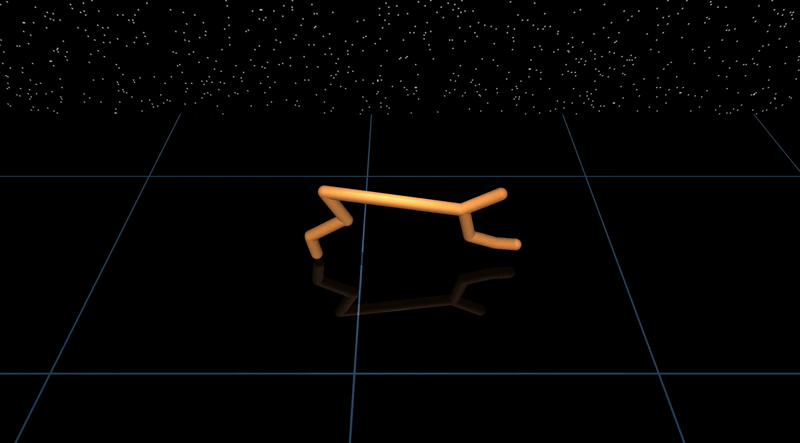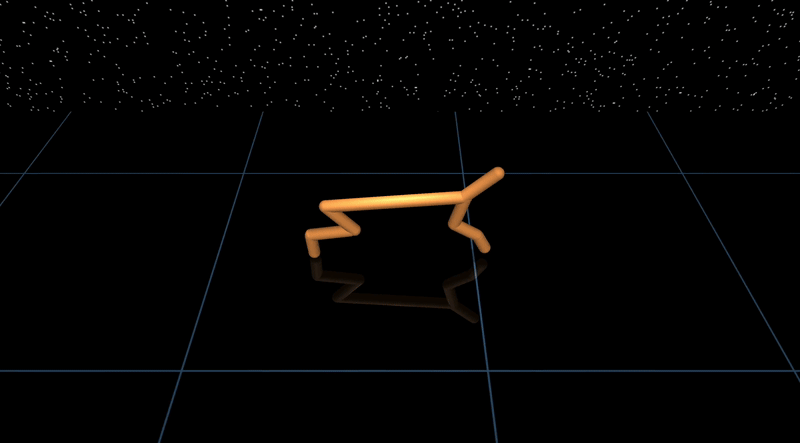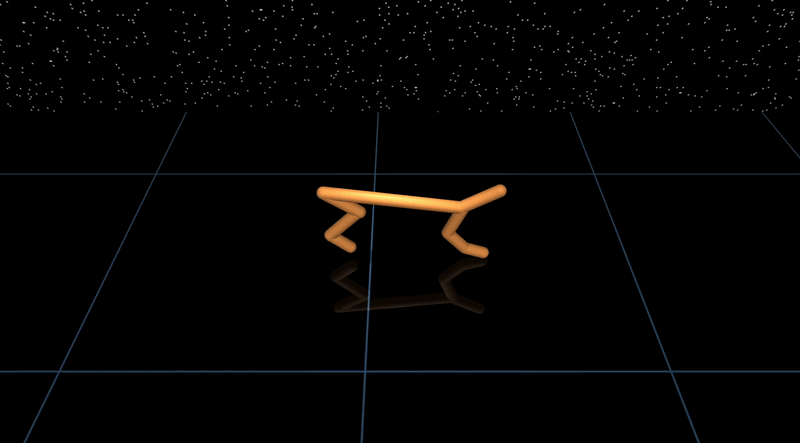
- Cheetah
- based on half_cheetah_v5
- modified solver settings
- Humanoid
- based on humanoid_v5
- modified solver settings
- only contact between feet and floor
- no rewards or observations dependent on contact forces
- Walker
- based on walker2d_v5
- modified solver settings
- only contact between feet and floor
Usage
Note: run multiple times to find good policies.
Run from build/:
Ant

Search:
./rs --env ant --search
Visualize policy checkpoint:
./rs --env ant --load pretrained/ant_2063_239 --visualize
Cheetah
Search:
./rs --env cheetah --search
Visualize policy checkpoint:
./rs --env cheetah --load pretrained/cheetah_3750_239 --visualize
Humanoid

Search:
./rs --env humanoid --search
Visualize policy checkpoint:
./rs --env humanoid --load pretrained/humanoid_2291_1931 --visualize
Walker

Search:
./rs --env walker --search
Visualize policy checkpoint:
./rs --env walker --load pretrained/walker_5619_41 --visualize
Command-line
Setup:
--env:ant,cheetah,humanoid,walker--search: run random search to improve policy--checkpoint: filename incheckpoint/to save policy--load: provide string incheckpoint/directory to load policy from checkpoint--visualize: visualize policy--num_threads: number of threads / parallel workers
Search settings:
--nsample: number of random directions to sample--ntop: number of random directions to use for policy update--niter: number of policy updates--neval: number of policy evaluations during search--nhorizon_search: number of environment steps during policy improvement--nhorizon_eval: number of environment steps during policy evaluation--random_step: step size for random direction during policy perturbation--update_step: step size for policy update during policy improvement--nenveval: number of environments for policy evaluation--reward_shift: subtract baseline from per-timestep reward
Notes
- This implementation is not deterministic. You may need to run the search multiple times to find a good policy.
- The environments are based on the v5 MuJoCo Gym environments but may not be exact in all details.
- The search settings are based on Simple random search provides a competitive approach to reinforcement learning: Table 9 but may not be exact in all details either.
This repository was developed to:
- understand the Augmented Random Search algorithm
- understand how to compute numerically stable running statistics
- understand the details of Gym environments
- experiment with code generation tools that are useful for improving development times, including: ChatGPT and Claude
MuJoCo models use resources from Gymnasium and dm_control
Questions
What is rs.cpp?
thowell/rs.cpp is a public repo on GitHub by thowell. A multi-threaded C++ implementation of random search for locomotion tasks using MuJoCo.
Is rs.cpp open source?
It declares the MIT license on GitHub.
Does rs.cpp run on macOS, Windows or Linux?
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
How do I install rs.cpp?
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Is rs.cpp still maintained?
Its last change on GitHub was on 2024-07-18. Take My Repo does not judge from that whether it is maintained.
What do people who ran rs.cpp say?
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.