murmure
Fully local, private and cross platform Speech-to-Text with LLM Post-processing
- 1.2k
- TypeScript
- AGPL-3.0
- 2 d ago
Fully local, private and cross platform Speech-to-Text with LLM Post-processing
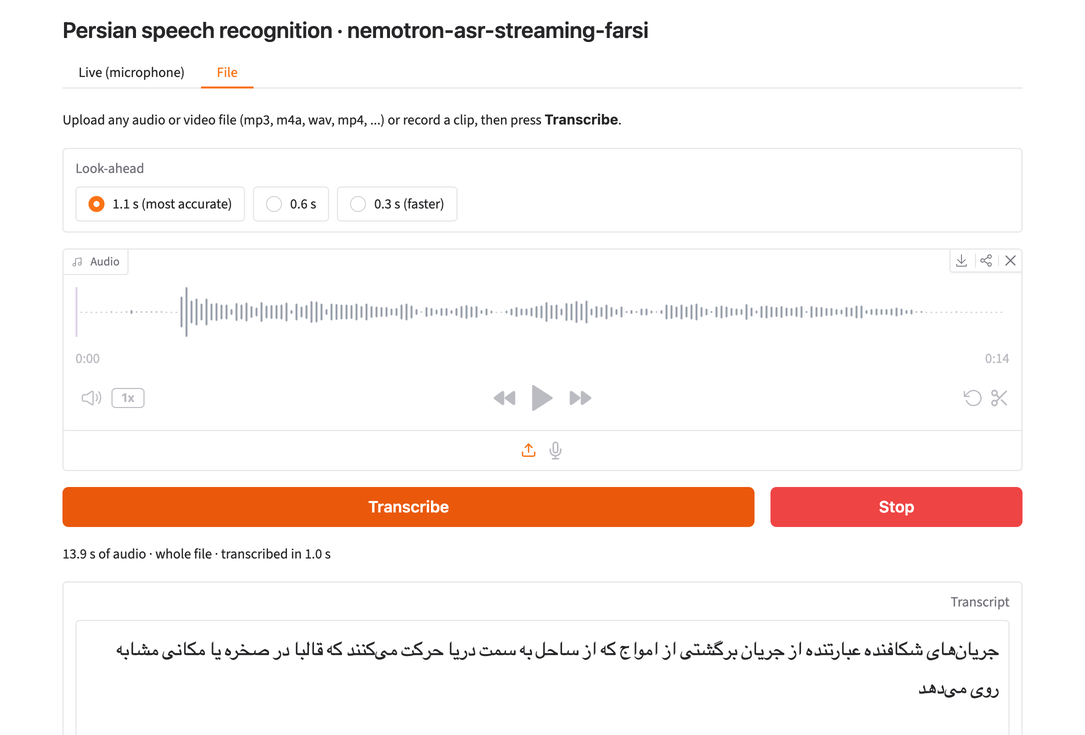
Streaming Persian (Farsi) speech recognition: fine-tuning NVIDIA Nemotron 3.5 ASR streaming. Data prep, training, evaluation, inference.
Offline speech-to-text on the STM32N6 microcontroller: free English speech recognition on the NPU, no cloud
Open benchmark for phone & word timestamp accuracy on human-labeled TIMIT and Buckeye across clean and degraded speech (reverb, noise, music, babble). Evaluates 32 forced aligners & ASR models in two tracks: MFA, WhisperX, Charsiu, Qwen3, Parakeet-TDT, Deepgram, Olign & more. Reproducible CLI, monthly leaderboards & arXiv paper.
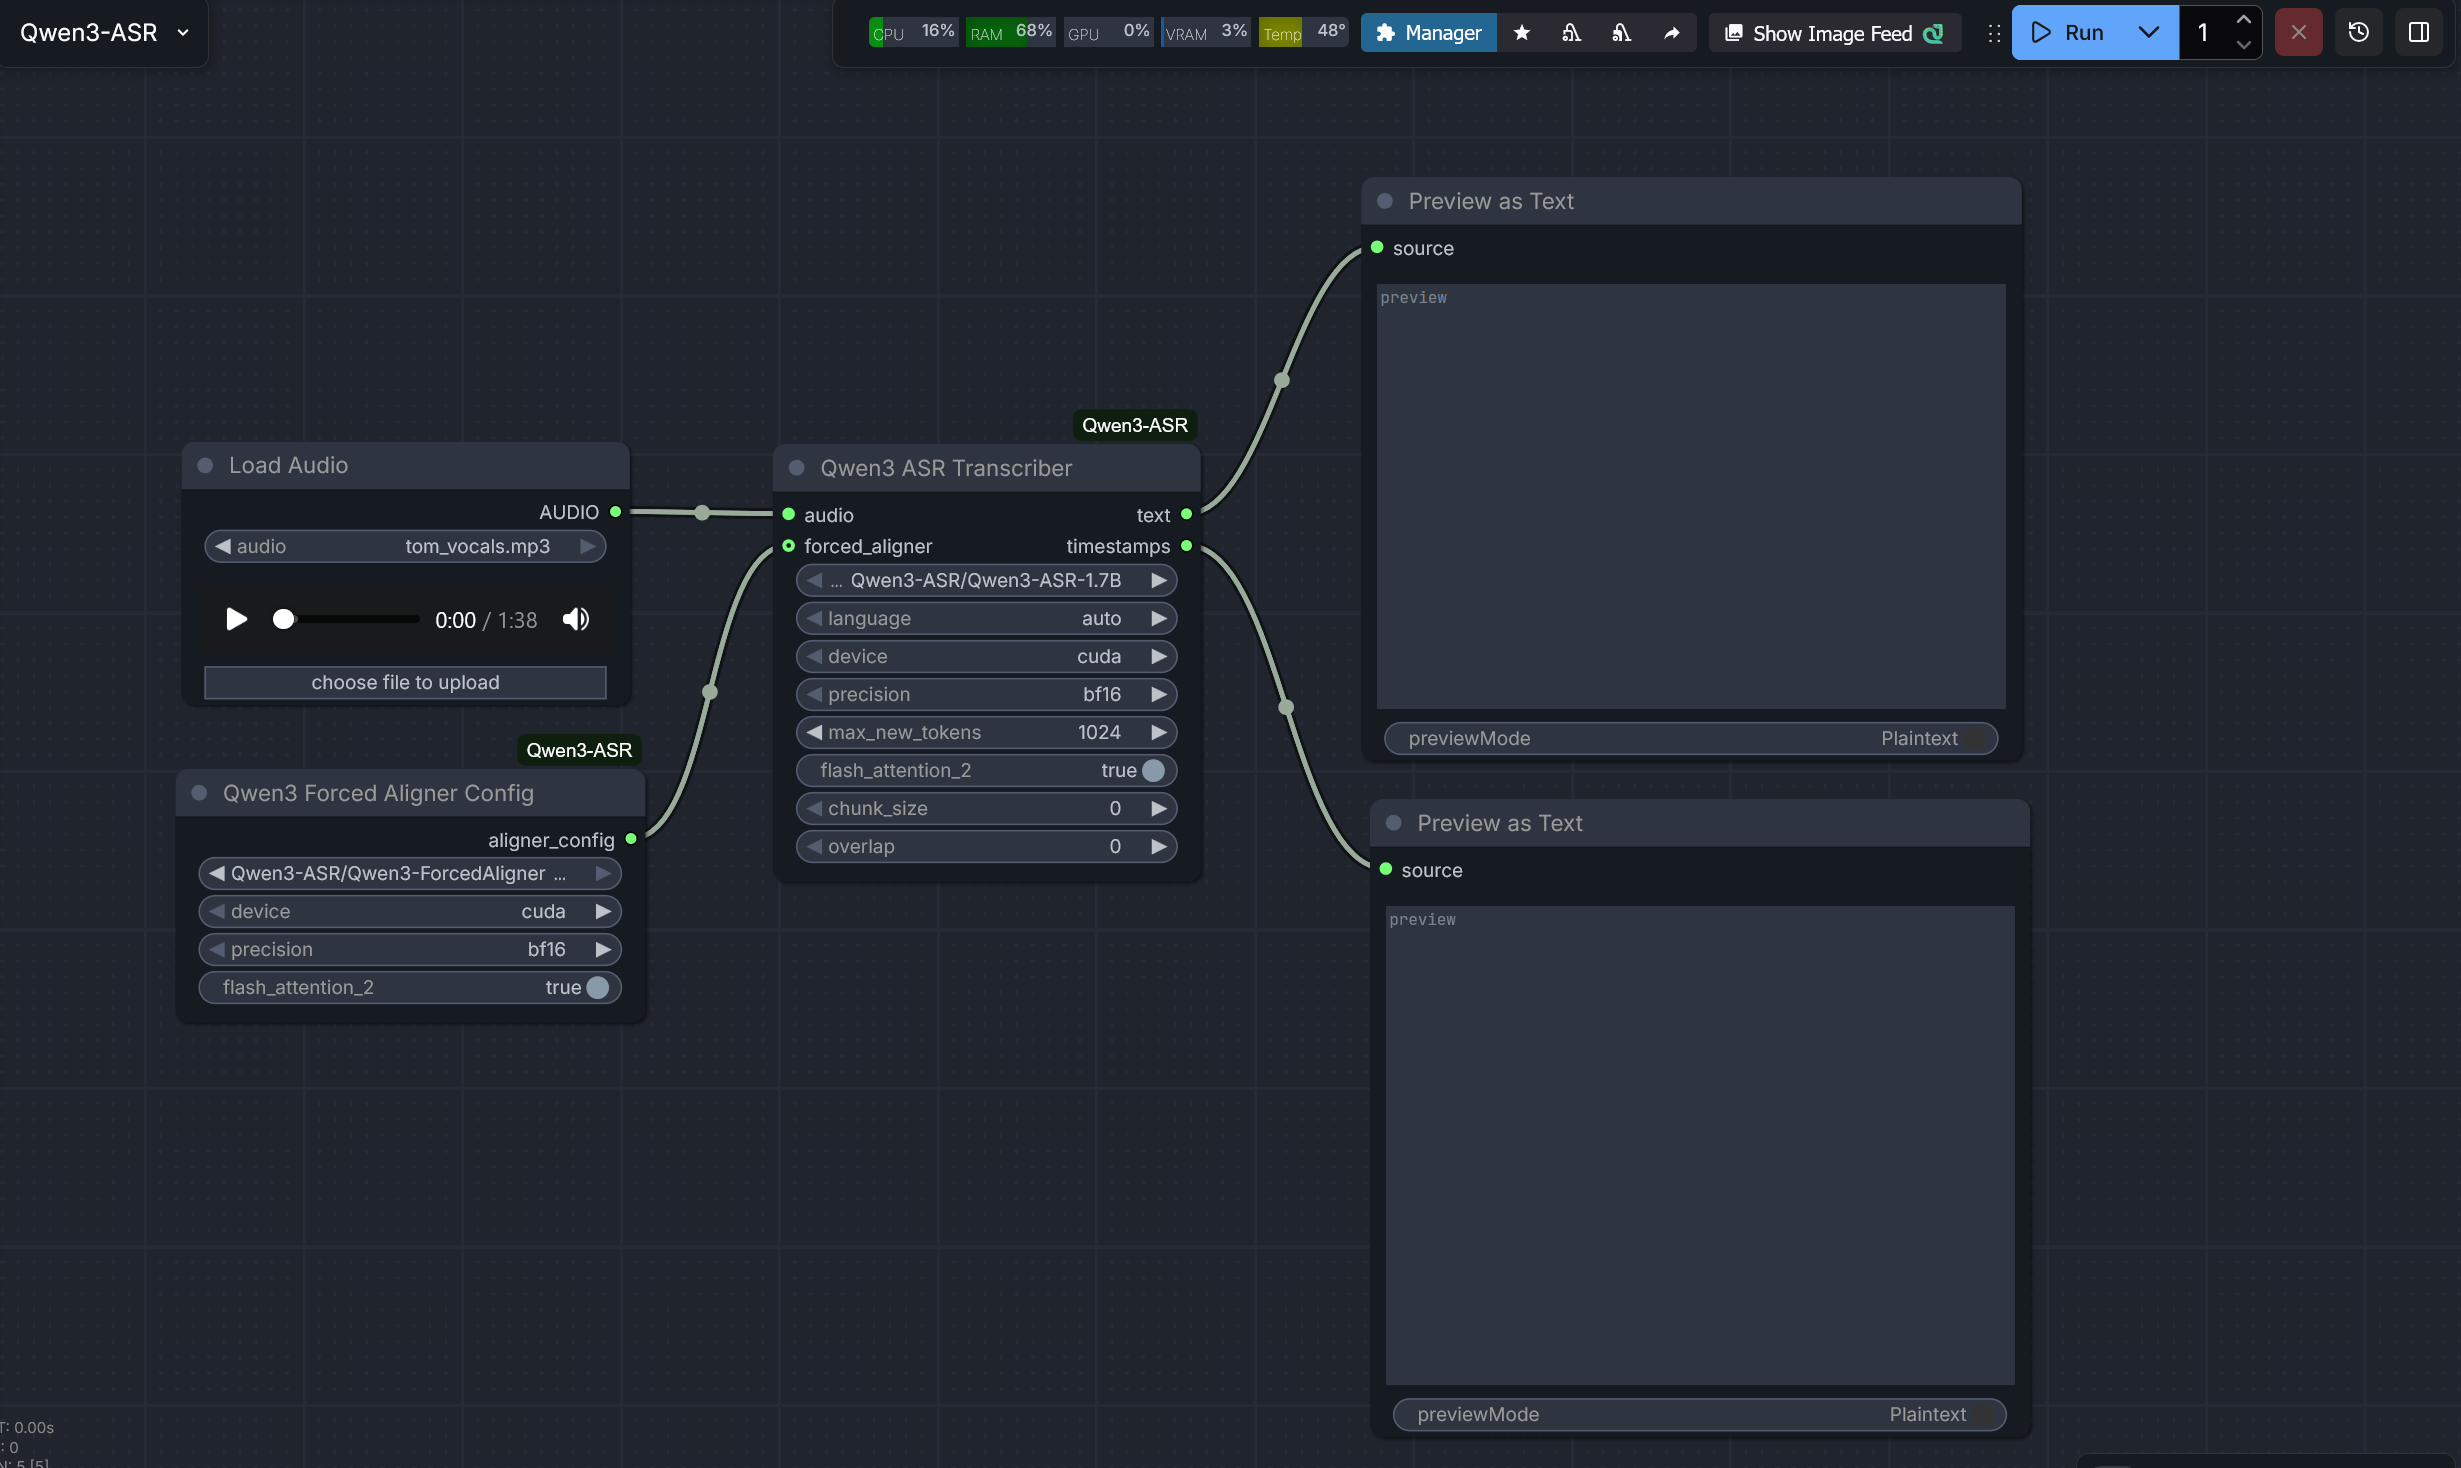
ComfyUI nodes for Qwen3-ASR (0.6B/1.7B) and ForcedAligner. Supports high-accuracy ASR and language identification for 52 languages/dialects, including 22 Chinese dialects and various English accents. Features word-level timestamps, long audio transcription, and VRAM-optimized inference.
Pre-compiled ASR model weights for the VoxRT on-device runtime. Encrypted .vxrt v2 format. streaming-medium-pc: FastConformer 32M, CTC + RNN-T, CC-BY-4.0 (NVIDIA NeMo).
Official plugin for OrcaDub — AI video dubbing (bundles the @orcadub/mcp server + dub skill)
A collection of Python scripts demonstrating how to run various AI tasks locally using models from the Hugging Face Hub and the transformers library (along with related libraries like datasets, sentence-transformers, etc.). These examples cover a range of modalities including text, vision, and audio, showcasing different models and pipelines.
An intelligent Streamlit application to transcribe and analyze multi-speaker medical consultations. This tool automatically identifies who spoke when (diarization), transcribes their speech (ASR), and assigns their role (Clinician or Patient), even in conversations that mix English and other languages like Hindi or Tamil.
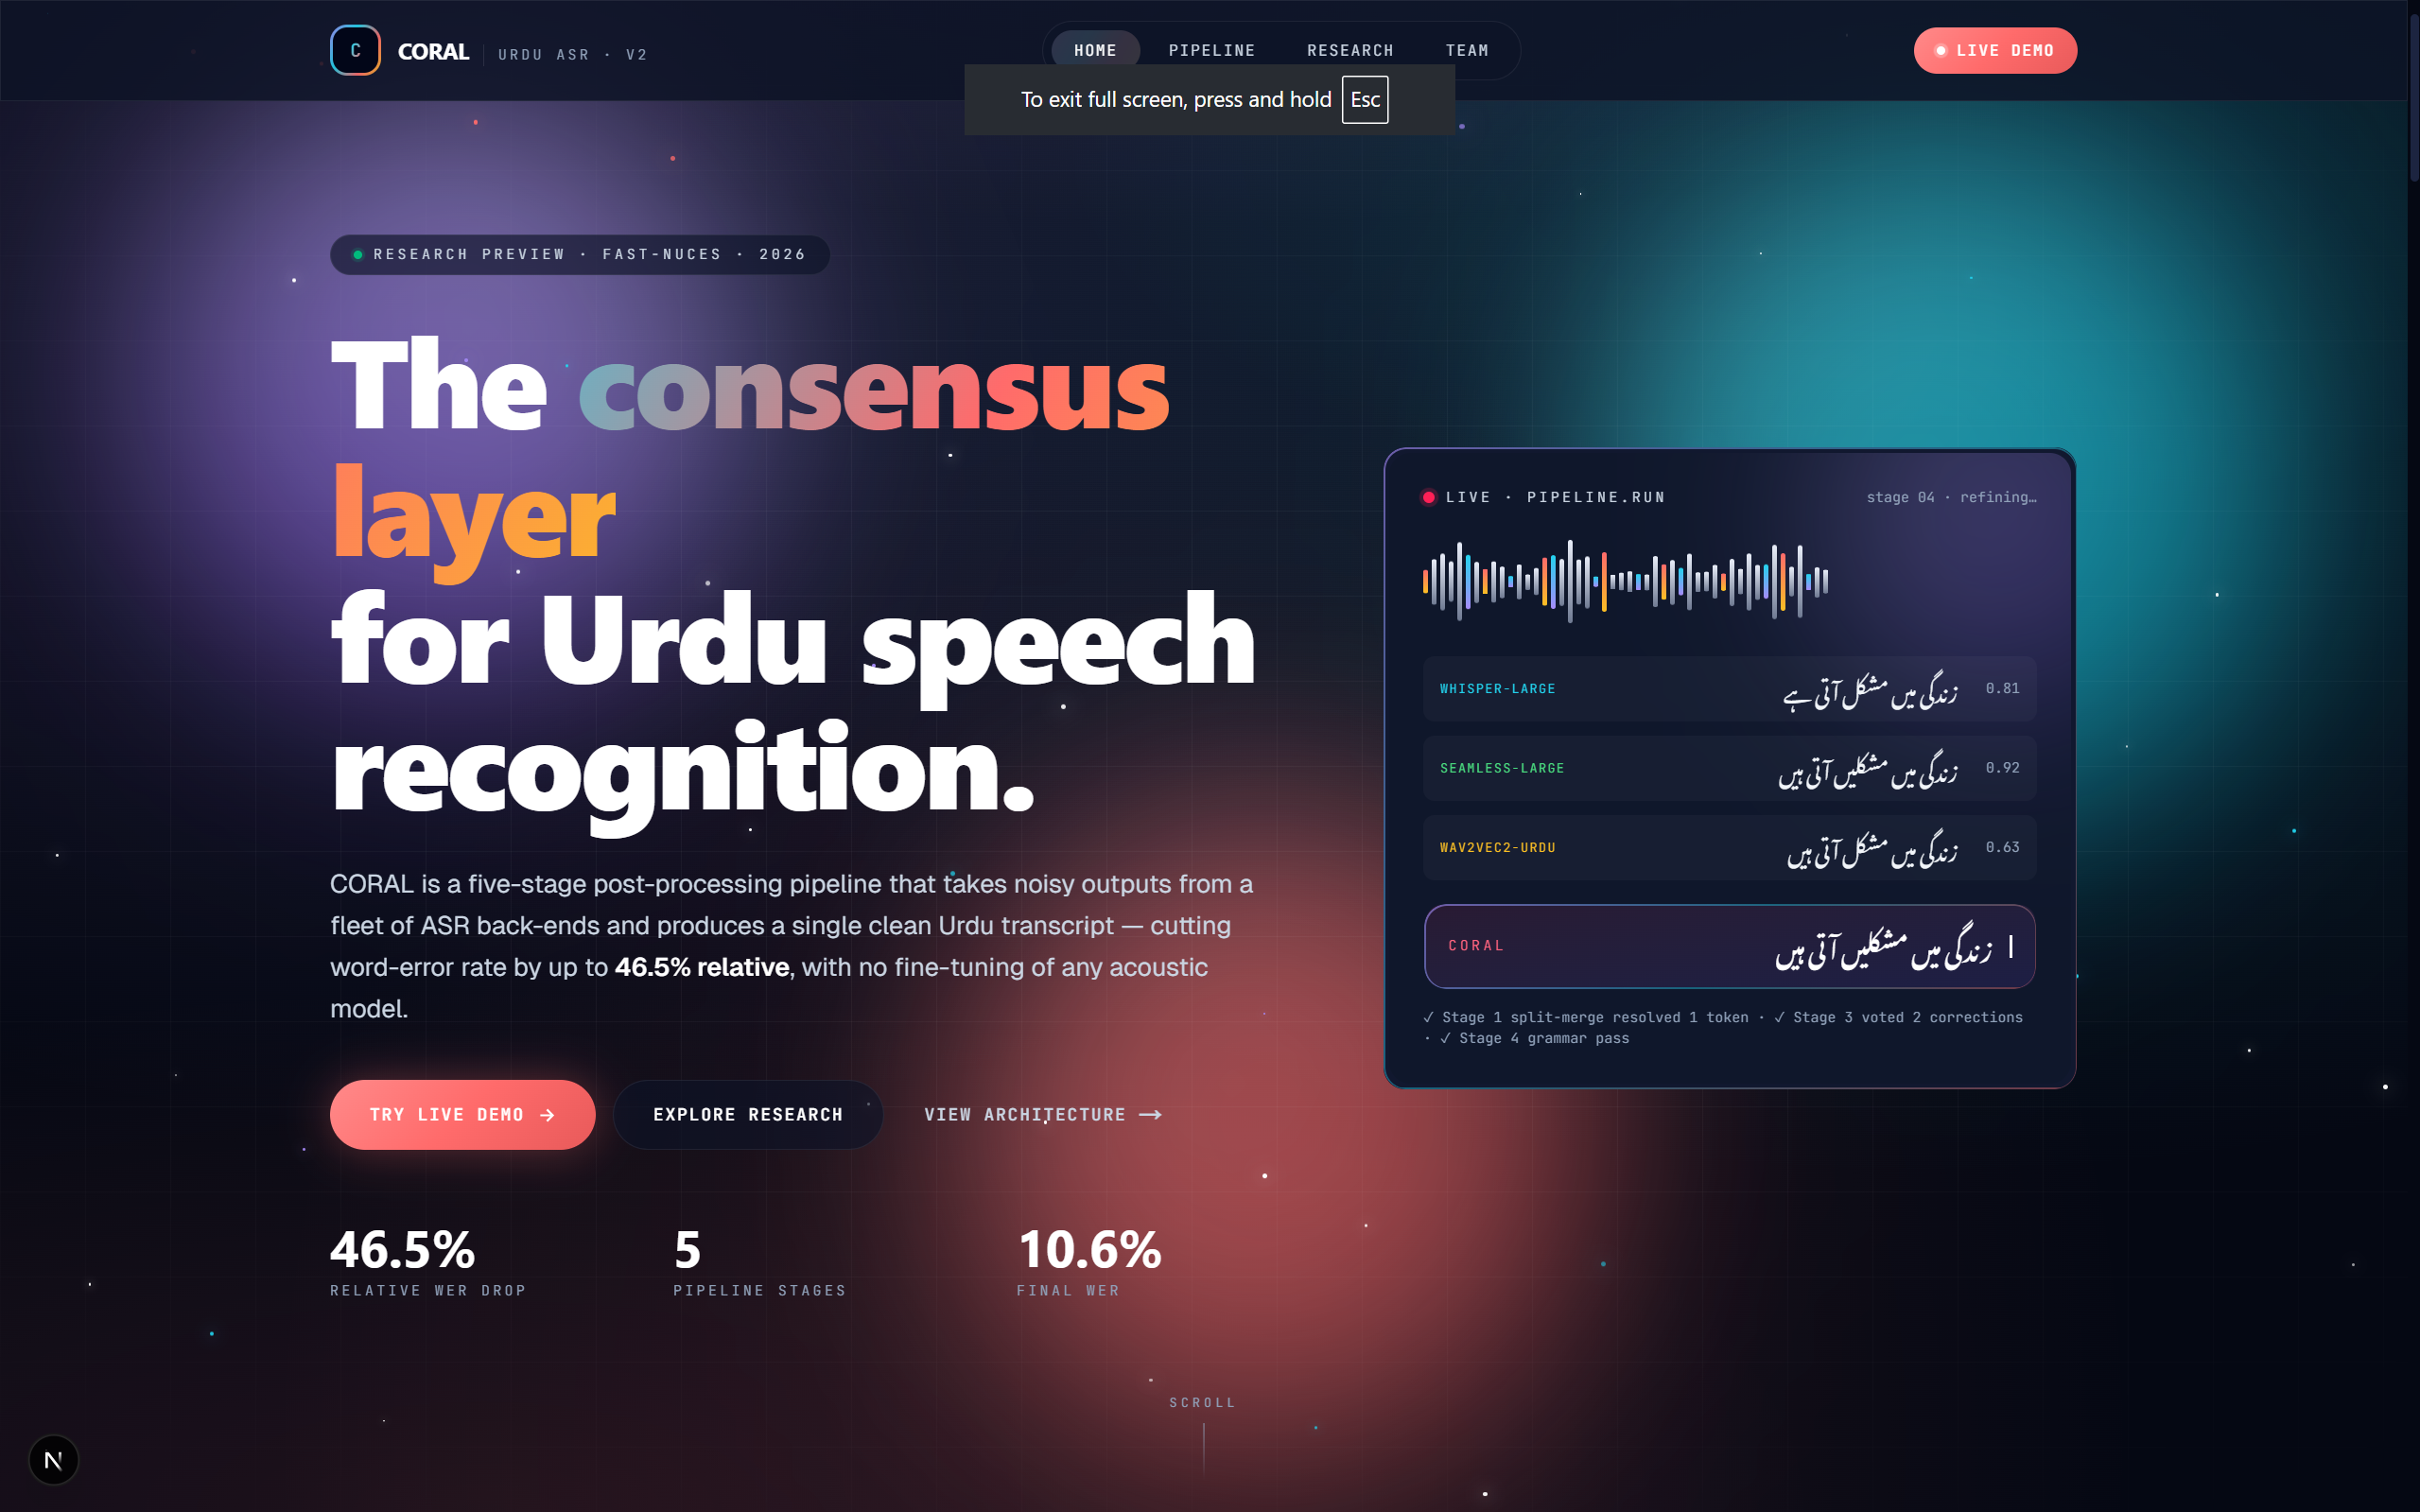
Multi-stage Urdu ASR correction engine reducing Word Error Rate via confidence-weighted ensembles, n-gram OOV detection, and LLM refinement - without requiring model fine-tuning.
ASR Pipeline (GLM-ASR) optimized using custom Triton kernels (achieving a 72.2% improvement in speed)
Turn spoken Arabic ASR transcripts into exact values for voice agents: phone numbers, SAR/AED amounts, dates, times, emails and order IDs. Rule-based, stdlib-only Python library and CLI.