onediff
OneDiff: An out-of-the-box acceleration library for diffusion models.
- 2k
- Jupyter Notebook
- Apache-2.0
- 12 mo ago
OneDiff: An out-of-the-box acceleration library for diffusion models.
开源的 ComfyUI 一体化管理平台 —— 工作流与模型统一管理,内置负载均衡、可视化表单、积分用户系统和后台管理,支持自托管/an all-in-one, open-source platform for managing ComfyUI workflows and AI models. Features load balancing, visual forms, a user system with credits, and a full admin panel. Ready for self-hosting.
SmartGallery DAM is a local-first, browser-based Digital Asset Manager for ComfyUI. Generate without opening ComfyUI. Query your gallery with AI, in natural language. Advanced file manager, filter by prompt, model, LoRA, date and comment. Status tags, ratings, virtual collections, client sharing. Mobile-friendly, cross-platform, Docker-ready.
A Collection of Google Colab Notebooks for various projects
Local-first Agentic Idea-to-video Studio Using ComfyUI + FastAPI + SvelteKit
ComfyUI Node of Clarity AI creative image upscaler and enhancer. ComfyUI alternative of Magnific AI
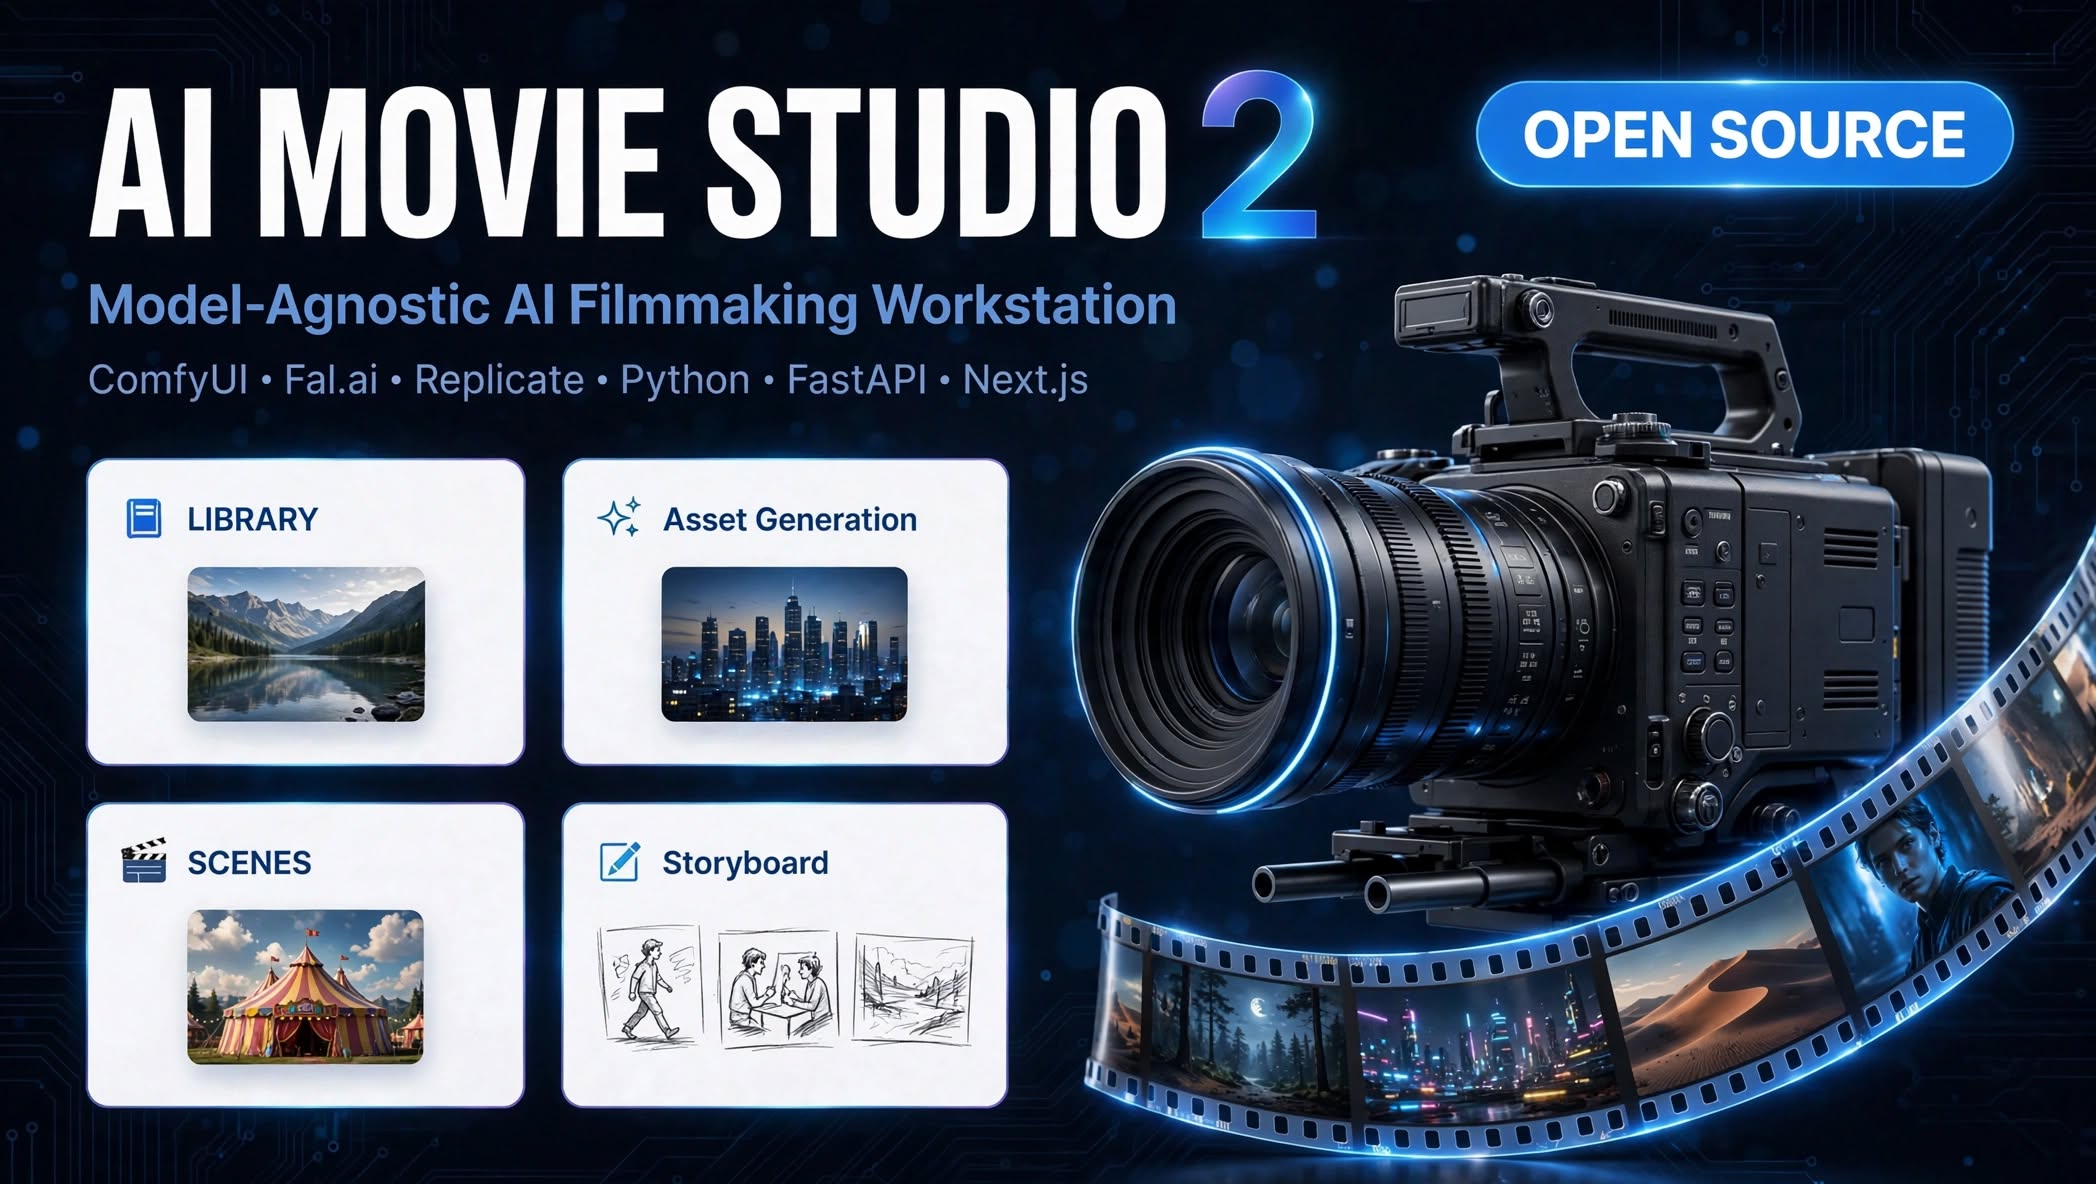
Model-agnostic AI filmmaking workstation. 3D storyboard, ComfyUI local + Fal/Replicate cloud, multi-reference continuity, timeline export. Alternative to Storyboarder, LTX Studio.
TBG Enhanced Tiled Upscaler and Refiner upscales up to 200MP with precise control. It features dual-model processing (structure + detail), per-pixel denoising to control where creativity is applied, and per-tile and per-object prompts, denoise, and seeds. Advanced fast previews. New generative tile fusion seamless joining, even on high-denoise.
ComfyUI nodes to save time and keep your workflows tidy. Bundle multiple wires into one wire. Create customizable presets nodes.
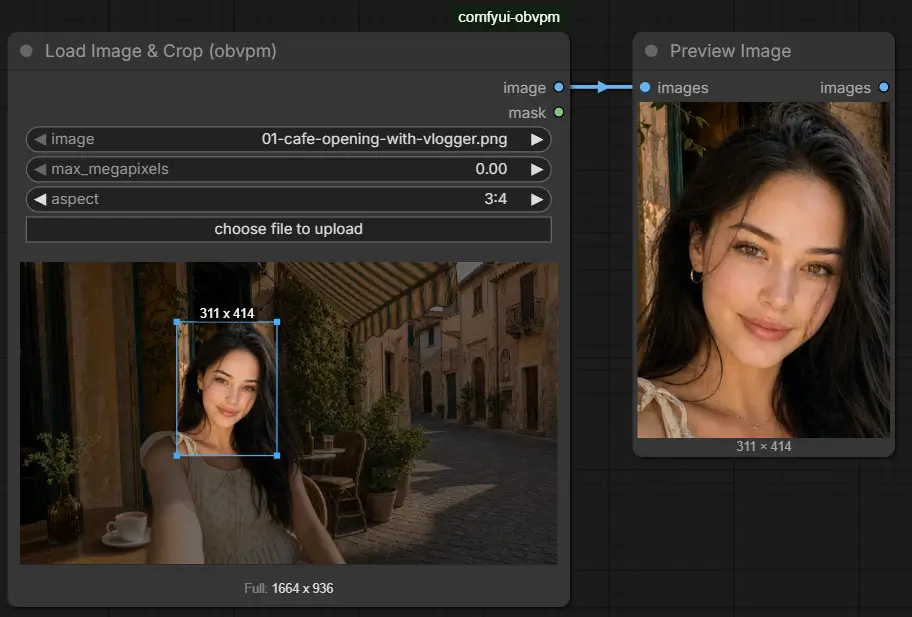
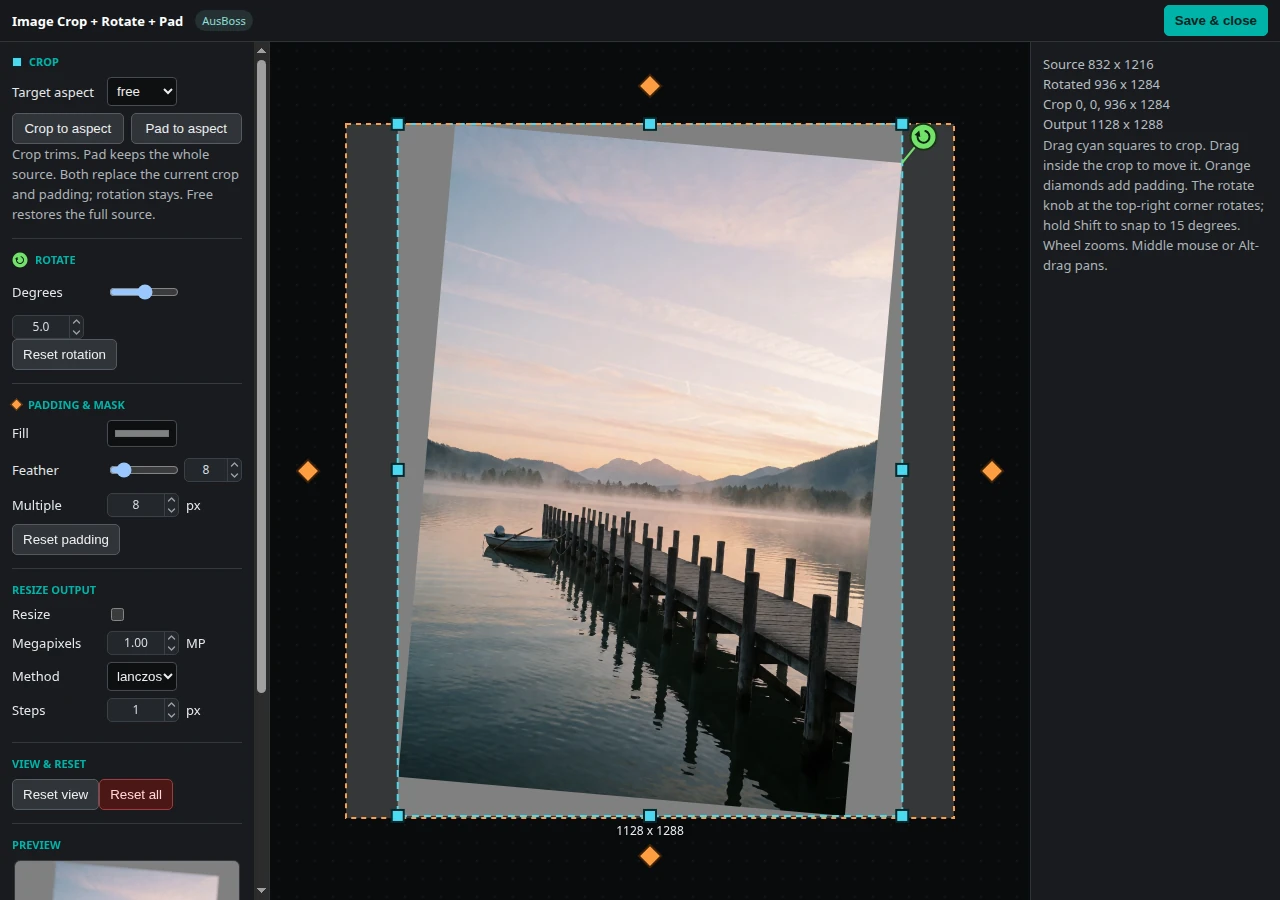
ComfyUI nodes I made for my own workflows: click or type to mask a thing, crop, rotate and pad by dragging handles, inpaint and outpaint that keep your original pixels, tiled upscale, a video trim timeline, folder batches, layout boxes and a LoRA stack. I keep adding more.
Desktop image library for photographers and creators. Search by content, face or the text in a picture, get help from local AI models to tag and organise your images. Connect ComfyUI to generate and edit pictures, and AI-toolkit to train LoRAs. Also runs as a headless server.
ComfyUI-OmniGen2 is now available in ComfyUI, OmniGen2 is a powerful and efficient unified multimodal model. Its architecture is composed of two key components: a 3B Vision-Language Model (VLM) and a 4B diffusion model.
Use AI to Animate - ComfyUI Custom Nodes include IMG Caches, Switches, Prompt & Checkpoint changer...
ComfyUI workflows to create smooth transitions between video clips using Wan VACE. Works with video from any model or other source-LTX-2, drone footage, stock video, personal recordings, etc.
ComfyUI nodes designed to help make common video editing tasks with video generation models less complicated. Smooth transitions, extensions, outpainting. Primarily designed for Wan VACE, with some LTX-2 support.
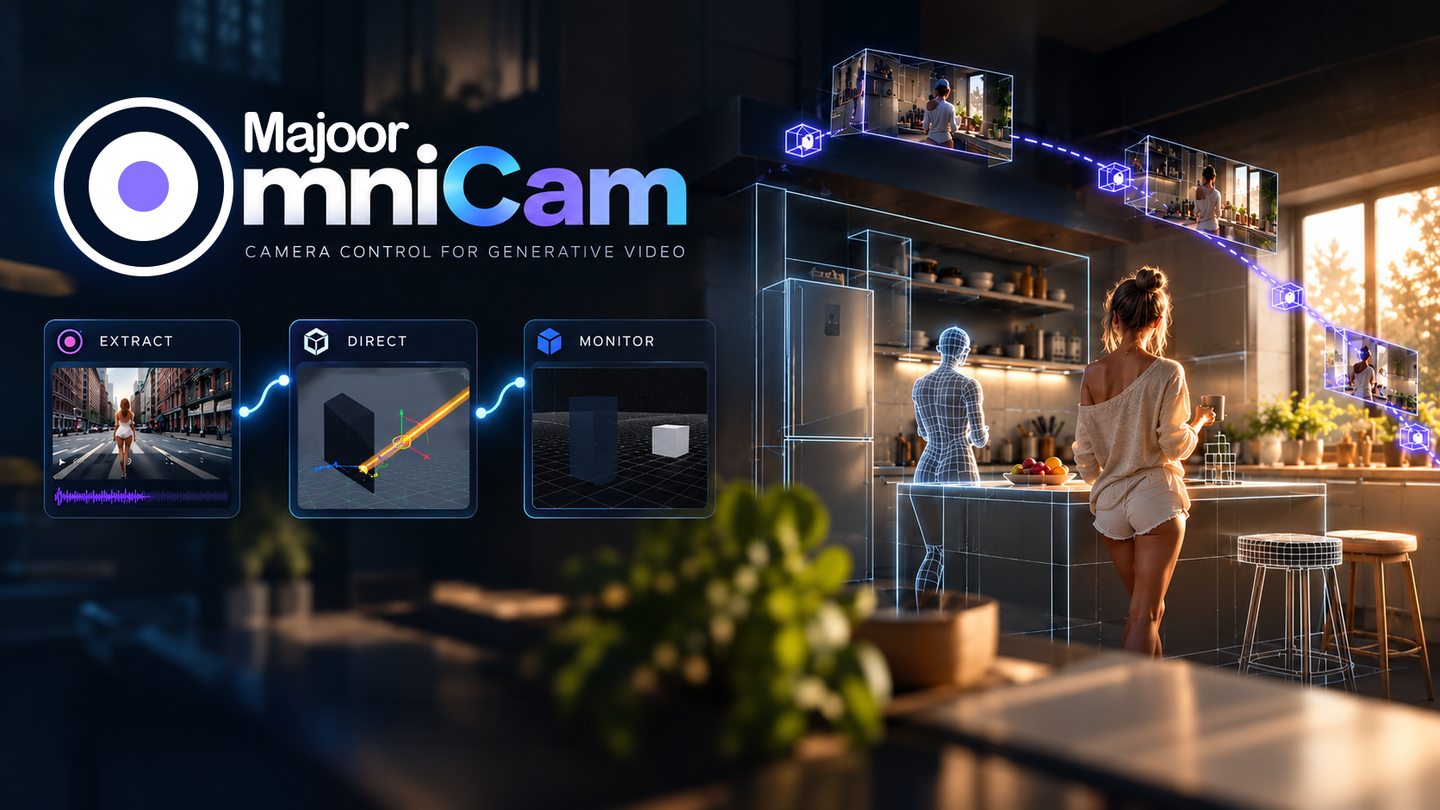
Majoor OmniCam is a camera layout and animation tool for ComfyUI. It lets you prepare camera motion without running image or video generation while editing. You can position cameras, create keyframes, preview motion, and record a simple reference video for compatible video models.
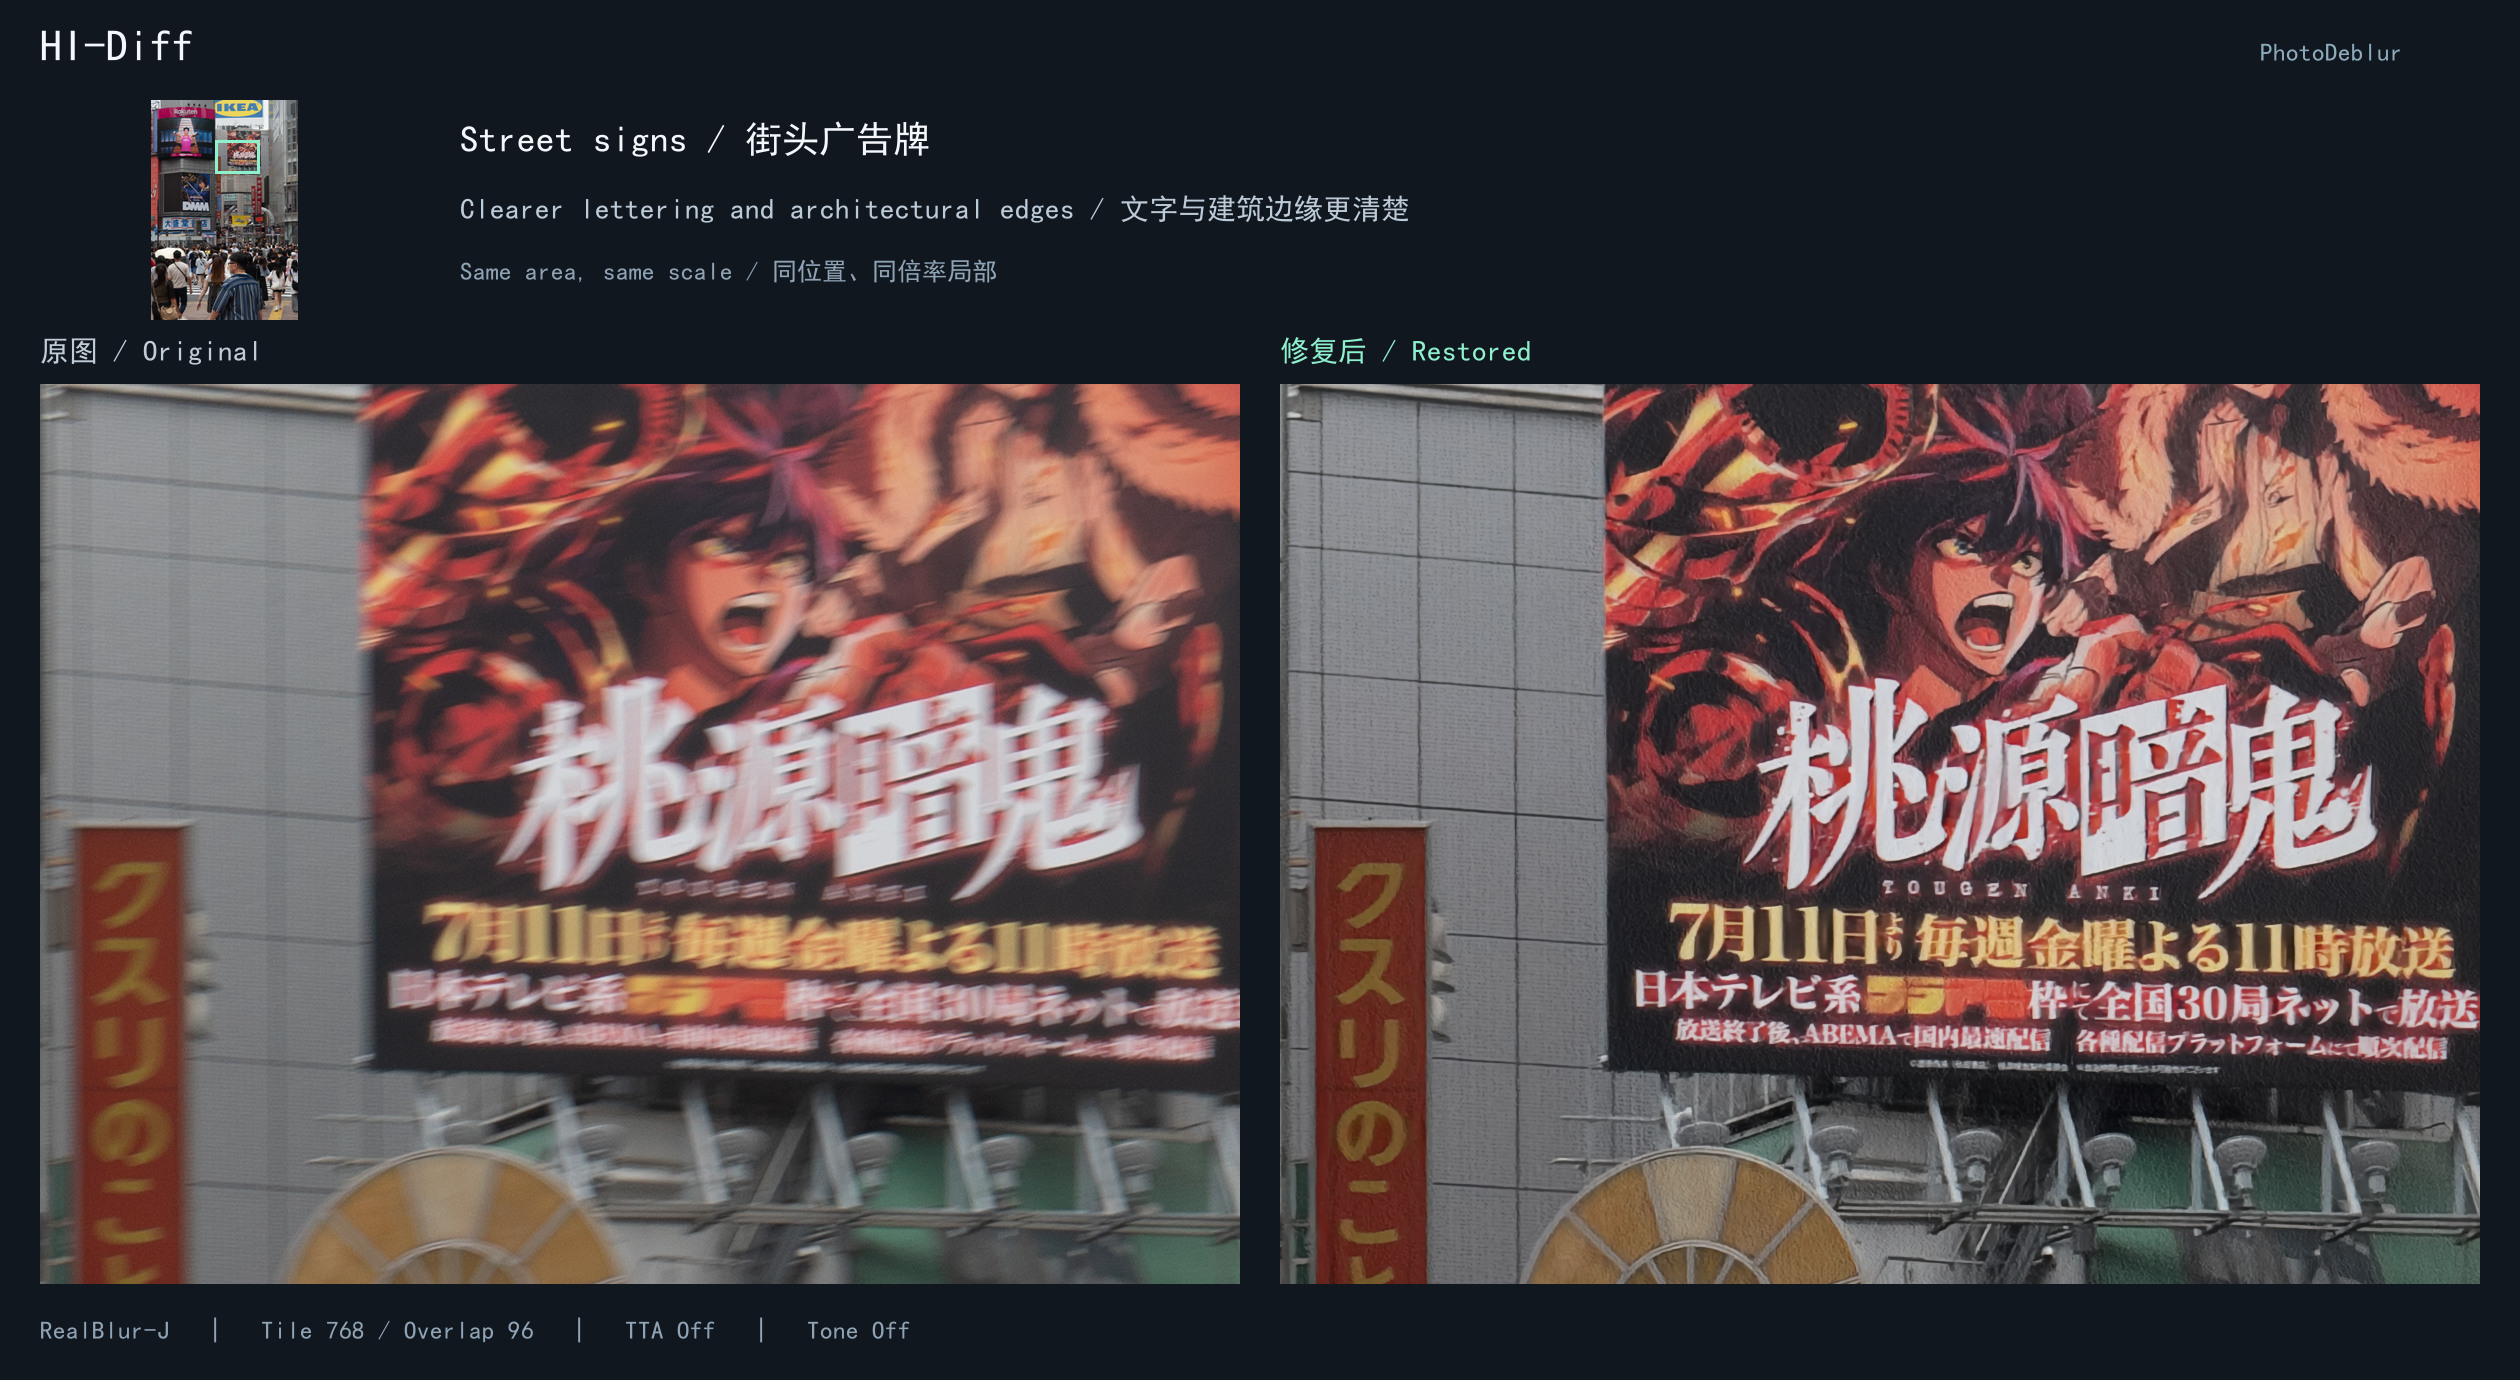
Photo deblurring for ComfyUI with HI-Diff and MISCFilter. comfy ui节点以及工作流支持手抖与运动模糊修复、原尺寸分块处理及模型下载。
ComfyUI API Integration, ComfyUI Automated Workflow, ComfyUI API 一键集成, ComfyUI 自动流程
🎬 A Codex-first MiniMax H3 video production plugin: 👤 character & 🏙️ scene design, 🧩 storyboards, 🎞️ ComfyUI generation, ✂️ post-production, and ✅ QC.
ComfyUI interface adaptation of the musubi-tunner library to train Wan 2.1 loras.
AI rotoscoping and video matting in ComfyUI: click one person, get a native 4K alpha with hair-level edges. SAM3 picks the subject, LTX-2.5 alpha-gen draws the edge. 12 GB VRAM, EXR in/out, open weights.
ComfyUI-AniSora is now available in ComfyUI, Index-AniSora is the most powerful open-source animated video generation model. It enables one-click creation of video shots across diverse anime styles including series episodes, Chinese original animations, manga adaptations, VTuber content, anime PVs, mad-style parodies(鬼畜动画), and more!
Automated LoRA Training Docker Builds for Alibaba Cloud 2026
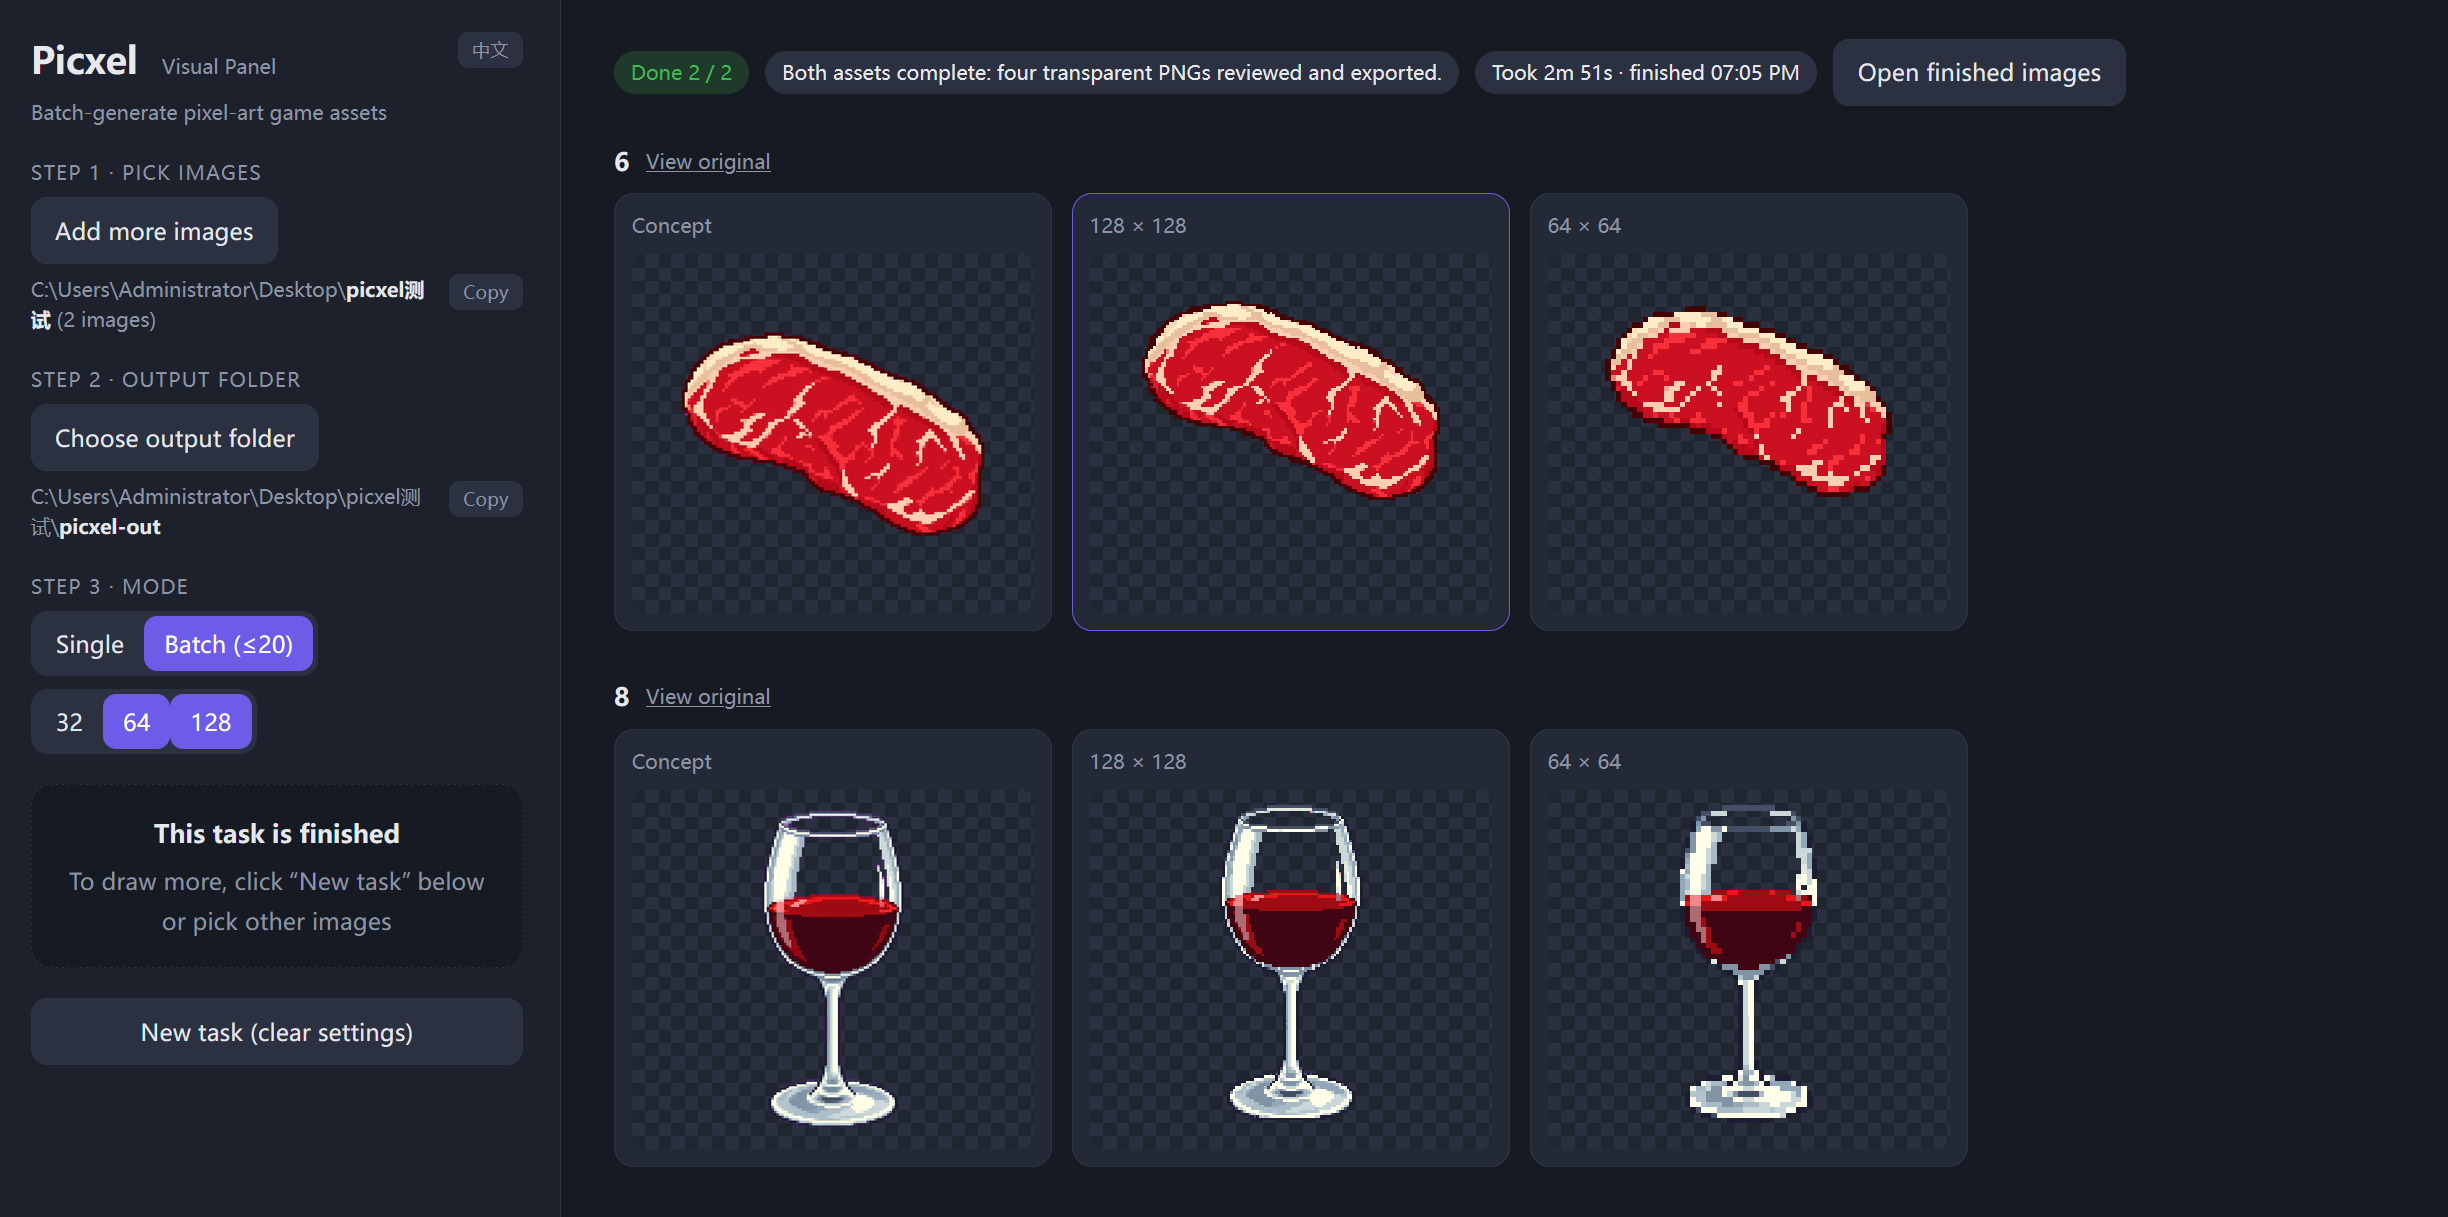
Turn reference images into pixel-art game assets,for indie game developers.
ComfyUI-Hunyuan3D-2.1 is now available in ComfyUI, Hunyuan3D-2.1 is a scalable 3D asset creation system that advances state-of-the-art 3D generation through two pivotal innovations: Fully Open-Source Framework and Physically-Based Rendering (PBR) Texture Synthesis.
Run multiple isolated ComfyUI workspaces with Smart custom node analysis
ModelFinder - ComfyUI 一站式启动器 | One-click deploy, model finder, AI diagnosis, batch queue | Windows launcher for ComfyUI
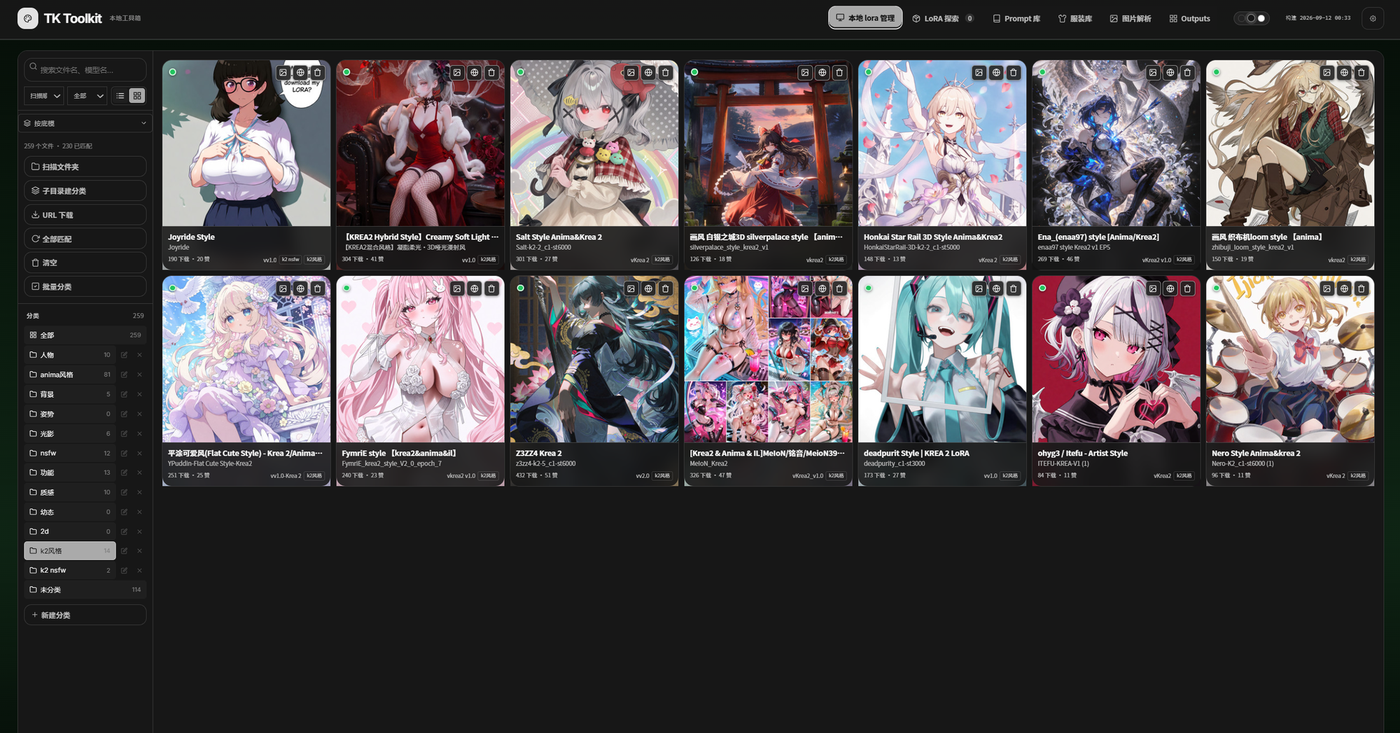
TK Toolkit (formerly Anima Toolkit) — all-in-one Anima/SD toolkit for ComfyUI: LoRA manager (batch apply + Civitai metadata & downloads), Danbooru search & waterfall gallery, bilingual prompt cards with Chinese tag autocomplete, output gallery, and batch-workflow utilities.
Custom ComfyUI nodes for downloading, converting, and previewing audio/video from YouTube and 1,000+ other platforms
ComfyUI-ThinkSound is now available in ComfyUI, ThinkSound is a unified Any2Audio generation framework with flow matching guided by Chain-of-Thought (CoT) reasoning.
ComfyUI-HunyuanVideo-Avatar is now available in ComfyUI, HunyuanVideo-Avatar is a multimodal diffusion transformer (MM-DiT)-based model capable of simultaneously generating dynamic, emotion-controllable, and multi-character dialogue videos.
ComfyUI-Bagel is now available in ComfyUI, BAGEL is an open‑source multimodal foundation model with 7B active parameters (14B total) trained on large‑scale interleaved multimodal data.