fp16

YOLOv8-ONNX-TensorRT
👀 Apply YOLOv8 exported with ONNX or TensorRT(FP16, INT8) to the Real-time camera
- 59
- Python
- AGPL-3.0
- 2 y ago

zerfoo
Pure Go machine learning framework. Train, run, and serve ML models with go build. Zero CGo.
- 38
- Go
- Apache-2.0
- 5 wk ago

GPU-Tensor-Unlock-Universal
Pre-driver FMLA32 Tensor Core unlocker and PTX benchmark console for GeForce RTX 40-series, RTX 30-series and RTX 20-series on Windows 10/11 (UEFI USB) and Linux (gpu_unlock.ko), with friendly UI for Win/Linux. Restores full 2x FP16/BF16/TF32->FP32 accumulate rate with automatic hardware profiling, pre-flight ROM checks, and zero VBIOS flashing.
- 30
- C
- GPL-2.0
- 3 d ago

onnx-tensorrt-optimization
40x faster AI inference: ONNX to TensorRT optimization with FP16/INT8 quantization, multi-GPU support, and deployment
- 8
- Python
- MIT
- 12 mo ago

llm-inference-bench
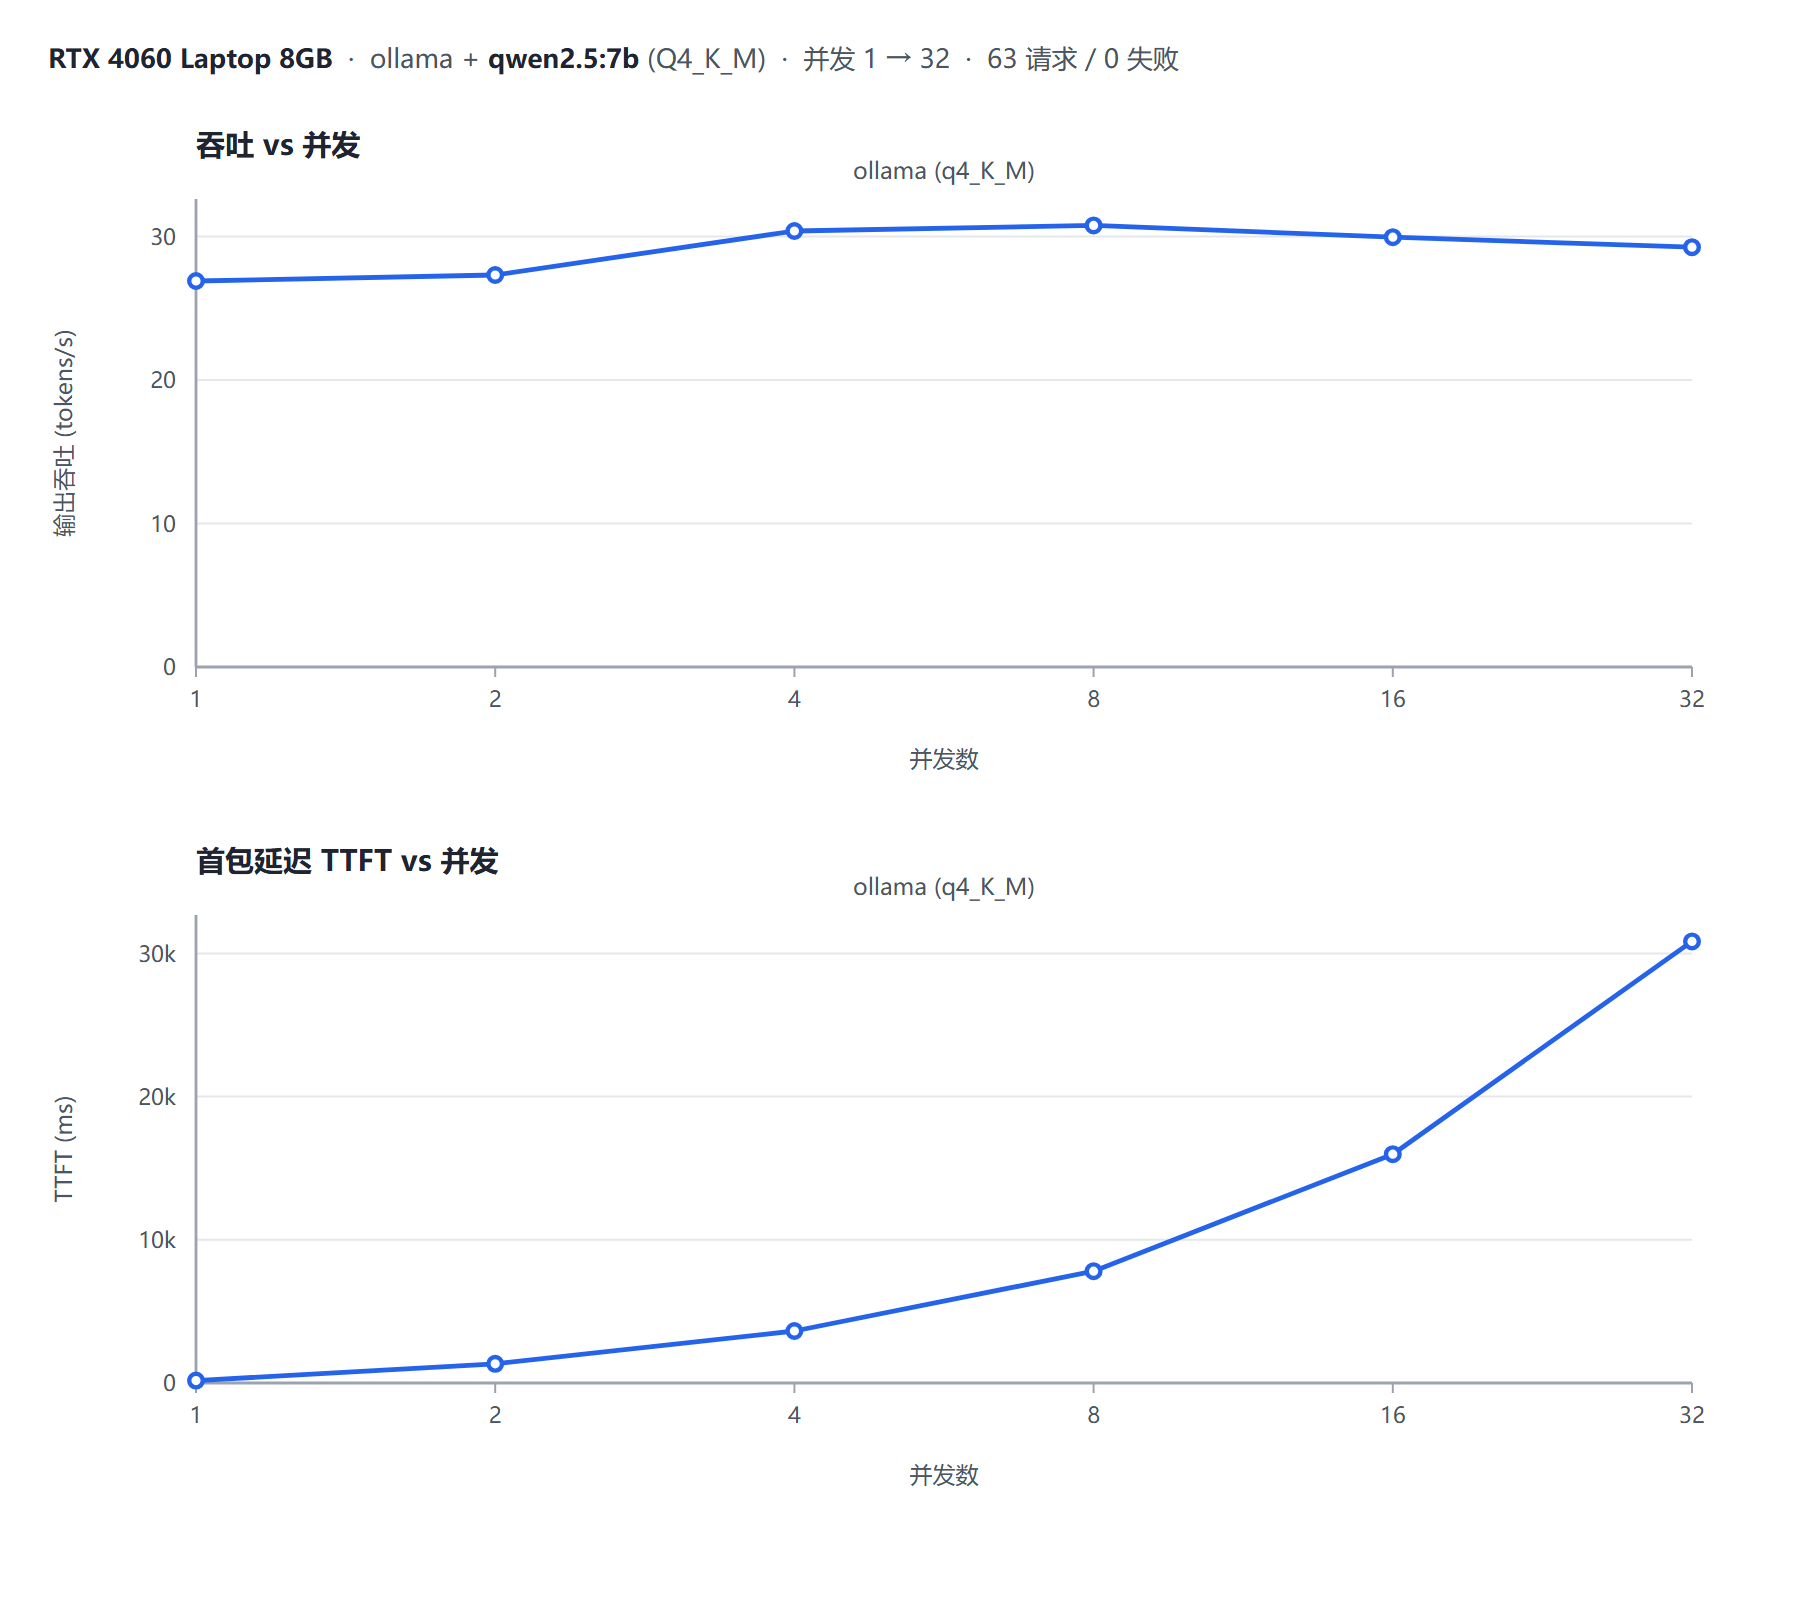
Benchmark self-hosted LLM inference across engines (vLLM, Ollama) and quantisation levels (FP16 / INT8 / AWQ / GPTQ). Concurrency sweeps, TTFT / TPOT / P99 tail latency, VRAM curves, Prometheus + Grafana, self-contained HTML reports.
- 2
- Python
- MIT
- 8 d ago

ComfyUI-Qwen-V100-MixedPrecision
V100-optimized mixed precision for Qwen Image in ComfyUI — 1.43x faster sampling on NVIDIA Tesla V100 32GB (Volta/sm_70).
- 3
- Python
- 10 d ago

Gemma-4-26B-A4B-it_gpuep_1.0_gpu_128
Text generation model, used with onnxruntime-genai.
- 1
- 163
- apache-2.0
- 4 mo ago
svg-code-generator-i1-GGUF
- 1
- 512
- apache-2.0
- 15 mo ago