LightCompress
[EMNLP 2024 & AAAI 2026] A powerful toolkit for compressing large models including LLMs, VLMs, and video generative models.
- 755
- Python
- Apache-2.0
- 6 mo ago
[EMNLP 2024 & AAAI 2026] A powerful toolkit for compressing large models including LLMs, VLMs, and video generative models.
SOTA low-bit LLM quantization (INT8/FP8/MXFP8/INT4/MXFP4/NVFP4) & sparsity; leading model compression techniques on PyTorch, TensorFlow, and ONNX Runtime
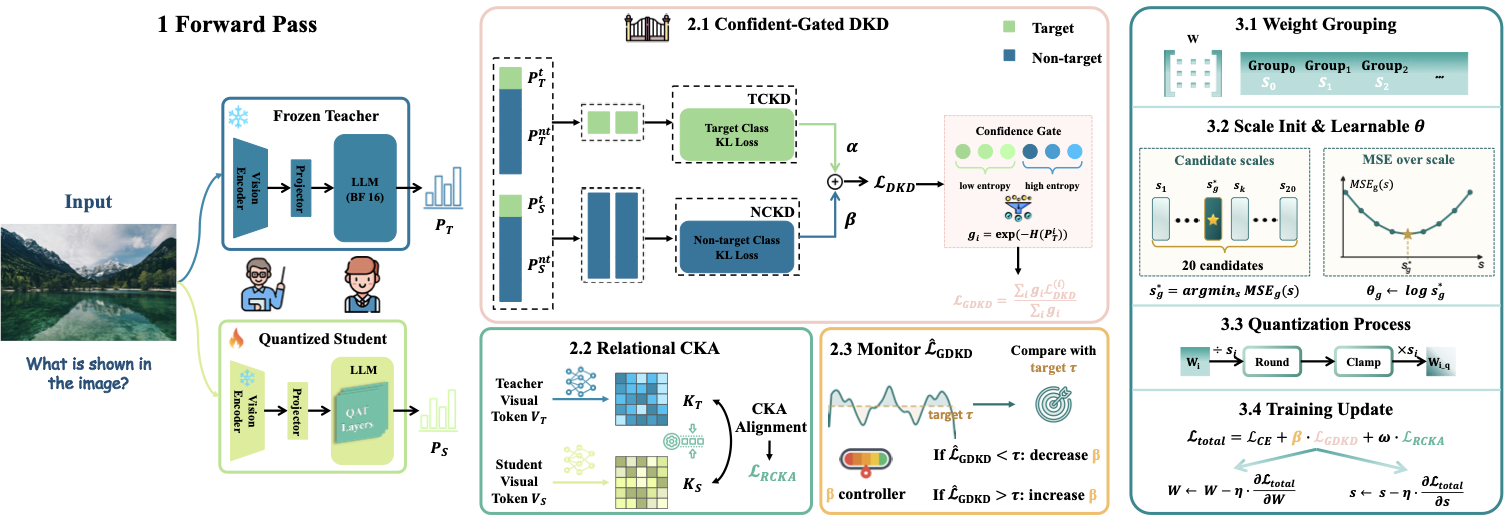
[ICML 2026] GRACE: deployable INT4 VLM via quantization-aware distillation.
Image text to text model, used with transformers.
Text generation model, used with transformers.
Text generation model, used with transformers.
Image text to text model, used with transformers.
Native Windows vLLM 0.33.0 (Python 3.13/CUDA 13.0), plus a Python 3.14/CUDA 13.2 build; older versions on the Releases page. PyTorch 2.14, FlashAttention/Rust, OpenAI serving, 10 KV formats, Multi-TurboQuant, experimental CPU/NVMe KV offload. No WSL or Docker.
Text generation model, used with transformers.
EAGLE E4B speculative decoding drafter for Gemma 4 31B DECKARD HERETIC Uncensored NVFP4 — optimized for NVIDIA DGX Spark
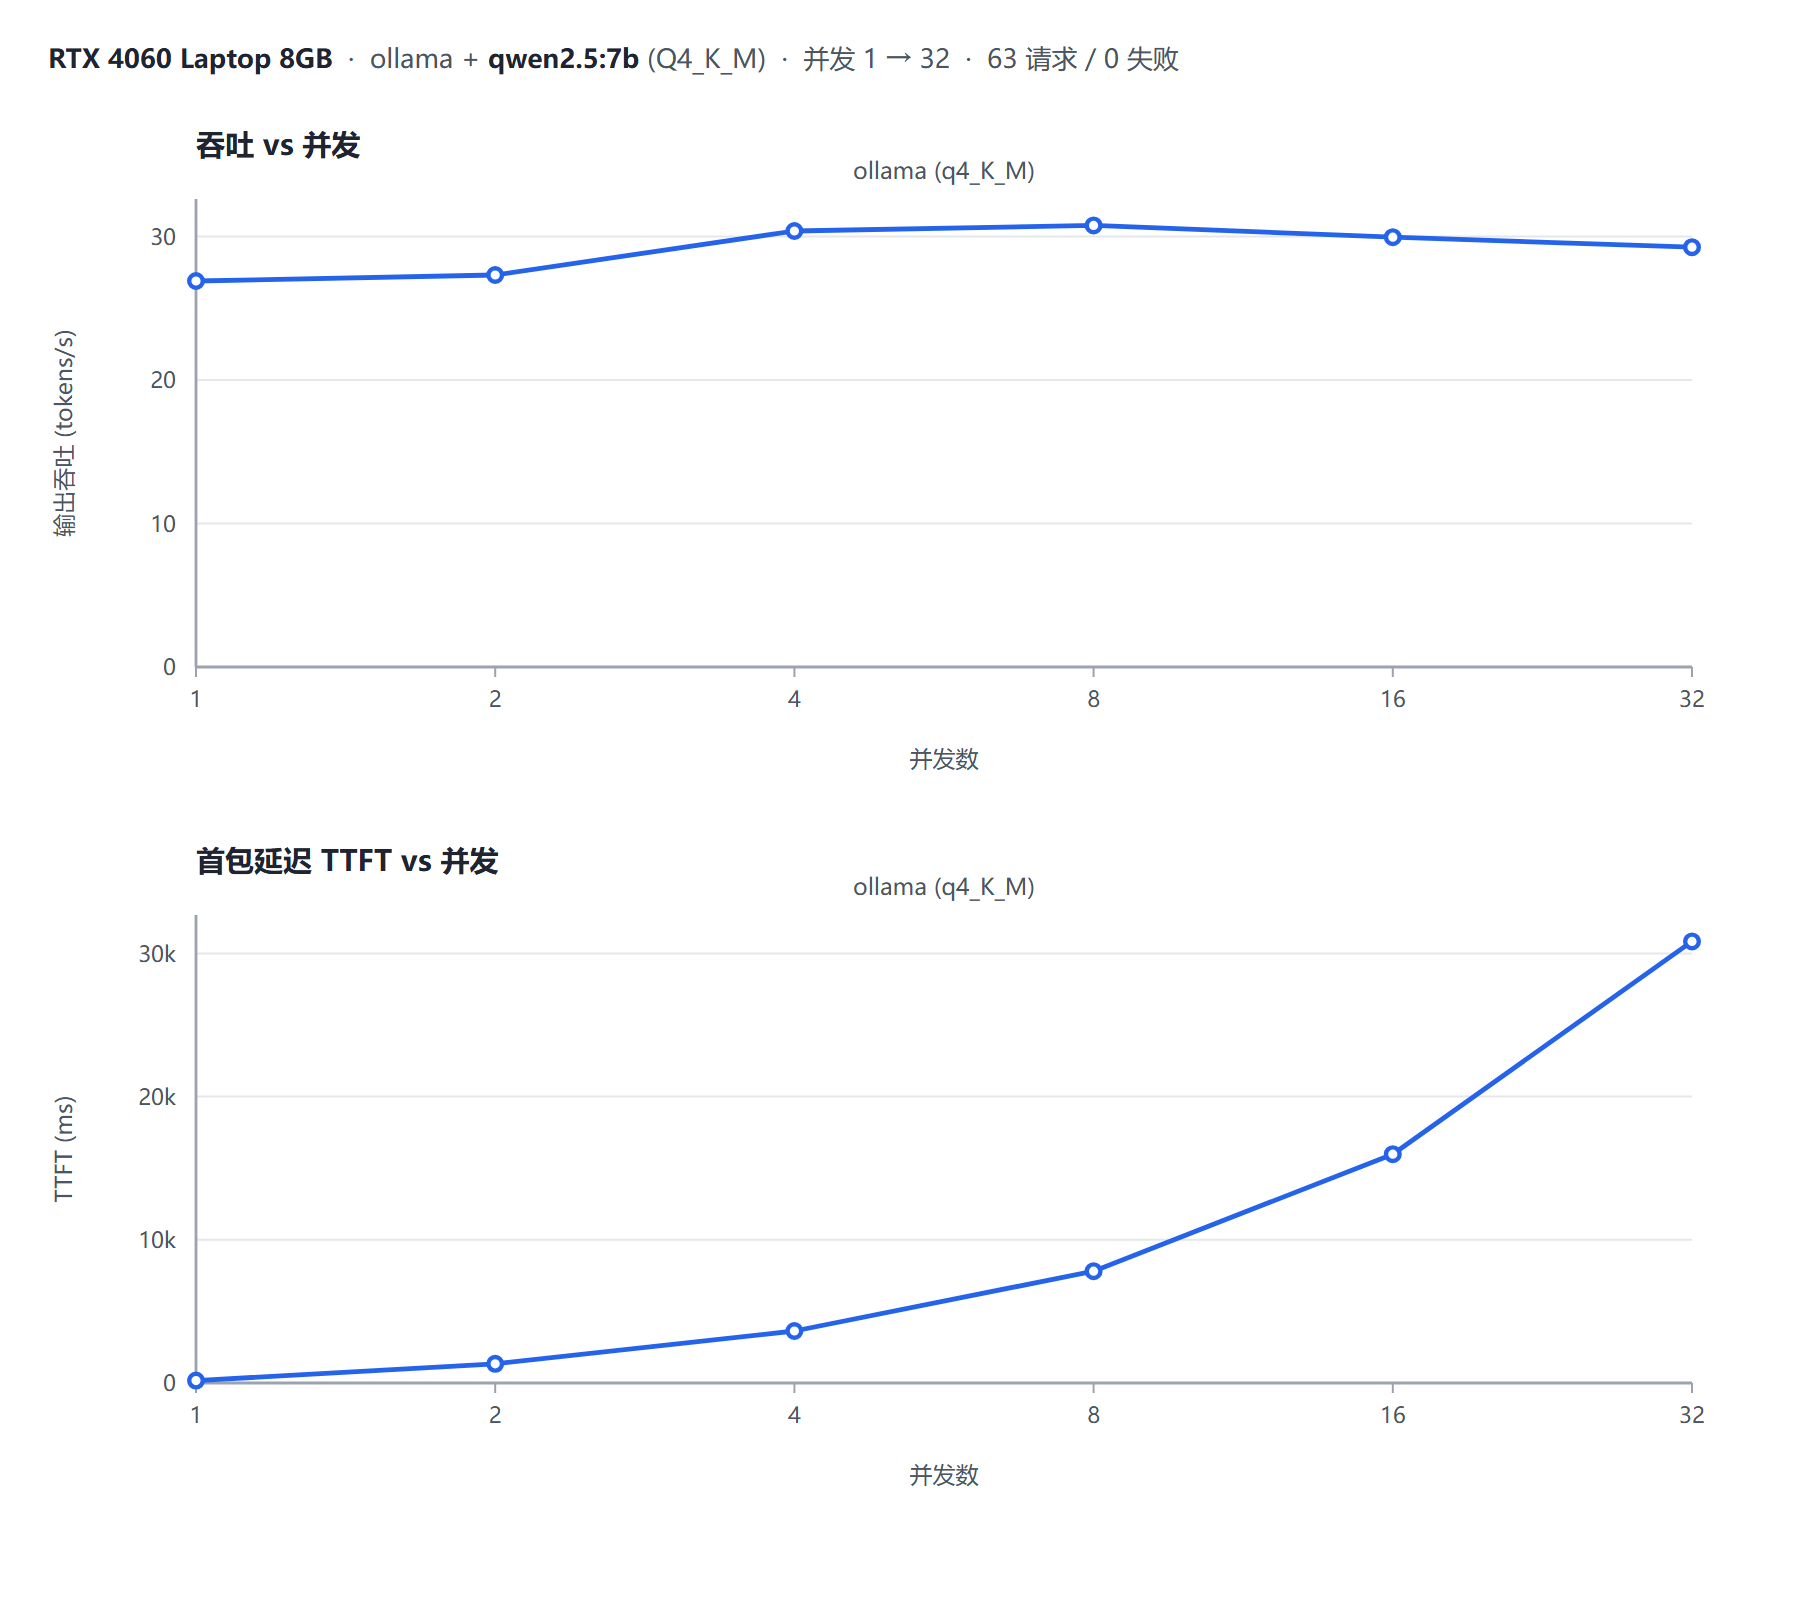
Benchmark self-hosted LLM inference across engines (vLLM, Ollama) and quantisation levels (FP16 / INT8 / AWQ / GPTQ). Concurrency sweeps, TTFT / TPOT / P99 tail latency, VRAM curves, Prometheus + Grafana, self-contained HTML reports.
Effortlessly quantize, benchmark, and publish Hugging Face models with cross-platform support for CPU/GPU. Reduce model size by 75% while maintaining performance.
Compare GPTQ, AWQ, RTN, SmoothQuant and FP8 quantization on Qwen3-0.6B with LLM Compressor: model size, perplexity, speed and output quality against the BF16 base model.
Local chat front end for DeepSeek-R1-Distill (AWQ) on an RTX 4060 laptop with vLLM — in-process FastAPI server or streaming UI over vllm serve
Pure-CUDA OpenAI-compatible server for Qwen3.8-27B on one RTX 3090: AWQ INT4 or GGUF, DFlash2 speculative decode (up to 149 tok/s on code), 262K context, prefix cache
Qwen3-VL 8B 圖表理解微調、量化與 serving 實證作品
Runs in the browser on Hugging Face
GPU-accelerated LLM inference benchmarking suite covering GGUF, AWQ, and GPTQ quantization formats with TensorRT-LLM integration stubs. Includes latency/throughput metrics dashboard and Docker + Kubernetes deployment configs.