gemm

how-to-optimize-gemm
- 2k
- C
- 3 y ago


cudnn-frontend
cuDNN Frontend is NVIDIA's modern, open-source entry point to the cuDNN library and a growing collection of high-performance open-source kernels.
- 1k
- Cuda
- Apache-2.0
- 1 d ago

awesome-cuda-and-hpc
🚀🚀🚀 This repository lists some awesome public CUDA, cuda-python, cuBLAS, cuDNN, CUTLASS, TensorRT, TensorRT-LLM, Triton, TVM, MLIR, PTX and High Performance Computing (HPC) projects.
- 526
- 16 mo ago

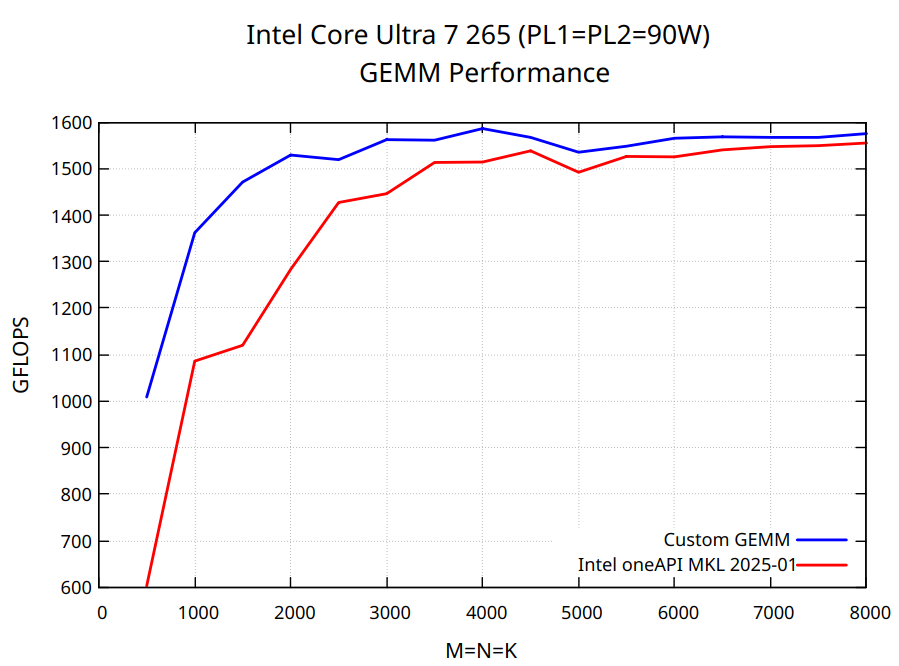

laser
The HPC toolbox: fused matrix multiplication, convolution, data-parallel strided tensor primitives, OpenMP facilities, SIMD, JIT Assembler, CPU detection, state-of-the-art vectorized BLAS for floats and integers
- 295
- Nim
- Apache-2.0
- 3 y ago


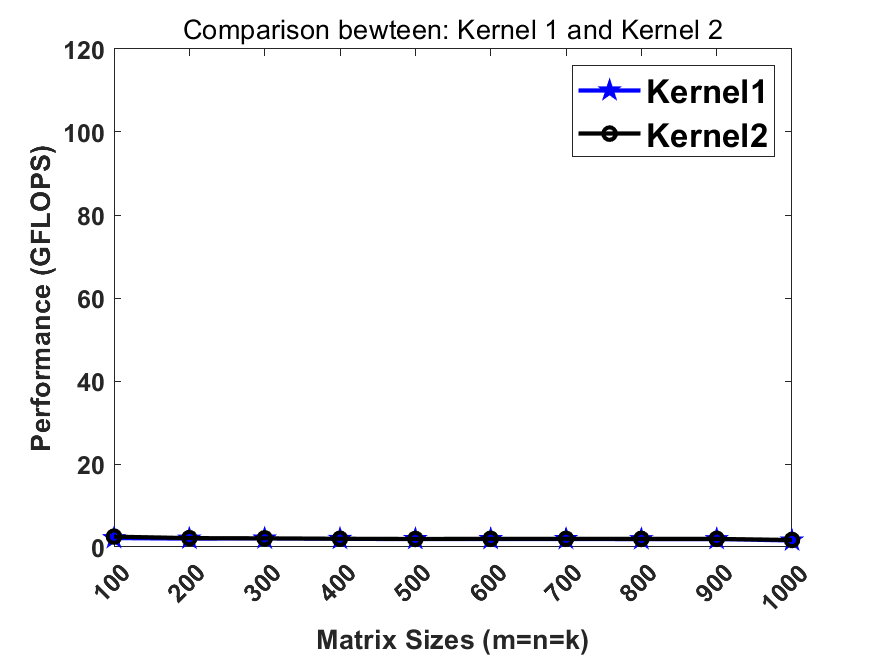
Optimizing-DGEMM-on-Intel-CPUs-with-AVX512F
Stepwise optimizations of DGEMM on CPU, reaching performance faster than Intel MKL eventually, even under multithreading.
- 165
- C
- GPL-3.0
- 5 y ago

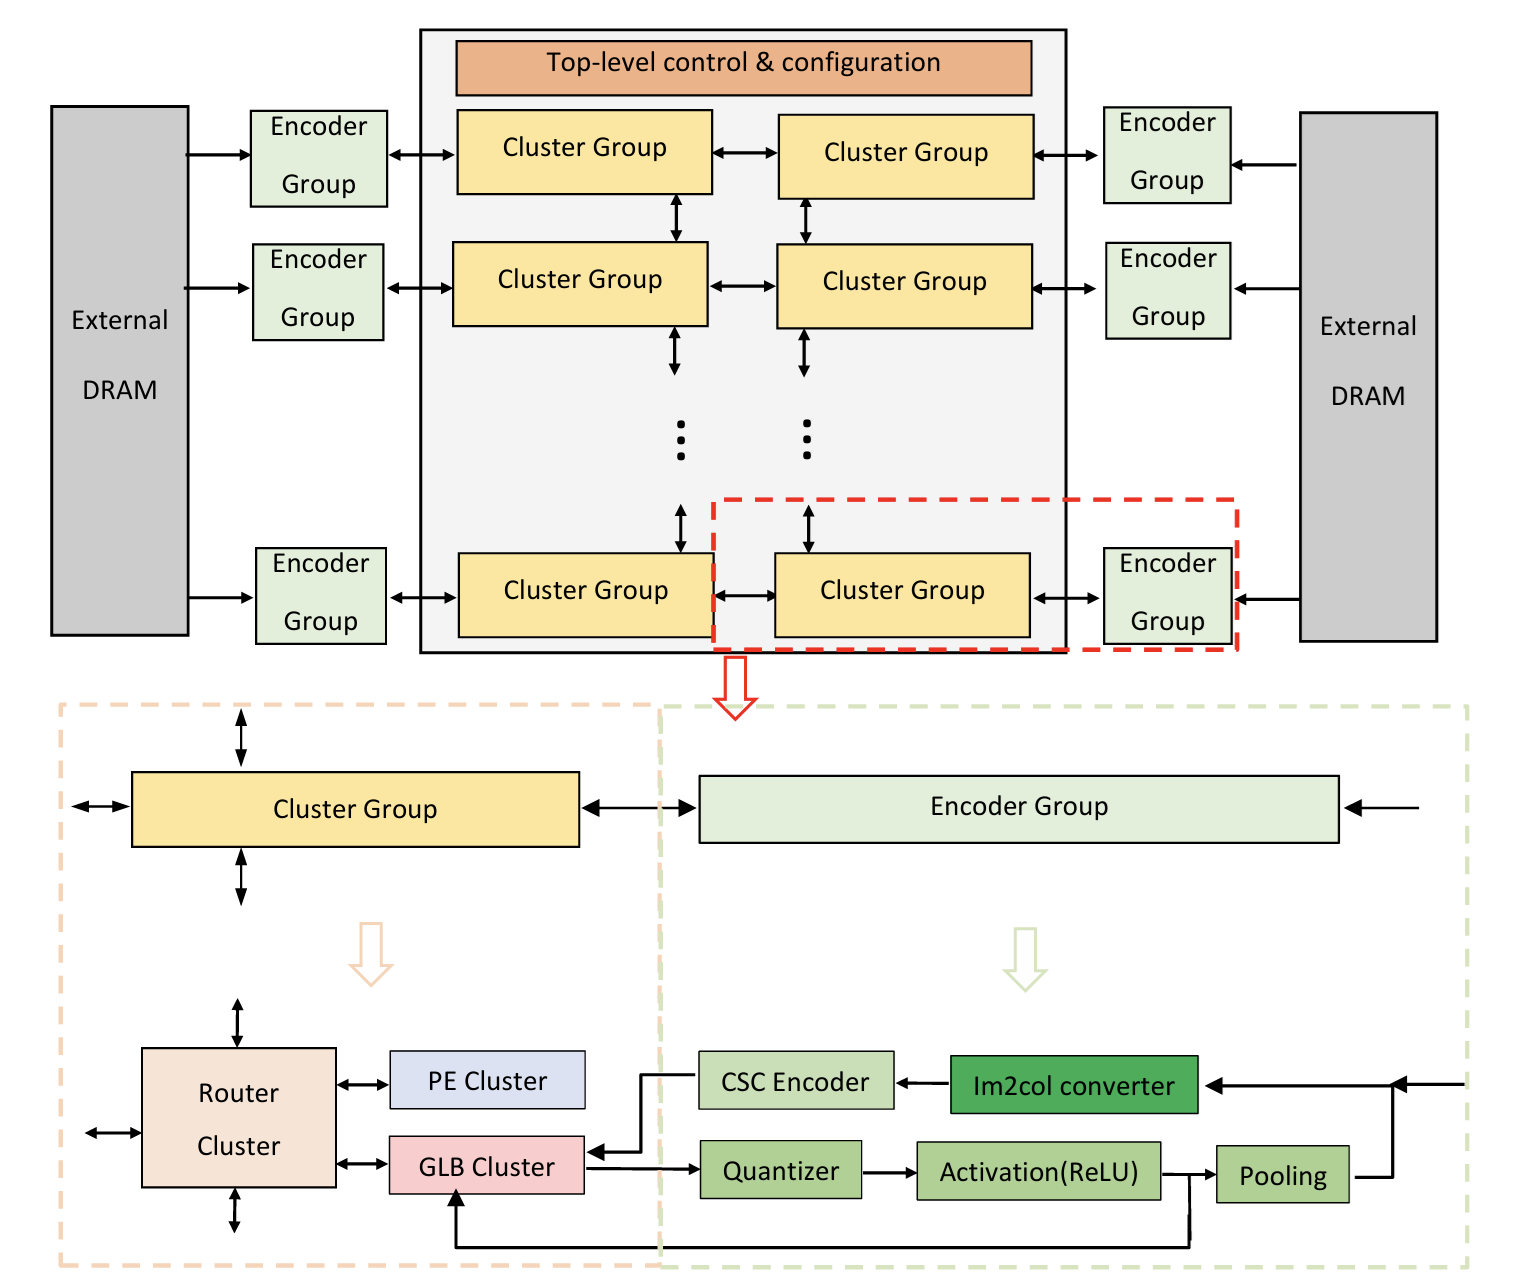
CNN-Accelerator-Based-on-Eyeriss-v2
A Flexible and Energy Efficient Accelerator For Sparse Convolution Neural Network
- 157
- Verilog
- MIT
- 16 mo ago

CUDA-Practice
CUDA编程练习项目-Hands-on CUDA kernels and performance optimization, covering GEMM, FlashAttention, Tensor Cores, CUTLASS, quantization, KV cache, NCCL, and profiling.
- 113
- Cuda
- MIT
- 6 mo ago


mmaemu
Bit-exact emulation of NVIDIA tensor-core FP8 GEMMs (torch._scaled_mm, Transformer Engine) as an H100 PCIe or RTX 4060 computes them, on the CPU or another CUDA GPU
- 64
- Python
- Apache-2.0
- 9 d ago

torch-cublas-hgemm
PyTorch half precision gemm lib w/ fused optional bias + optional relu/gelu
- 80
- Cuda
- 24 mo ago

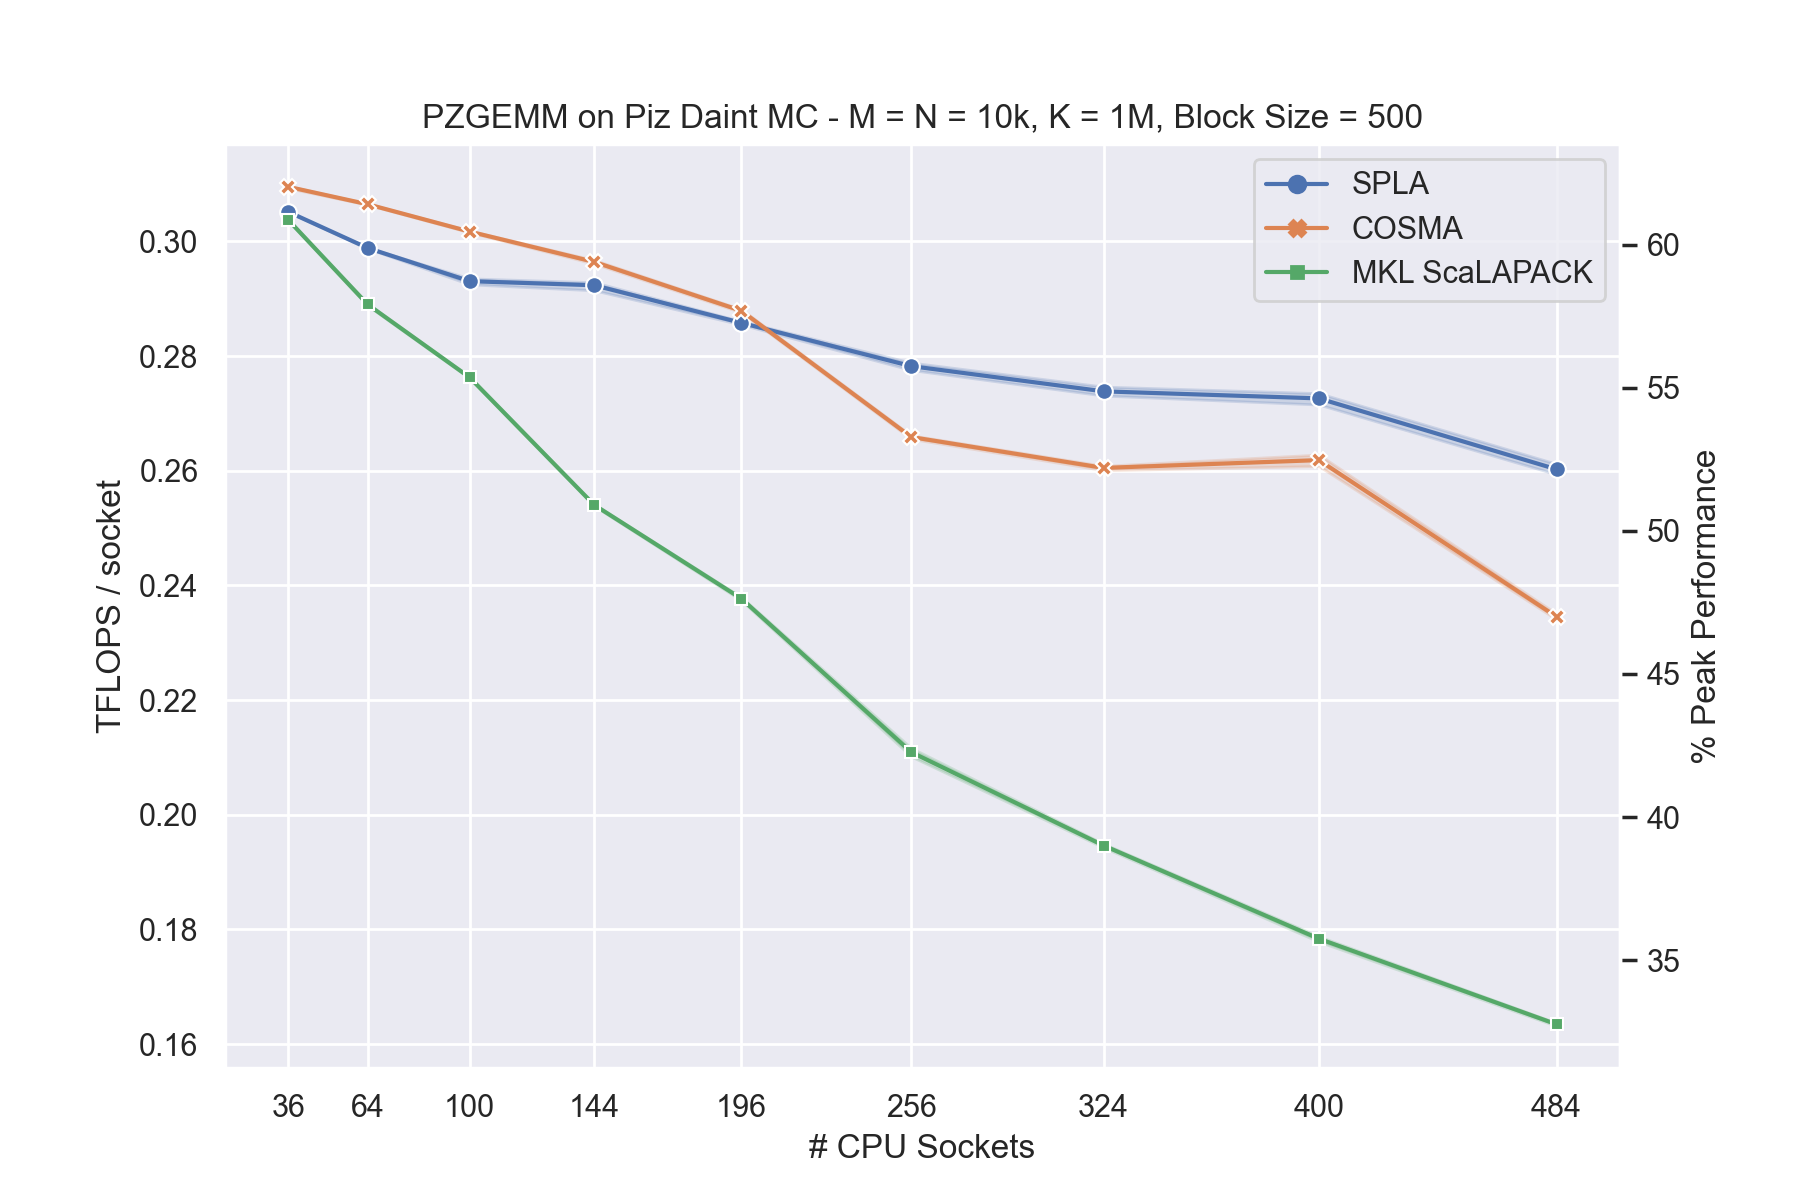
spla
Specialized Parallel Linear Algebra, providing distributed GEMM functionality for specific matrix distributions with optional GPU acceleration.
- 33
- C++
- BSD-3-Clause
- 2 y ago

