omlx
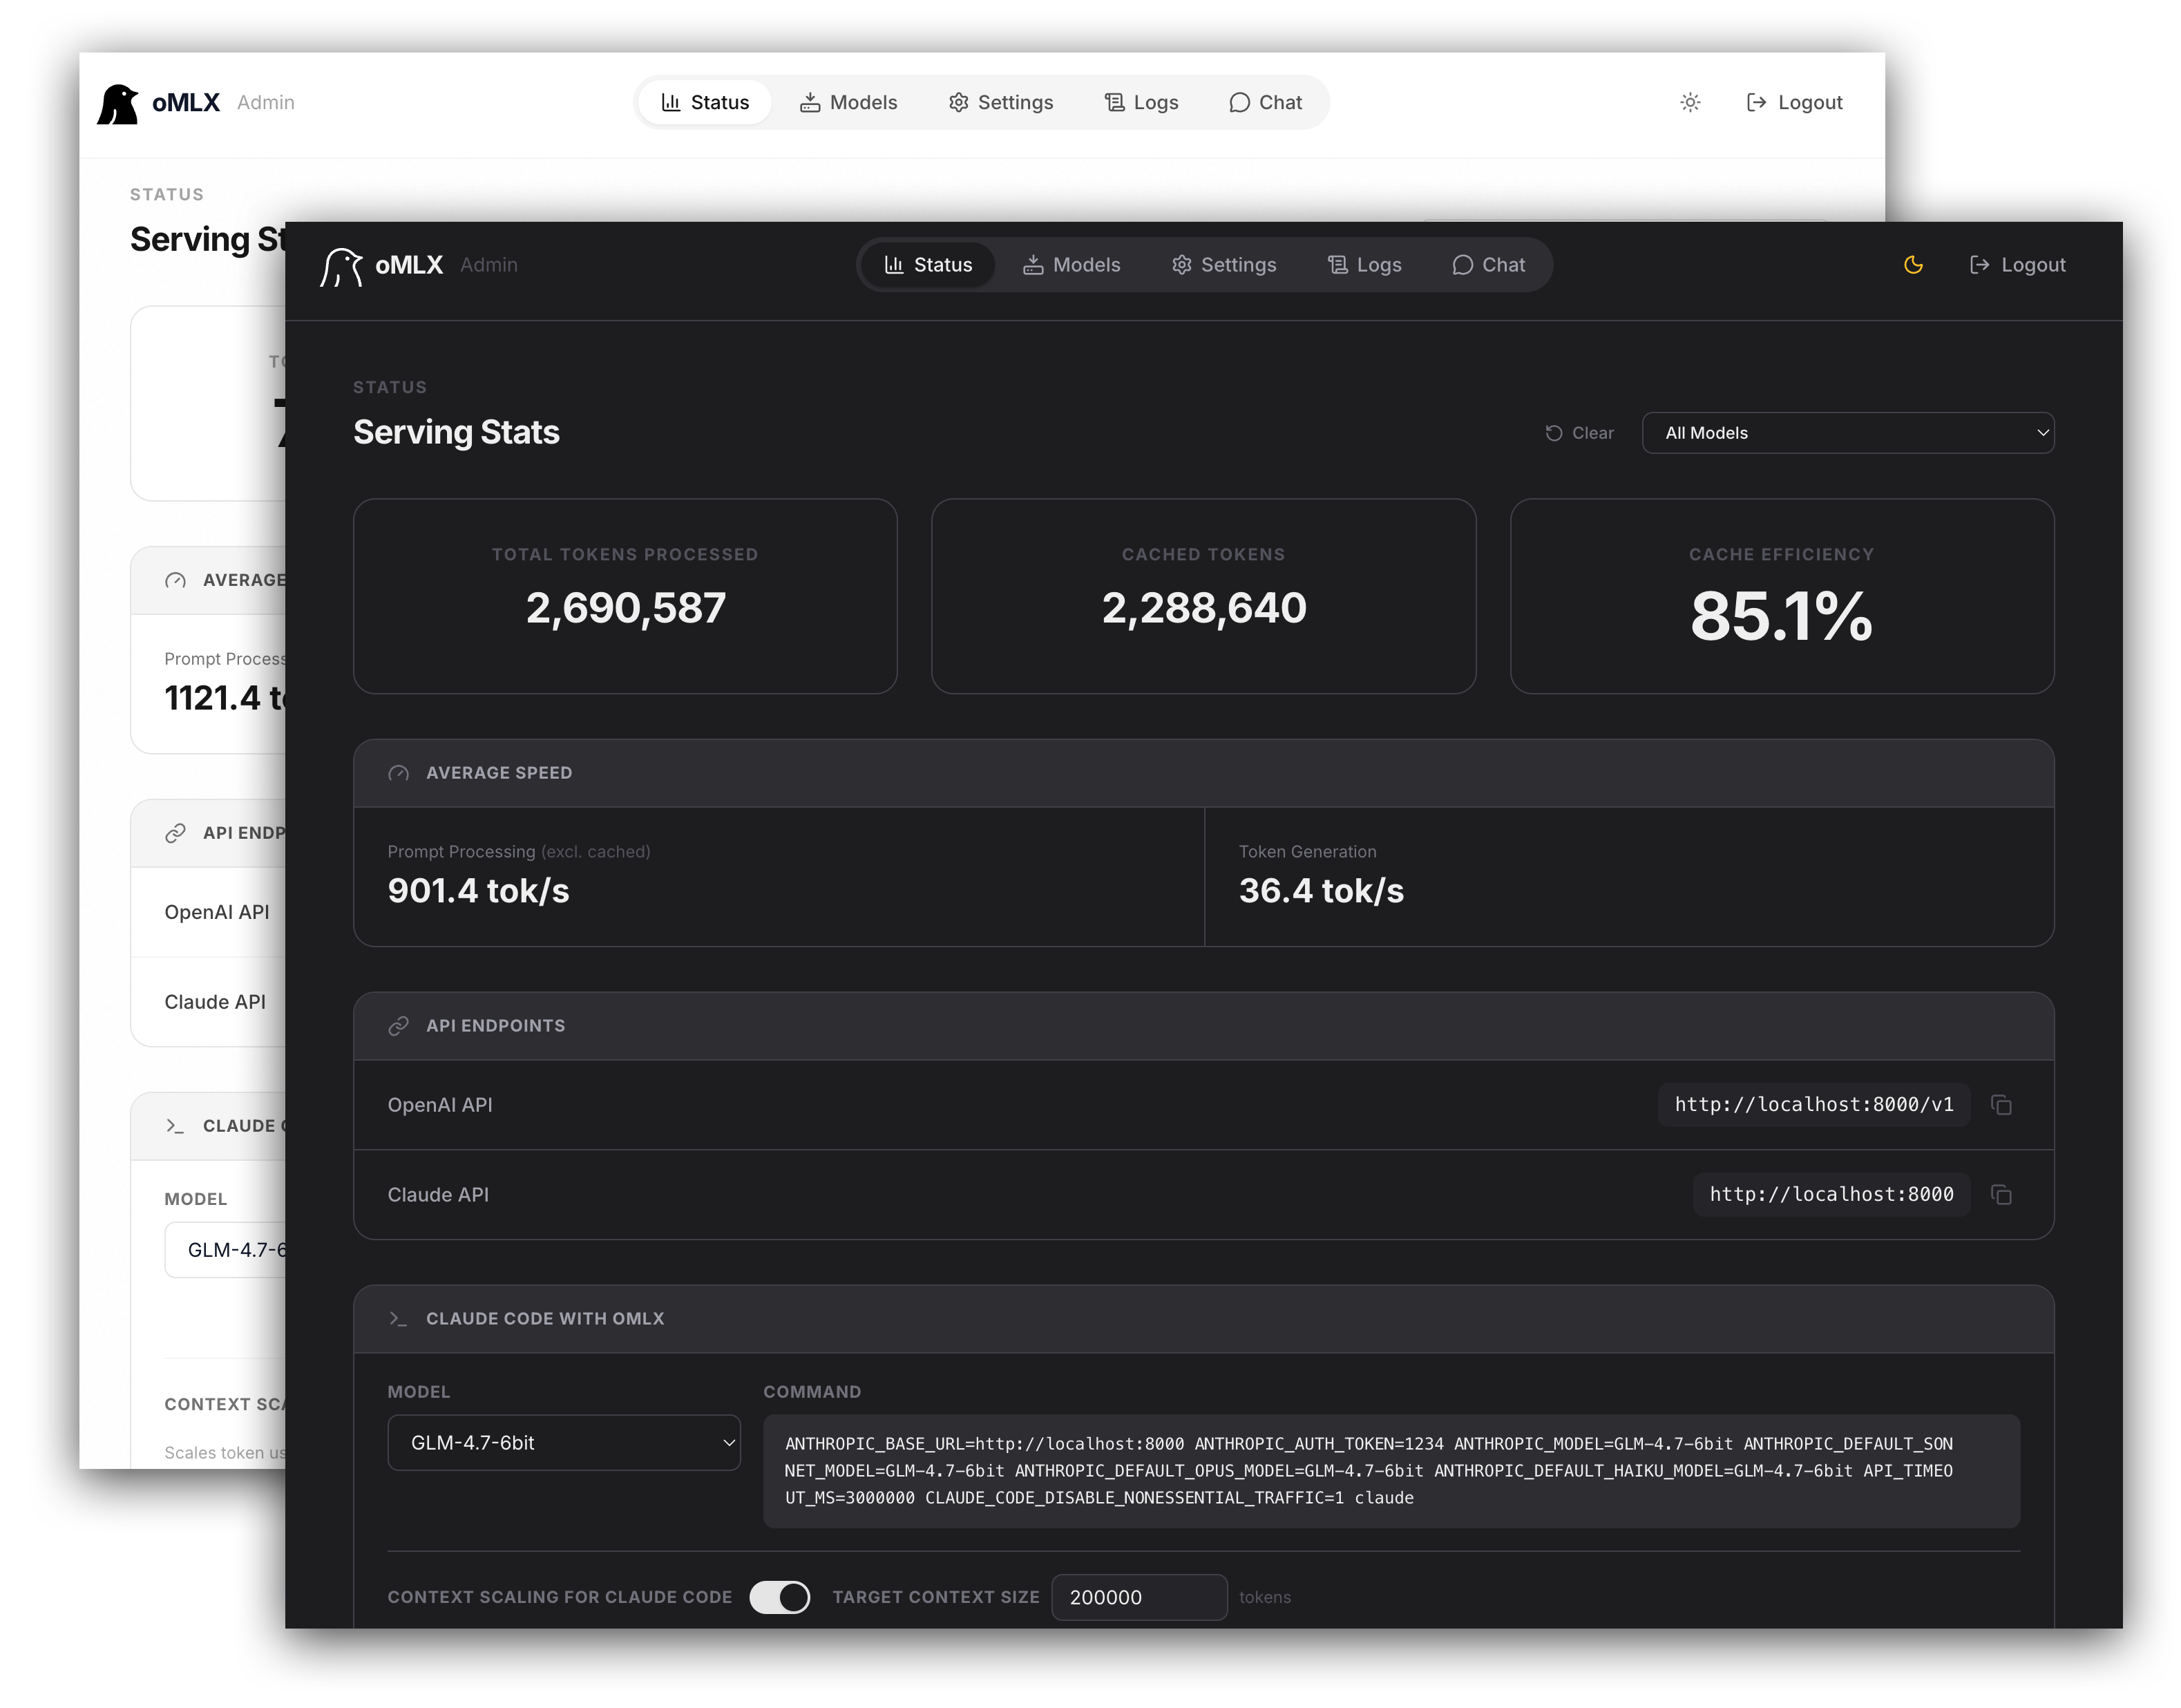
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar
- 24k
- Python
- Apache-2.0
- 14 h ago
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar
⚡ Pure-Rust WebGPU inference engine — OpenAI-API compatible, GGUF native, runs on any GPU. No Python. No llama.cpp. Single binary.
Rapid-MLX is an open-source (Apache 2.0) OpenAI- and Anthropic-compatible LLM inference server for Apple Silicon, built on MLX, focused on reliable tool calling for coding agents. Up to 4× faster than Apple's MLX (mlx-lm) on the same weights.
RamaLama is an open-source developer tool that simplifies the local serving of AI models from any source and facilitates their use for inference in production, all through the familiar language of containers.
Open-source inference server and production cluster for all the models your agent needs.
Turn any computer or edge device into a command center for your computer vision projects.
Jev-compatible API server for open decision models. Ollama for decision models: pull and serve 29 model families (Laya, pplx-decider, Clef, Winnow, coba...) locally or self-hosted behind /v1/systemone. The TypeSafe SDK works unchanged: set its base URL and pick an open model. CLI, desktop app, Docker, MCP server, public bench.
High-performance OpenAI and Anthropic compatible LLM inference server for Apple Silicon. Native MLX, continuous batching, multimodal models, MCP tool calling, and Claude Code support.
An open-source computer vision framework to build and deploy apps in minutes
Python + Inference - Model Deployment library in Python. Simplest model inference server ever.
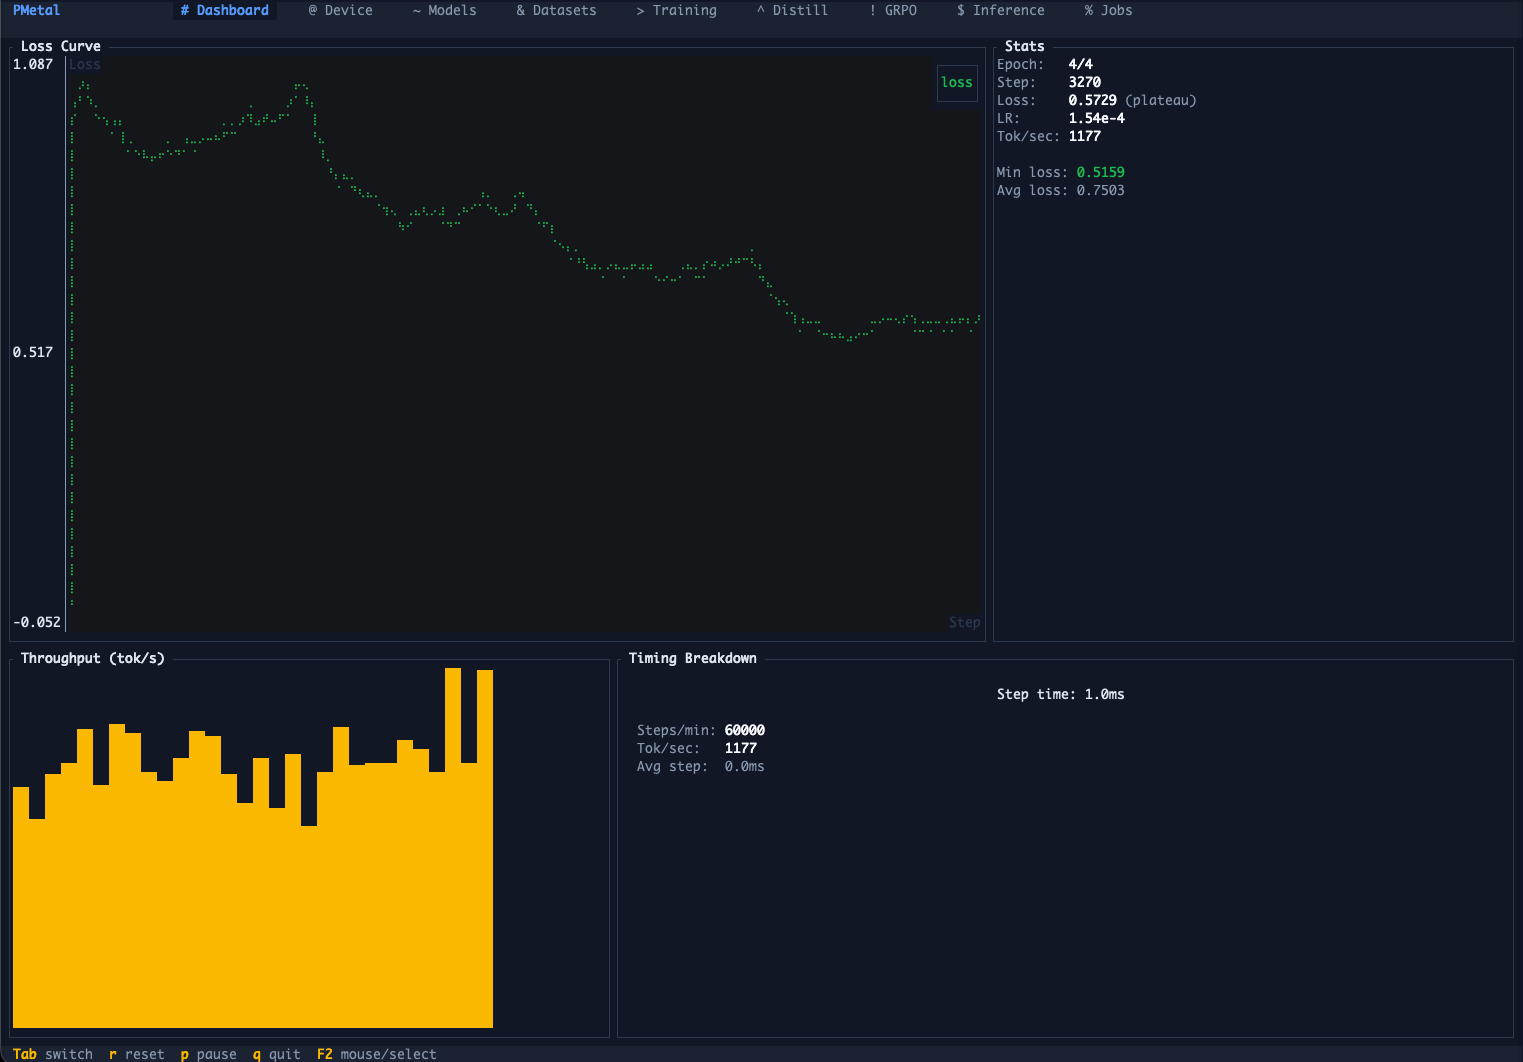
PMetal: high-performance Apple Silicon framework for local LLM inference, LoRA/QLoRA fine-tuning, serving, quantization, and MLX/Metal acceleration.
Work with LLMs on a local environment using containers
llama.cpp/ik_llama.cpp launcher: loads big MoE models across mismatched multi-GPU rigs by exact VRAM math.
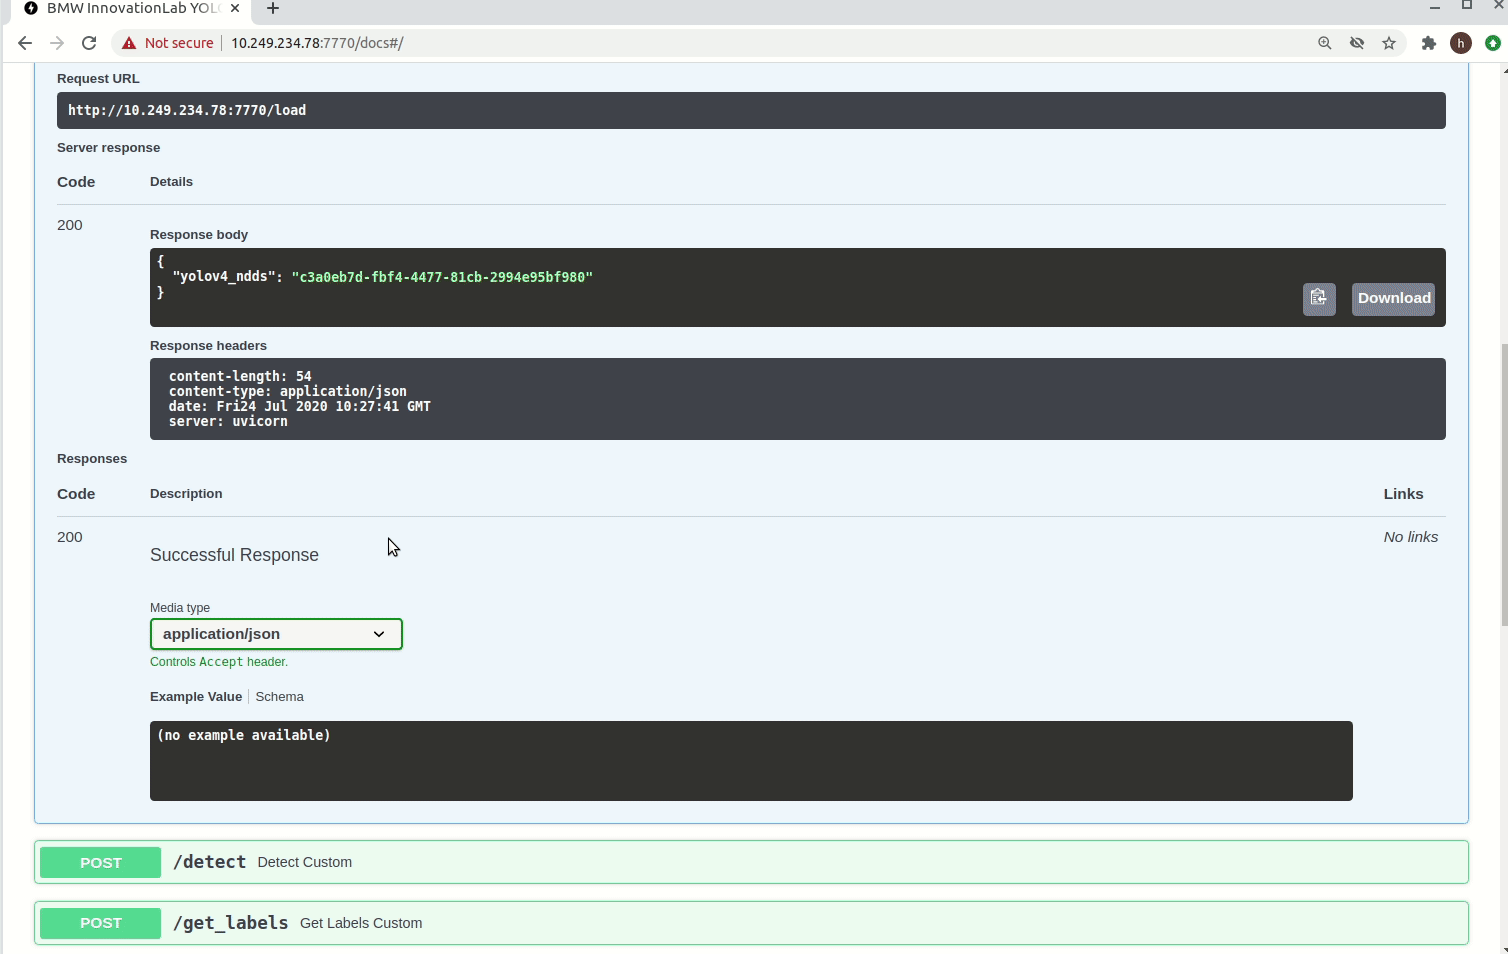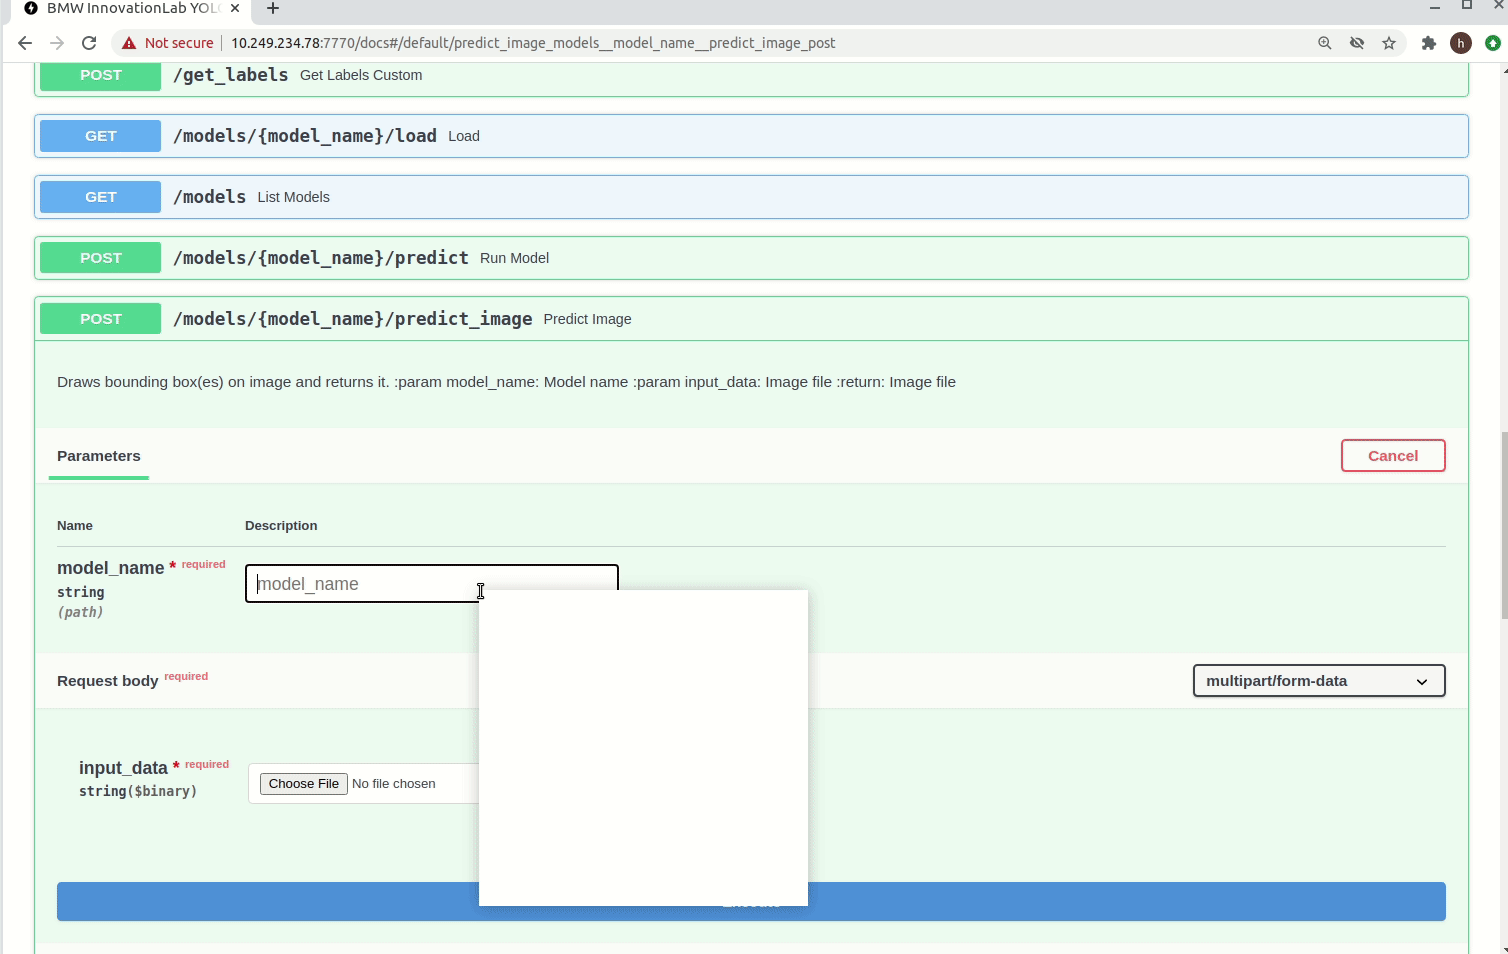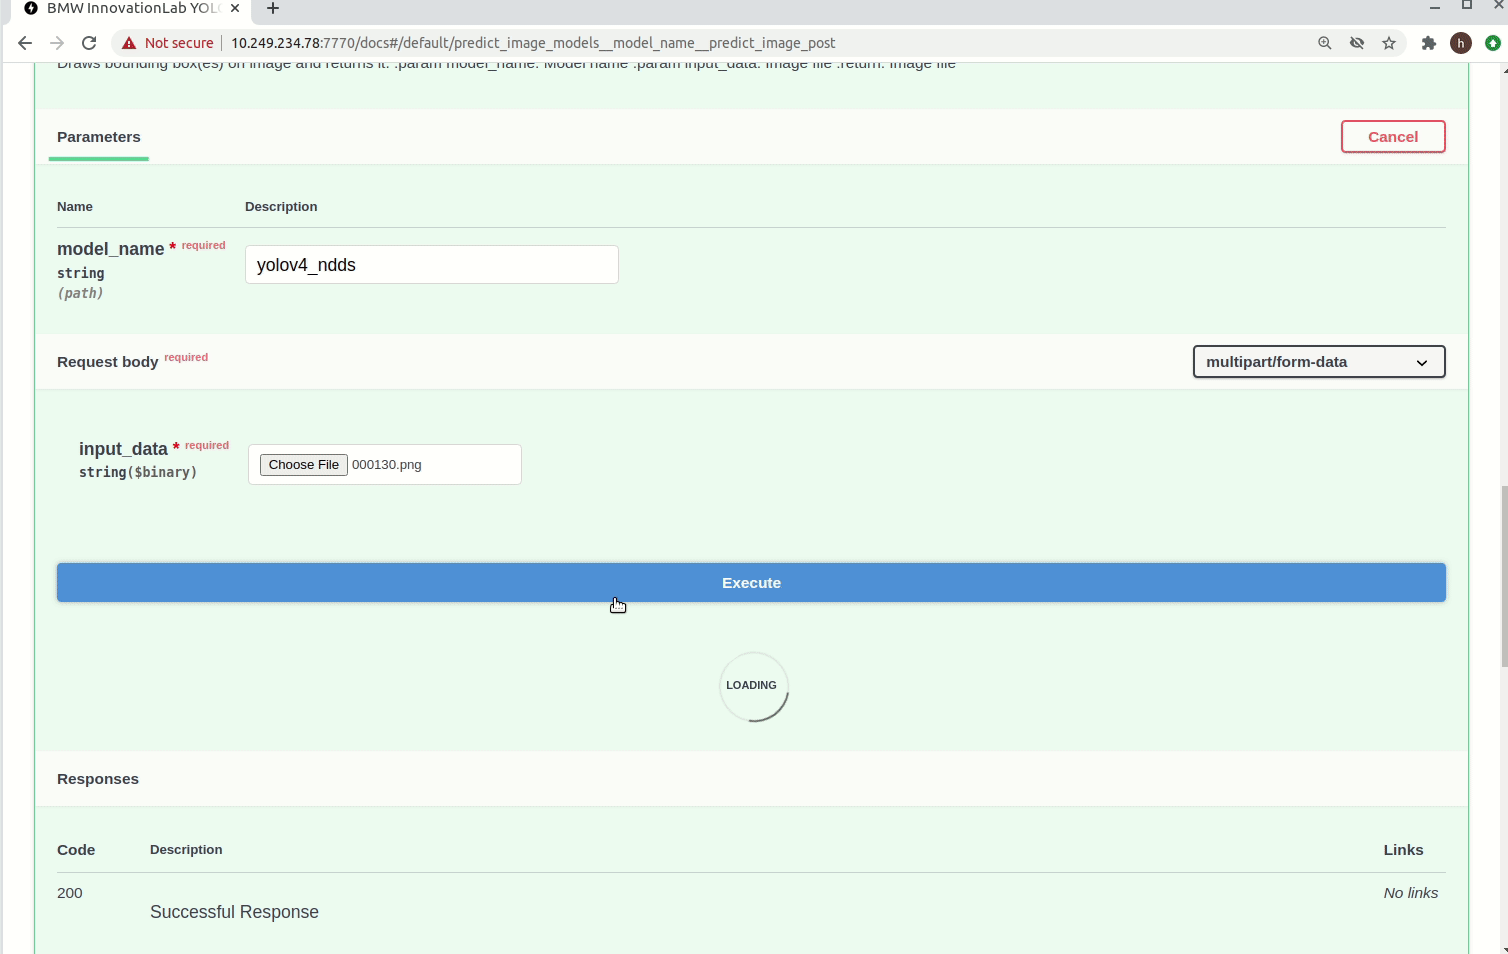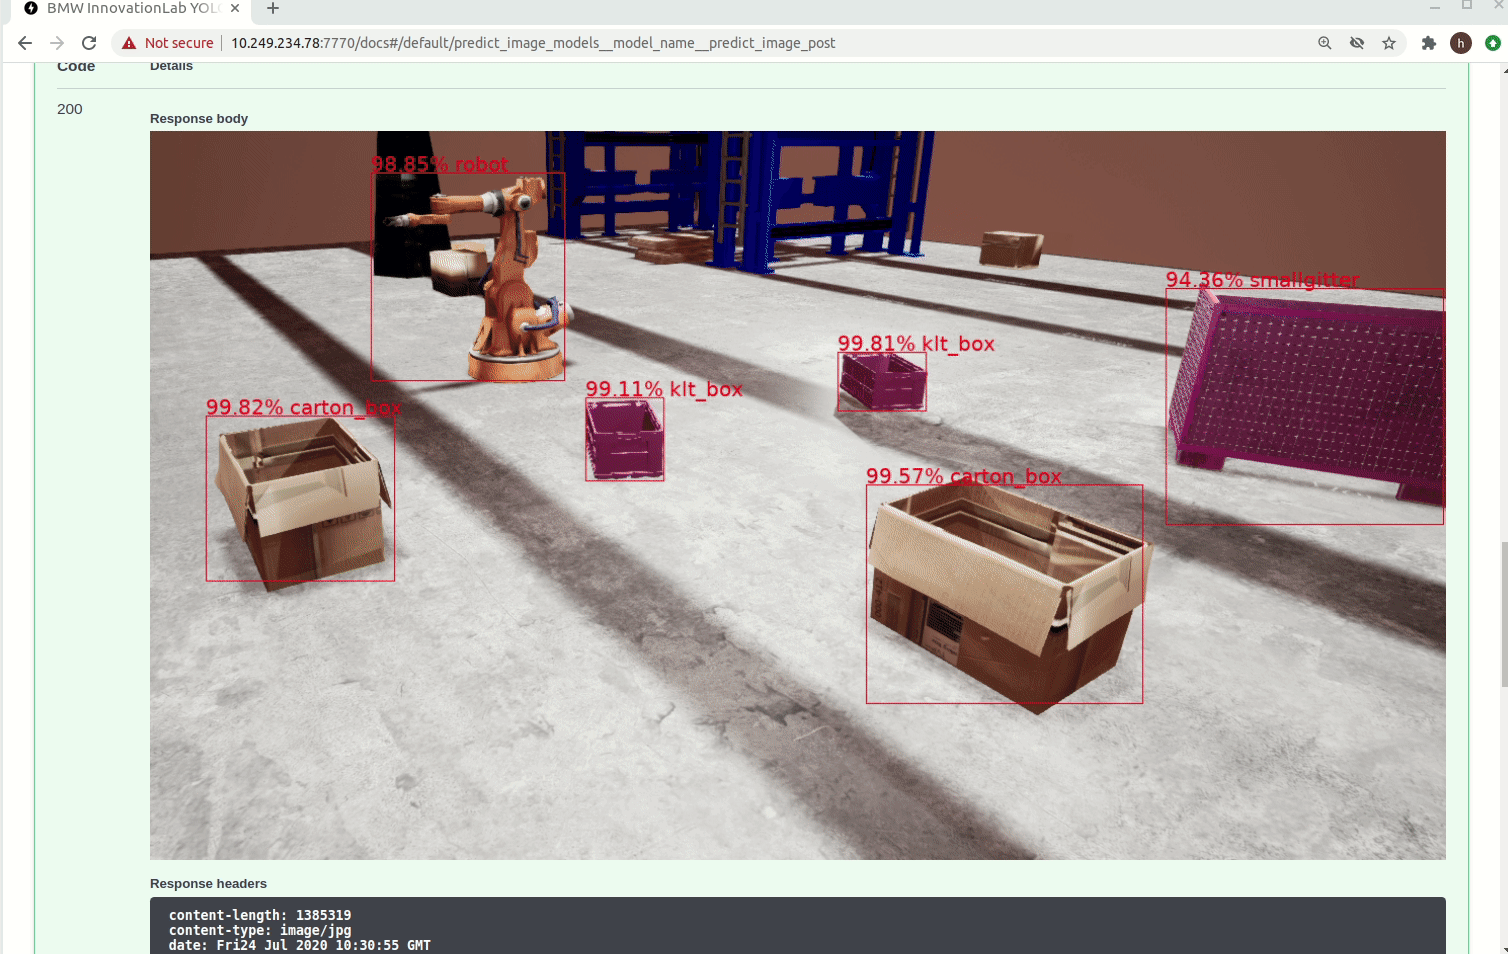
This is a repository for an nocode object detection inference API using the Yolov3 and Yolov4 Darknet framework.
This is a repository for an nocode object detection inference API using the Yolov4 and Yolov3 Opencv.
This is a repository for an object detection inference API using the Tensorflow framework.
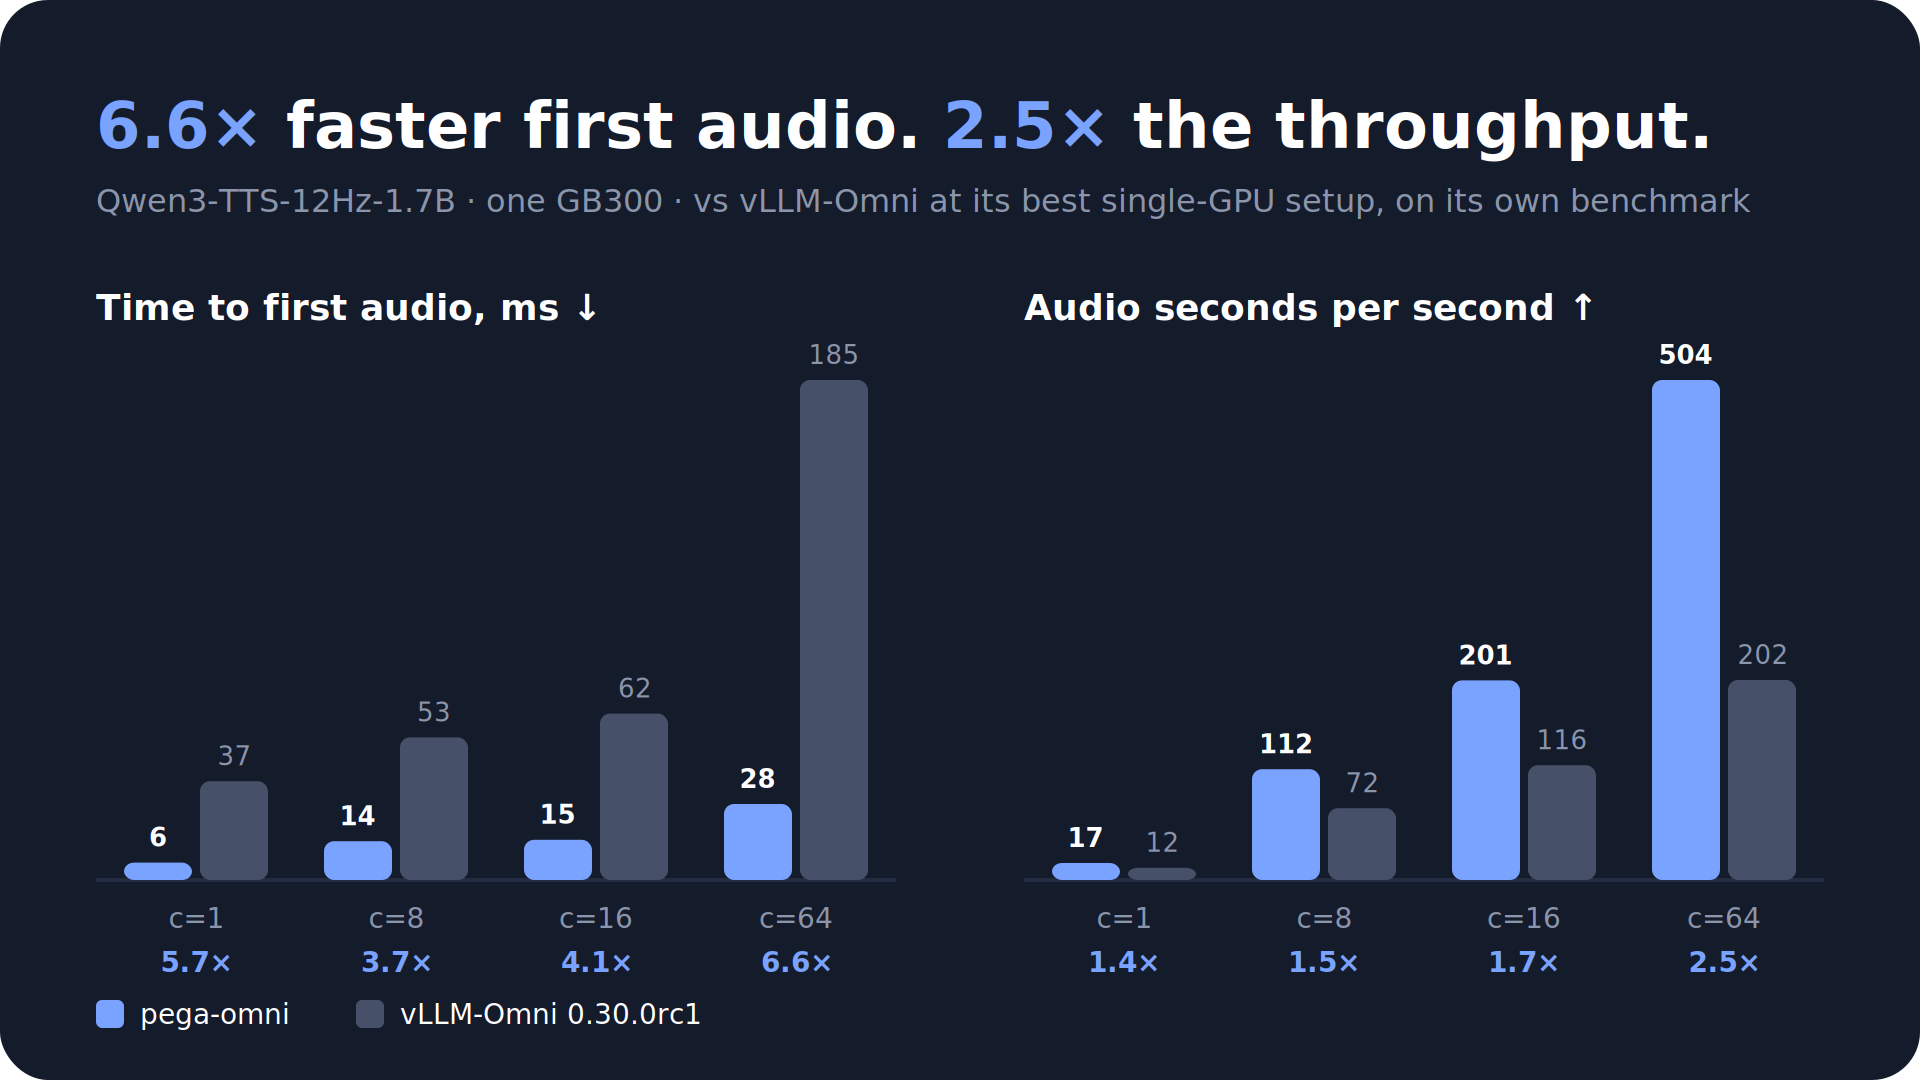
OpenAI-compatible speech serving in Rust: streaming TTS and full-duplex voice over GPT-Live. 128 concurrent PersonaPlex sessions on one GPU.
Self-hosted, OpenAI-compatible inference for the agentic era: reasoning LLMs, universal tool calling, and the Responses API alongside embeddings, speech, and image models — many models sharing your GPUs, one gateway. Powered by Ray Serve.
Serving AI/ML models in the open standard formats PMML and ONNX with both HTTP (REST API) and gRPC endpoints
👁 零代码零标注 CV AI 自动化测试工具 🚀 免除大量人工画框和打标签等,直接零代码快速自动化测试 CV 计算机视觉 AI 人工智能图像识别算法:行人检测、动植物分类、人脸识别、OCR 车牌识别、旋转校正、舞蹈姿态、抠图分割 等,还可一键 下载测试报告、导出训练和测试数据集
Local AI for your whole house: chat, images and voice on your own GPU. Computes each model's flags, fits them to your VRAM, and hot-swaps them behind one OpenAI- and Anthropic-compatible API.
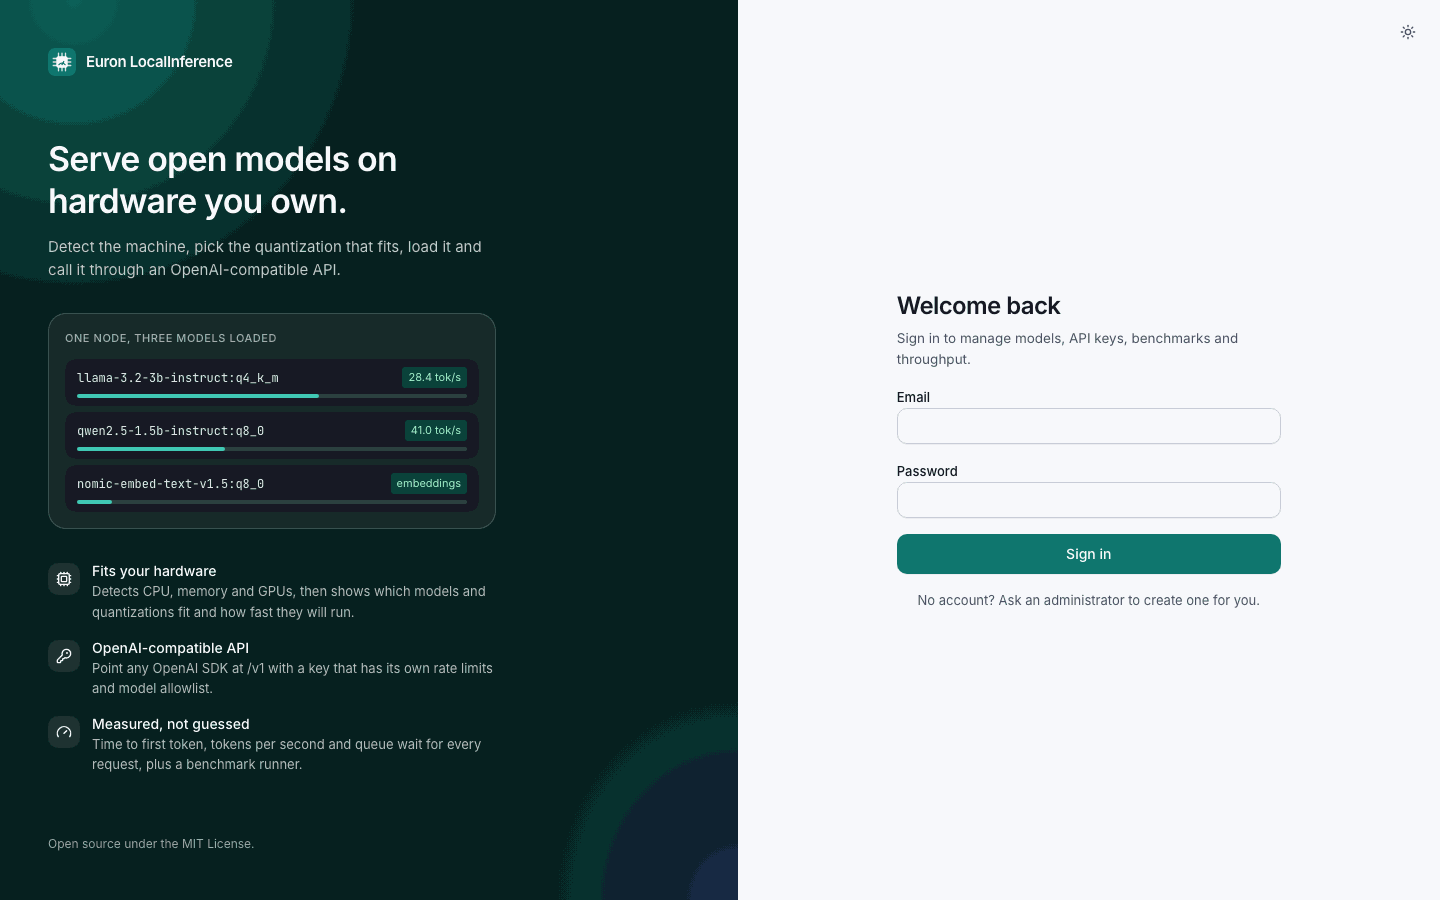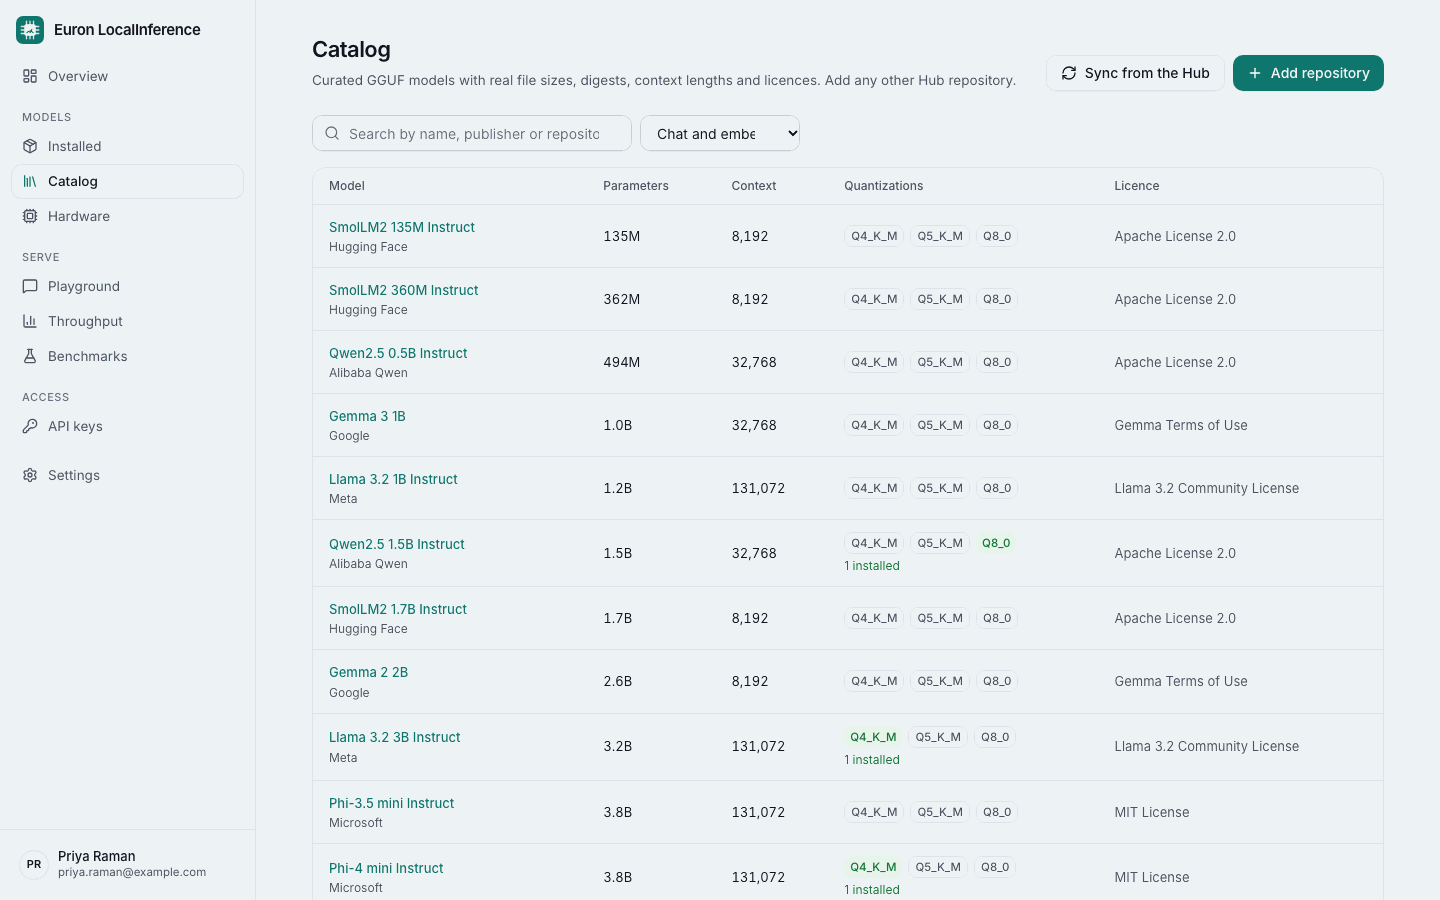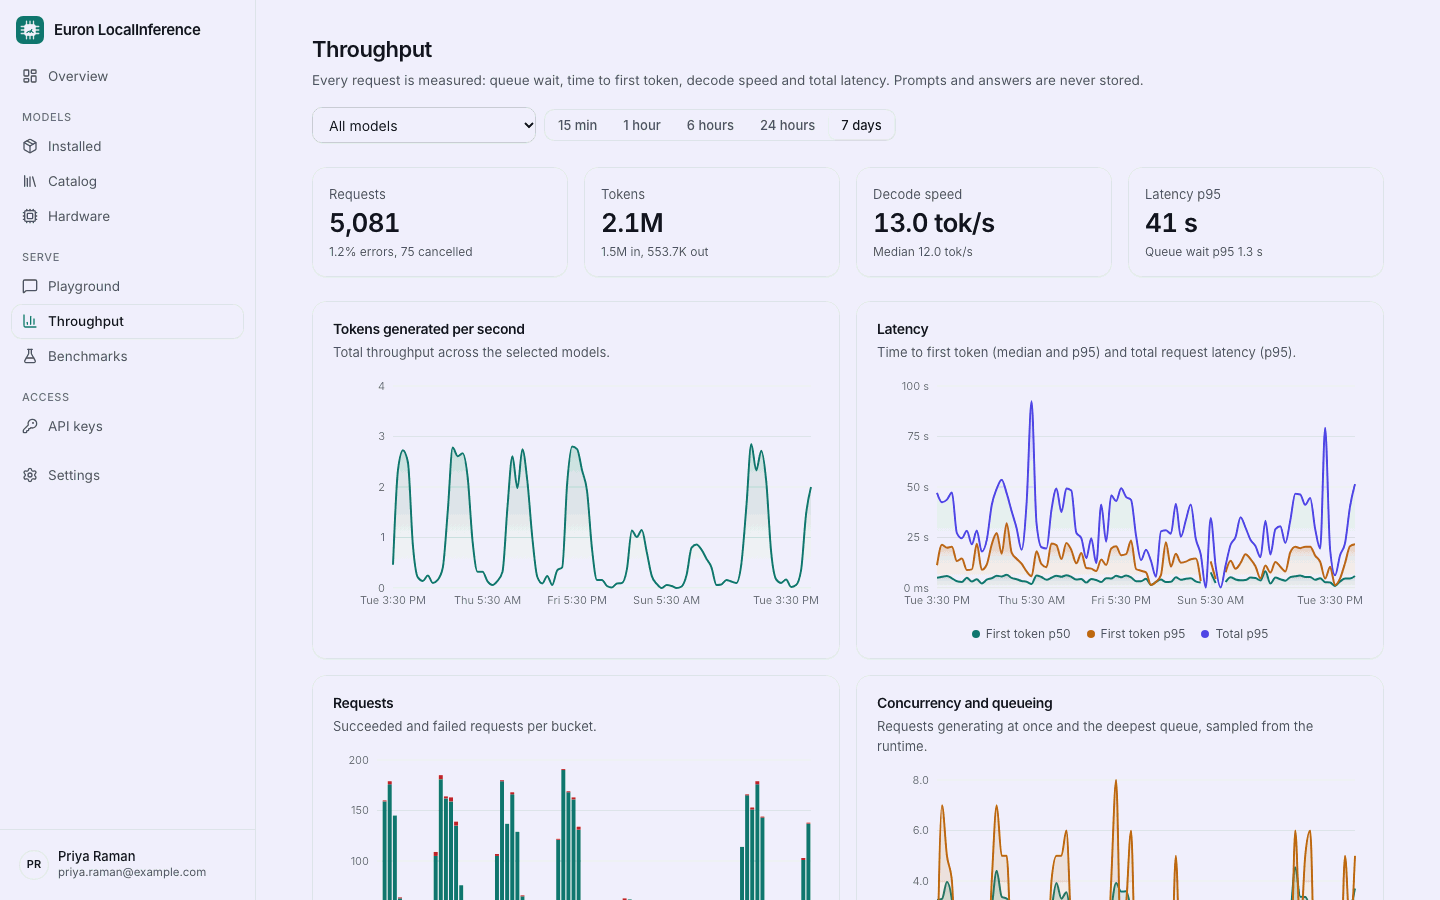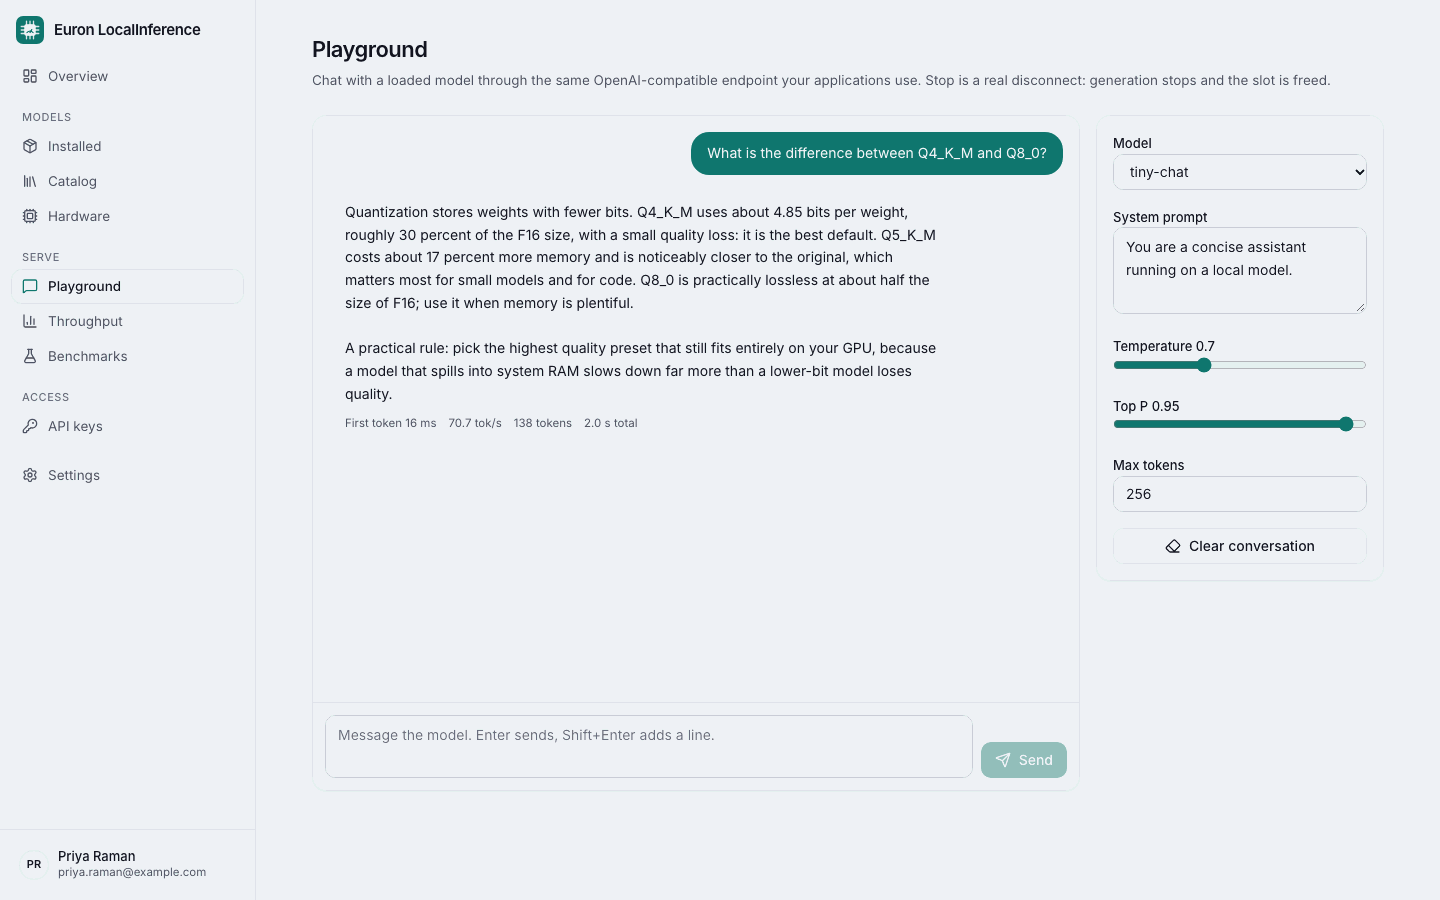
One-command local model serving: hardware detection, a GGUF model manager with quantization presets, an OpenAI-compatible API and a throughput dashboard. Terraform for AWS, Floci for local.