evaluizer
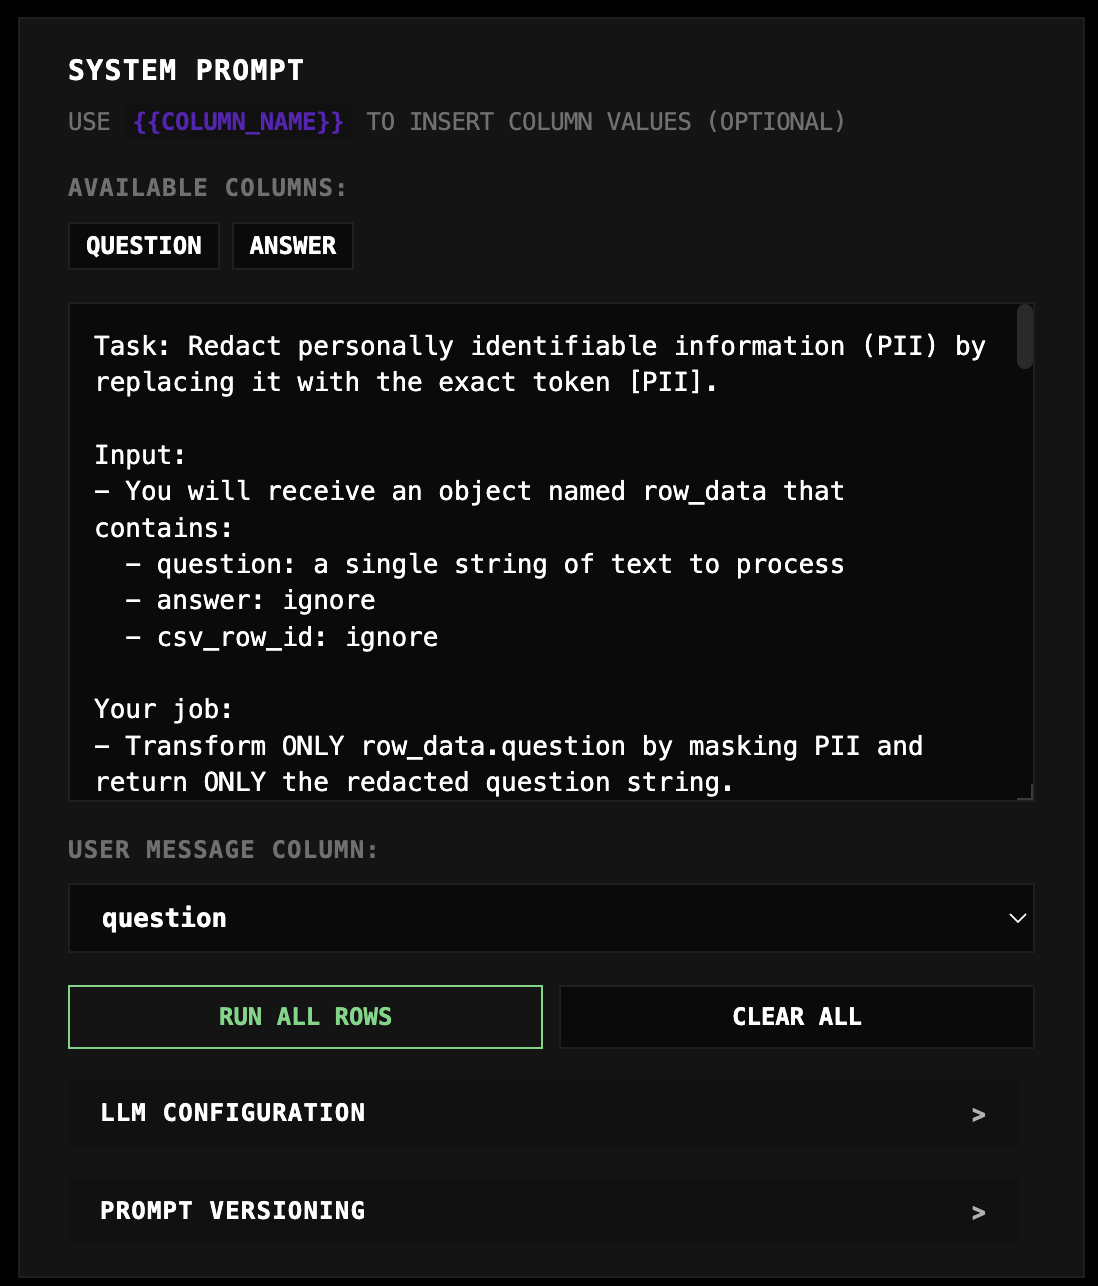
Visualize LLM outputs against datasets, manually annotate results, and run automated evaluations to algorithmically optimize prompts.
- 27
- TypeScript
- MIT
- 12 mo ago
Visualize LLM outputs against datasets, manually annotate results, and run automated evaluations to algorithmically optimize prompts.
AI Engineer interview prep for 2026: 267 real questions, 10 worked system designs, 12 company guides (OpenAI, Anthropic, DeepMind and more). Free, MIT. By Landed.
Core engine behind Calibrate, a framework for evaluating AI agents: speech-to-text, text-to-speech, LLM evaluation, end-to-end simulations
The comprehensive list of AI evaluation tools: 300+ open-source and commercial LLM evaluation frameworks, platforms, benchmarks, observability, red teaming, and guardrails — for LLMs, RAG, and AI agents.
7 Claude Code skills for software architecture review (Python, web, cloud, microservices). Includes A/B benchmarks against unskilled baseline, assertion-graded eval suite, and interactive dashboards.
Backend for Calibrate, a framework for evaluating AI agents: speech-to-text, text-to-speech, LLM evaluation, end-to-end simulations
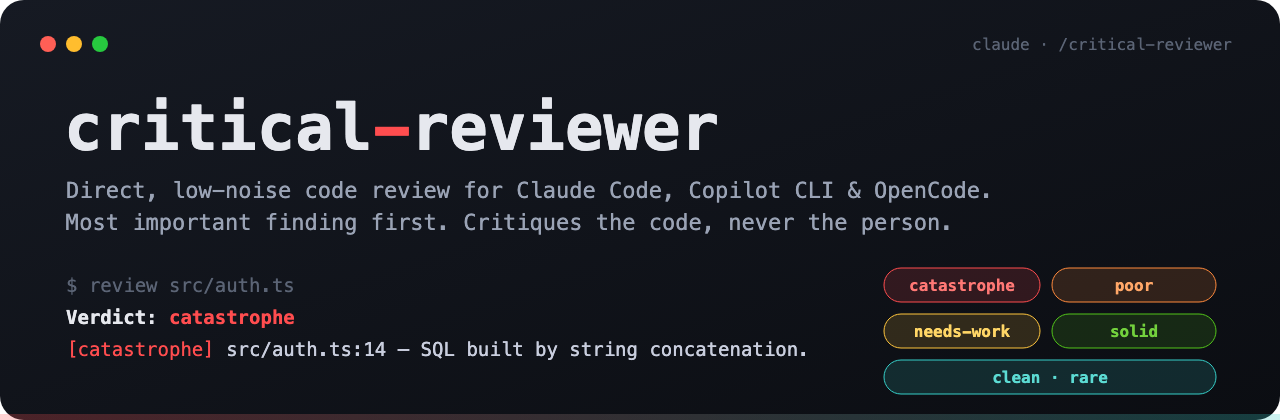
Direct, low-noise code review skill for Claude Code, GitHub Copilot CLI & OpenCode — most important finding first, one-word verdict, severity-tagged file:line issues. English & Polish.
2026 AI Product Engineer roadmap: 7 stages from LLM apps to RAG, agents, evals, and shipping. Annotated resources, tools, portfolio projects. MIT.
Frontend for Calibrate, a framework for evaluating AI agents: speech-to-text, text-to-speech, LLM evaluation, end-to-end simulations
Claude Code plugin: phased plan → implement → validate → adversarial debug-sweep loop, linked by a row-based verification.jsonl that the implementer can flip but never rewrite.
Behavioral evaluation framework for sentience-, emotion-, and welfare-related AI claims, with anti-sandbagging analysis.
In this we evaluate the LLM responses and find accuracy
A cosy fantasy voice for Claude Code: short themed lines and text art in chat, while code, commits and docs stay clean.
Propose-confirm expense agent for Hisab Kitab. FastAPI, OpenAI tool calling, Roman Urdu support and an eval suite.
Score model outputs against explicit rubrics with an Azure-backed judge, deterministic aggregation, and diffable JSON reports.