Soup
Fine-tune LLMs from one YAML. Layer streaming trains an 8B model on a 4 GB laptop GPU.
- 11k
- Python
- Apache-2.0
- 4 h ago
Fine-tune LLMs from one YAML. Layer streaming trains an 8B model on a 4 GB laptop GPU.
Turkish voice design with VoxCPM2 on a 4 GB GPU: describe a voice, pick a variant, read text in 30 languages. Patched audio.cpp, local UI in 30 languages, 14 ready-made voices.
Sınırsız Foto: Z-Image-Turbo (Q8_0, full quality) on a 4 GB GTX 1050 Ti laptop with 16 GB RAM. stable-diffusion.cpp + cuDNN VAE, Windows, every number measured. Unofficial. Not affiliated with Tongyi-MAI, leejet or NVIDIA.
WeeLLM runs large diffusion models with as little as 4 GB of VRAM, without any quantization. It dynamically determines how many layers can fit within the available VRAM and streams the text encoder and transformer layers to the GPU layer by layer, enabling inference on hardware with limited VRAM. It supports both safetensors and GGUF models.
Train LoRAs for Qwen-Image 2.1, FLUX.2 Klein 9B, FLUX.3 Image Klein, Krea 2, Z-Image, MOSS-Image, ERNIE-Image, Ideogram 4, Anima, SDXL (Pony, Illustrious, NoobAI), LTX 2.3, MiniMax-H3, and more on NVIDIA GPUs from 4–8 GB VRAM. One install, one launcher, NF4 models. Windows, Linux and RunPod.
DSH 插件 / DeepSeek Harness:视频 / 生图 / TTS 全能 · 本机运行(QQ 交流群 454707710)。★ 0.33.0 起许可★ 0.33.0 起许可改为 BSL 1.1(BUSL-1.1,非 OSI 开源许可):除托管/代管服务与直接竞品捆绑两类「竞争性使用」外免费生产使用,2030-11-15 转 Apache-2.0;0.32.1 及更早仍 MIT、不追溯。★ 1.0.0:选模型「假成功」根治(拒绝时如实回未生效 + ★ 1.0.0:选模型「假成功」根治(拒绝时如实回未生效 + 原因,不再无条件报已选)、优化面板与素材库白条同源修复(持久化缓存
Experimental local LLM inference for old hardware: in-tree llama.cpp fork, sparse KV, MTP, VRAM governor, Rust tooling.
MiniMax H3 video generation on 2080Ti 22G (Turing sm_75) - field-tested handbook, workflows & FAQ
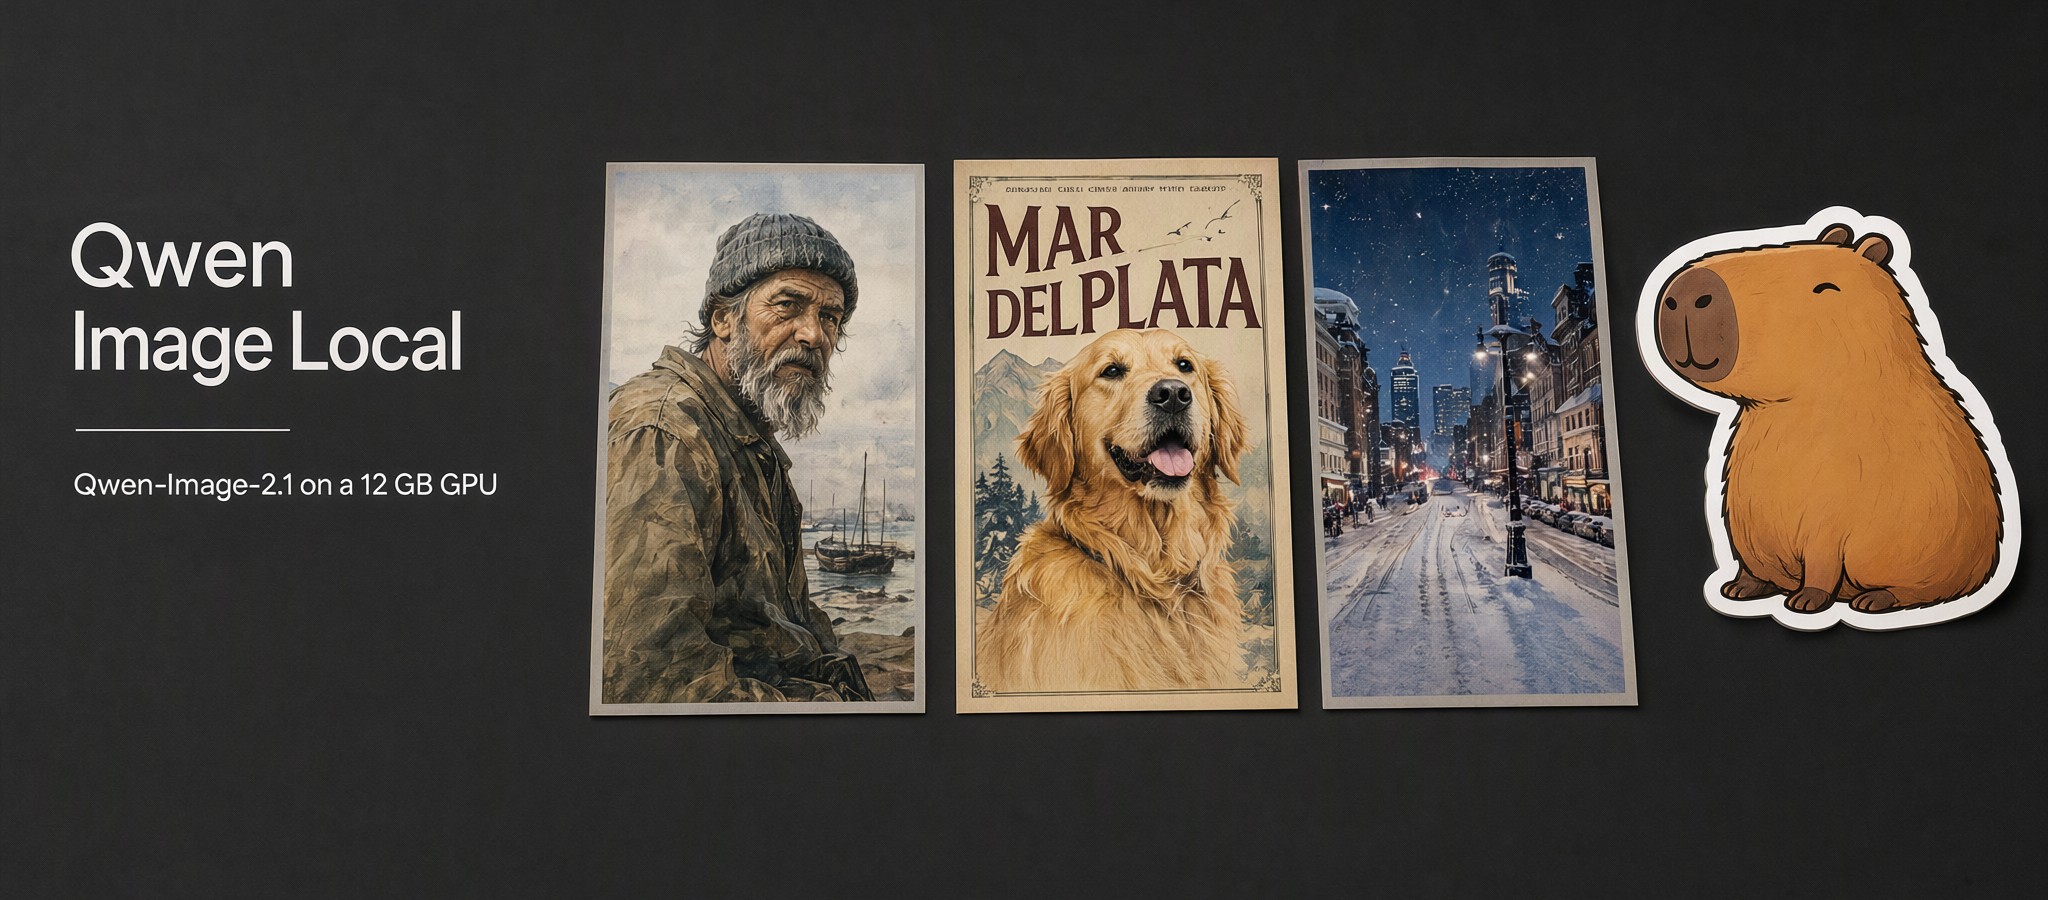
Type a prompt or drop up to 10 photos: Qwen-Image-2.1 renders it on your 12 GB GPU in ~35 s. Desktop app + CLI, honest benchmark vs gpt-image-2.
Text generation model, used with transformers.
Run Mixture-of-Experts LLMs (Qwen3, gpt-oss, GLM, DeepSeek) bigger than your RAM with llama.cpp: hot experts cached in RAM, the rest streamed from SSD. Windows (Vulkan/AMD, NVIDIA) and Linux, long context, coding agents.
Run Qwen-Image-2.1 on an 8GB GPU — one-command ComfyUI + GGUF setup, workflows and VRAM doctor.
Run a 35B LLM on a GTX 1070 with 8 GB VRAM: custom CUDA inference engine for Ornith-1.5-35B-A3B (MoE, NVFP4) on Windows, ~25-30 tok/s. Expert streaming, fused NVFP4 kernels, prefix cache, OpenAI-, Anthropic- and Ollama-compatible API for local AI agents.
Ternary LLMs on llama.cpp, any GPU — run a 27B model in 5.5–6.7 GB. Prebuilt Linux/Windows binaries, Vulkan and CUDA, OpenAI-compatible API.
Portable Windows GGUF converter with Vulkan ACTCAL, GSQ/RCO and MACaQ-R. / Конвертация и калибровка GGUF на RX 580.