qlora


Soup
Fine-tune LLMs from one YAML. Layer streaming trains an 8B model on a 4 GB laptop GPU.
- 11k
- Python
- Apache-2.0
- 1 h ago

bitsandbytes
Accessible large language models via k-bit quantization for PyTorch.
- 8.5k
- Python
- MIT
- 2 wk ago

Firefly
Firefly: 大模型训练工具,支持训练Qwen2.5、Qwen2、Yi1.5、Phi-3、Llama3、Gemma、MiniCPM、Yi、Deepseek、Orion、Xverse、Mixtral-8x7B、Zephyr、Mistral、Baichuan2、Llma2、Llama、Qwen、Baichuan、ChatGLM2、InternLM、Ziya2、Vicuna、Bloom等大模型
- 6.6k
- Python
- 2 y ago


LLM-Finetuning-Toolkit
Toolkit for fine-tuning, ablating and unit-testing open-source LLMs.
- 873
- Python
- Apache-2.0
- 1 d ago

halo
Halo is an open-source framework built by White Circle for training large language and multimodal models
- 867
- Python
- 3 h ago

can-i-finetune-this
Single-GPU LLM fine-tuning preflight: memory estimates, runnable LoRA/QLoRA recipes, and local measurements.
- 796
- Python
- MIT
- 6 wk ago



END-TO-END-GENERATIVE-AI-PROJECTS
End to End Generative AI Industry Projects on LLM Models with Deployment_Awesome LLM Projects
- 644
- MIT
- 22 mo ago

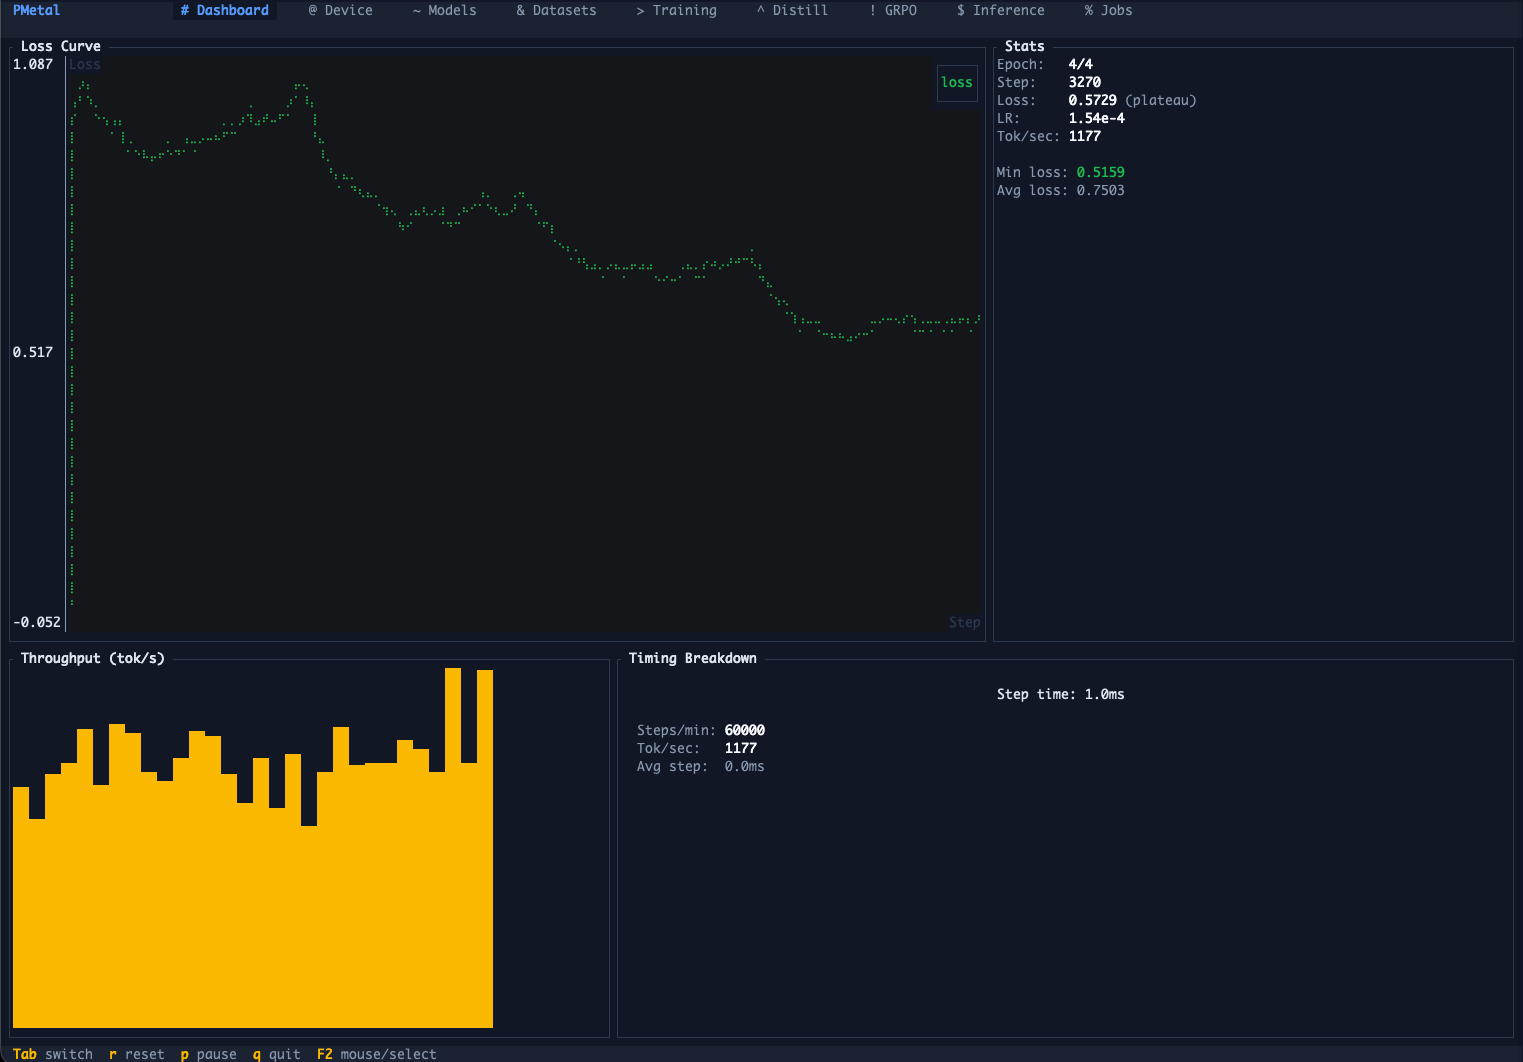
pmetal
PMetal: high-performance Apple Silicon framework for local LLM inference, LoRA/QLoRA fine-tuning, serving, quantization, and MLX/Metal acceleration.
- 334
- Rust
- 2 wk ago

mini-verl
verl for a single consumer GPU. PPO, GRPO and on-policy distillation on NVIDIA GPUs.
- 311
- Python
- Apache-2.0
- 2 mo ago

unsloth-buddy
Zero-friction LLM fine-tuning skill for Claude Code, Gemini CLI & any ACP agent. Unsloth on NVIDIA · TRL+MPS/MLX on Apple Silicon. Automates env setup, LoRA training (SFT, DPO, GRPO, vision), post-hoc GRPO log diagnostics, evaluation, and export end-to-end. Part of the Gaslamp AI platform.
- 282
- Python
- MIT
- 5 mo ago


Rearchitecting-LLMs
Official code for the Manning book on structural LLM optimization: depth/width pruning, knowledge distillation, and attention optimization, runnable on free Colab GPUs.
- 81
- Jupyter Notebook
- Apache-2.0
- 1 d ago

cavegemma
LoRA fine-tune Gemma 4 31B to speak caveman-mode natively. Style: github.com/JuliusBrussee/caveman
- 123
- Python
- 2 d ago

Cyber-Ornith-1.5-9B-OBLITERATED-i1-GGUF
- 72
- 838k
- apache-2.0
- 8 wk ago

MirrorFlow
从对话数据到训练:数字分身 + 模型蒸馏 From Dialogue Data to Training Closed-Loop: Digital Twin + Model Distillation
- 72
- Python
- Apache-2.0
- 8 mo ago

Finetuning-Suite
Finetune any model on HF in less than 30 seconds
- 59
- Jupyter Notebook
- Apache-2.0
- 3 wk ago

yolo-gen
Train YOLO + VLM with one command. Auto-generate vision-language training data from YOLO labels - no extra labeling needed.
- 41
- Python
- MIT
- 7 mo ago


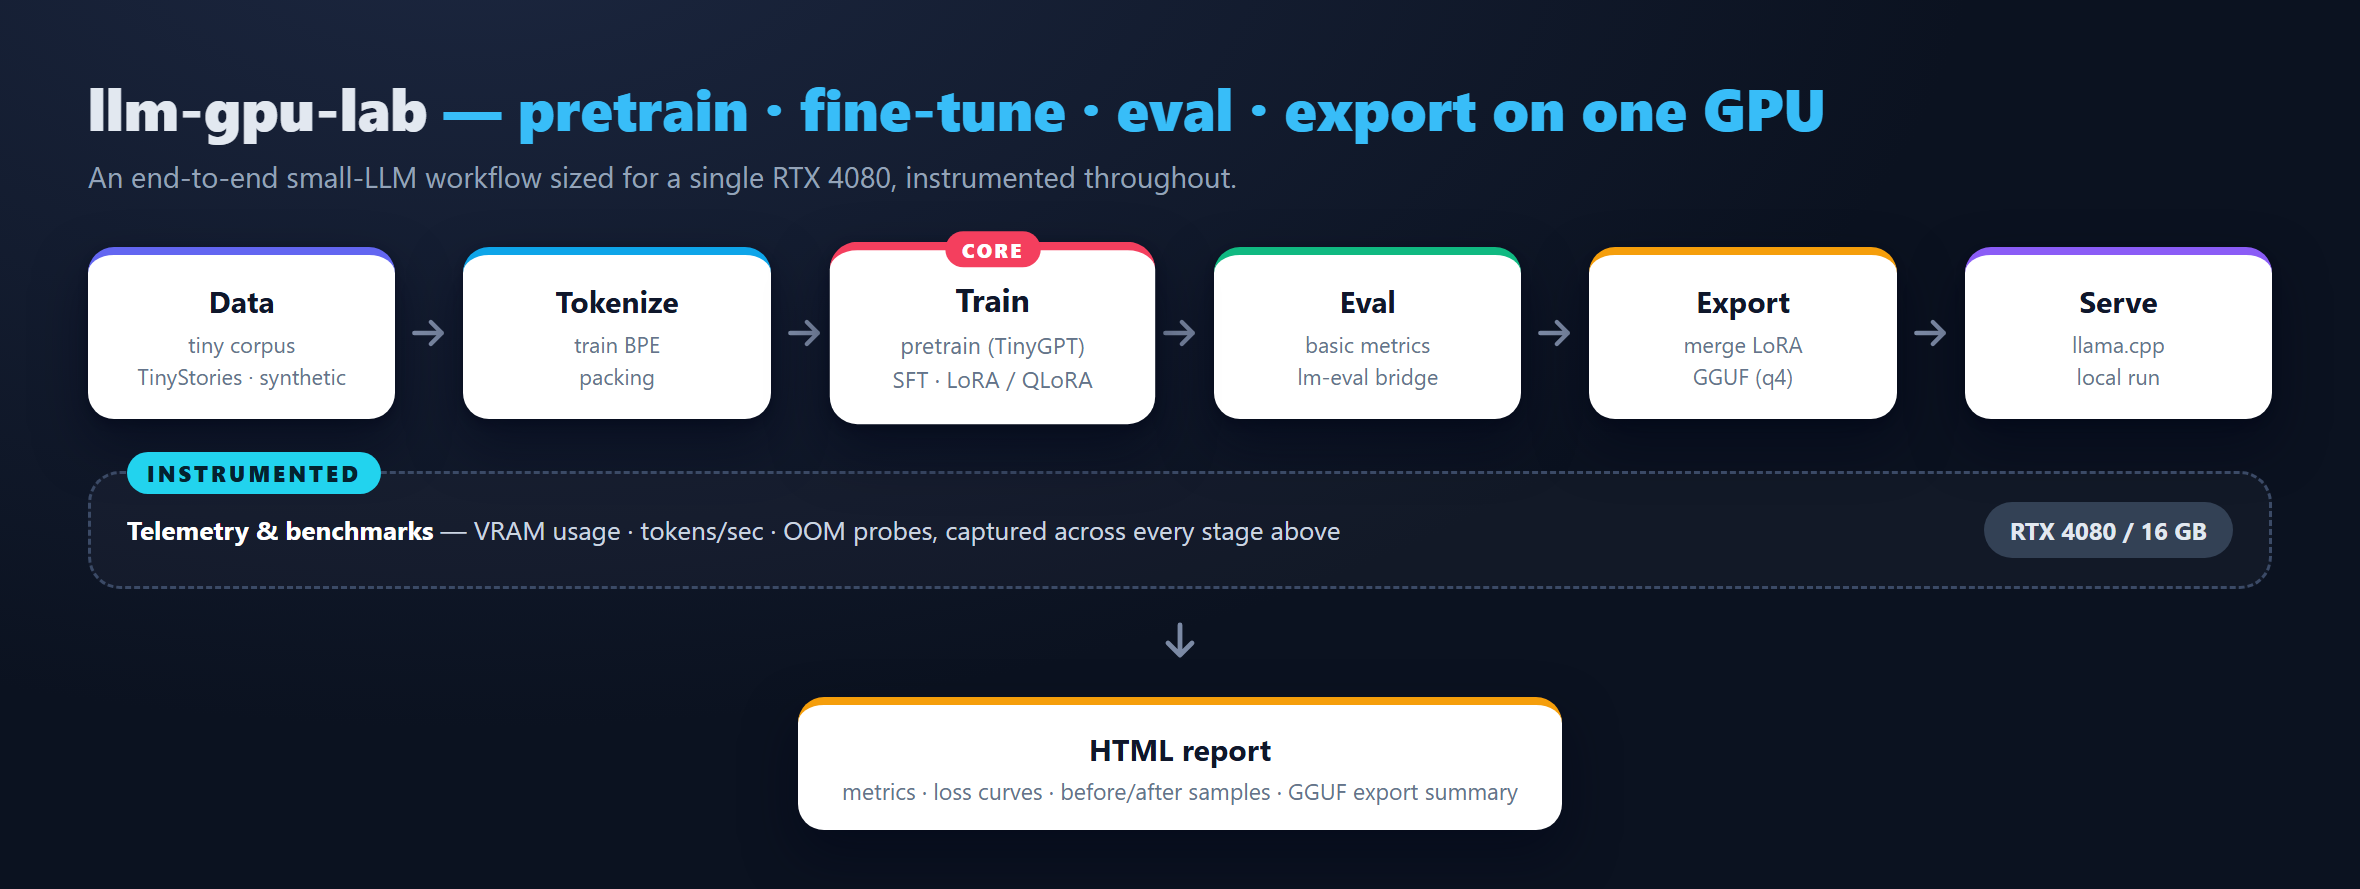
llm-gpu-lab
One GPU. Full LLM workflow. Real benchmarks. No cloud required.
- 36
- Python
- Apache-2.0
- 4 mo ago
xyntetik-runner
Local inference you can prove. A single-binary GGUF engine in C: serves, scores, and trains LoRA through the quantized weights it deploys, byte-reproducibly. Tool calls survive the token limit; every run replays as a signed receipt. CPU/CUDA/Metal, OpenAI- and Anthropic-compatible.
- 29
- C
- Apache-2.0
- 19 h ago

Mizan-27B-Turkish-Legal-LLM-mlx-4Bit
Image text to text model, used with mlx.
- 30
- 376
- cc-by-nc-4.0
- 4 mo ago
Parable-Qwen3-4B-Claude-Fable-5-GGUF
Text generation model, used with llama.cpp.
- 32
- 153k
- apache-2.0
- 4 mo ago
Qwen2.5-Coder-14B-n8n-Workflow-Generator
Text generation model, used with mlx.
- 25
- 3.4k
- apache-2.0
- 11 mo ago
Qwen3.6-27B-redteam-v5
- 19
- 1.9k
- apache-2.0
- 5 mo ago
genie-in-the-box
Genie in the Box: Distill Whisper STT => Mistral-7B => Phind/Phind-CodeLlama-34B-v2 => GPT 3.5 => Coqui's TTS/OpenAI TTS
- 15
- Jupyter Notebook
- AGPL-3.0
- 3 y ago

qwen-arabic-project
This project fine-tunes the Qwen2-1.5B model for Arabic language tasks using Quantized LoRA (QLoRA).
- 12
- Python
- GPL-3.0
- 19 mo ago


Parable-Granite-4.1-8B-Claude-Fable-5
Text generation model, used with transformers.
- 7
- 288
- apache-2.0
- 8 wk ago
LocalAIEngineeringWithOllamaCompanionToolkit
Companion Toolkit for "Local AI Engineering with Ollama"
- 3
- Python
- 5 mo ago

Parable-Granite-4.1-3B-Claude-Fable-5-GGUF
Text generation model, used with gguf.
- 6
- 116k
- apache-2.0
- 4 mo ago
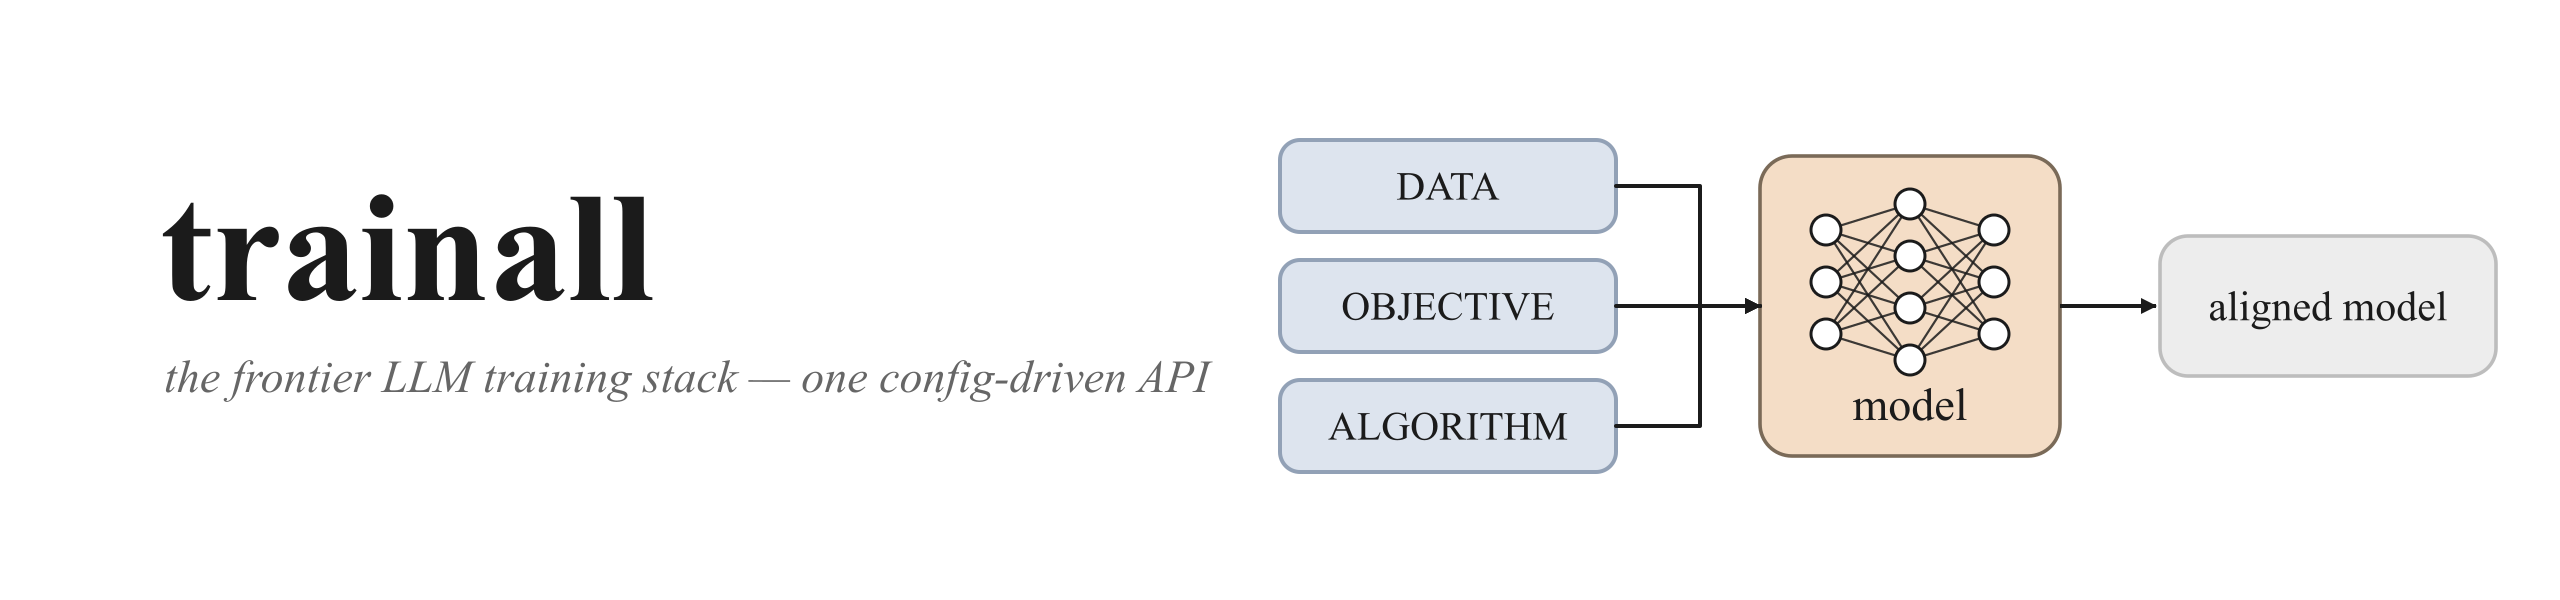
trainall
One library for the frontier LLM training stack — pre-training, CPT/DAPT, SFT, DPO/IPO/KTO/ORPO/SimPO/CPO, RLHF, RLVR+GRPO, agentic RL, distillation & self-play, LoRA/QLoRA — behind one config-driven, registry-based API. import trainall is torch-free.
- 2
- Python
- MIT
- 5 mo ago

Fine-Tuning Cost Calculator
What a LoRA, QLoRA or full fine-tune costs, live prices
Runs in the browser on Hugging Face
- 1
- mit
- 3 wk ago
WeightBake
Context Distillation via QLoRA SFT & DPO to eliminate 99.5% of system prompt bloat, shrink KV-cache by 15.3x, and accelerate vLLM TTFT latency by up to 17.5x
- 1
- Python
- Apache-2.0
- 4 d ago

LLM-QLoRA-Finetuning-with-Code
Large Language Model (LLM) fine-tuning repository focused on Quantized Low-Rank Adaptation (QLoRA) and memory-efficient training. Covers 4-bit quantization, NF4, Double Quantization, LoRA adapters, supervised fine-tuning, dataset preparation, and model evaluation using Python, PyTorch, Hugging Face PEFT, TRL, and BitsAndBytes.
- 1
- Jupyter Notebook
- MIT
- 4 d ago

All-LLM-Fine-Funing-Methods
End-to-end fine-tuning of Hugging Face models using LoRA, QLoRA, quantization, and PEFT techniques. Optimized for low-memory with efficient model deployment
- 1
- Jupyter Notebook
- MIT
- 3 wk ago
cxr-draft-auditor
Research/educational chest X-ray draft auditor: image-grounded findings vs draft impression, with a deterministic comparator. NOT a medical device.
- 1
- Python
- Apache-2.0
- 3 mo ago

analytics-copilot-text2sql
Analytics Copilot (Text-to-SQL) is an end-to-end LLM engineering project that builds a production-style Natural Language → SQL assistant. It fine-tunes Mistral-7B-Instruct using QLoRA/LoRA adapters on the b-mc2/sql-create-context dataset, trains with a clean instruction-tuning prompt format, and ships a complete evaluation + deployment workflow.
- 1
- Jupyter Notebook
- MIT
- 4 mo ago

Qwen3-VL ChartQA|圖表理解工作台
Qwen3-VL 8B 圖表理解微調、量化與 serving 實證作品
Runs in the browser on Hugging Face
- 0
- mit
- 2 mo ago
behavior-tune
QLoRA post-training and evaluation for Qwen3-4B, with a public adapter, dataset, matched evaluation, CLI/API, and reproducible tooling.
- 0
- Python
- 3 mo ago
