mae


ViTPose
The official repo for [NeurIPS'22] "ViTPose: Simple Vision Transformer Baselines for Human Pose Estimation" and [TPAMI'23] "ViTPose++: Vision Transformer for Generic Body Pose Estimation"
- 2.2k
- Python
- Apache-2.0
- 11 mo ago

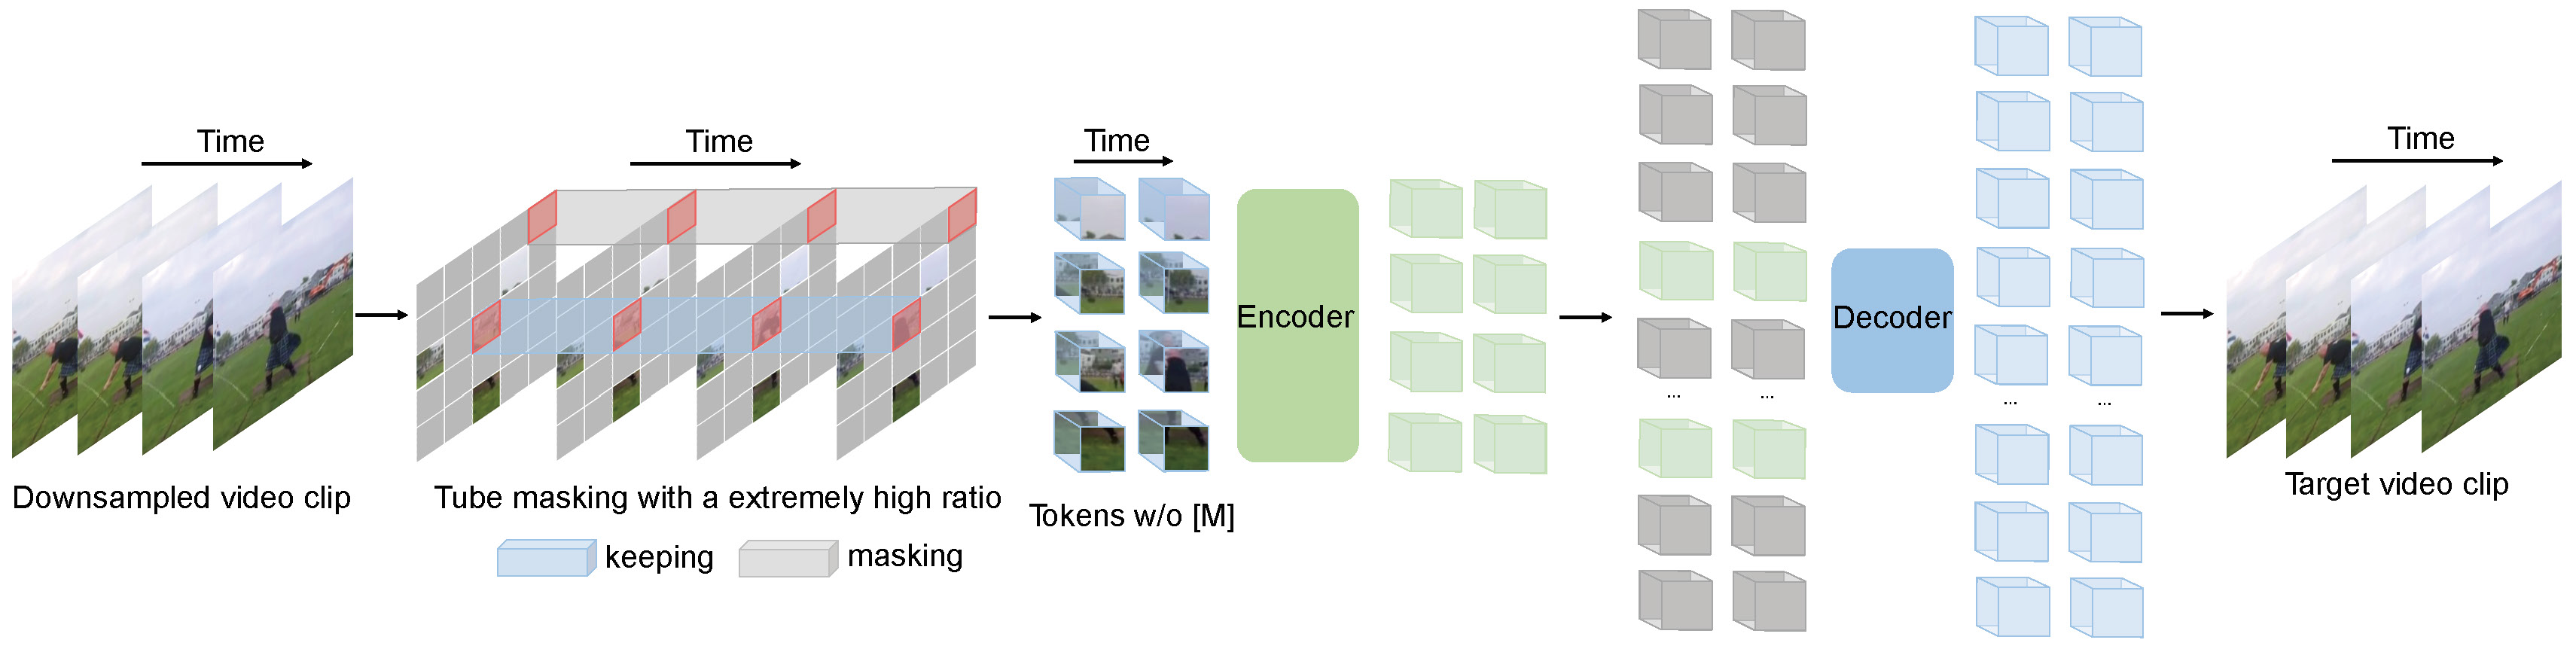
VideoMAE
[NeurIPS 2022 Spotlight] VideoMAE: Masked Autoencoders are Data-Efficient Learners for Self-Supervised Video Pre-Training
- 1.8k
- Python
- 3 y ago

awesome-vision-models
Vision Foundation Models: SAM, ViT, CLIP, DINOv2, object detection, segmentation, and multimodal AI for computer vision.
- 29
- Makefile
- MIT
- 12 mo ago
