InternVideo
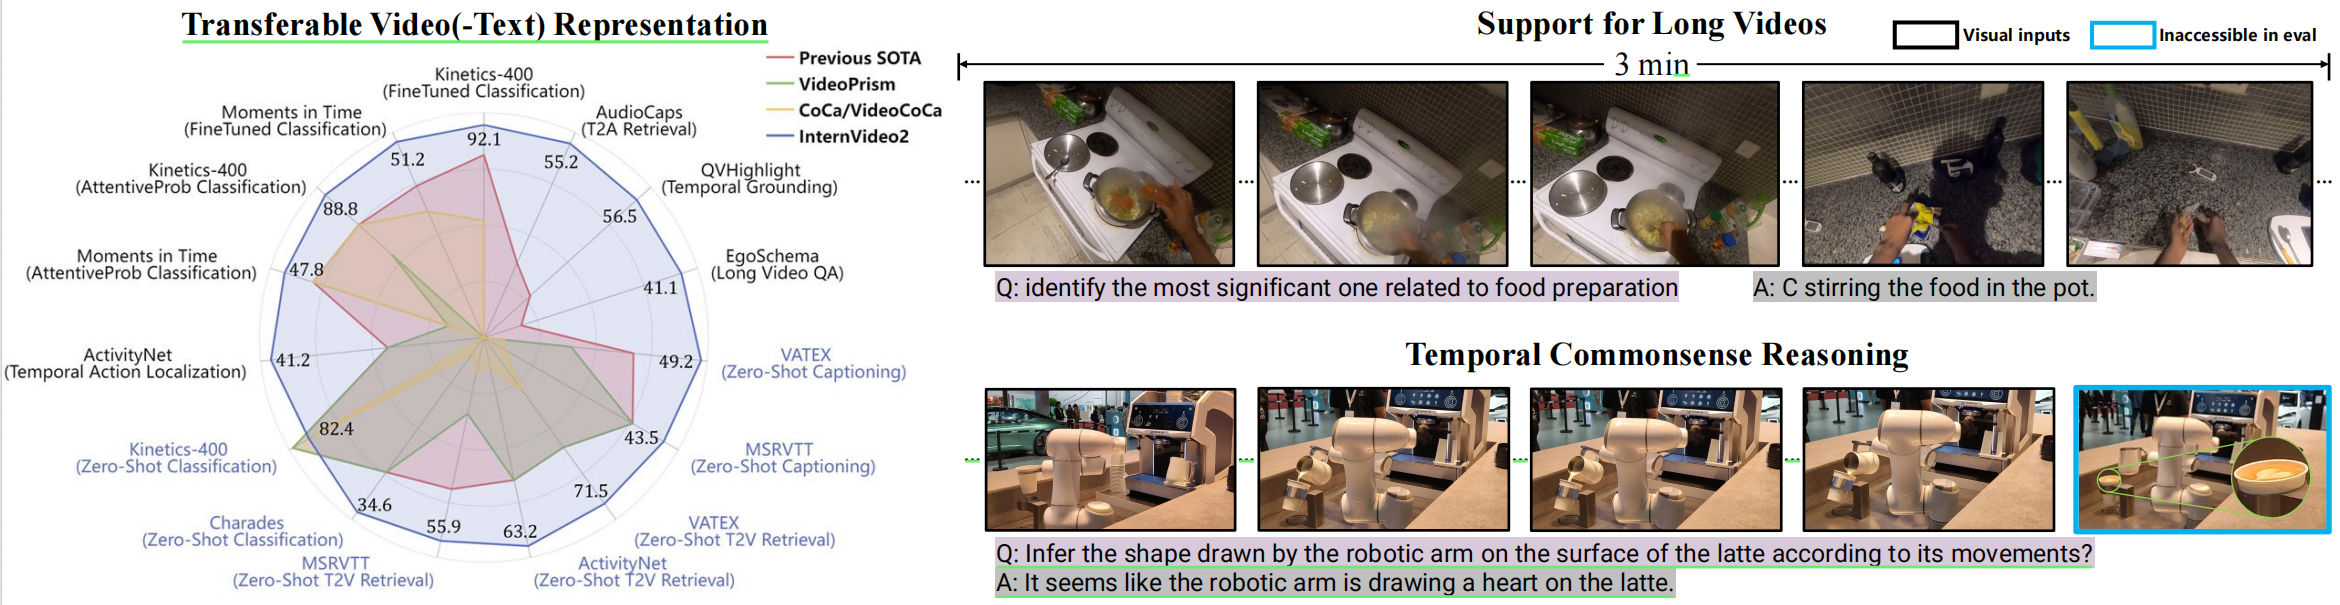
[ECCV2024] Video Foundation Models & Data for Multimodal Understanding
- 2.4k
- Python
- Apache-2.0
- 5 mo ago
[ECCV2024] Video Foundation Models & Data for Multimodal Understanding
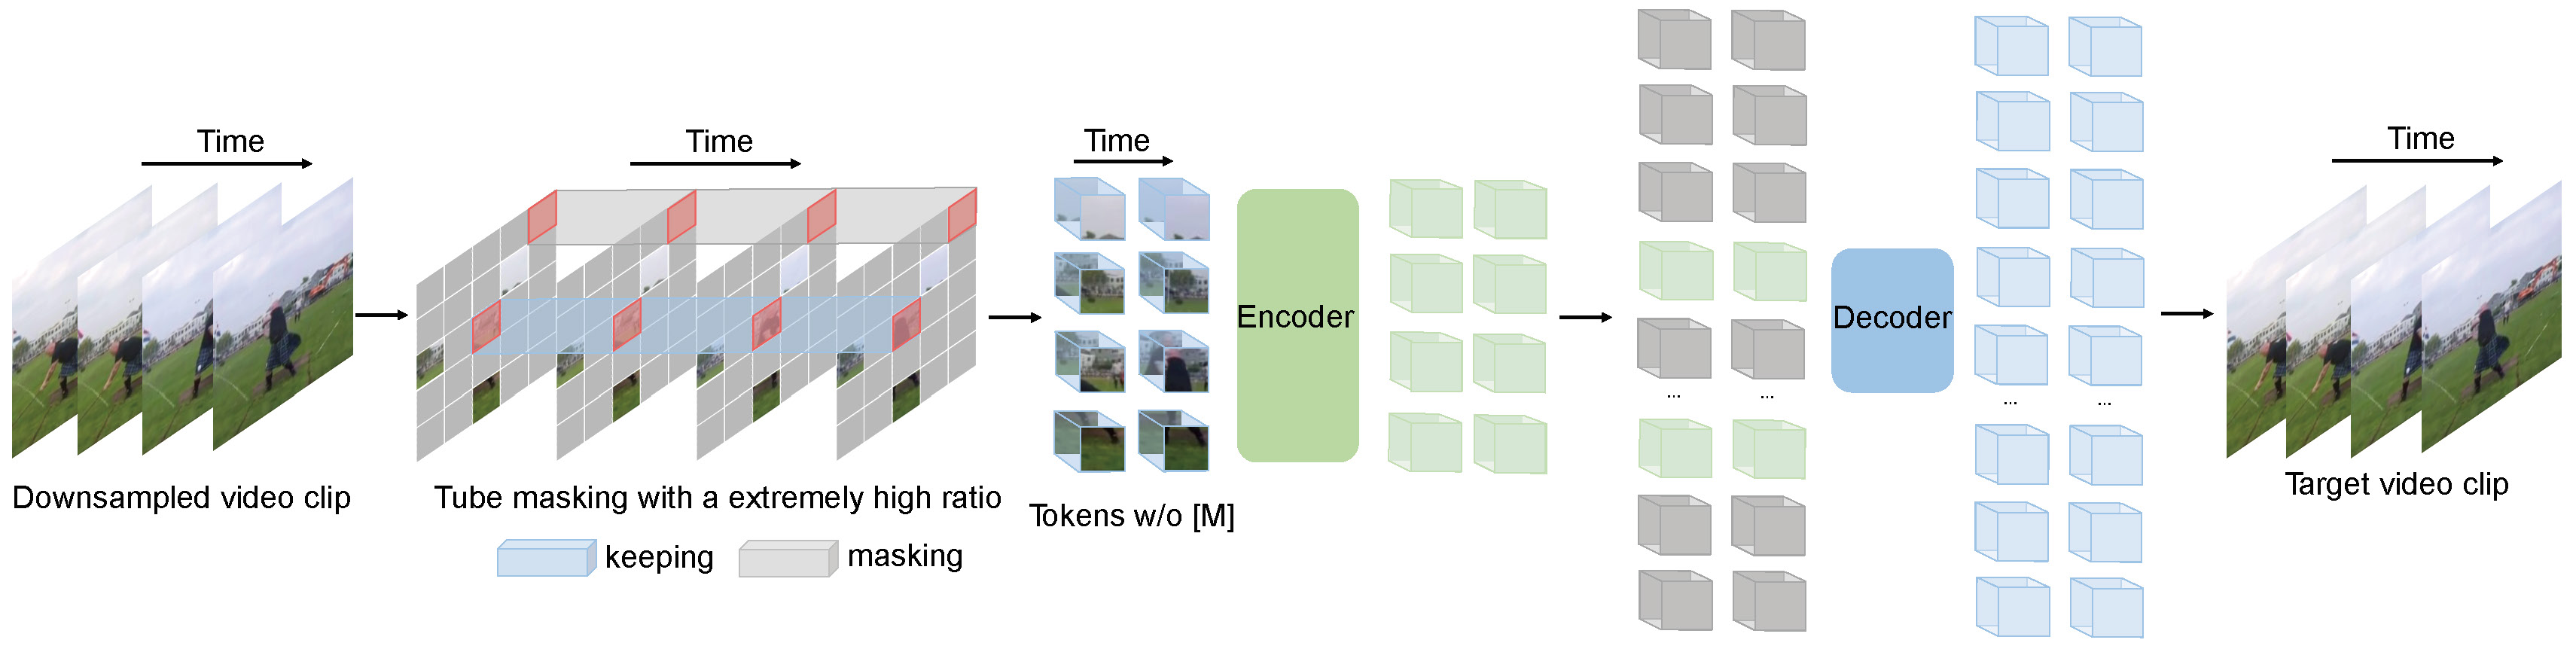
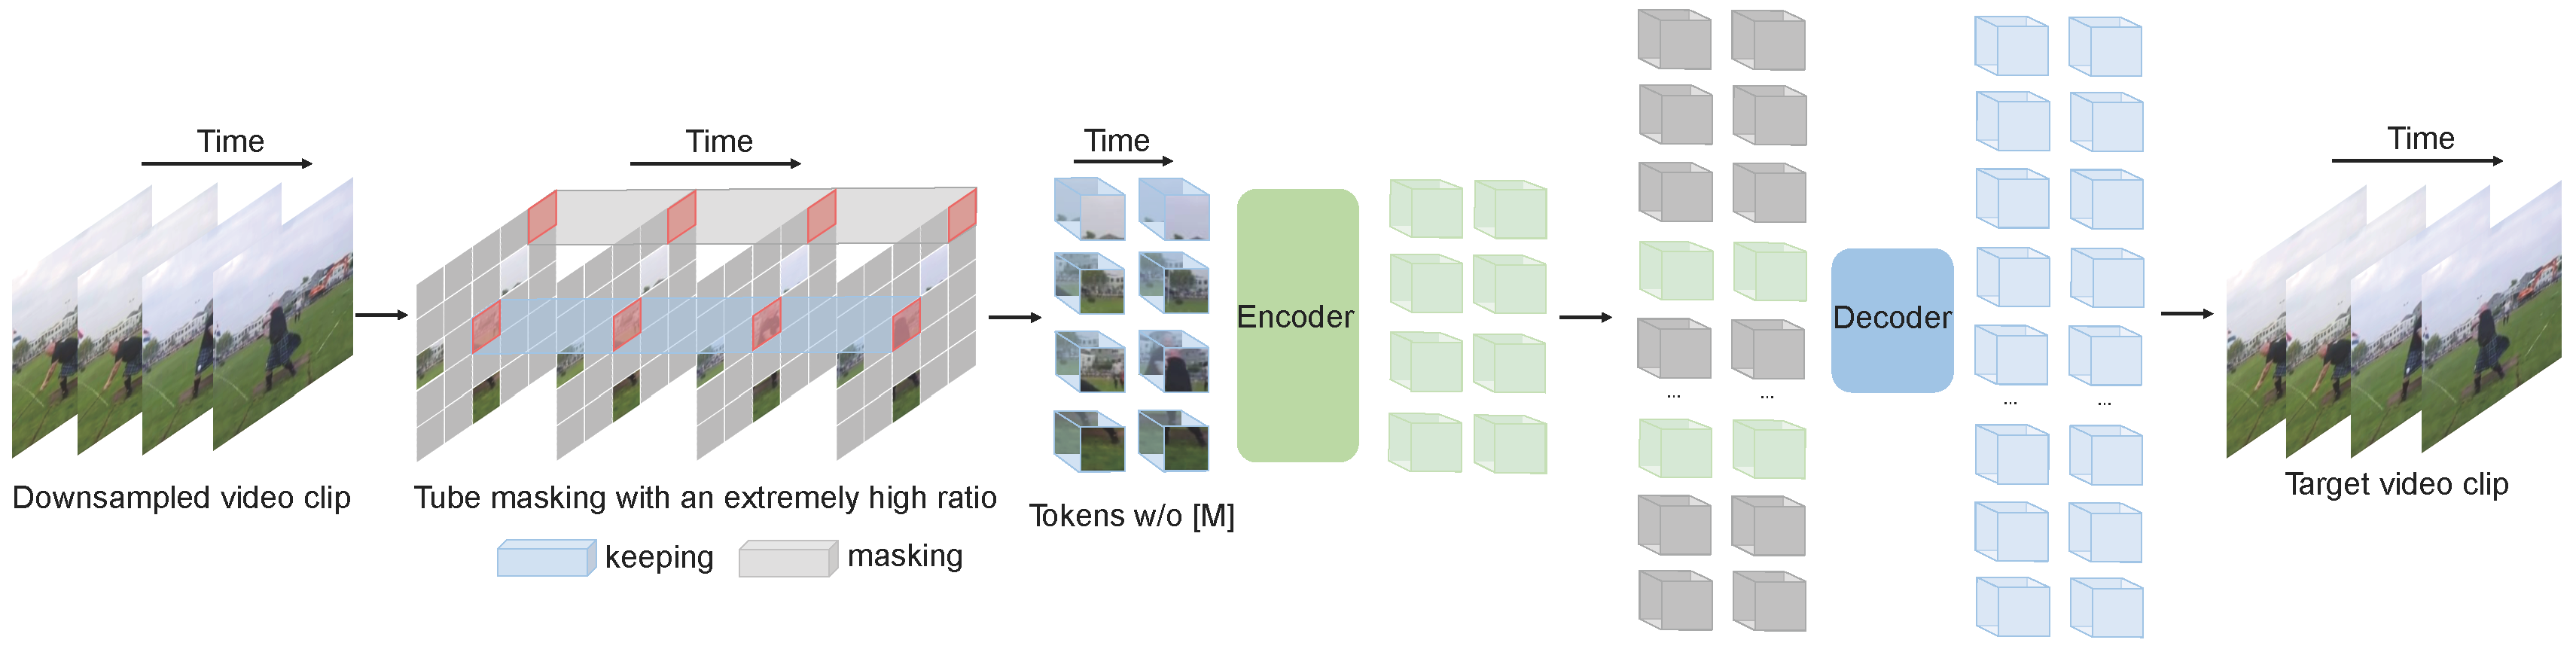
[NeurIPS 2022 Spotlight] VideoMAE: Masked Autoencoders are Data-Efficient Learners for Self-Supervised Video Pre-Training
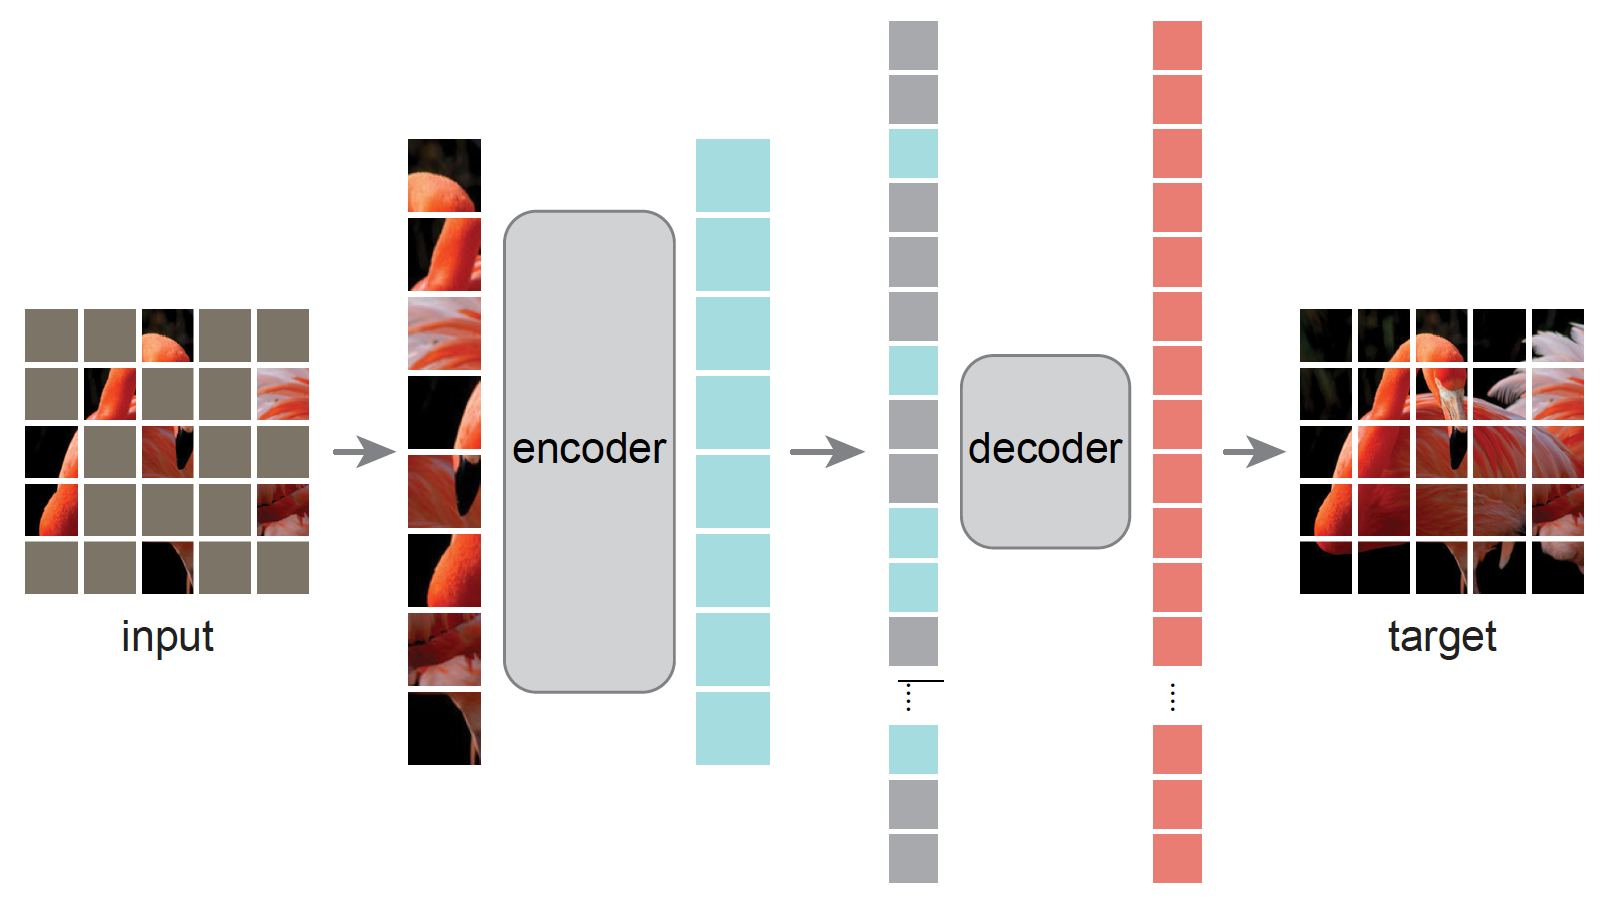
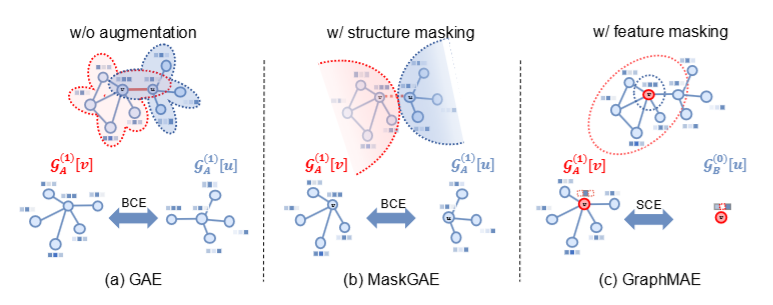
A collection of literature after or concurrent with Masked Autoencoder (MAE) (Kaiming He el al.).
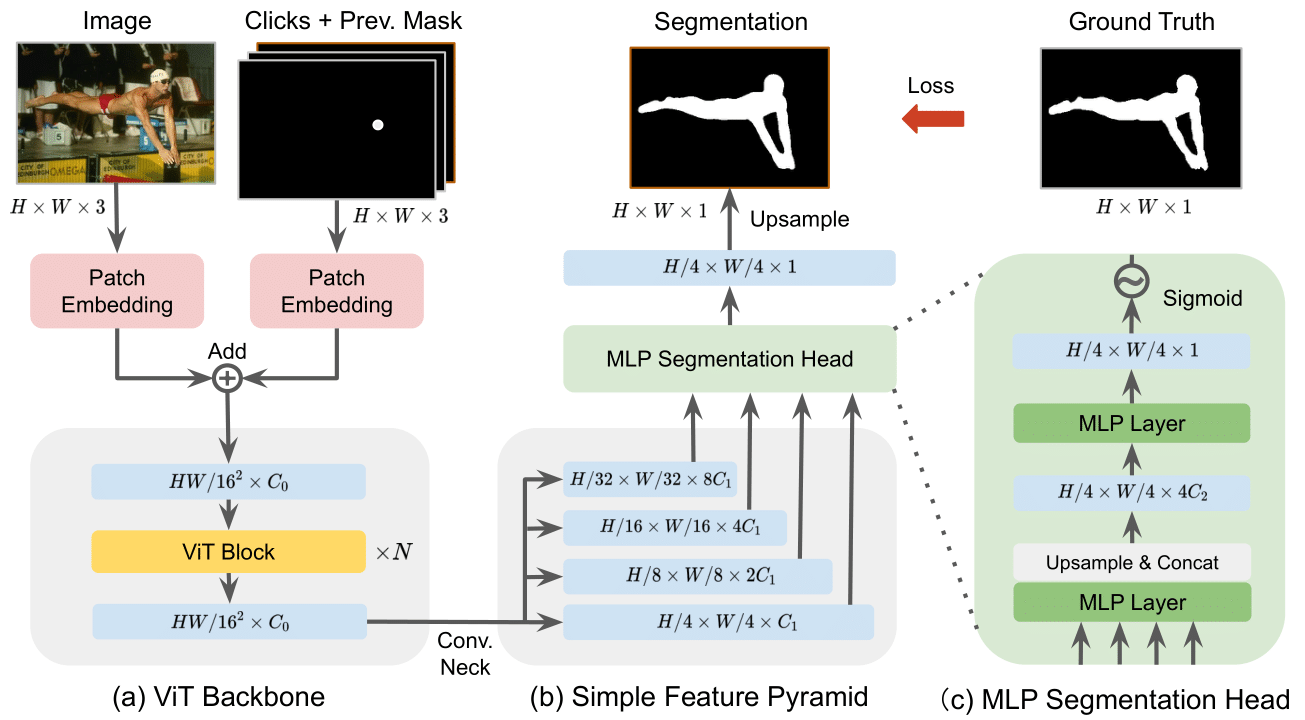
SimpleClick: Interactive Image Segmentation with Simple Vision Transformers (ICCV 2023)
[ECCV 2024] Pytorch code for our ECCV'24 paper NeRF-MAE: Masked AutoEncoders for Self-Supervised 3D Representation Learning for Neural Radiance Fields
Codebase for the paper 'EncodecMAE: Leveraging neural codecs for universal audio representation learning'
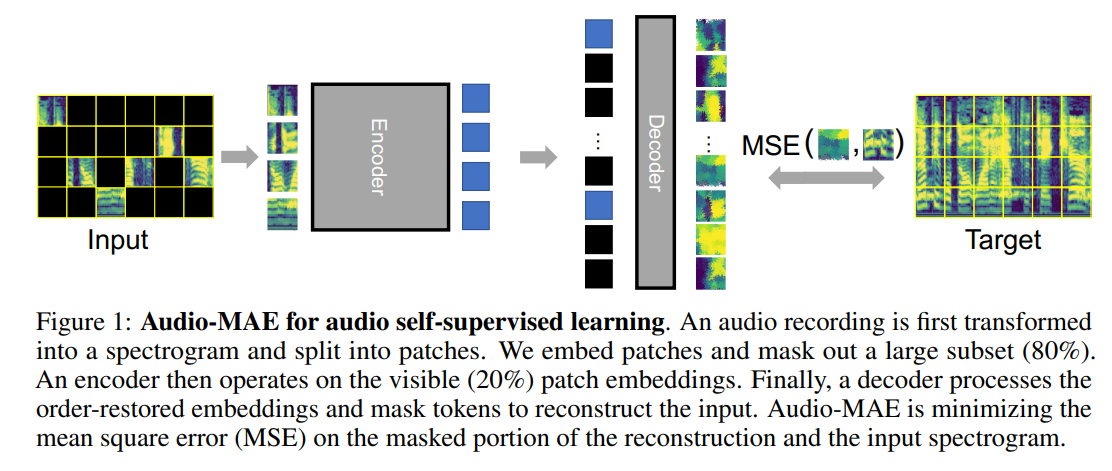
Unofficial PyTorch implementation of Masked Autoencoders that Listen
[ICML 2023] Architecture-Agnostic Masked Image Modeling -- From ViT back to CNN
[WACV'25] Official implementation of "PK-YOLO: Pretrained Knowledge Guided YOLO for Brain Tumor Detection in Multiplane MRI Slices".