mixed-precision
Qwen3.8-Flash-Next-GSQ-RCO-Coder-GGUF
Image text to text model, used with gguf.
- 655
- 854k
- apache-2.0
- 5 wk ago
OrcaSAQ-2-Cyber-27B-Uncensored-GGUF
Text generation model, used with llama.cpp.
Gated access
- 639
- 11k
- apache-2.0
- 10 d ago
DeepSeek-V4.1-Flash-1017-abliterated-GGUF
Text generation model, used with gguf.
Gated access
- 554
- 117k
- mit
- 9 d ago
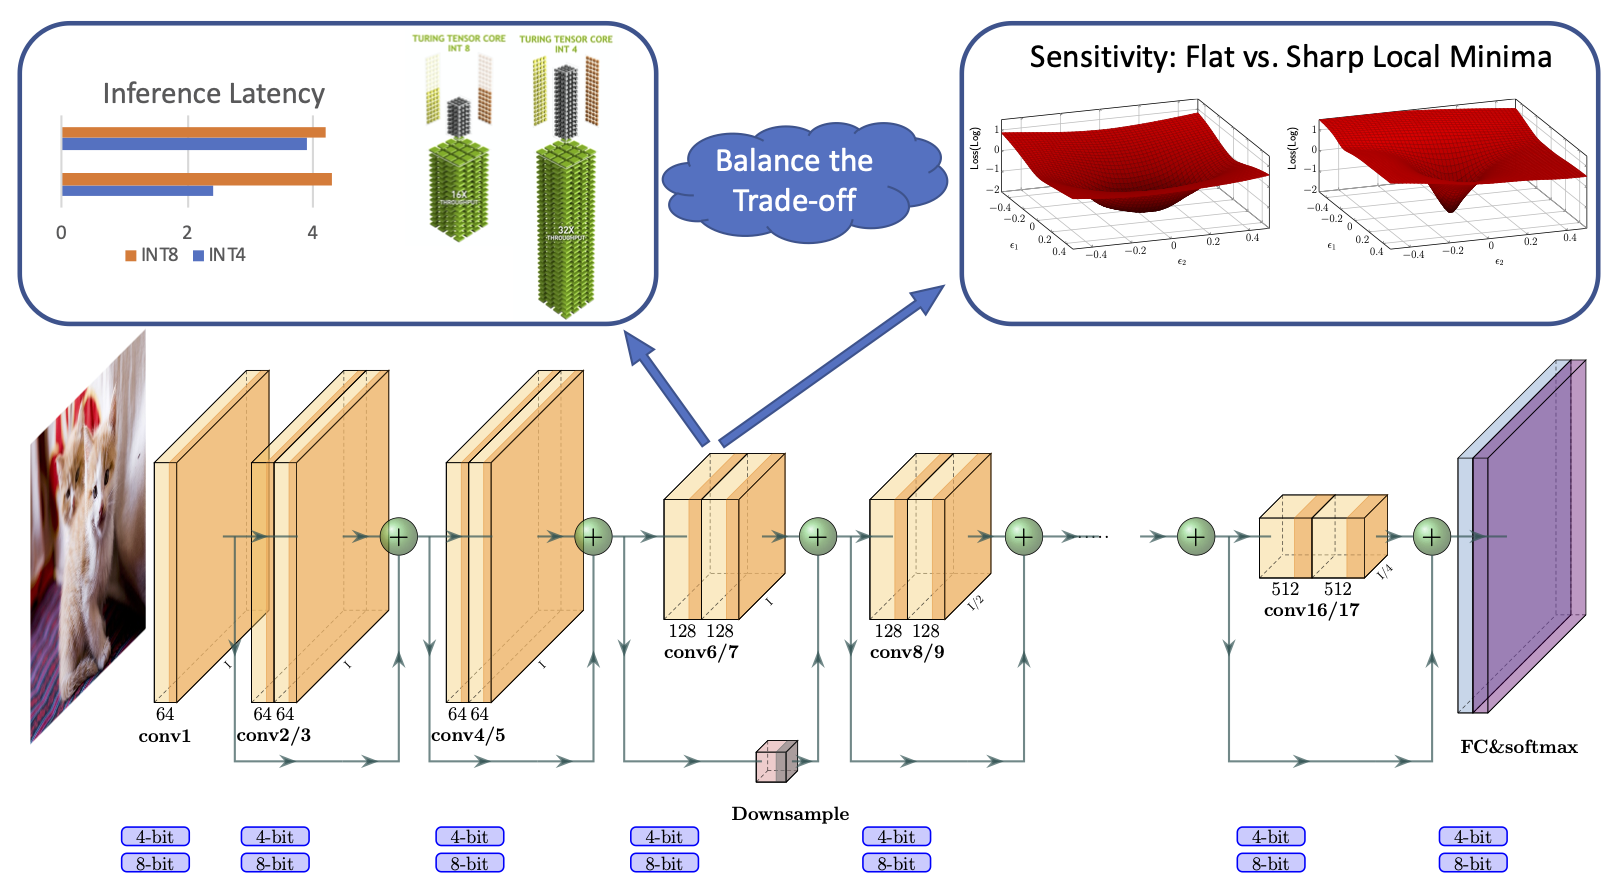
HAWQ
Quantization library for PyTorch. Support low-precision and mixed-precision quantization, with hardware implementation through TVM.
- 467
- Python
- MIT
- 4 y ago


haq
[CVPR 2019, Oral] HAQ: Hardware-Aware Automated Quantization with Mixed Precision
- 411
- Python
- MIT
- 6 y ago

Qwen3.8-27B-Uncensored-NVFP4
Image text to text model, used with transformers.
Gated access
- 388
- 26k
- apache-2.0
- 4 wk ago
DeepSeek-V4.1-Flash-1017-GSQ-RCO-Coder-GGUF
Image text to text model, used with gguf.
- 247
- 525k
- mit
- 3 wk ago
Huihui-DeepSeek-V4.1-Flash-1017-abliterated-GGUF
Image text to text model, used with transformers.
- 234
- 137k
- mit
- 13 d ago
Qwen3.8-27B-EfficientThink-Uncensored-K3-Opus5-Grok4.6-GPT5.6Sol-SFT-SimPO-DFlash2-GGUF
- 124
- 44k
- apache-2.0
- 2 mo ago
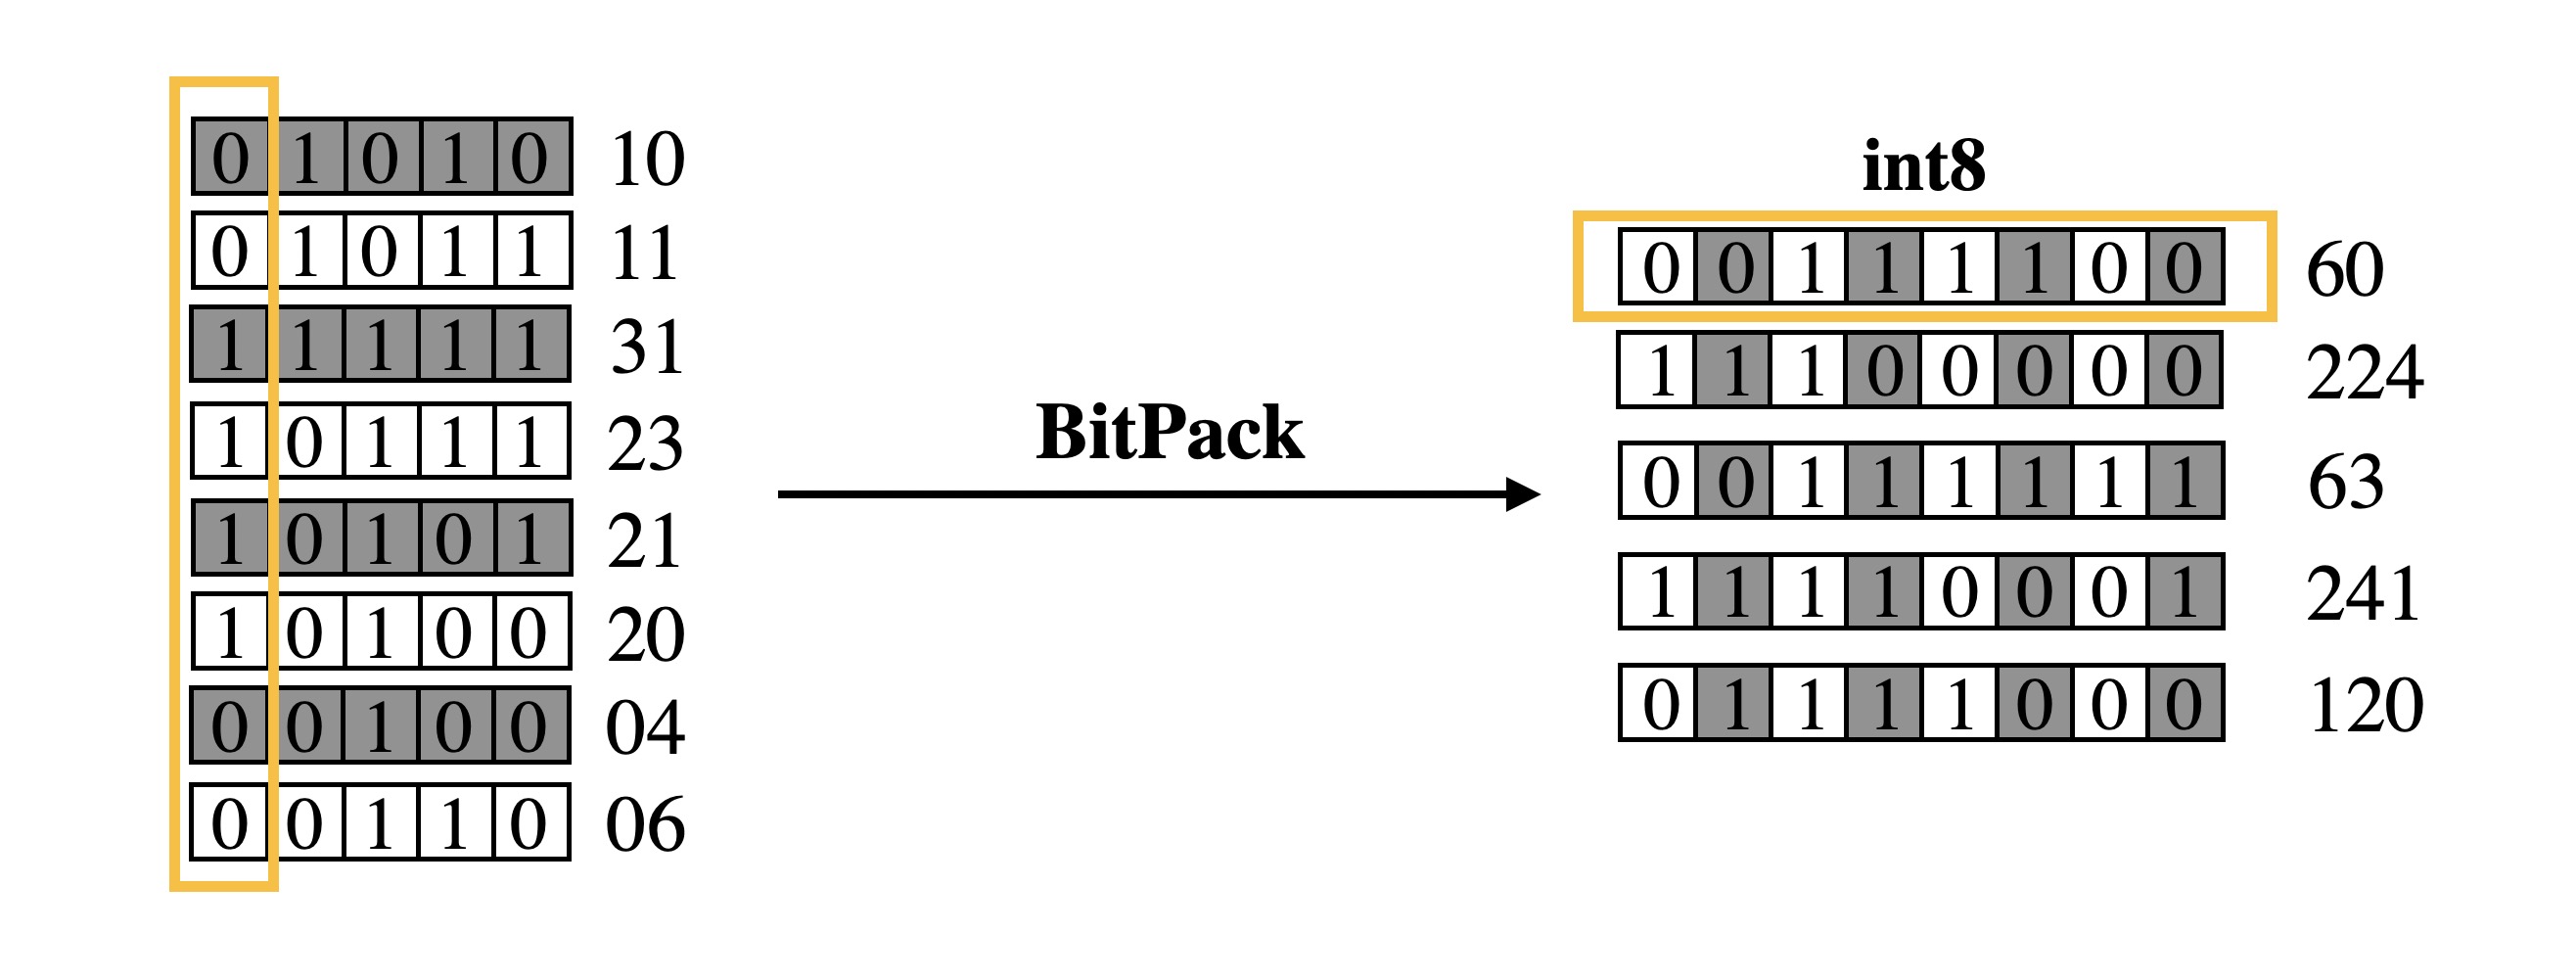
BitPack
BitPack is a practical tool to efficiently save ultra-low precision/mixed-precision quantized models.
- 58
- Python
- MIT
- 4 y ago
DeepSeek-V4.1-Flash-1017-XQ-Uncensored
- 62
- 27k
- mit
- 13 d ago
SuperDeepseek-V4-Flash-abliterated-MQ-2xDGX
Text generation model, used with transformers.
- 70
- 707
- mit
- 3 mo ago

quadbit
The only deployed sparse FP4 GEMM on SM120: beats CUTLASS 80b on every shape, wins end-to-end request latency in 81 of 112 serving regimes vs dense NVFP4.
- 3
- Python
- MIT
- 2 wk ago

ComfyUI-Qwen-V100-MixedPrecision
V100-optimized mixed precision for Qwen Image in ComfyUI — 1.43x faster sampling on NVIDIA Tesla V100 32GB (Volta/sm_70).
- 3
- Python
- 11 d ago

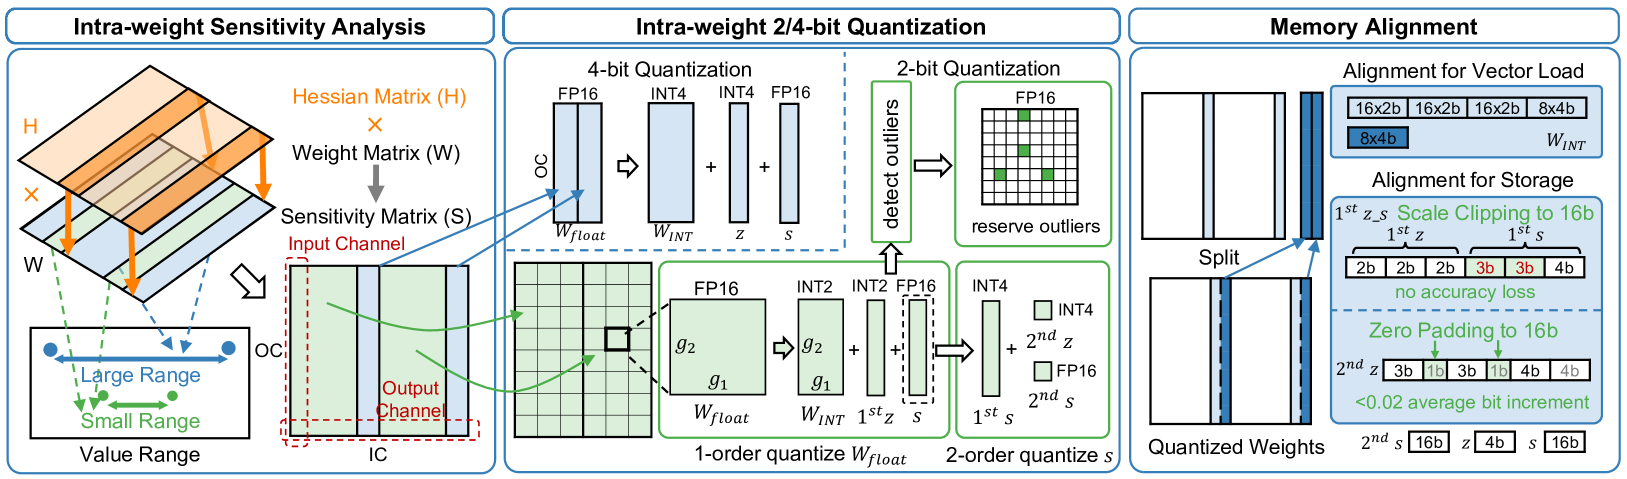
memboost
CUDA mixed-precision 2/4-bit weight quantizer for LLMs (reimplements arXiv:2311.16442)
- 1
- Python
- 8 wk ago

mtl5
C++ header-only linear algebra library for mixed-precision algorithm design and optimization
- 1
- C++
- MIT
- 2 d ago

comfyui-native-quantizer
Native mixed-precision quantization for ComfyUI models and text encoders W4A8, W4A4, INT8, FP8, streaming conversion, architecture-aware policies, and validation.
- 2
- Python
- Apache-2.0
- 3 wk ago

ramp-quant
RAMP: RL-guided Adaptive Mixed-Precision quantization for GGUF models. Data-free sensitivity analysis, evolutionary search, per-tensor type optimization. Produces hardware-optimized GGUF for consumer GPUs.
- 1
- Python
- Apache-2.0
- 7 mo ago

gsq-rocm
GSQ (Gumbel-Softmax Quantization) ported to AMD ROCm: gfx1200/gfx1201 (RDNA4) and gfx115x (RDNA3.5 APUs)
- 0
- Python
- Apache-2.0
- 3 wk ago

TensorFlow_Python_Code_Generation
Fine-tuning CodeT5 for Python code generation on the MBPP dataset. Features custom TensorFlow training loops, mixed precision, XLA optimization, and distributed multi-GPU strategies.
- 0
- Jupyter Notebook
- MIT
- 20 mo ago
