Torch-Pruning
[CVPR 2023] DepGraph: Towards Any Structural Pruning; LLMs, Vision Foundation Models, etc.
- 3.4k
- Python
- MIT
- 5 d ago
[CVPR 2023] DepGraph: Towards Any Structural Pruning; LLMs, Vision Foundation Models, etc.
Efficient AI Backbones including GhostNet, TNT and MLP, developed by Huawei Noah's Ark Lab.
Pretrained language model and its related optimization techniques developed by Huawei Noah's Ark Lab.
micronet, a model compression and deploy lib. compression: 1、quantization: quantization-aware-training(QAT), High-Bit(>2b)(DoReFa/Quantization and Training of Neural Networks for Efficient Integer-Arithmetic-Only Inference)、Low-Bit(≤2b)/Ternary and Binary(TWN/BNN/XNOR-Net); post-training-quantization(PTQ), 8-bit(tensorrt); 2、 pruning: normal、regular and group convolutional channel pruning; 3、 grou
A toolkit to optimize ML models for deployment for Keras and TensorFlow, including quantization and pruning.
List of papers related to neural network quantization in recent AI conferences and journals.
Accelerate your Neural Architecture Search (NAS) through fast, reproducible and modular research.
A list of high-quality (newest) AutoML works and lightweight models including 1.) Neural Architecture Search, 2.) Lightweight Structures, 3.) Model Compression, Quantization and Acceleration, 4.) Hyperparameter Optimization, 5.) Automated Feature Engineering.
Quantization library for PyTorch. Support low-precision and mixed-precision quantization, with hardware implementation through TVM.
Infrastructures™ for Machine Learning Training/Inference in Production.
a collection of computer vision projects&tools. 计算机视觉方向项目和工具集合。
[EMNLP 2026] 📚 A curated list of Awesome Efficient dLLMs Papers with Codes
🤖 An automated machine learning framework for audio, text, image, video, or .CSV files (50+ featurizers and 15+ model trainers). Python 3.6 required.
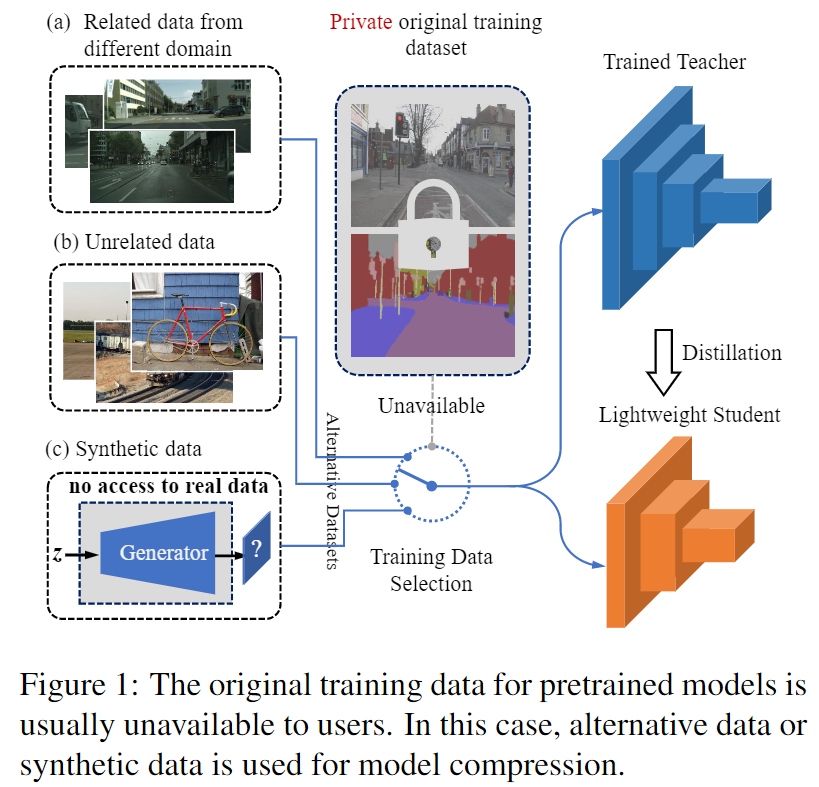
Code and pretrained models for paper: Data-Free Adversarial Distillation
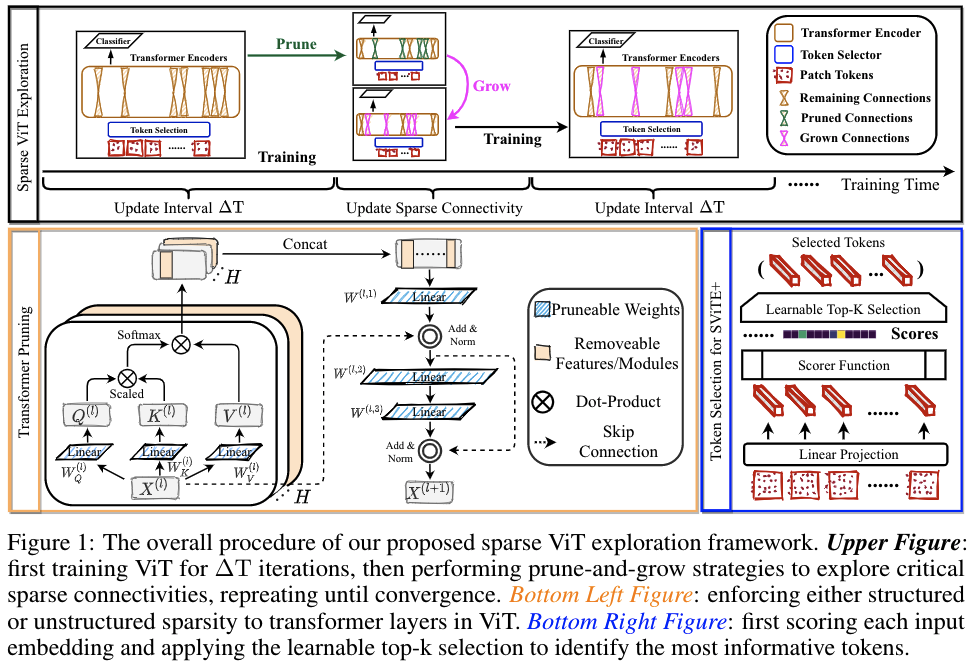
[NeurIPS'21] "Chasing Sparsity in Vision Transformers: An End-to-End Exploration" by Tianlong Chen, Yu Cheng, Zhe Gan, Lu Yuan, Lei Zhang, Zhangyang Wang
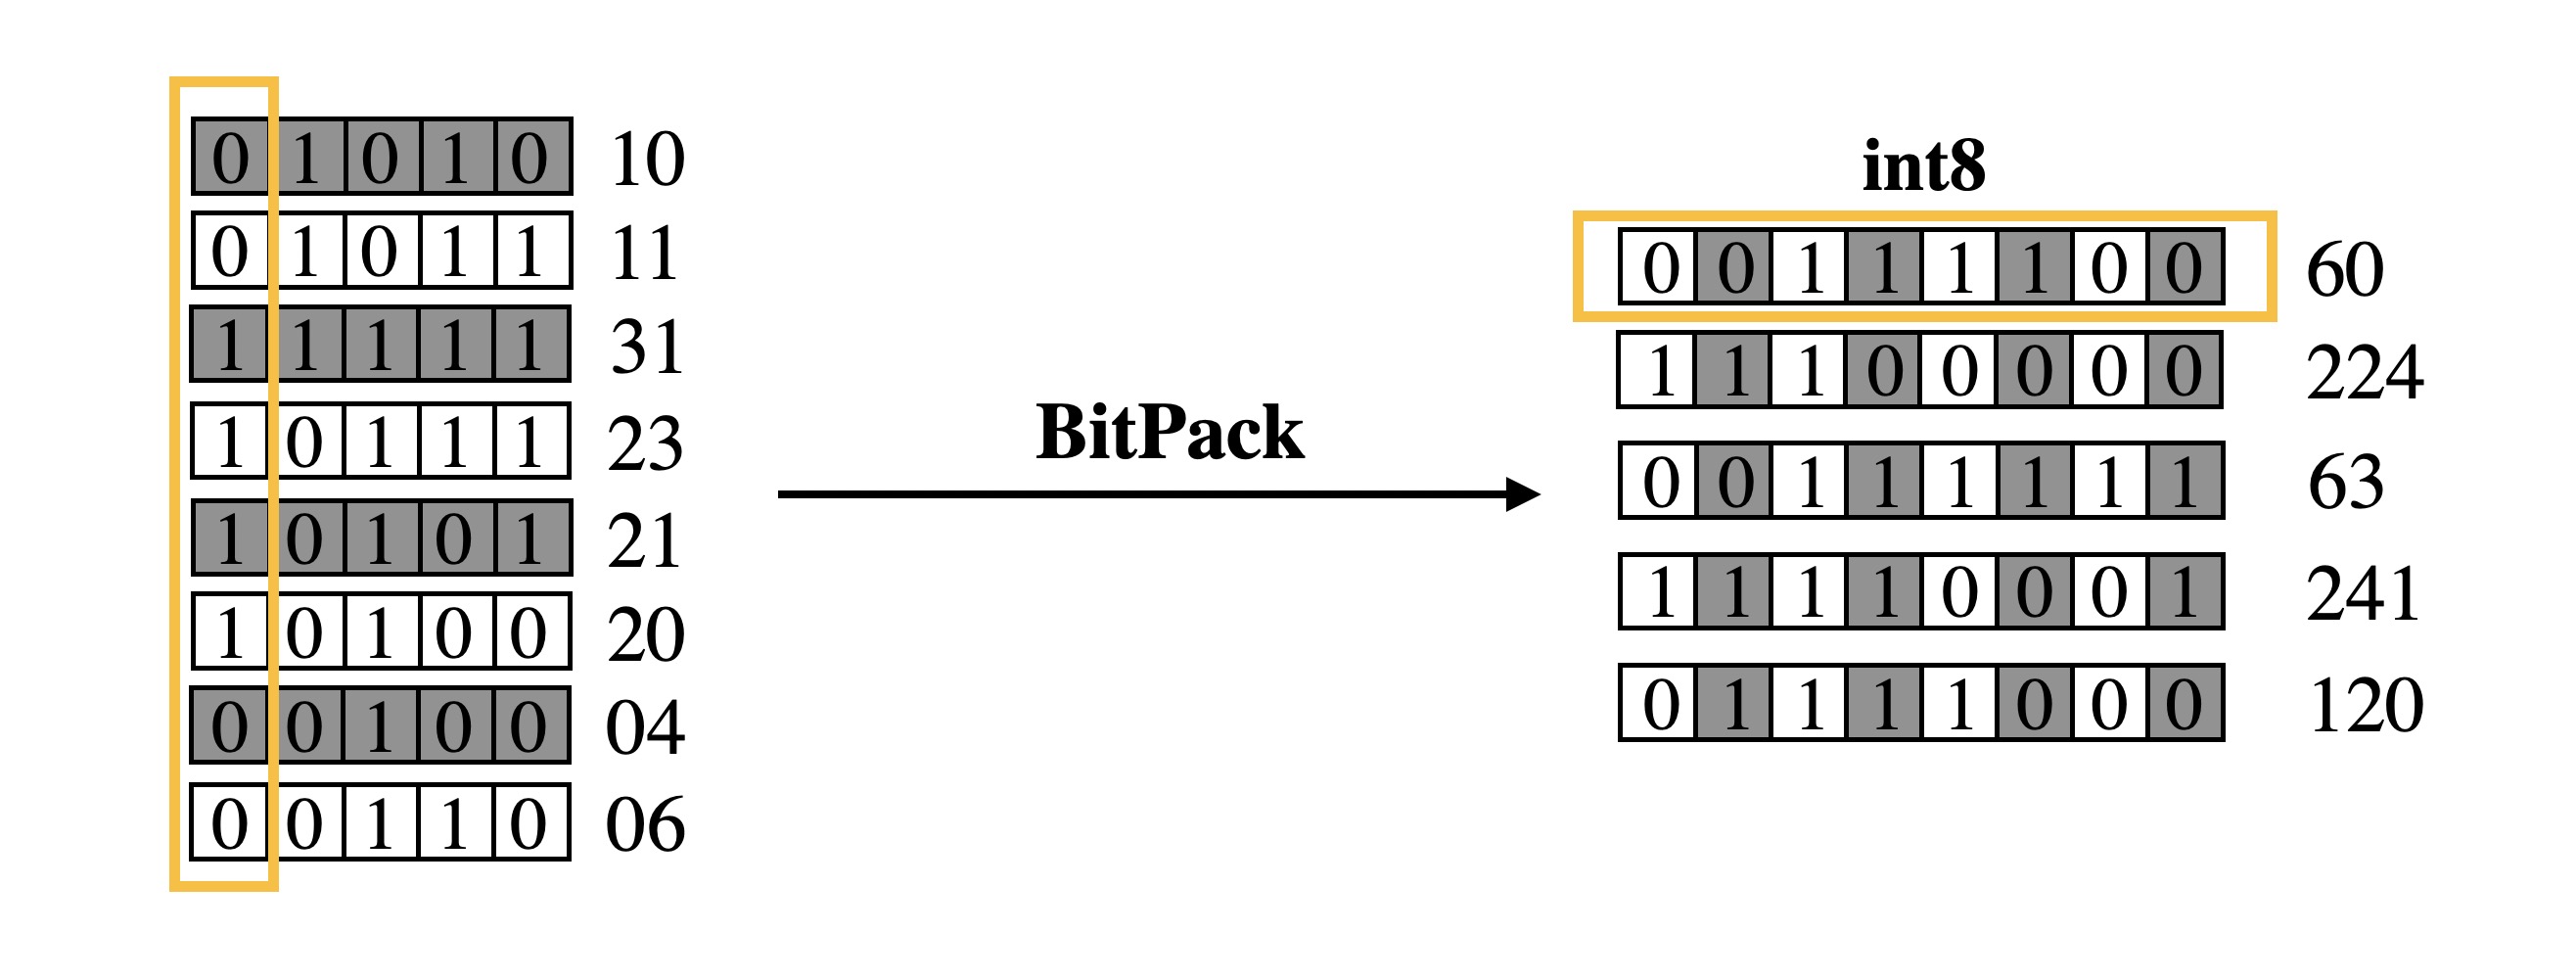
BitPack is a practical tool to efficiently save ultra-low precision/mixed-precision quantized models.
The Codebase for Causal Distillation for Language Models (NAACL '22)
Dive into advanced quantization techniques. Learn to implement and customize linear quantization functions, measure quantization error, and compress model weights using PyTorch for efficient and accessible AI models.
Learn linear quantization techniques using the Quanto library and downcasting methods with the Transformers library to compress and optimize generative AI models effectively.
Pre-quantized ternary models for VLMs, multimodal, and audio — the models GGUF can't touch