mlx-lm

Open repos and models their makers tagged mlx-lm, most starred first. The same for everyone.

AI agentsRepo

Rapid-MLX

Rapid-MLX is an open-source (Apache 2.0) OpenAI- and Anthropic-compatible LLM inference server for Apple Silicon, built on MLX, focused on reliable tool calling for coding agents. Up to 4× faster than Apple's MLX (mlx-lm) on the same weights.

  • 4.2k
  • Python
  • Apache-2.0
  • 3 h ago
raullenchaiTake it
Voice and audioRepo

mlx-openai-server

A high-performance API server that provides OpenAI-compatible endpoints for MLX models. Developed using Python and powered by the FastAPI framework, it provides an efficient, scalable, and user-friendly solution for running MLX-based vision and language models locally with an OpenAI-compatible interface.

  • 363
  • Python
  • MIT
  • 6 d ago
cubist38Take it
AI on my own machineRepo

Mac-MLX

macMLX brings local LLM inference to Apple Silicon with a first-class native macOS experience. No cloud, no telemetry, no Electron — just your Mac running models at full speed.

  • 86
  • Swift
  • 5 d ago
magicnightTake it
AI on my own machineRepo

VeloxQuant-MLX

Fast KV-cache quantization for Apple Silicon (MLX) — 43 research-adapted compression methods with Metal kernels

  • 36
  • Python
  • MIT
  • 9 h ago
rajveer43Take it
AI on my own machineRepo

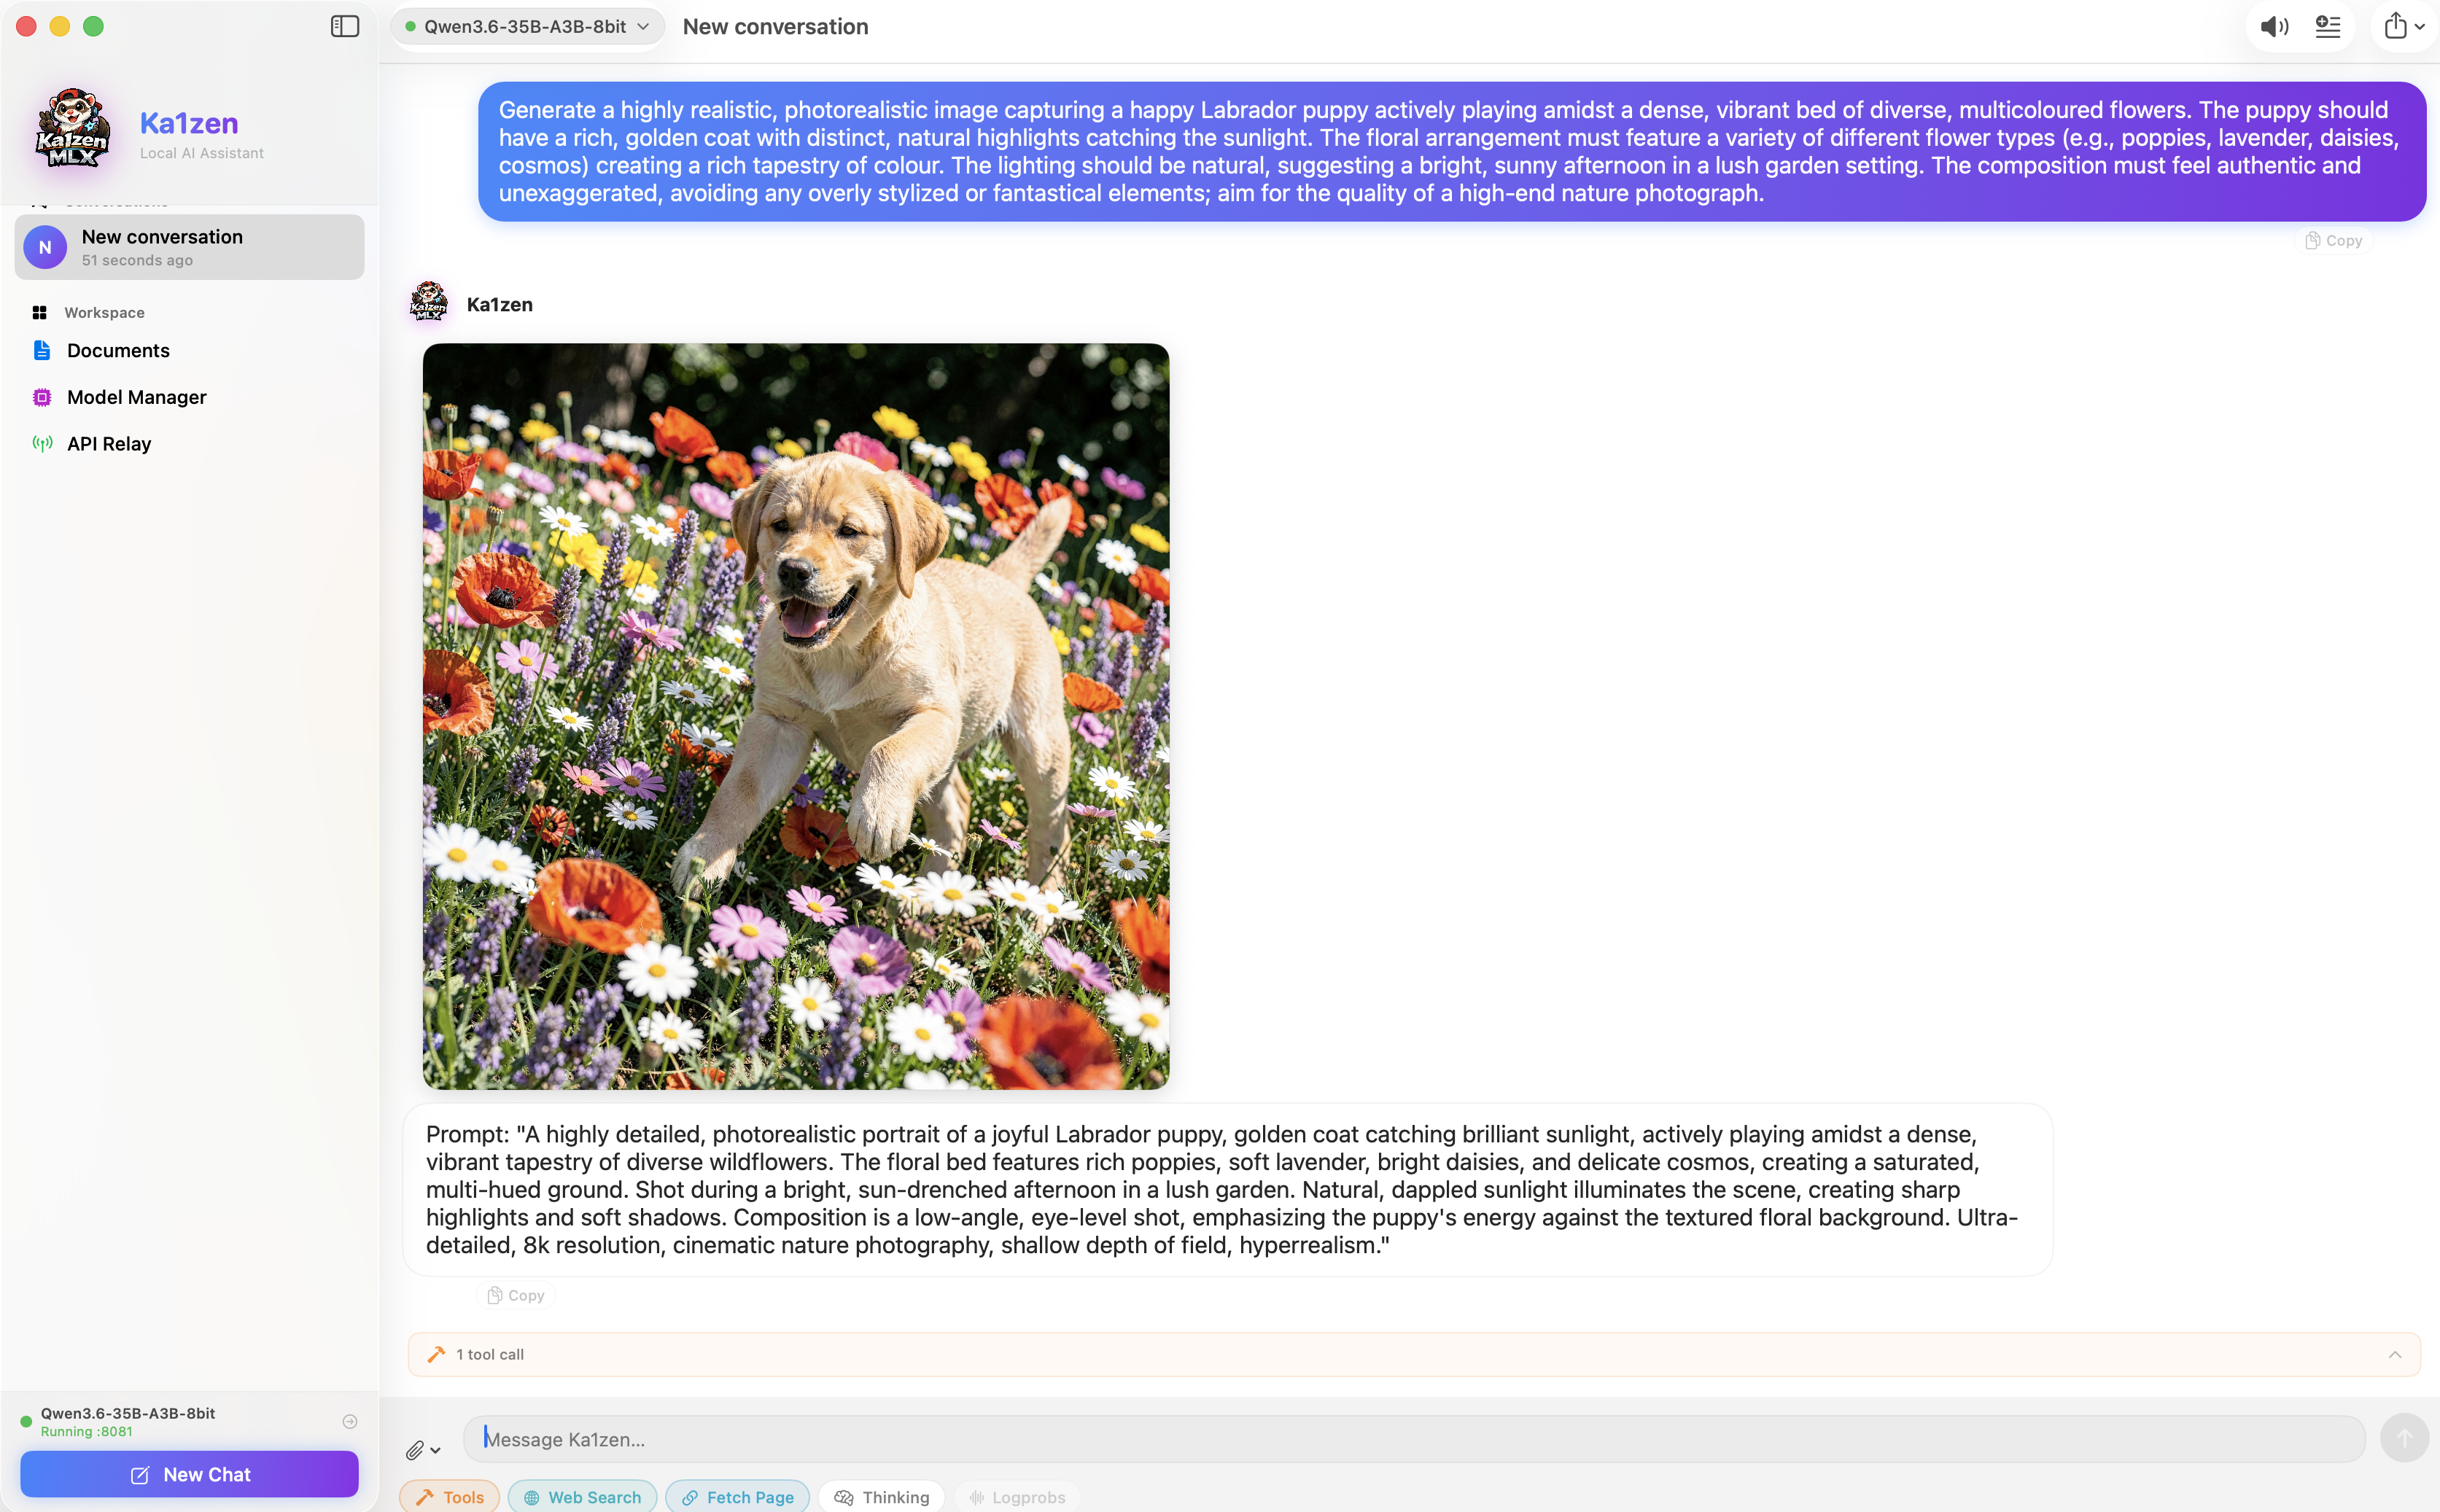
Ka1zen

Local AI for Apple Silicon. Chat with open LLMs (Qwen, Gemma, DeepSeek, Mistral, Llama…) fully offline on your Mac via Apple MLX — private by design, zero telemetry.

  • 13
  • 3 wk ago
Flor1an-BTake it
GitHubRepo

metal-guard

Defensive layer for mlx / mlx-lm / mlx-vlm on Apple Silicon. Prevents IOGPUFamily kernel panics, SIGABRT, and Mac reboots from MLX inference. Includes a community-curated registry of known-panic models (KNOWN_PANIC_MODELS) with hardware contexts, root-cause hypotheses, and verified workarounds.

  • 13
  • Python
  • MIT
  • 6 mo ago
HarperbotTake it
AI on my own machineRepo

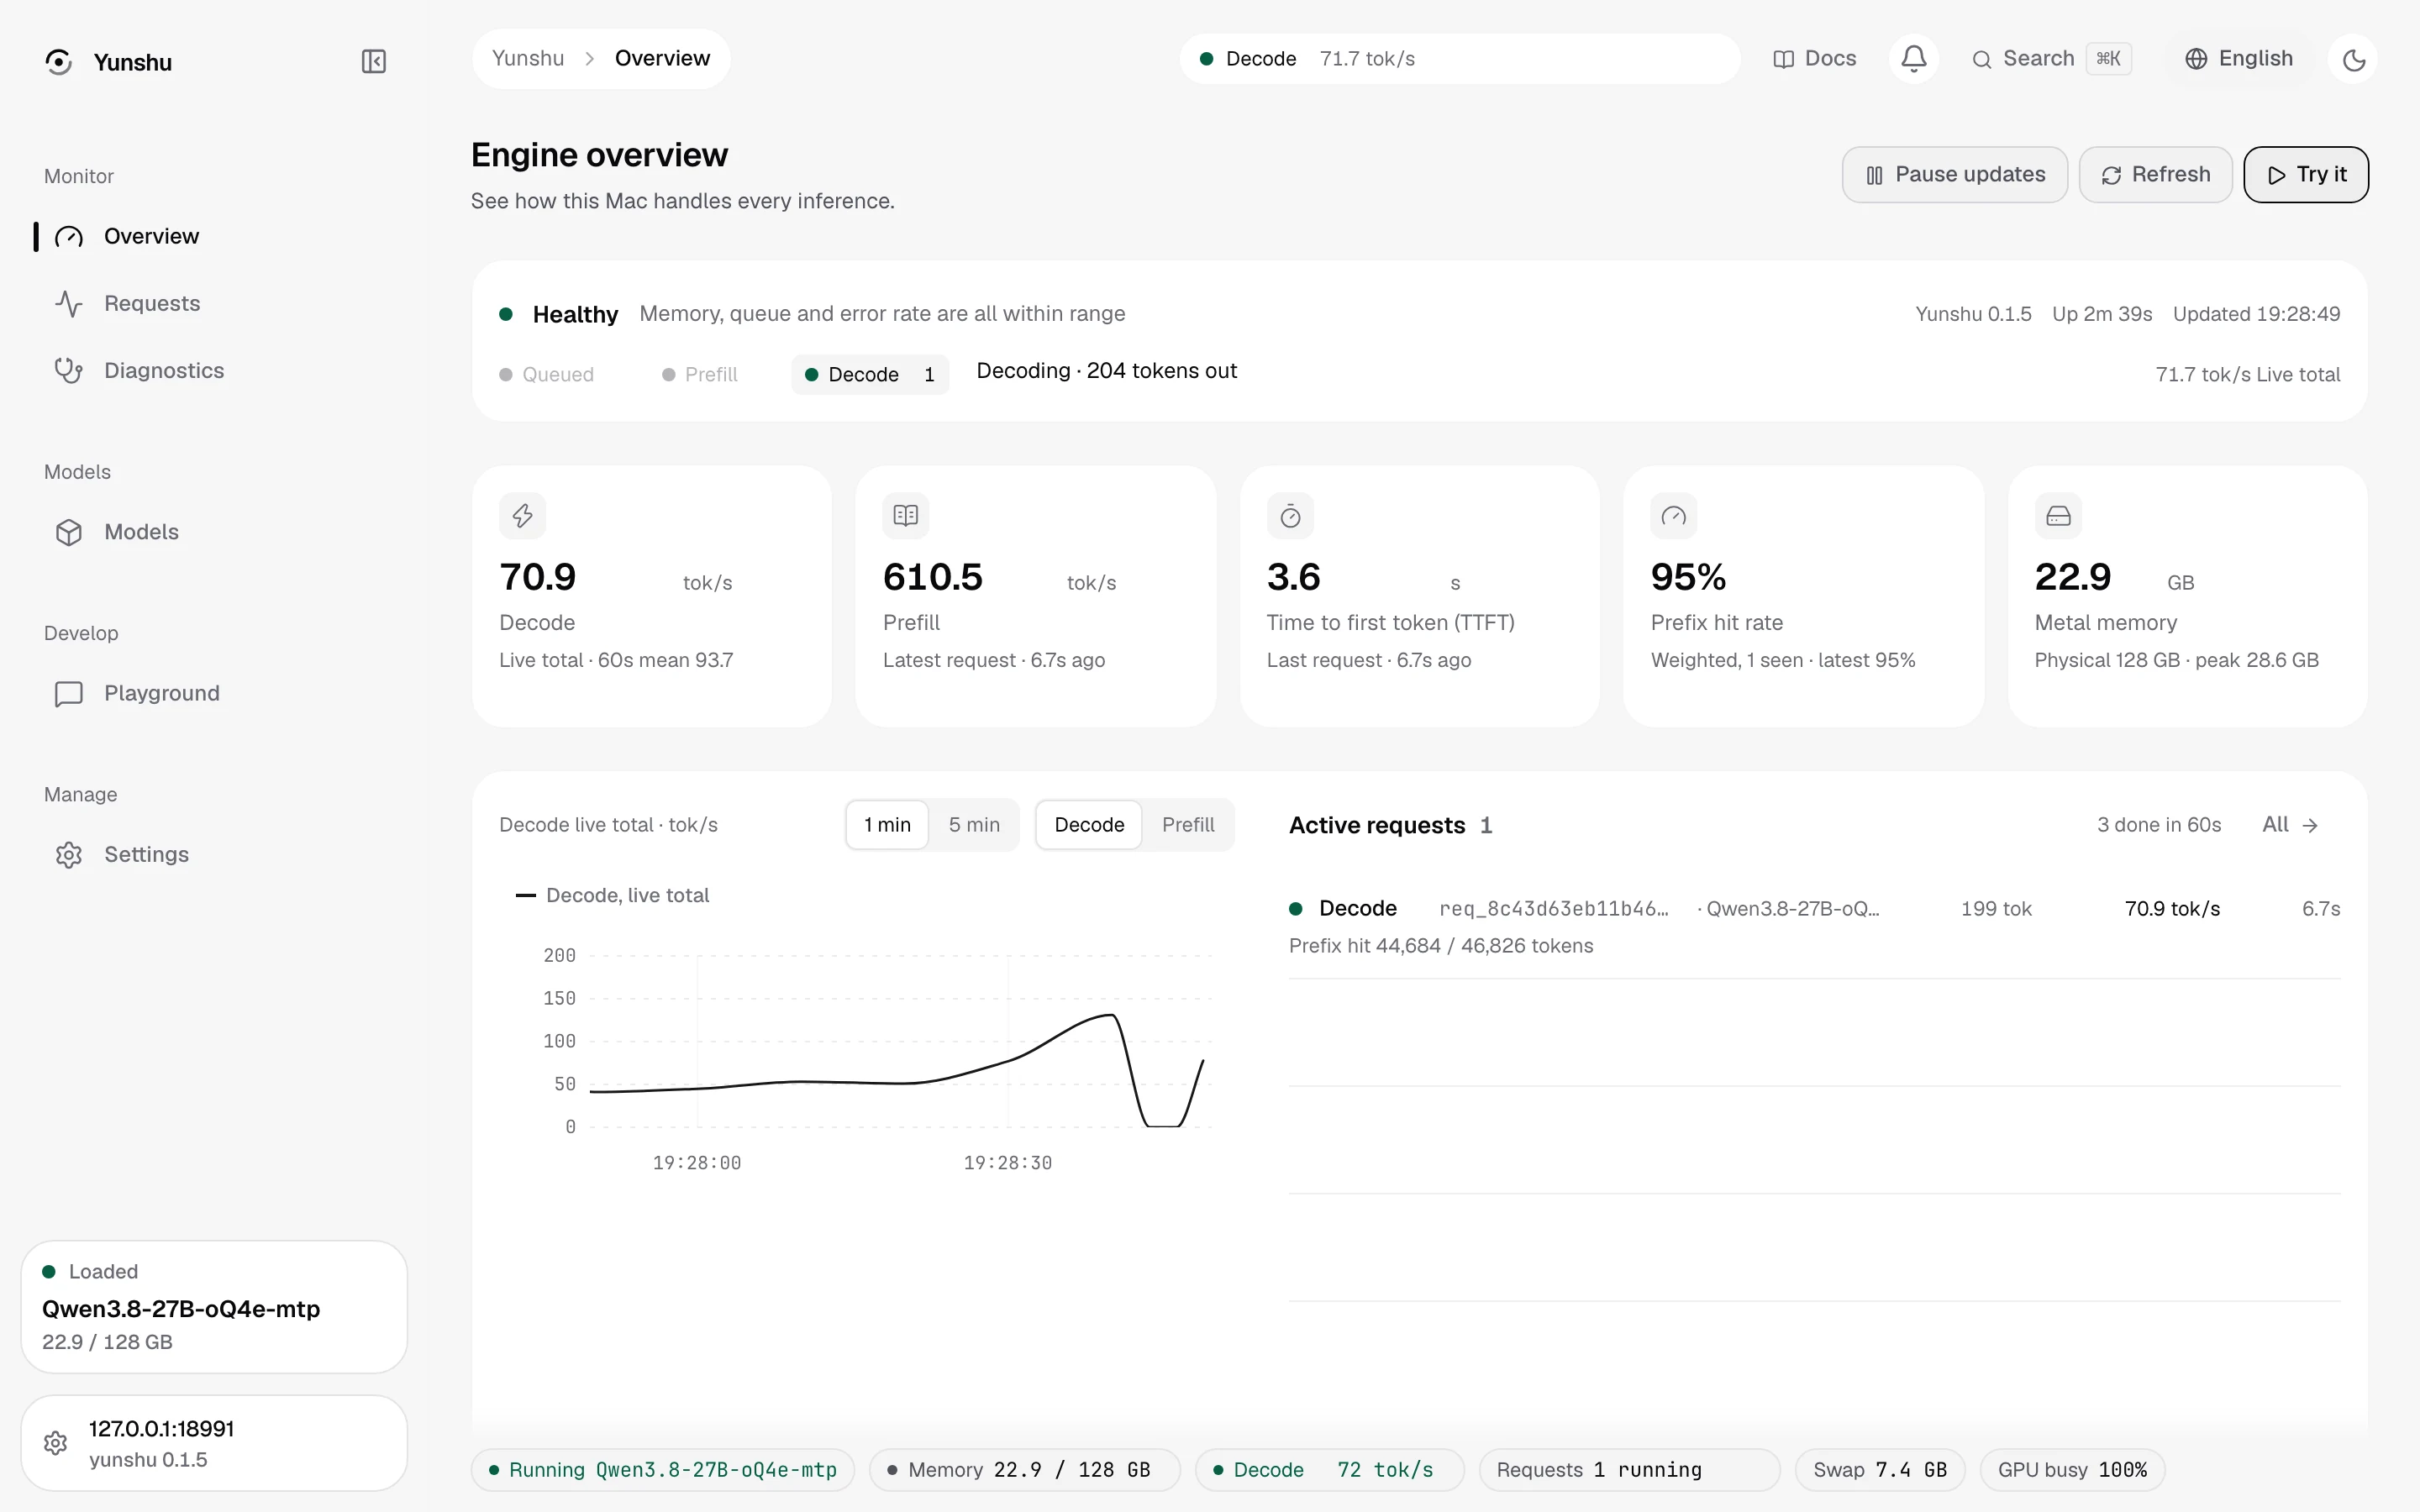
Yunshu

Fast local LLM / VLM inference engine for Apple Silicon (MLX). OpenAI- and Anthropic-compatible, lossless speculative decoding (DFlash2 / MTP), hybrid-model prefix cache with RAM/SSD tiers, native Claude Code / Codex / opencode support. Qwen3.8-27B tuned first.

  • 3
  • Python
  • Apache-2.0
  • 10 d ago
YuhuanStudioTake it
Search GitHub and Hugging Face for mlx-lm

Get , open it once and sign in. Then come back here and press the button again.