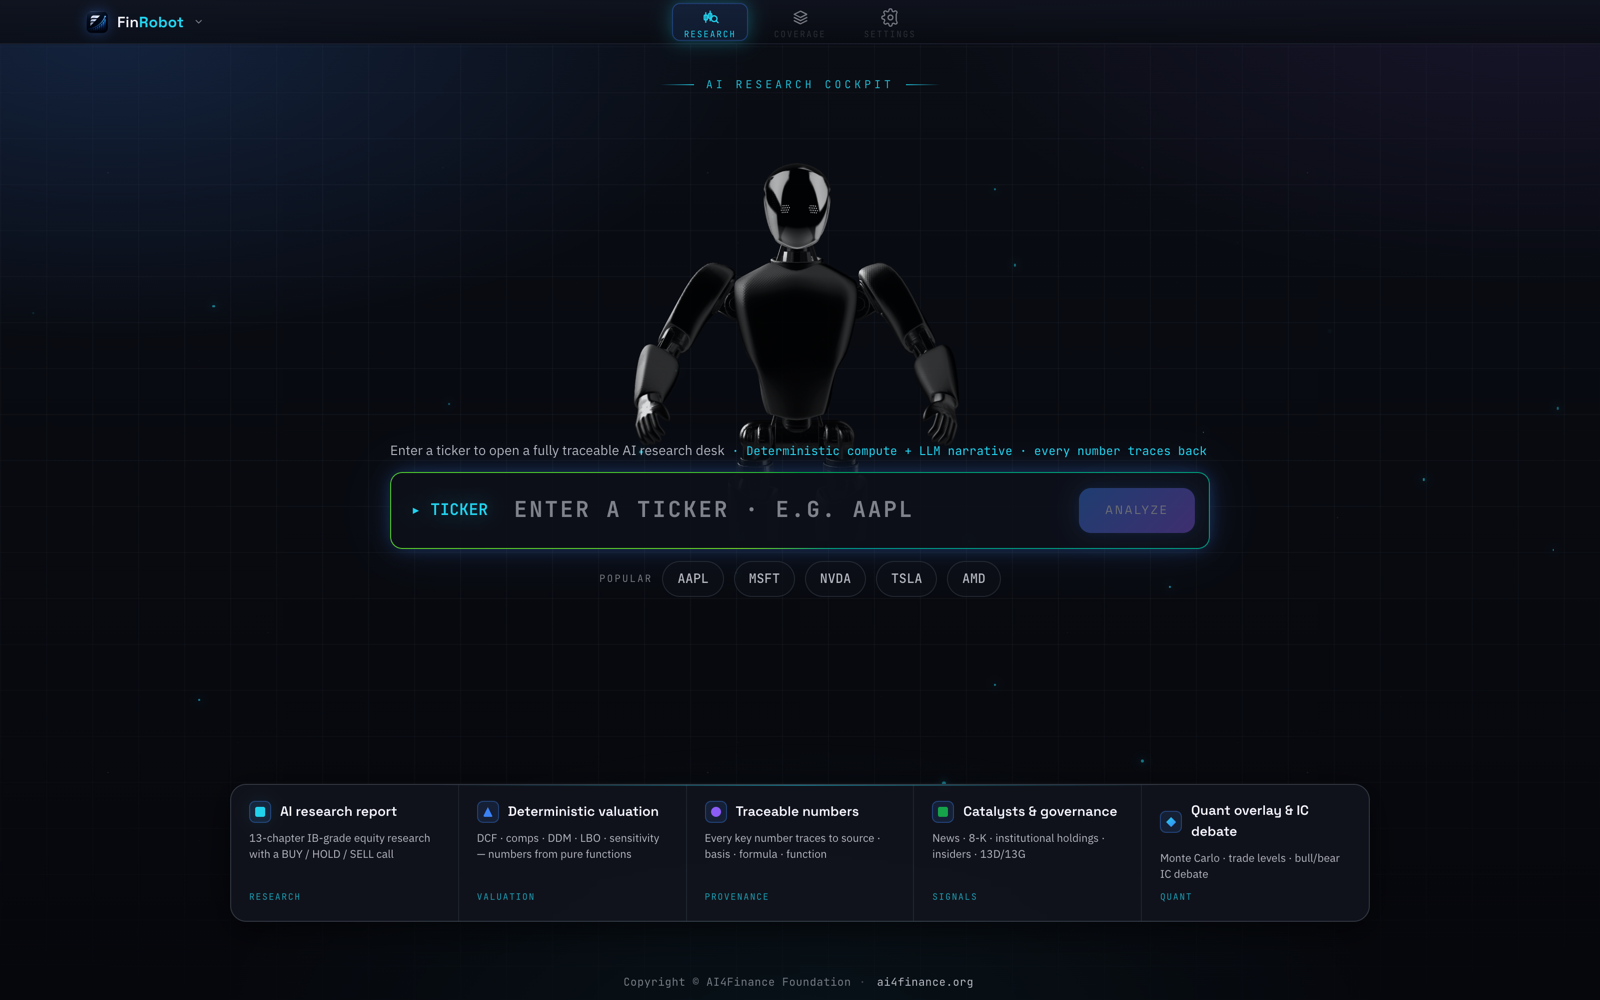
FinRobot
FinRobot: An Open-Source AI Agent Platform for Financial Applications using Large Language Models
- 8.5k
- Python
- Apache-2.0
- 4 wk ago
FinRobot: An Open-Source AI Agent Platform for Financial Applications using Large Language Models
[ICLR 2024] Official implementation of " 🦙 Time-LLM: Time Series Forecasting by Reprogramming Large Language Models"
Implementation of "BitNet: Scaling 1-bit Transformers for Large Language Models" in pytorch
A collection of original, innovative ideas and algorithms towards Advanced Literate Machinery. This project is maintained by the OCR Team in the Language Technology Lab, Tongyi Lab, Alibaba Group.
A flexible package for multimodal-deep-learning to combine tabular data with text and images using Wide and Deep models in Pytorch
收集 CVPR 最新的成果,包括论文、代码和demo视频等,欢迎大家推荐!Collect the latest CVPR (Conference on Computer Vision and Pattern Recognition) results, including papers, code, and demo videos, etc., and welcome recommendations from everyone!
Recent Advances in Vision and Language PreTrained Models (VL-PTMs)
awesome grounding: A curated list of research papers in visual grounding
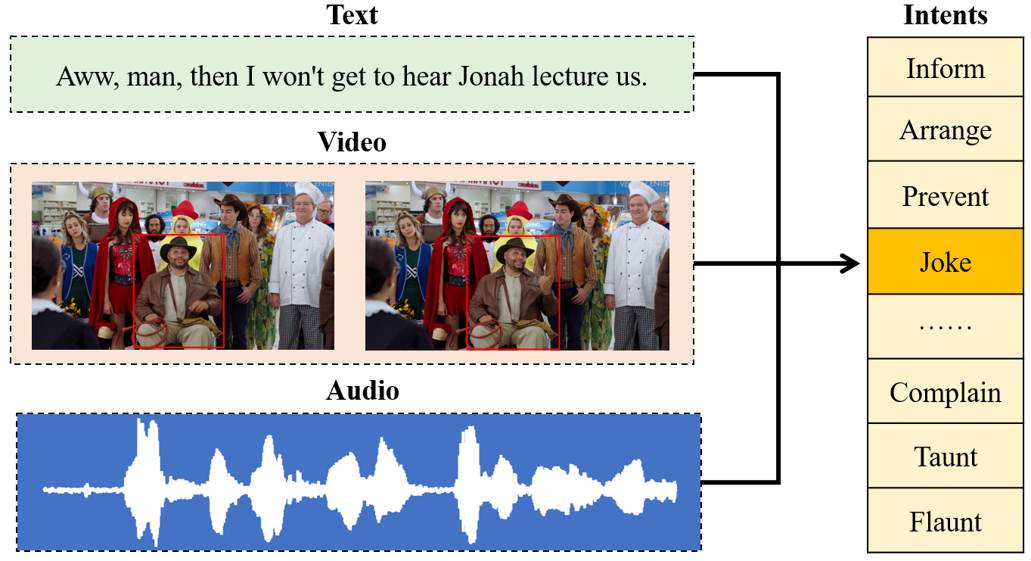
This repository contains various models targetting multimodal representation learning, multimodal fusion for downstream tasks such as multimodal sentiment analysis.
A collection of resources on applications of multi-modal learning in medical imaging.
Official implementation for "Blended Latent Diffusion" [SIGGRAPH 2023]
This repo contains evaluation code for the paper "MMMU: A Massive Multi-discipline Multimodal Understanding and Reasoning Benchmark for Expert AGI"
[ICML 2026] ByteDance's All-in-One Video Generation Model for Human-Object Interaction Video Generation
Deep learning based content moderation from text, audio, video & image input modalities.
TensorFlow implementation of "Multimodal Speech Emotion Recognition using Audio and Text," IEEE SLT-18
Code and Pretrained Models for ICLR 2023 Paper "Contrastive Audio-Visual Masked Autoencoder".
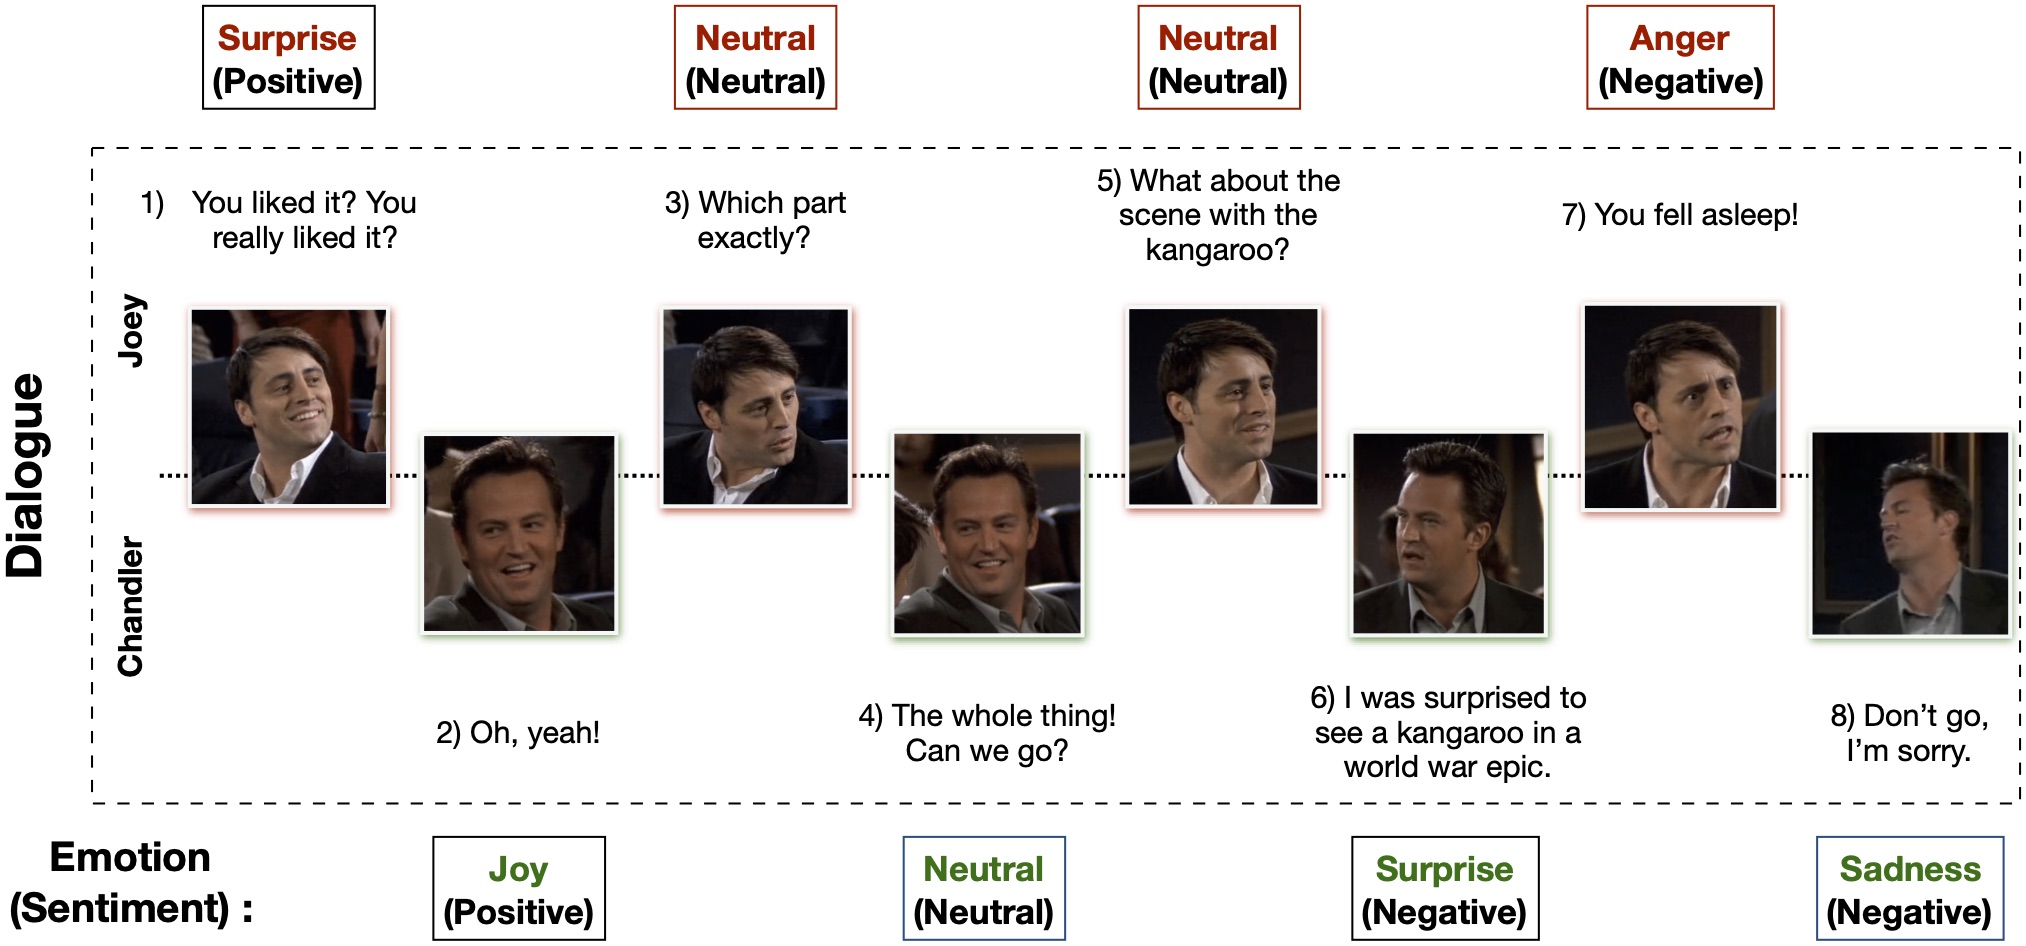
A comprehensive reading list for Emotion Recognition in Conversations
Implementation of CVPR 2023 paper "Prompting Large Language Models with Answer Heuristics for Knowledge-based Visual Question Answering".
My implementation of "Patch n’ Pack: NaViT, a Vision Transformer for any Aspect Ratio and Resolution"
Multimodal Co-Attention Transformer for Survival Prediction in Gigapixel Whole Slide Images - ICCV 2021
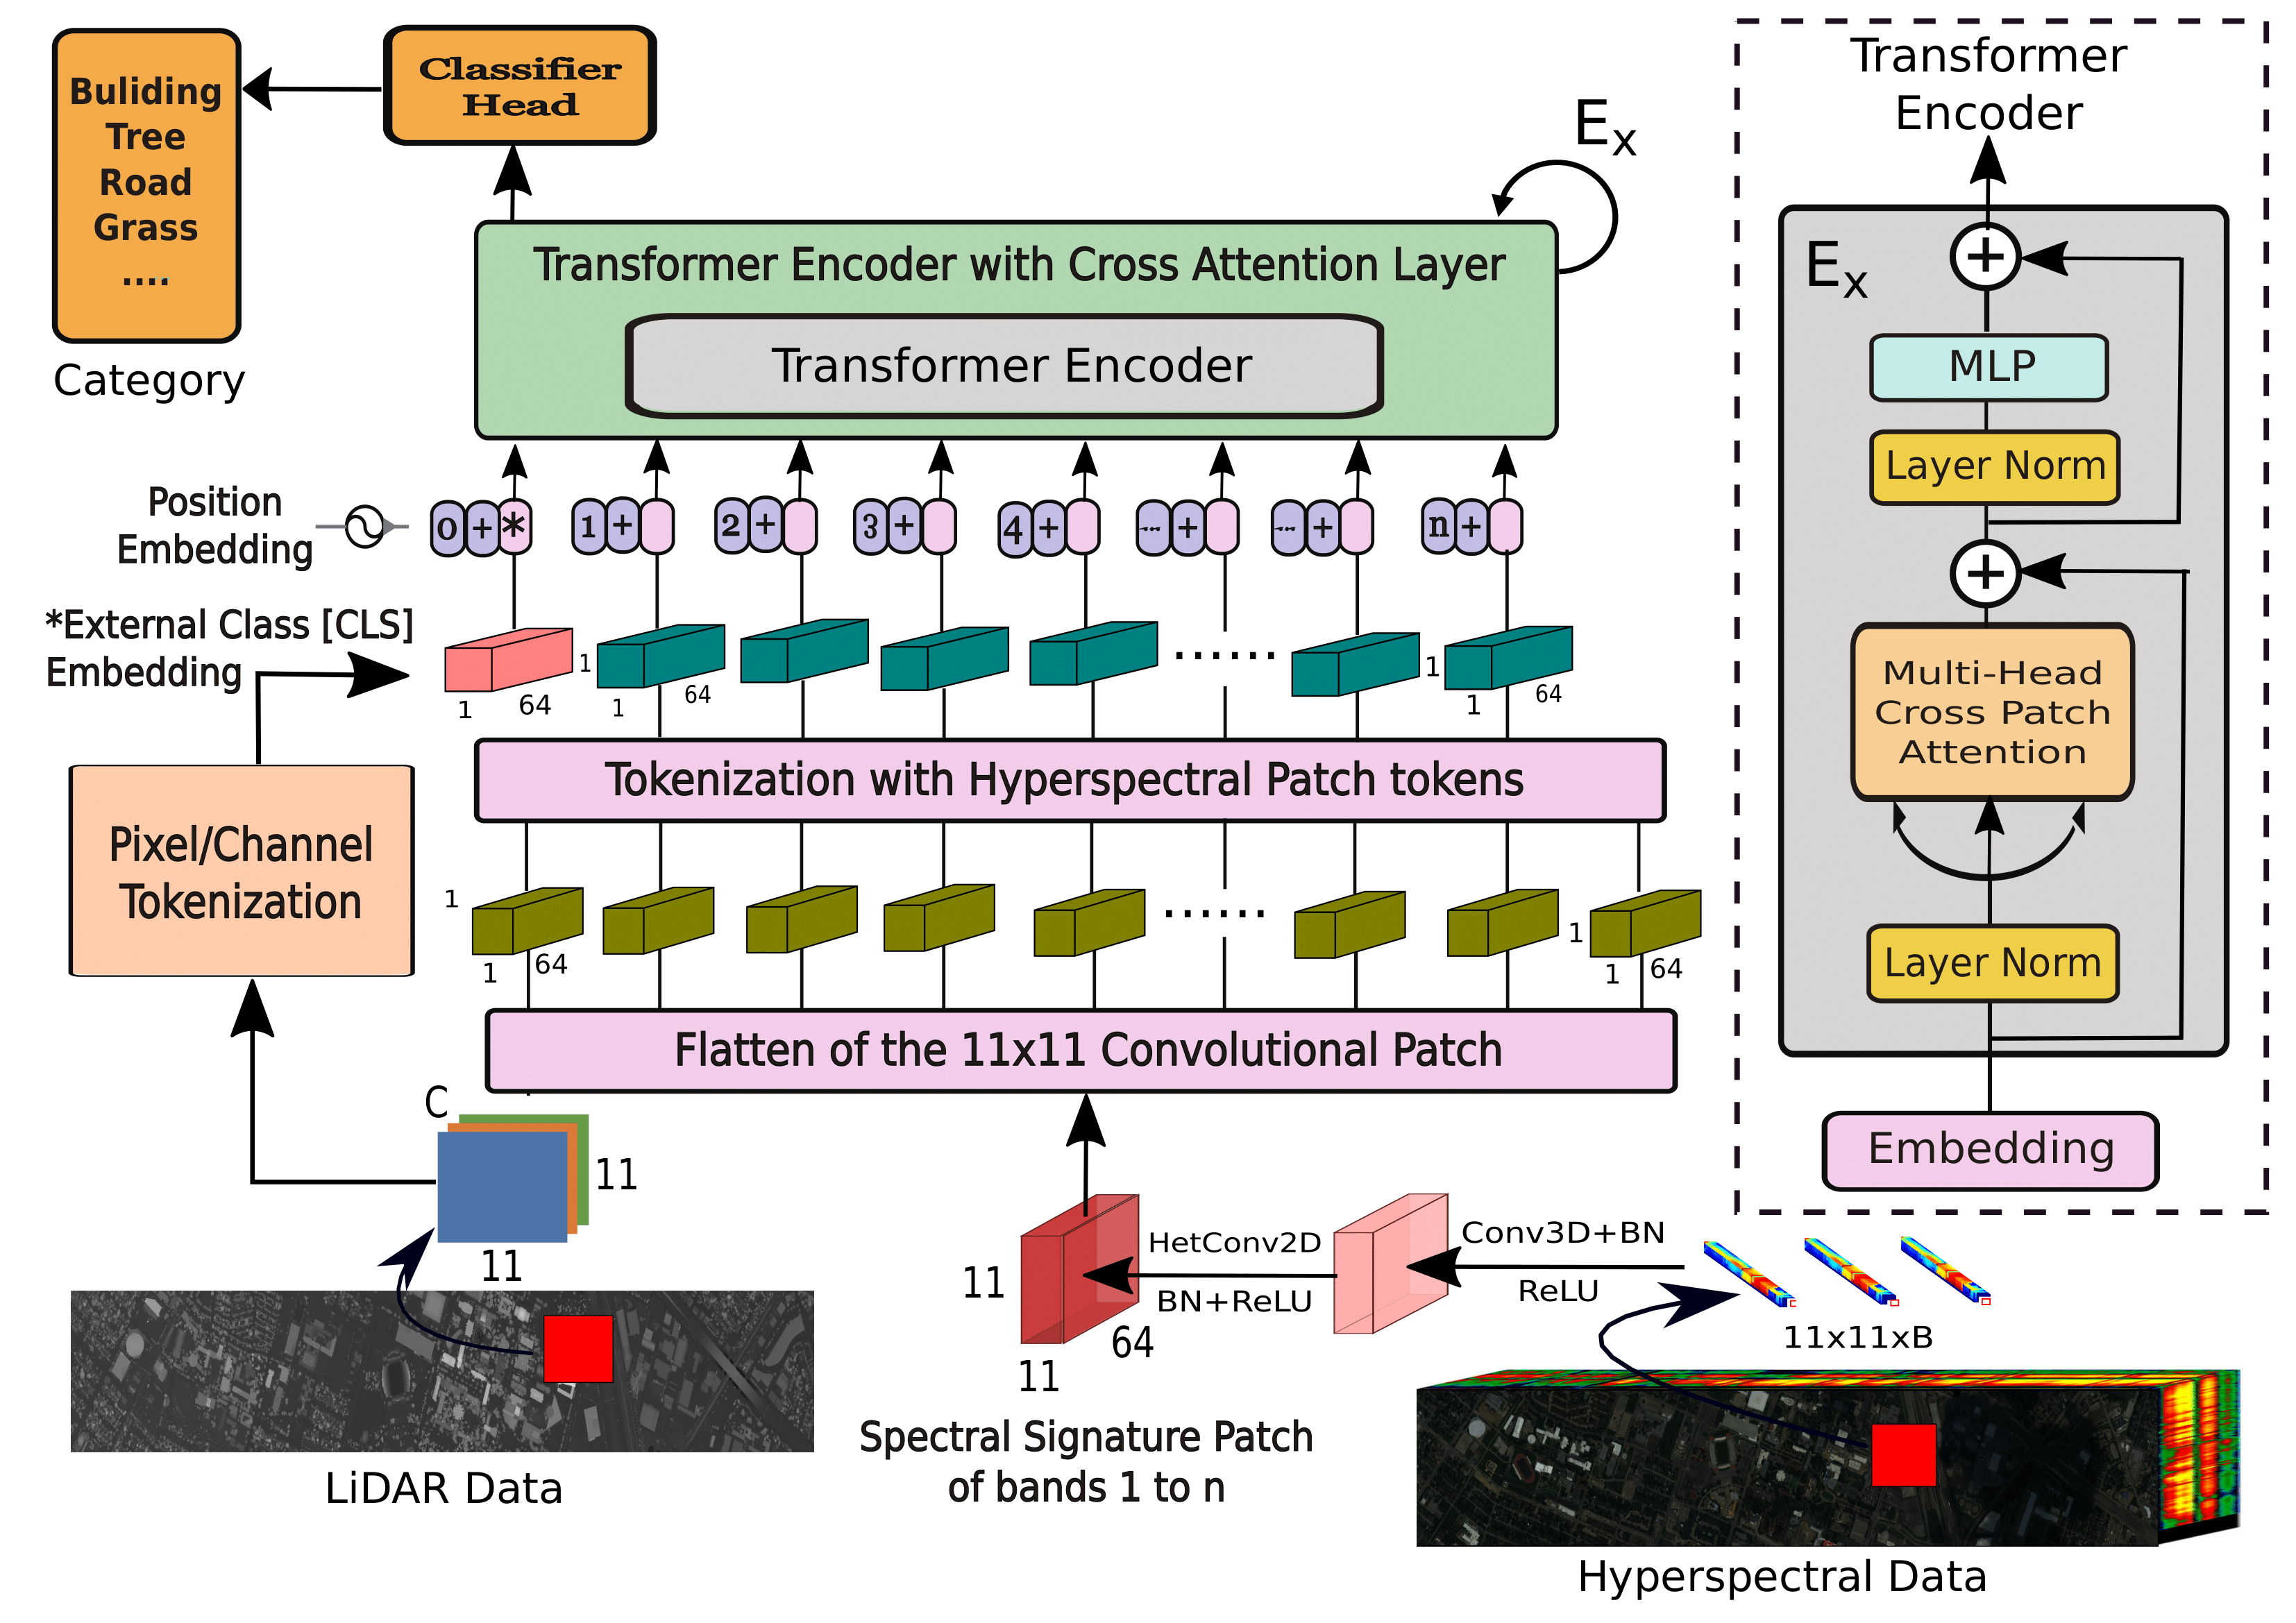
Pytorch implementation of Multimodal Fusion Transformer for Remote Sensing Image Classification.
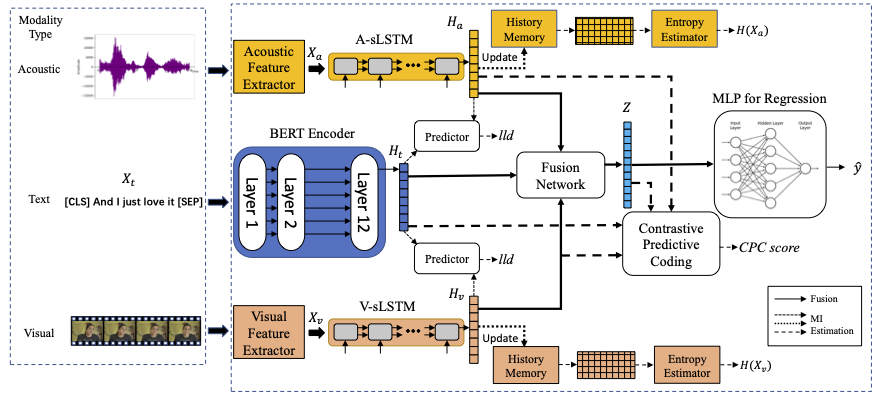
This repository contains the official implementation code of the paper Improving Multimodal Fusion with Hierarchical Mutual Information Maximization for Multimodal Sentiment Analysis, accepted at EMNLP 2021.
Swarming algorithms like PSO, Ant Colony, Sakana, and more in PyTorch 😊
Implementation of PALI3 from the paper PALI-3 VISION LANGUAGE MODELS: SMALLER, FASTER, STRONGER"
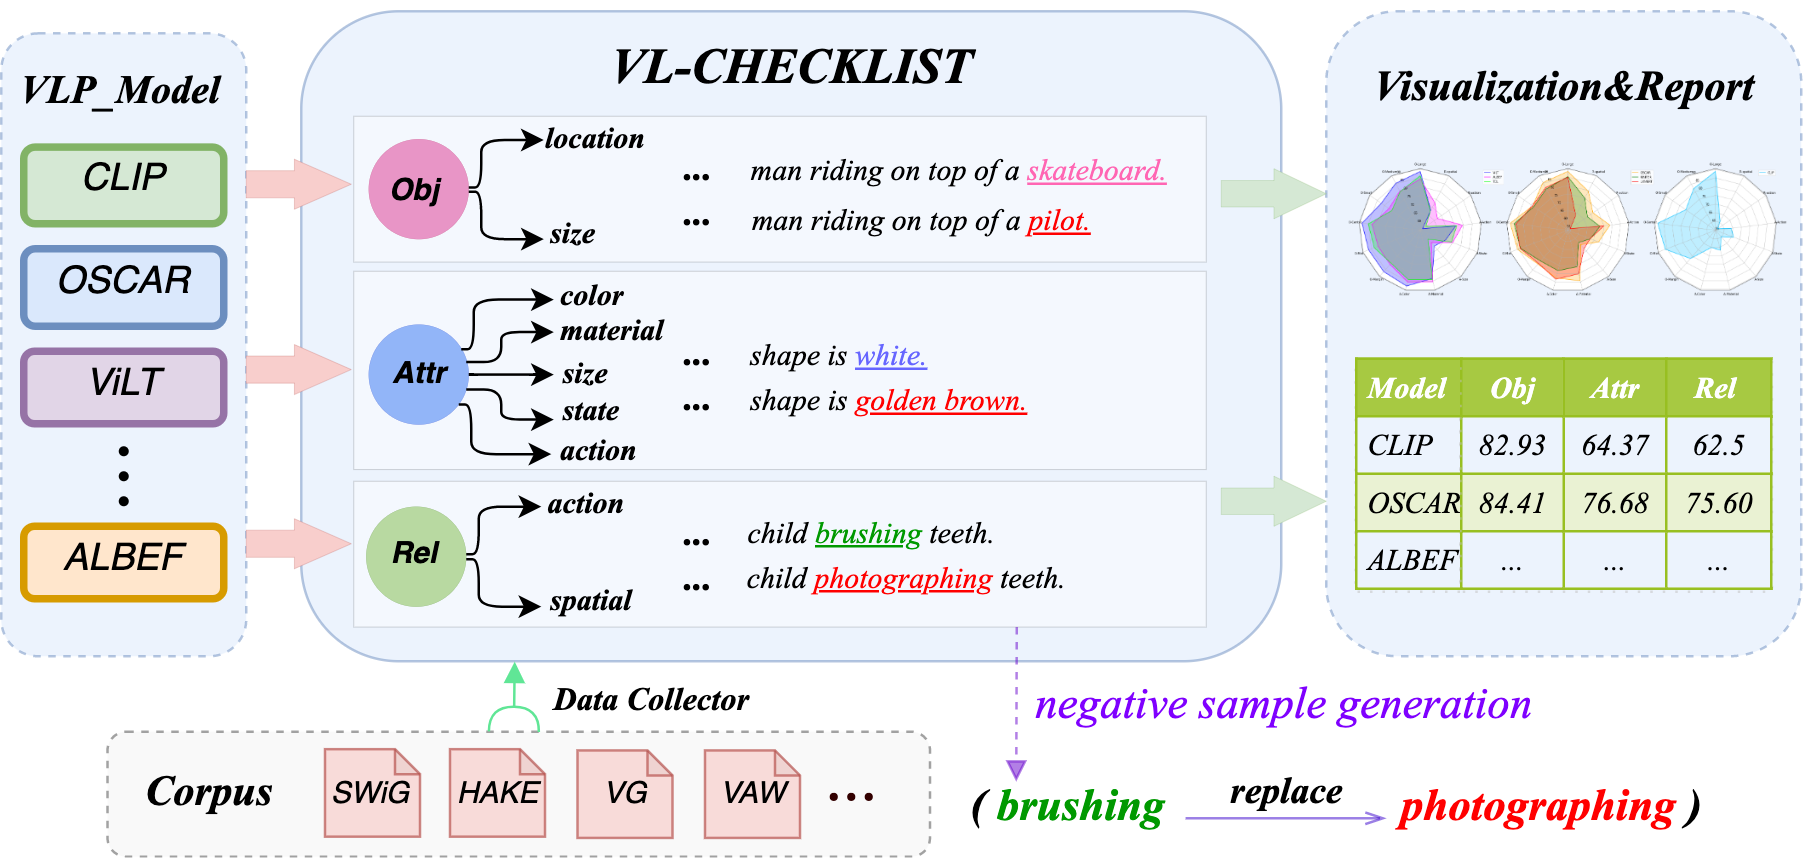
Evaluating Vision & Language Pretraining Models with Objects, Attributes and Relations. [EMNLP 2022]
The code for our IEEE ACCESS (2020) paper Multimodal Emotion Recognition with Transformer-Based Self Supervised Feature Fusion.
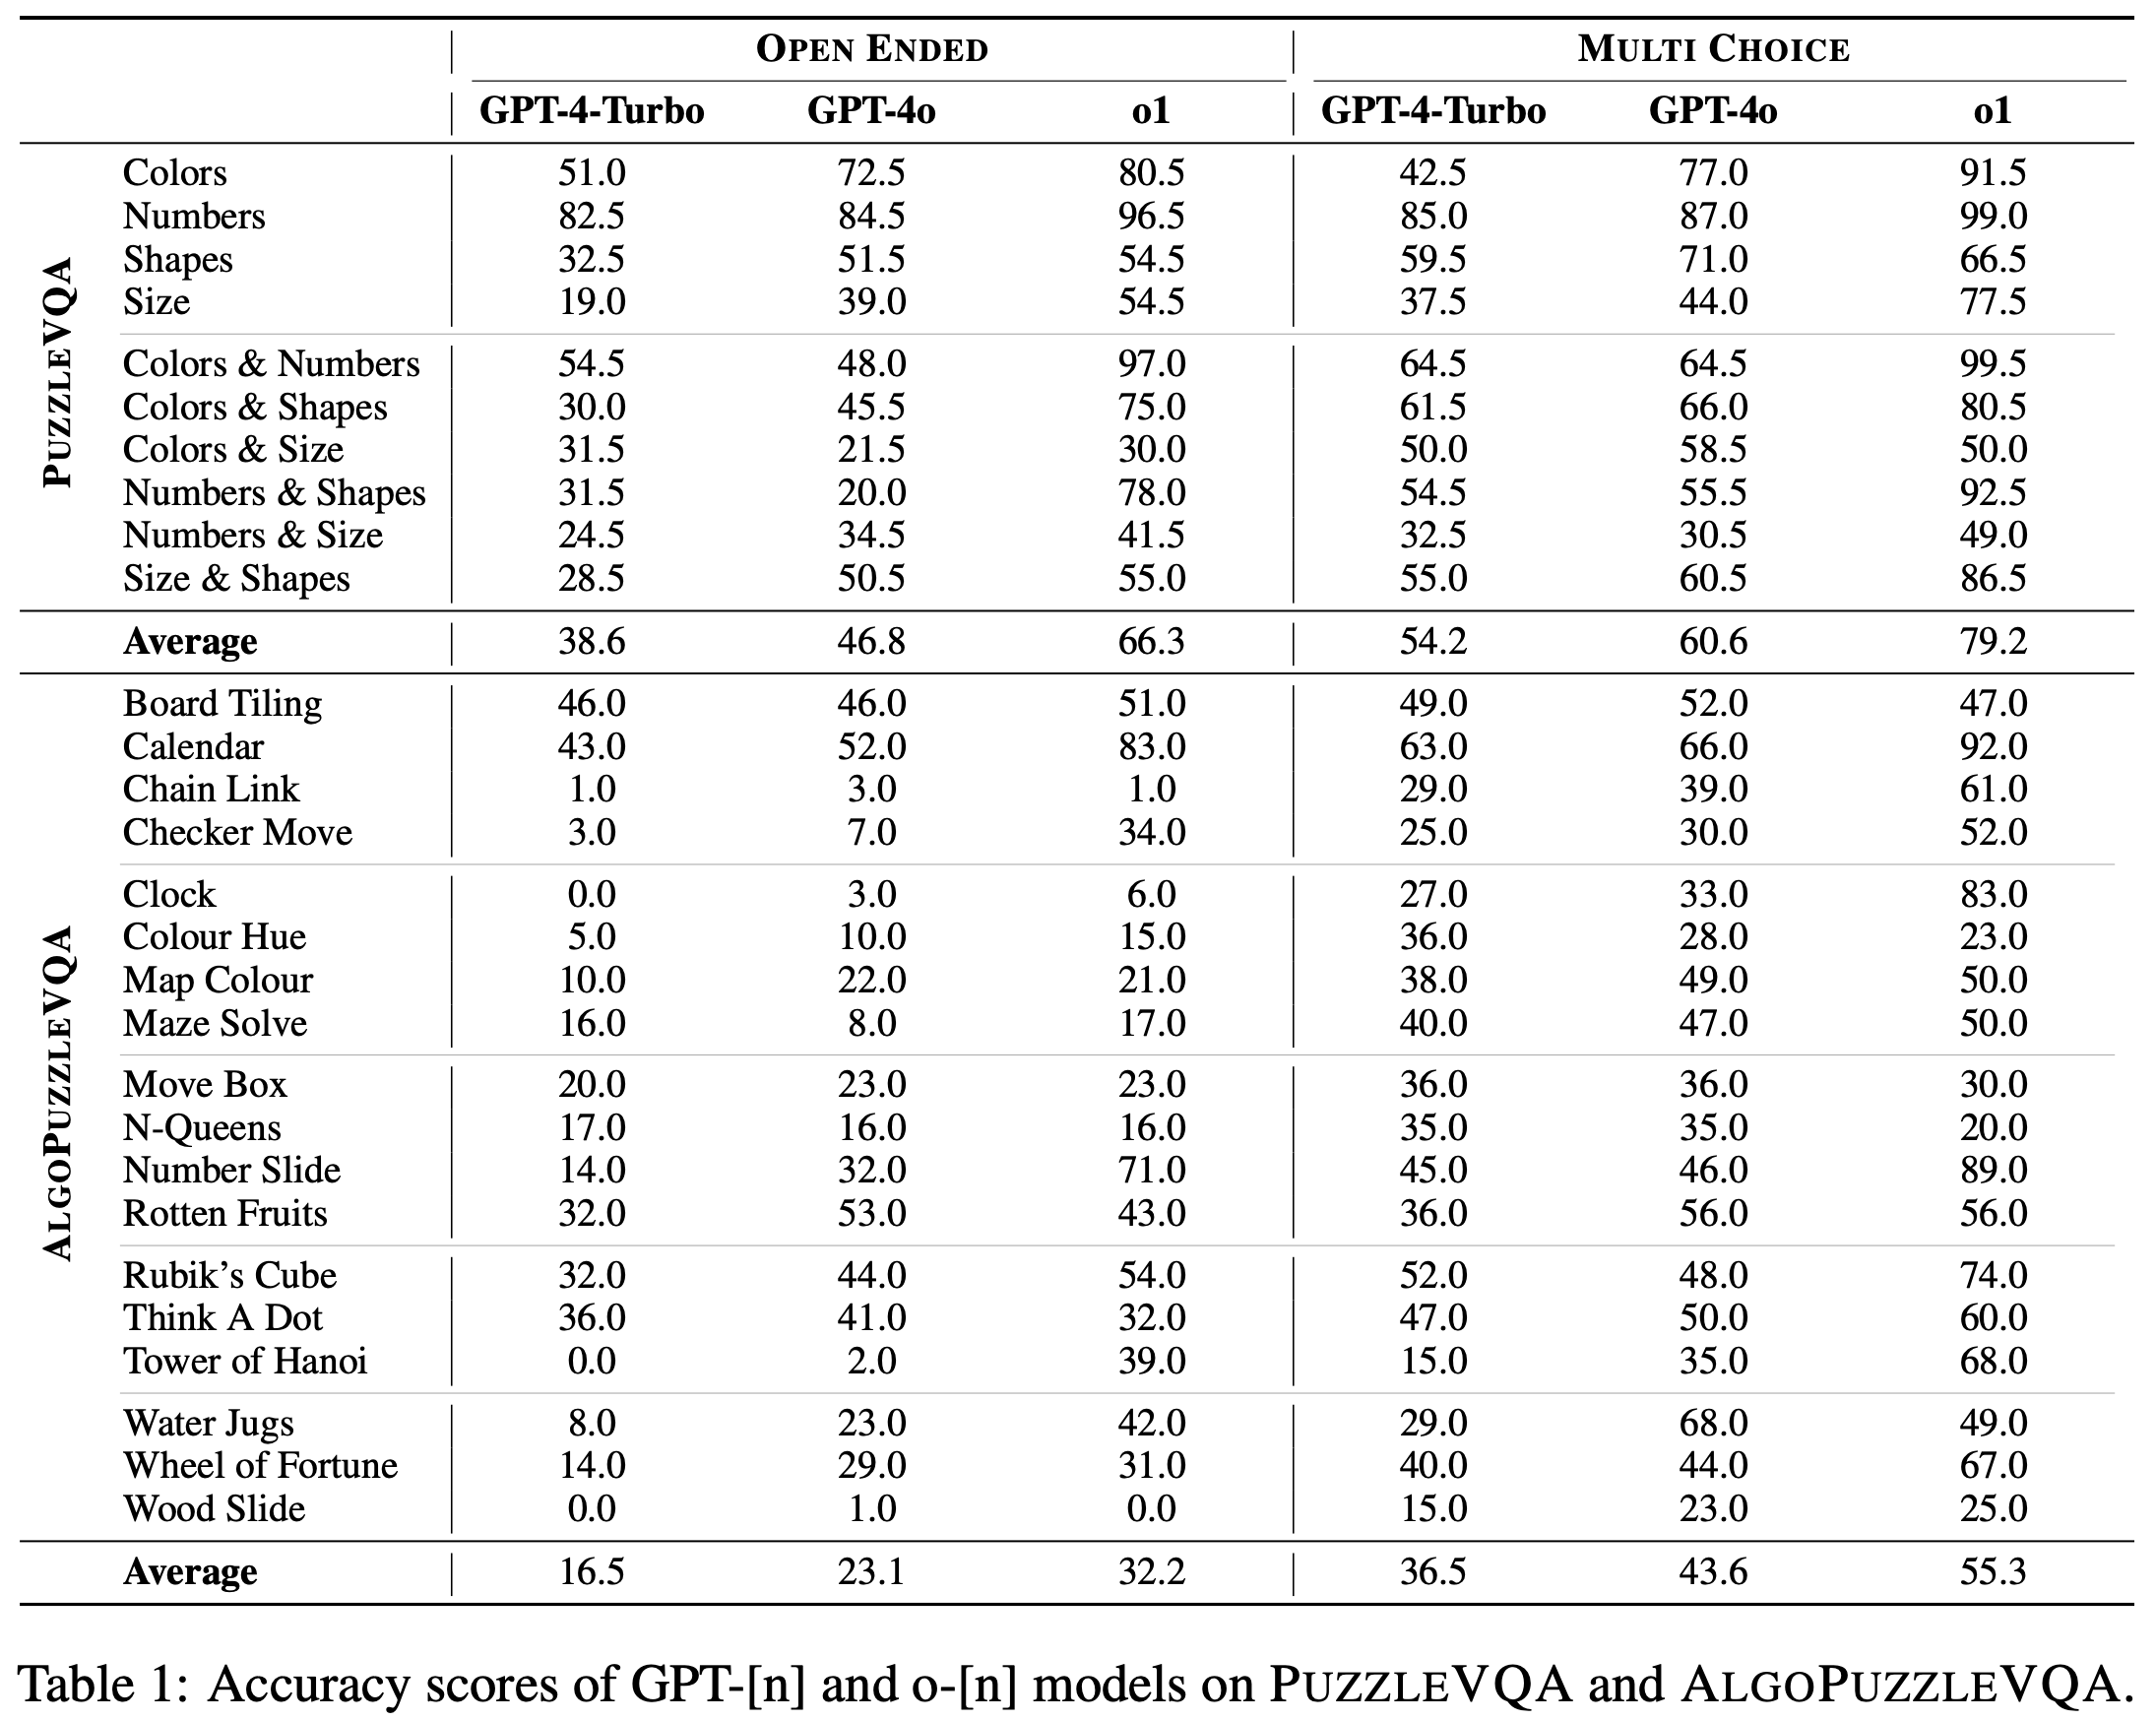
This repository is maintained to release dataset and models for multimodal puzzle reasoning.
[NeurIPS 2022] Official code for REVIVE: Regional Visual Representation Matters in Knowledge-Based Visual Question Answering