Ovis
A novel Multimodal Large Language Model (MLLM) architecture, designed to structurally align visual and textual embeddings.
- 1.5k
- Python
- Apache-2.0
- 4 mo ago
A novel Multimodal Large Language Model (MLLM) architecture, designed to structurally align visual and textual embeddings.
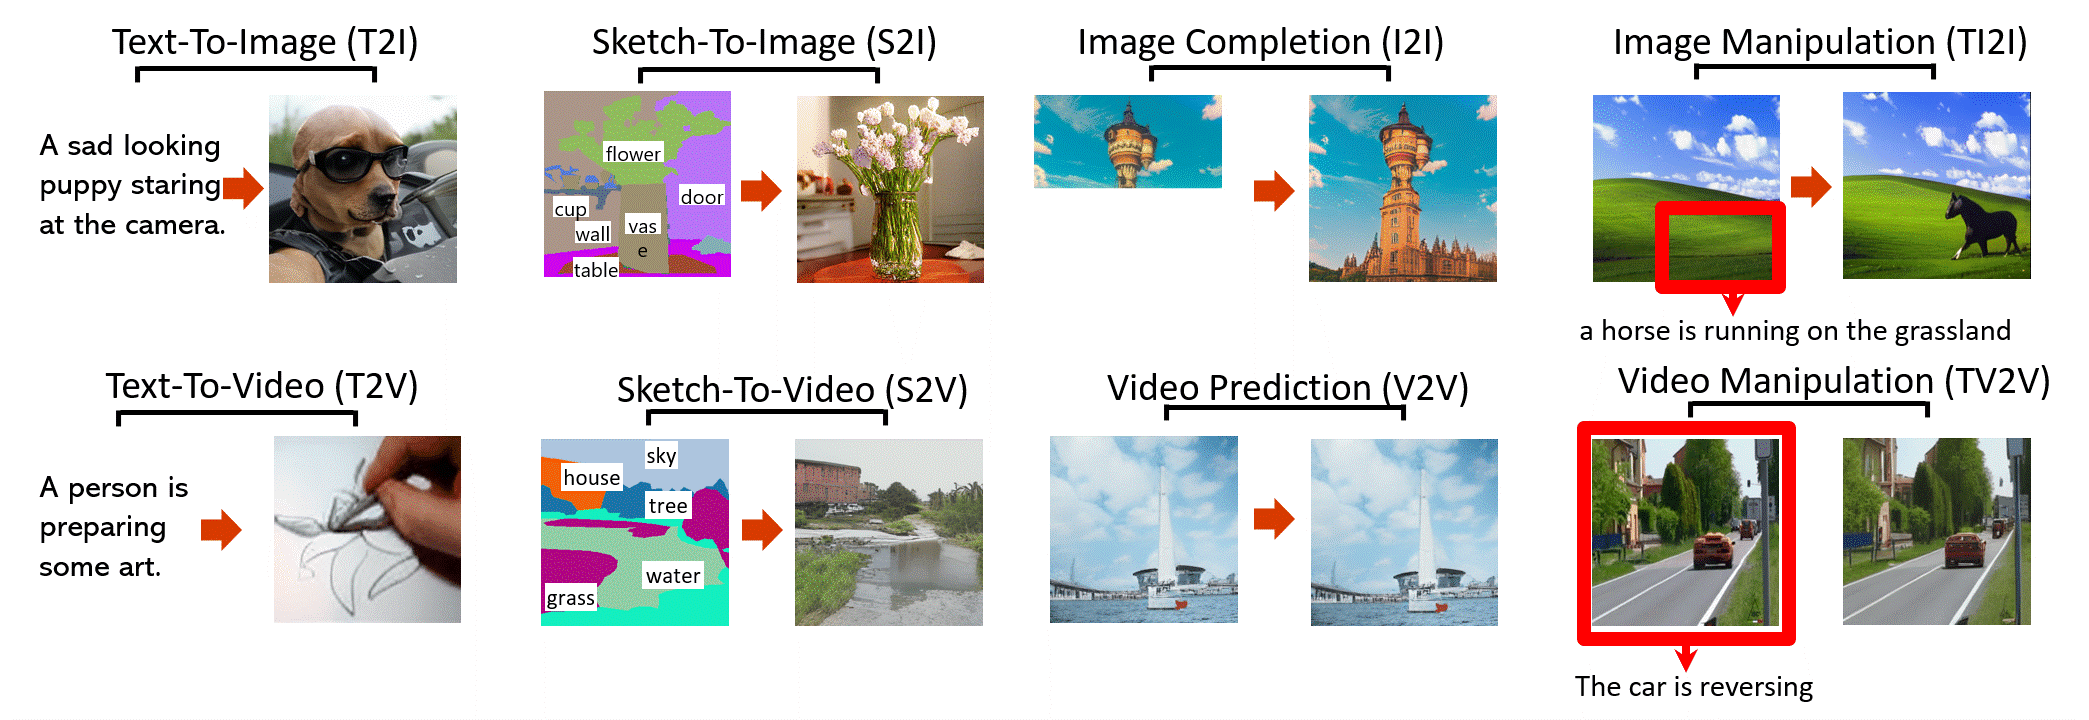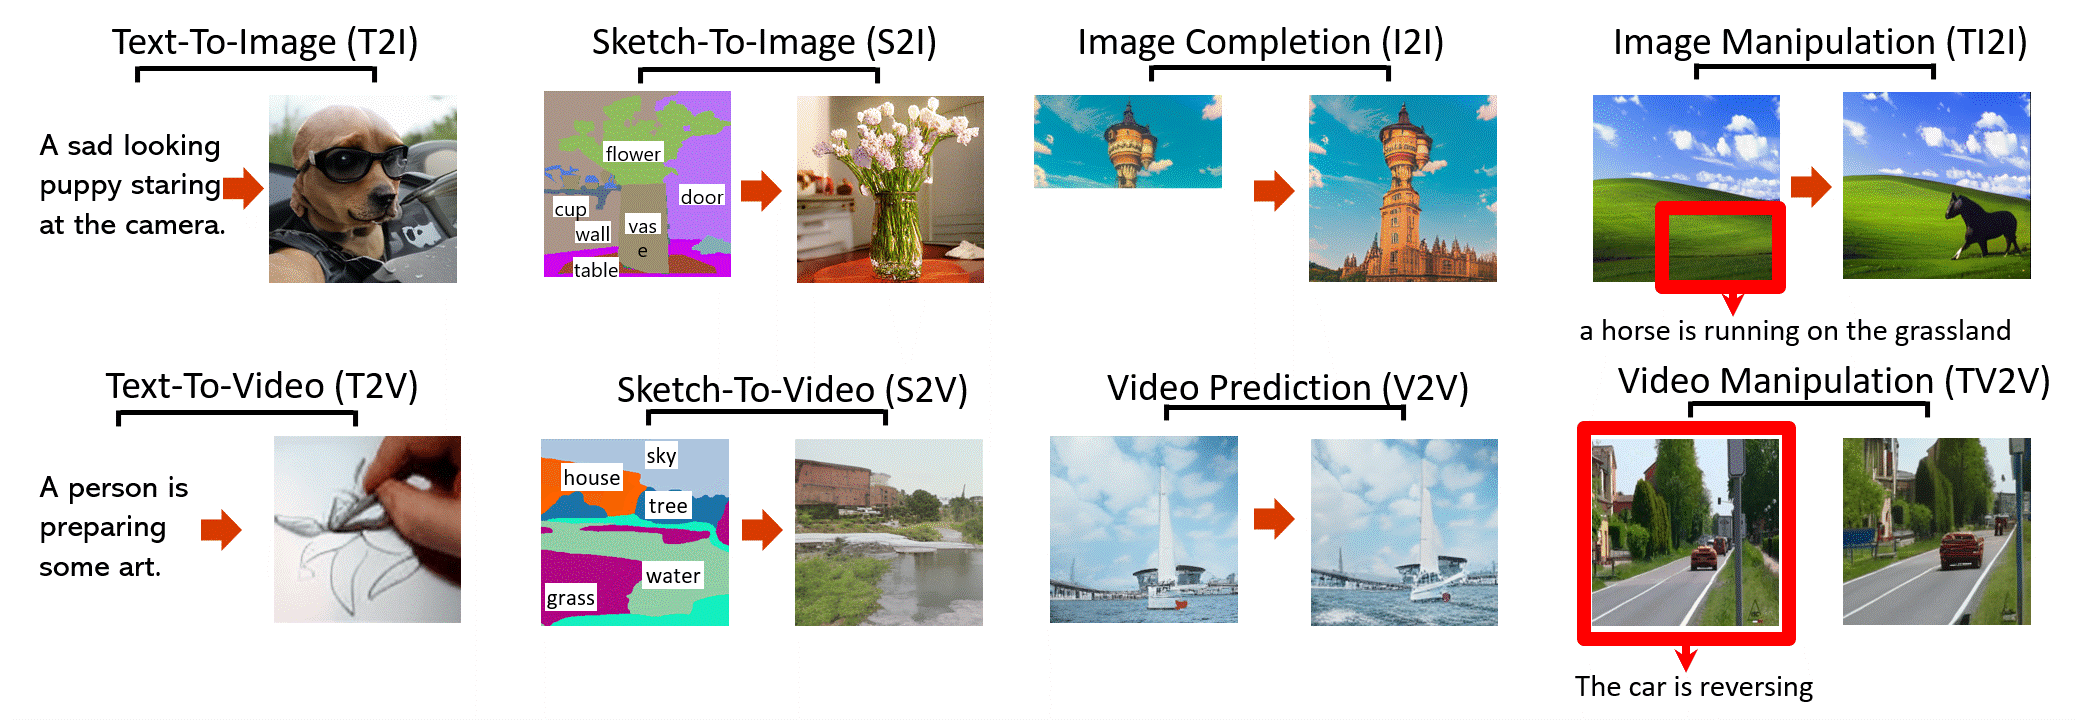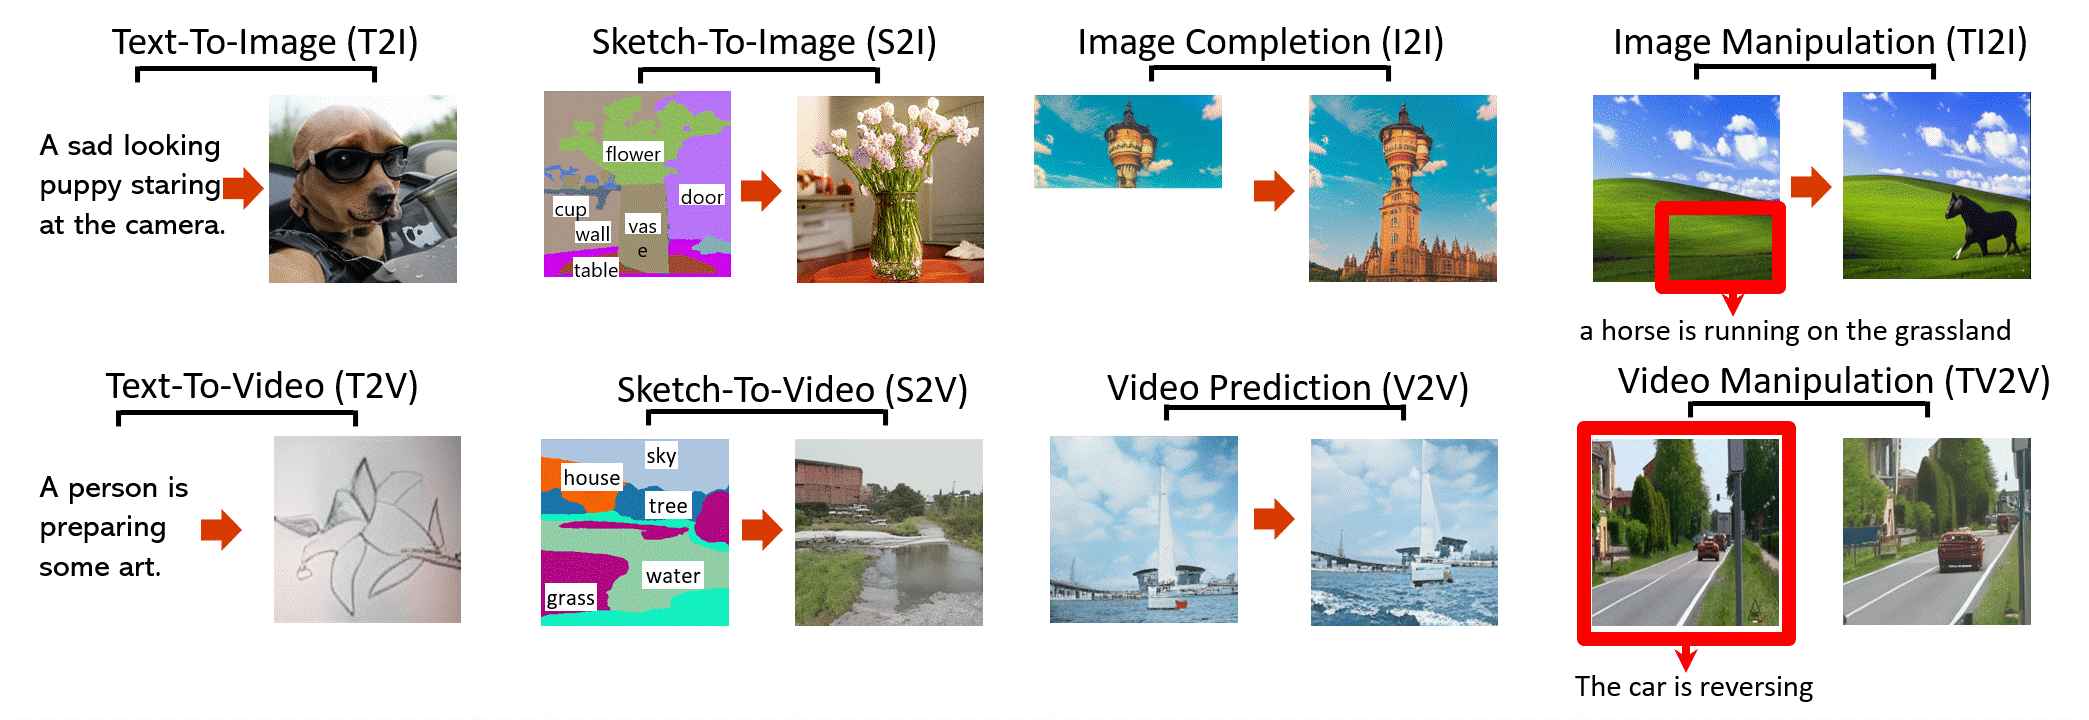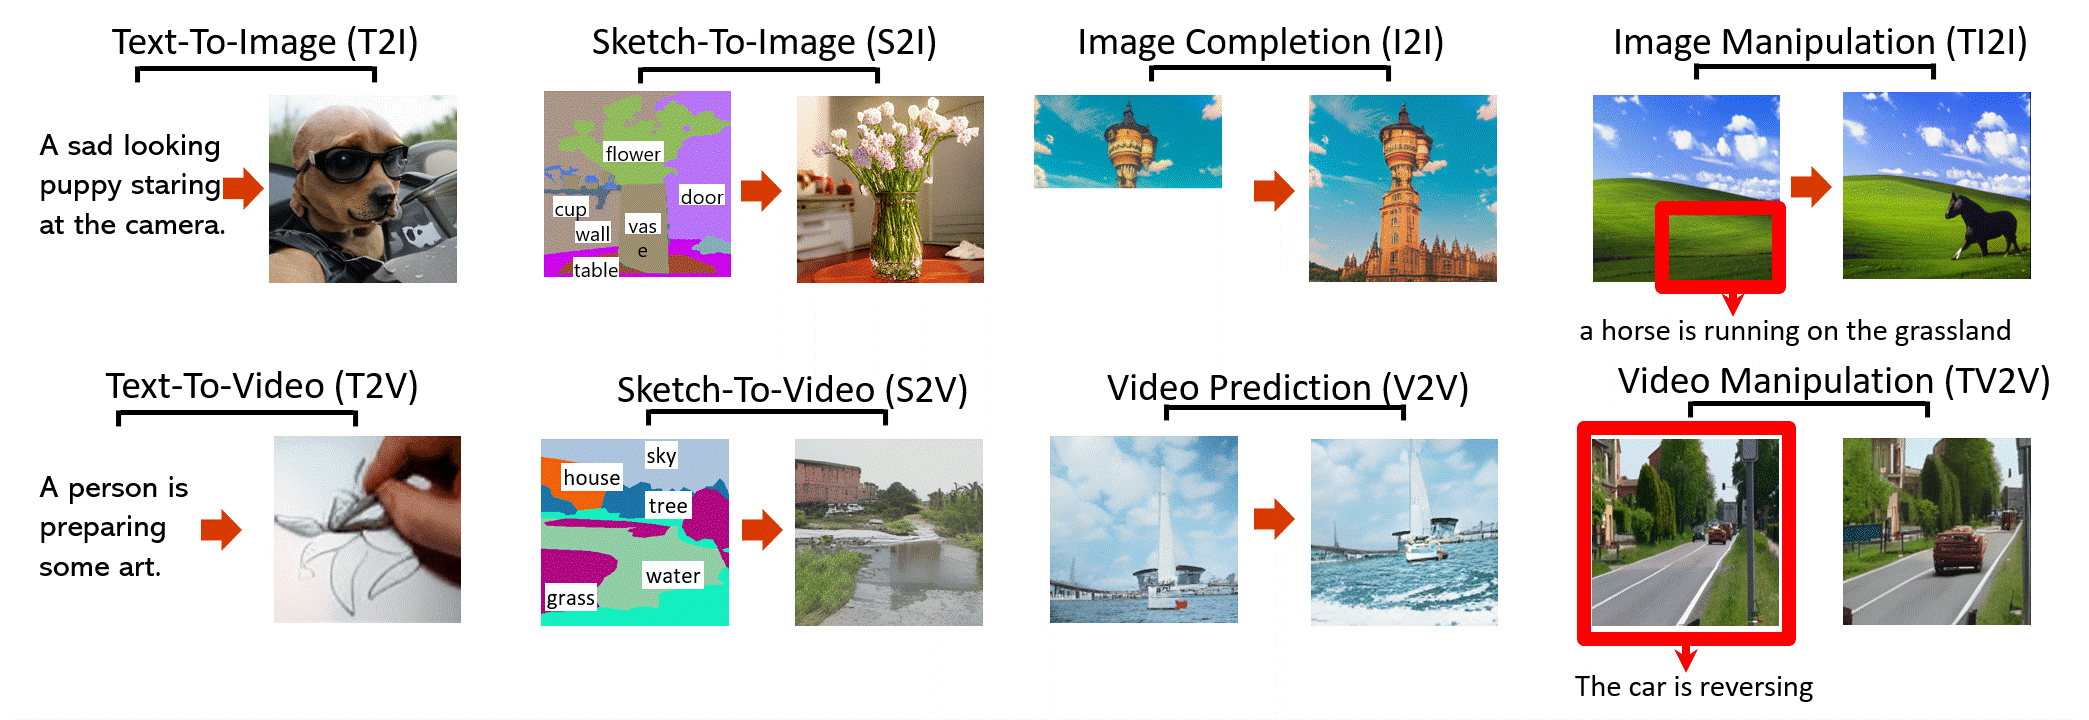
[TPAMI 2023] Multimodal Image Synthesis and Editing: The Generative AI Era
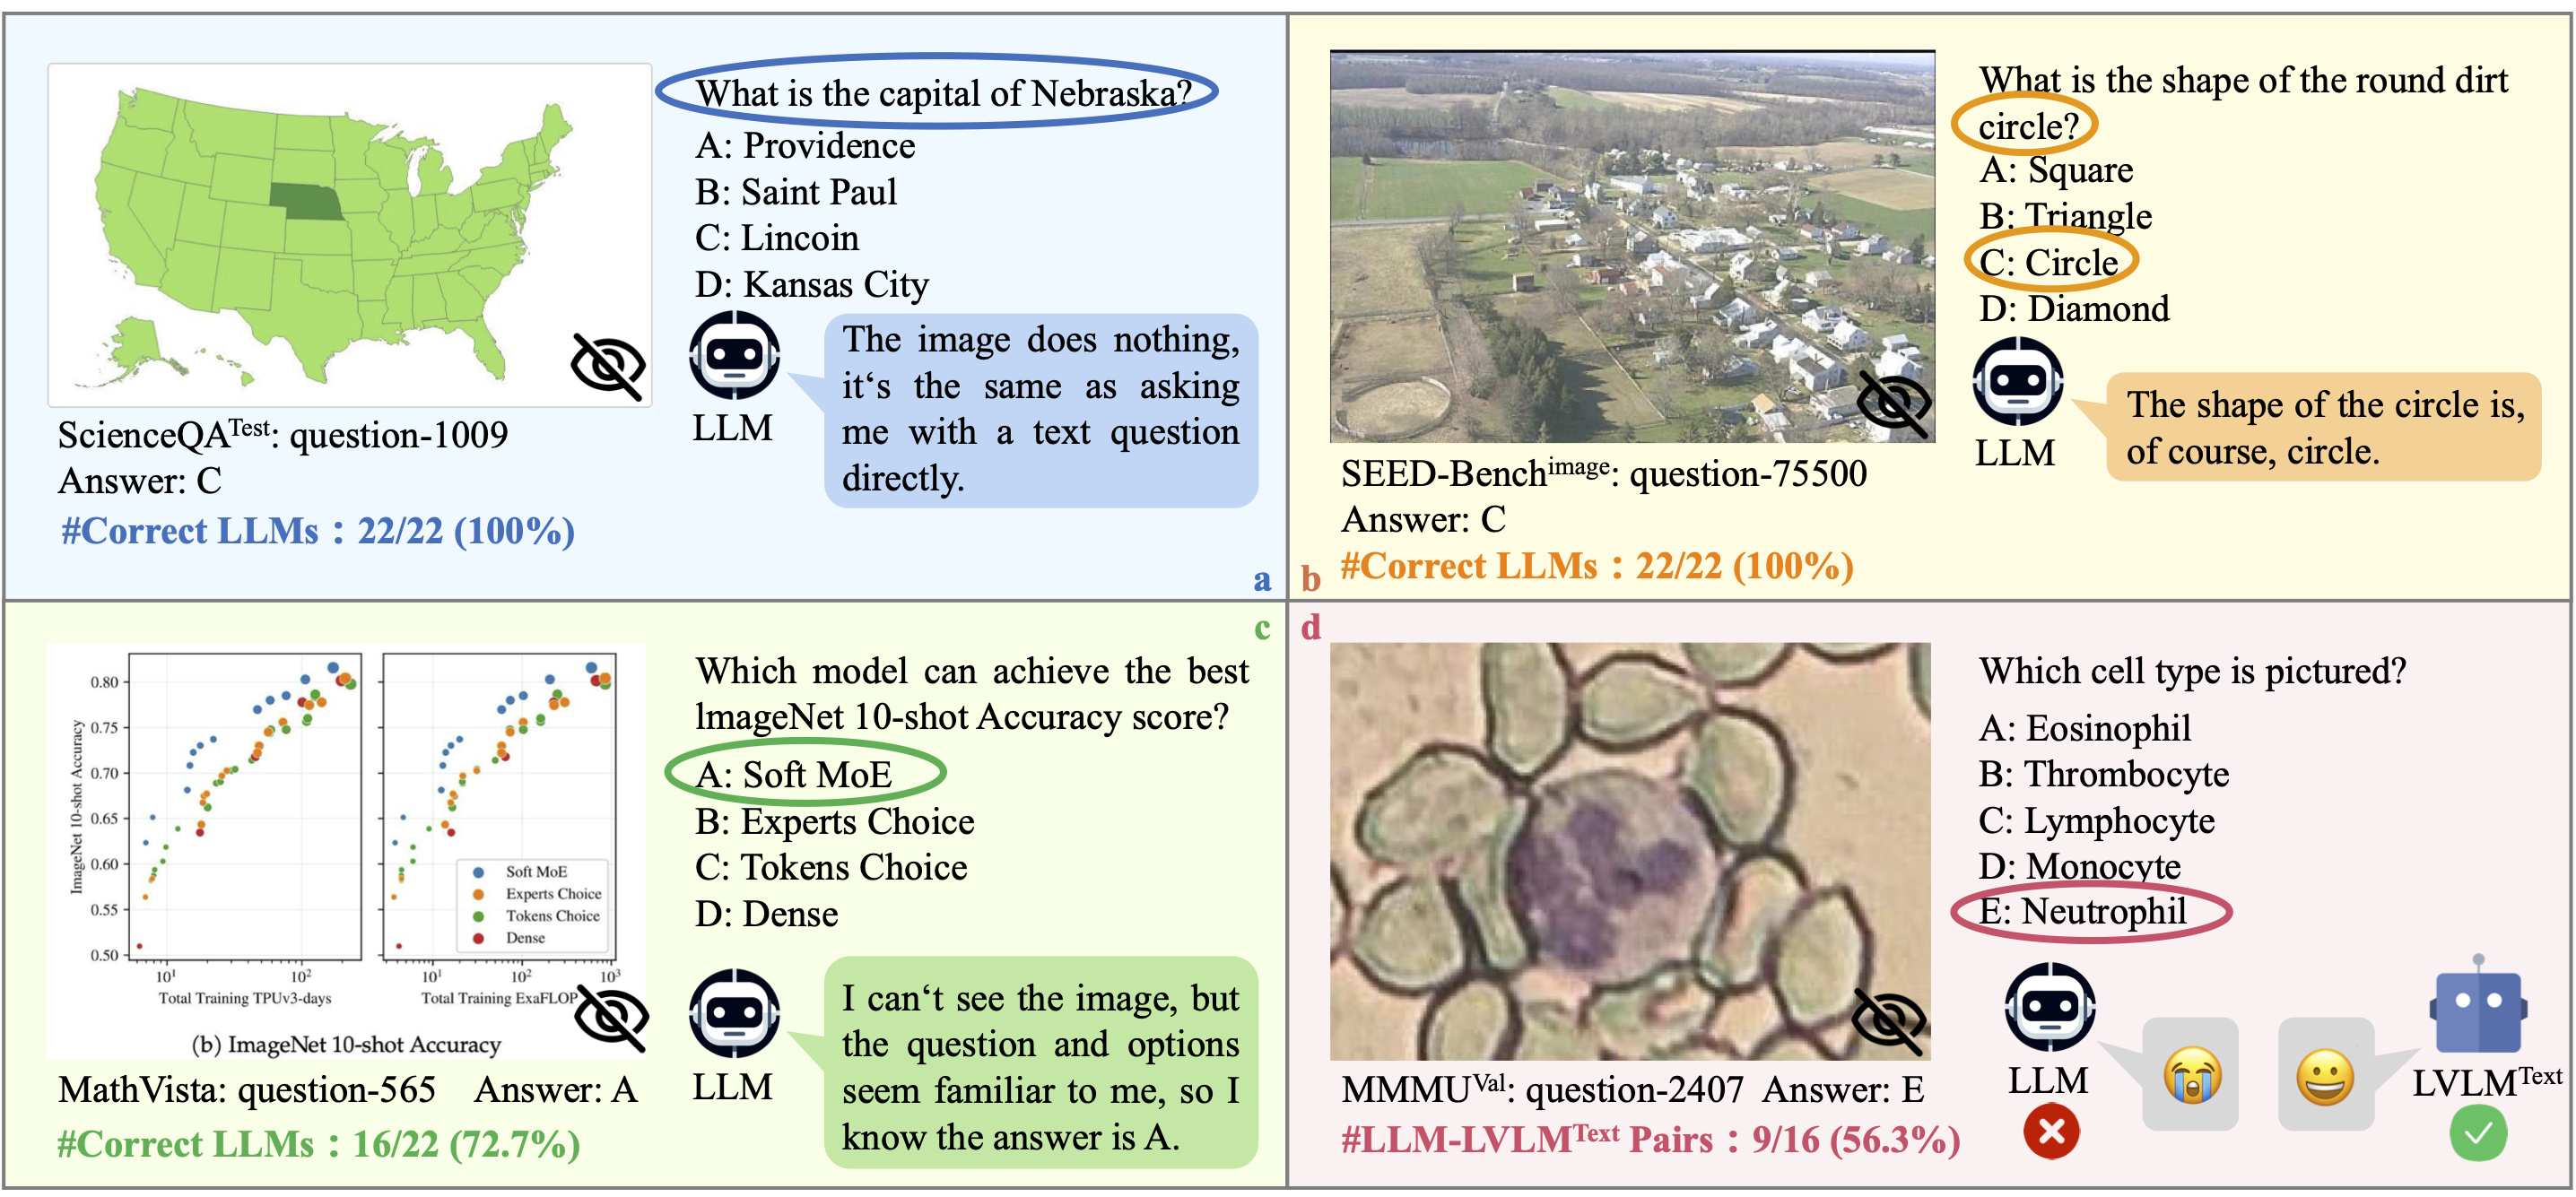
This repo contains evaluation code for the paper "MMMU: A Massive Multi-discipline Multimodal Understanding and Reasoning Benchmark for Expert AGI"
🔥🔥🔥 A curated list of papers on LLMs-based multimodal generation (image, video, 3D and audio).
A CLI tool/python module for generating images from text using guided diffusion and CLIP from OpenAI.
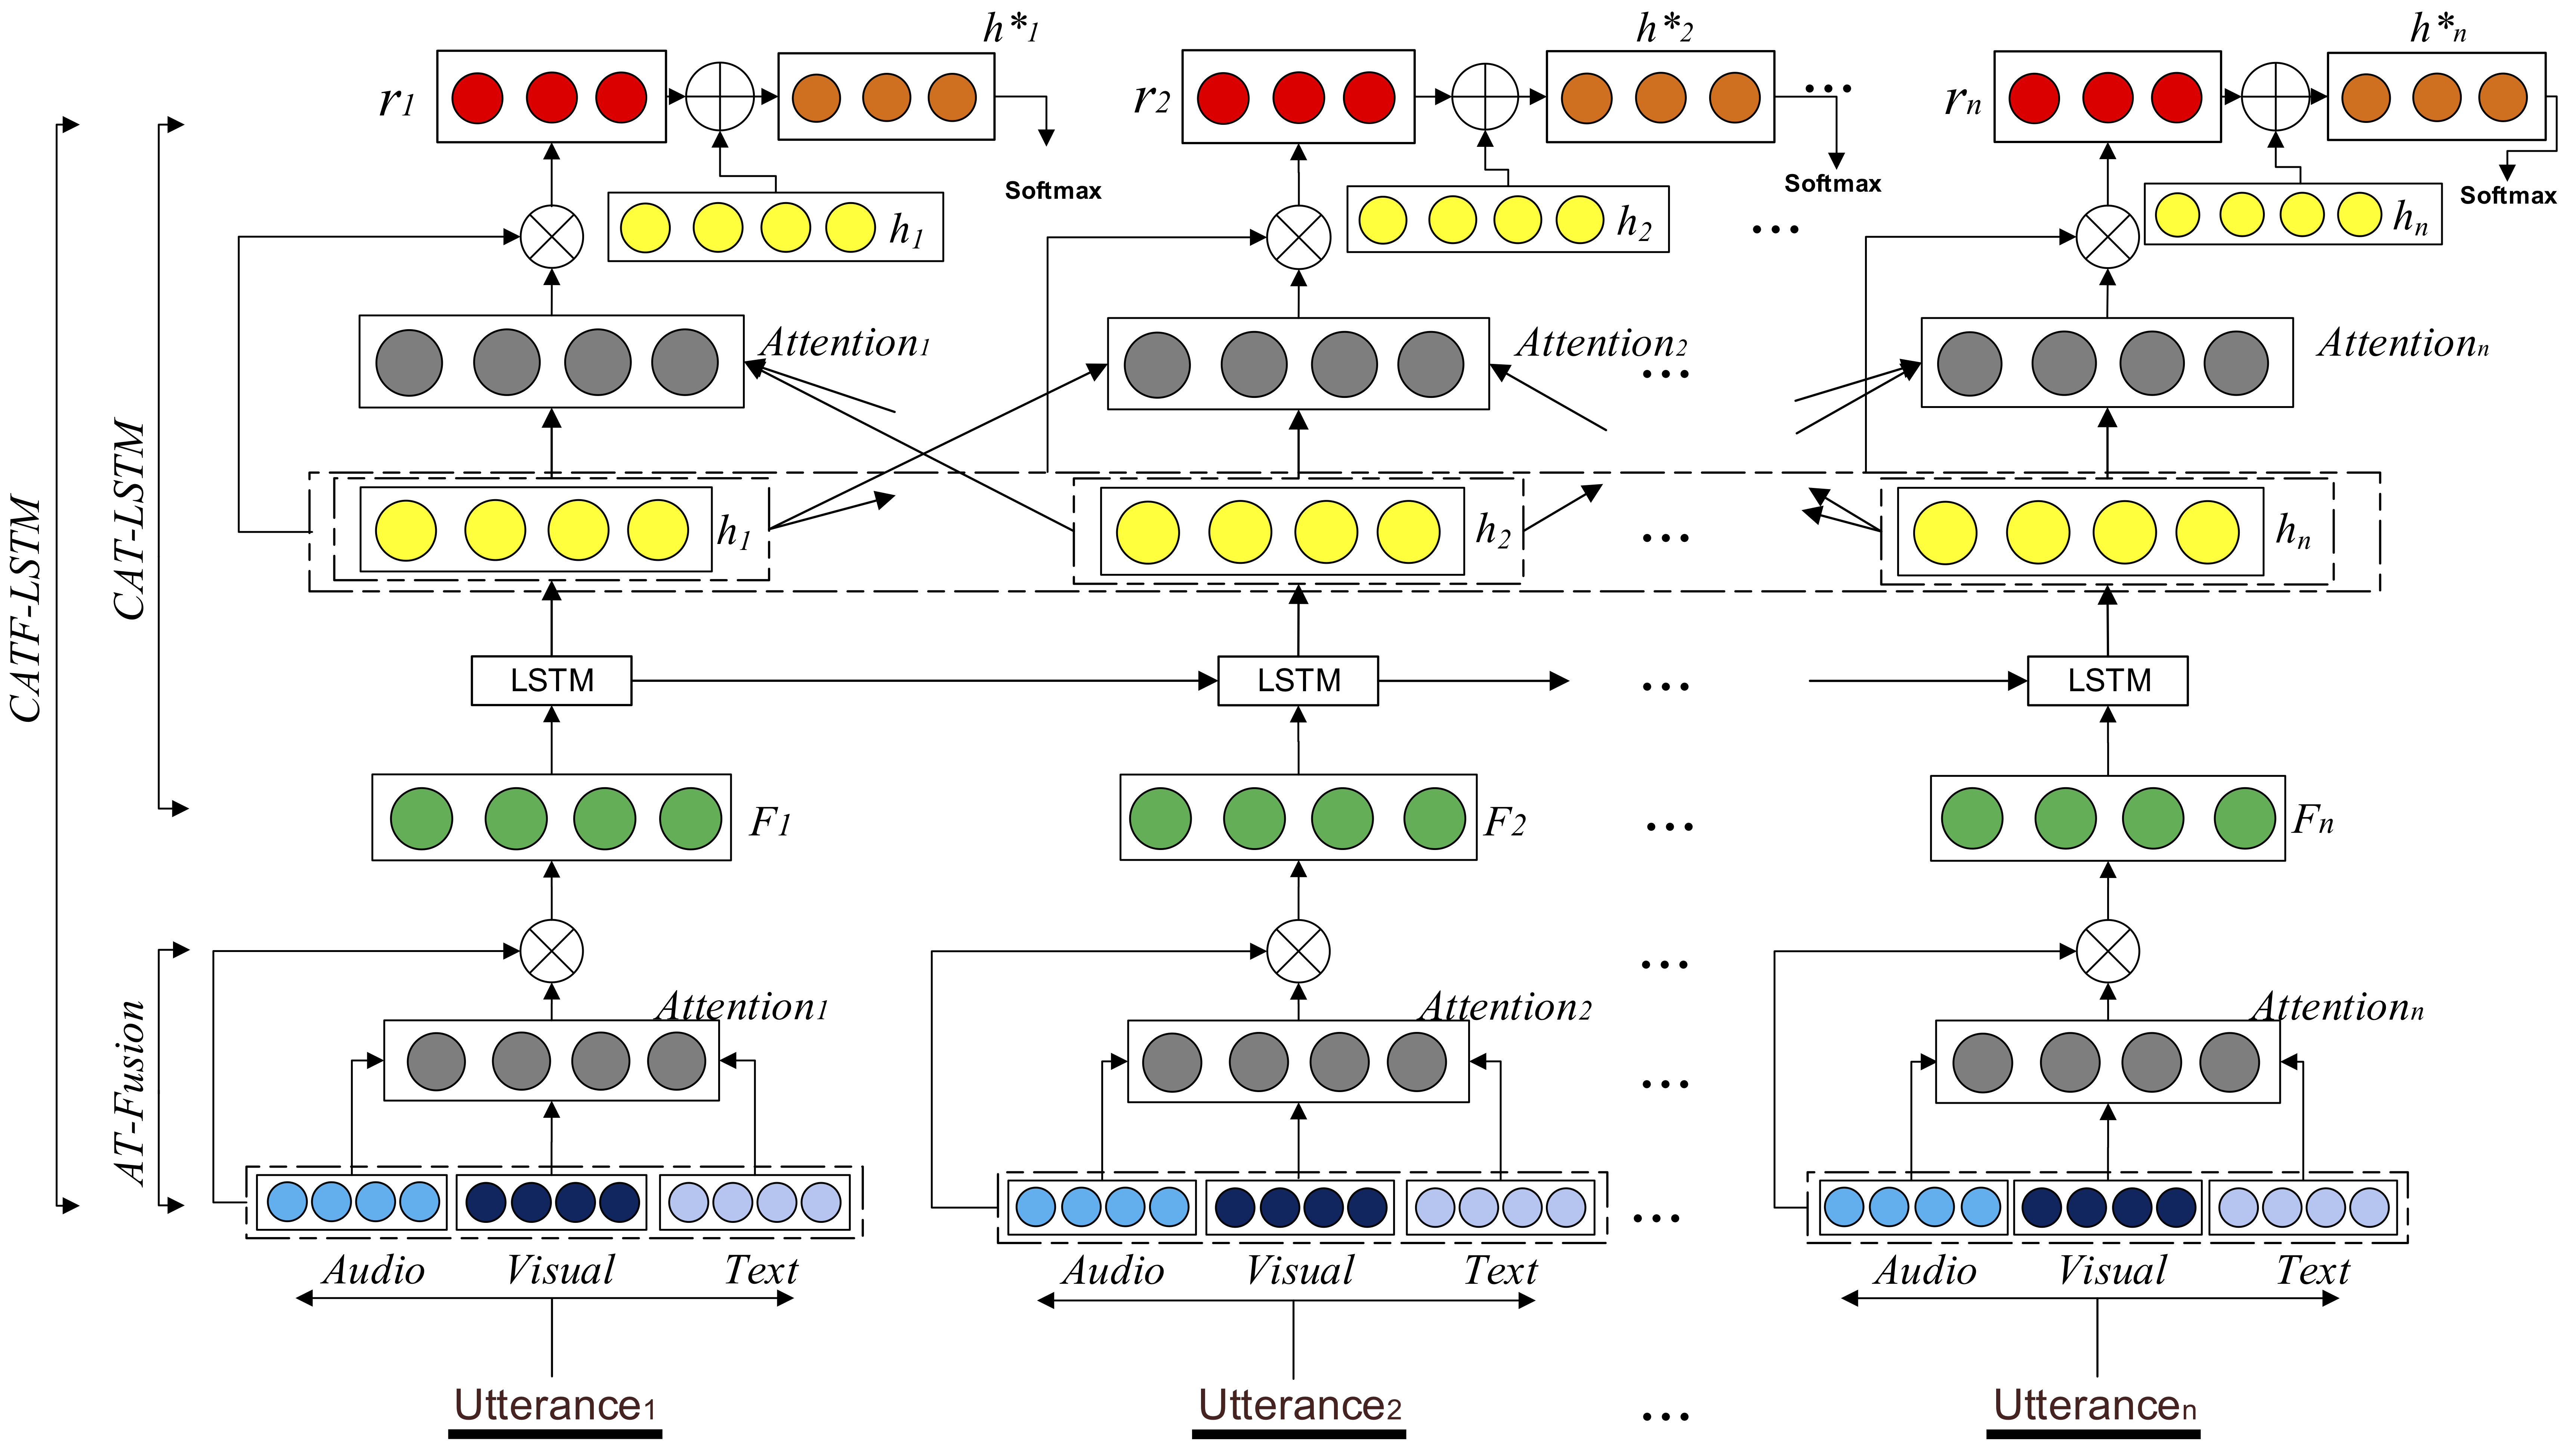
Attention-based multimodal fusion for sentiment analysis
My implementation of "Patch n’ Pack: NaViT, a Vision Transformer for any Aspect Ratio and Resolution"
[NeurIPS 2024] This repo contains evaluation code for the paper "Are We on the Right Way for Evaluating Large Vision-Language Models"
Swarming algorithms like PSO, Ant Colony, Sakana, and more in PyTorch 😊
Implementation of PALI3 from the paper PALI-3 VISION LANGUAGE MODELS: SMALLER, FASTER, STRONGER"
A deep learning framework for building multimodal multi-task learning systems.
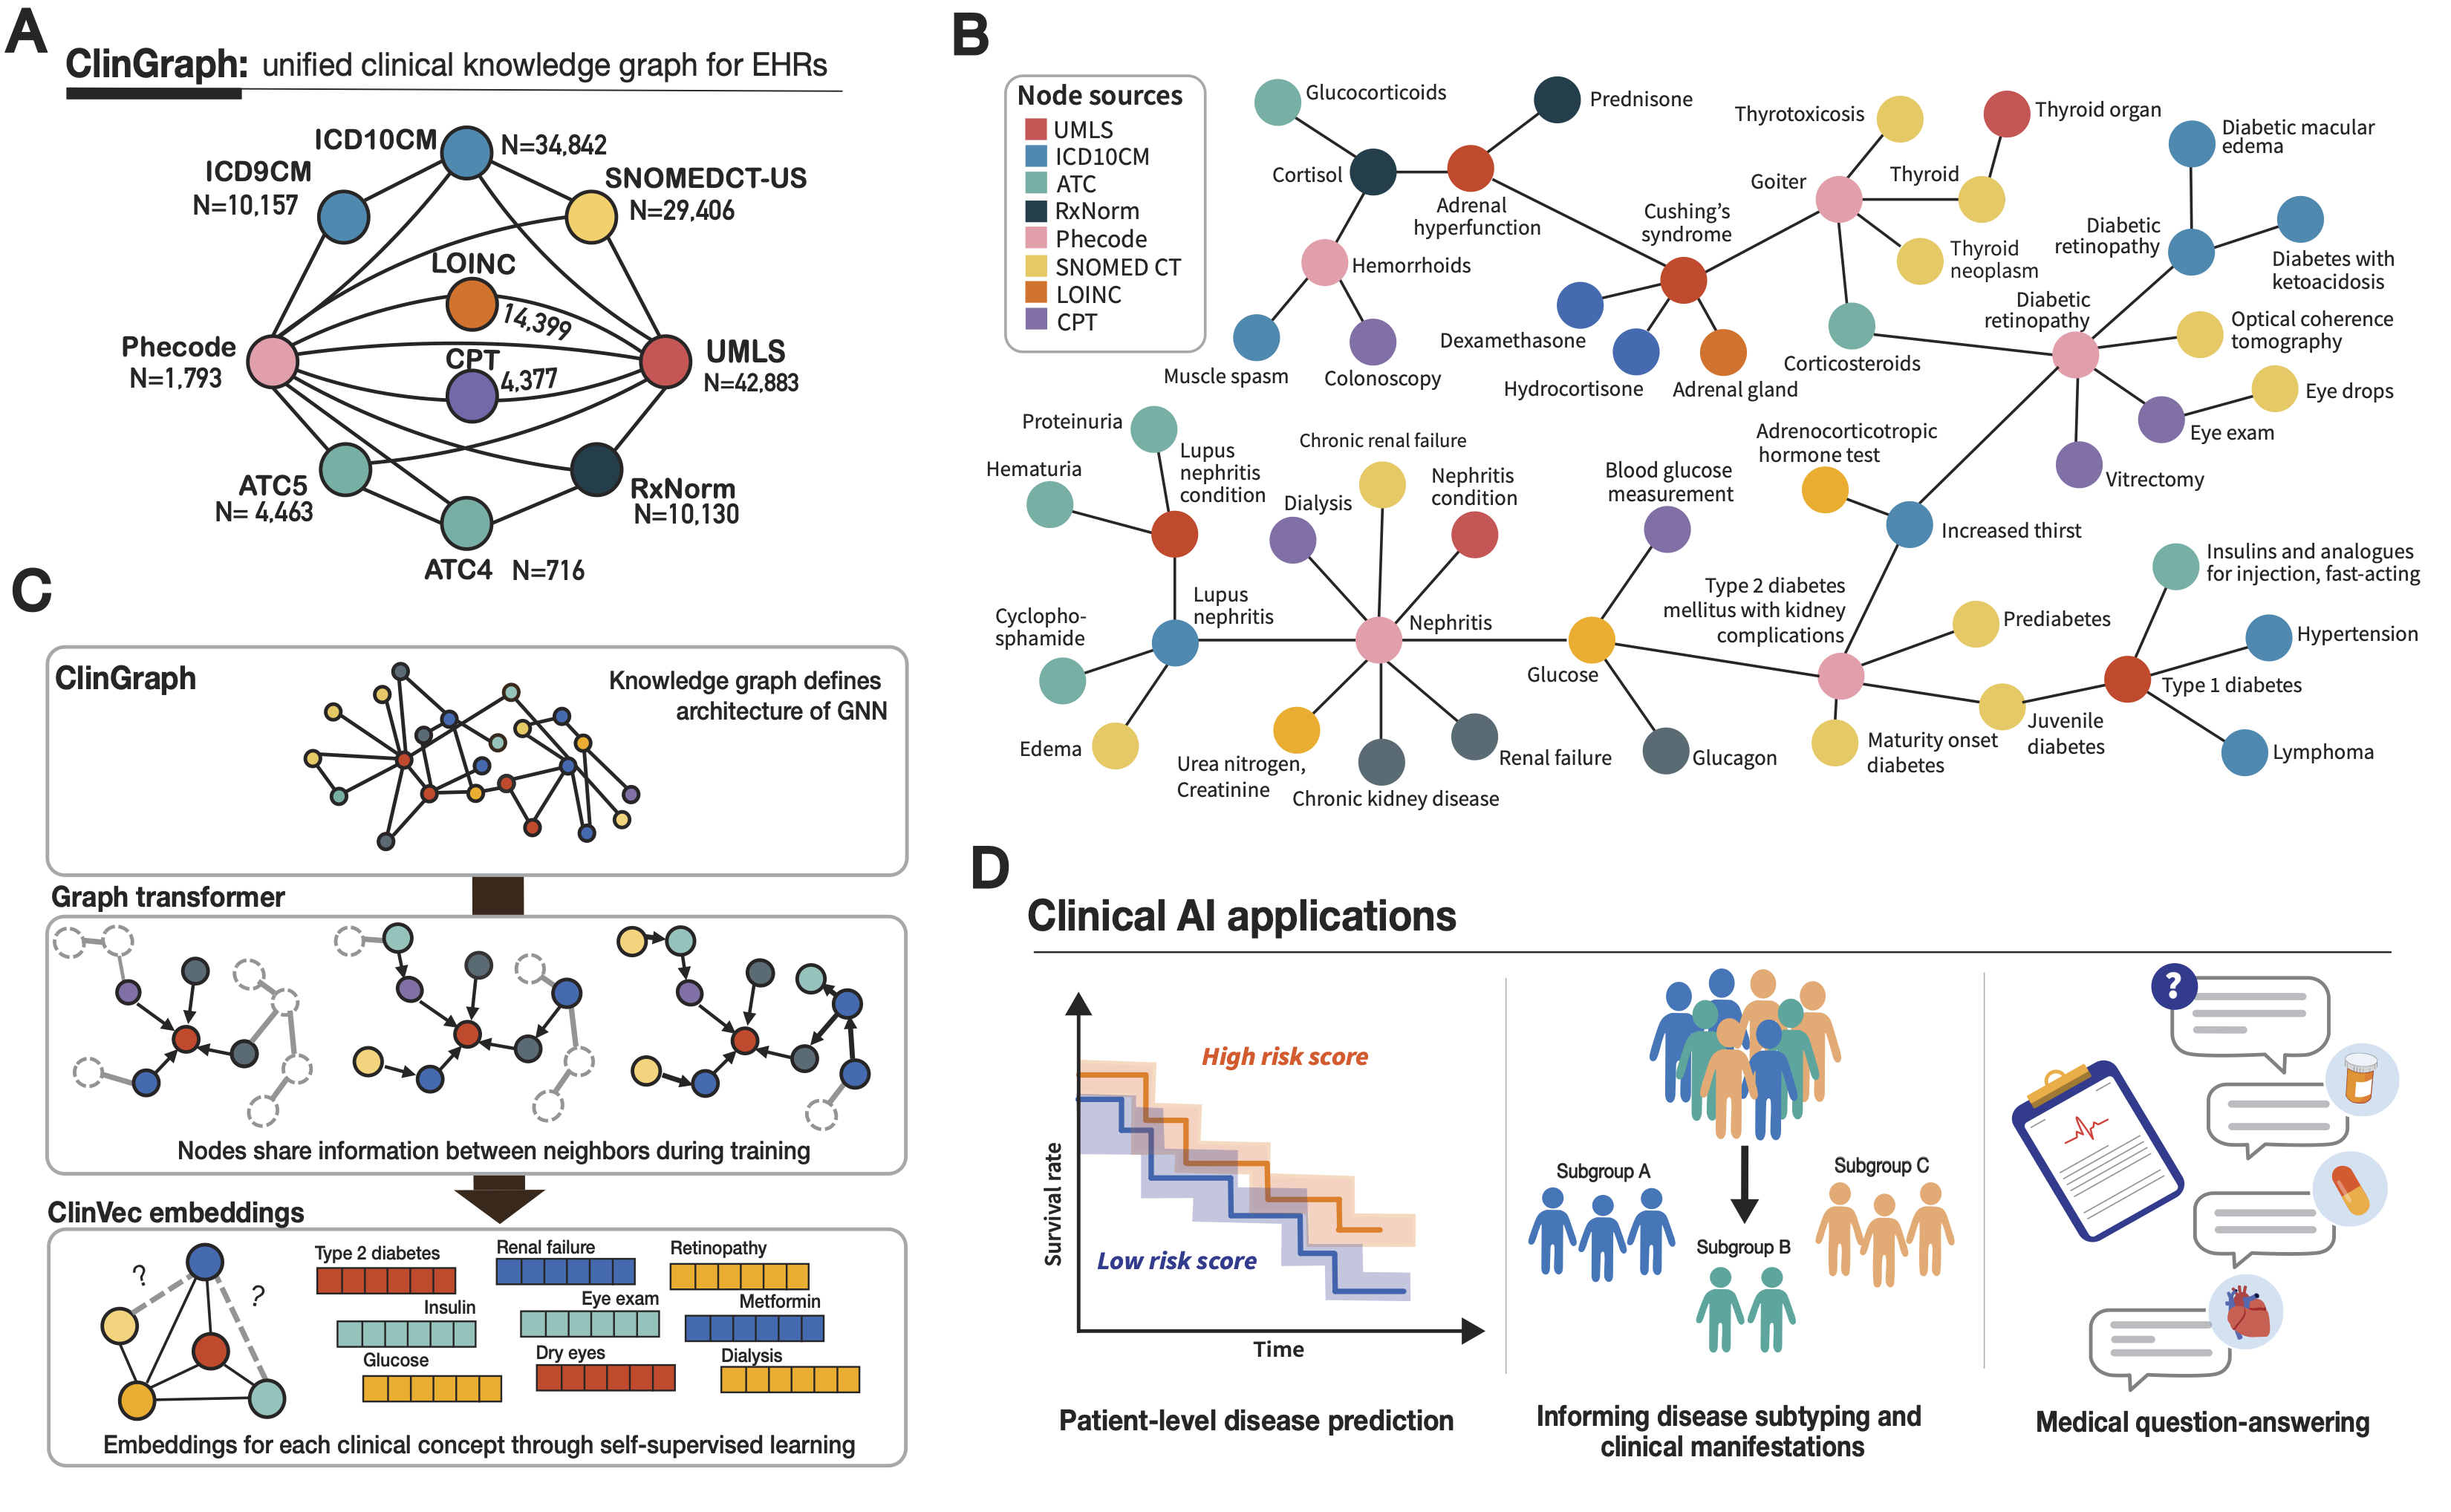
ClinVec: Unified Embeddings of Clinical Codes Enable Knowledge-Grounded AI in Medicine
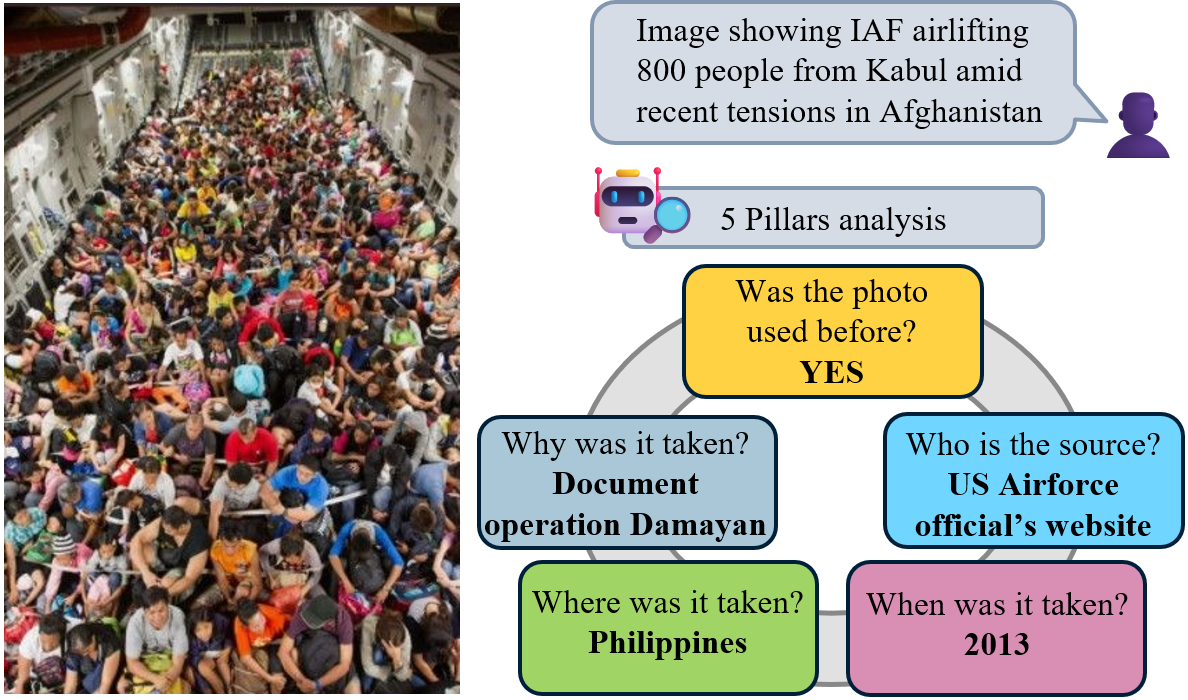
Code associated with the EMNLP 2024 Main paper: "Image, tell me your story!" Predicting the original meta-context of visual misinformation.
This repo contains evaluation code for the paper "MileBench: Benchmarking MLLMs in Long Context"
This repository contains a curated collection of notebooks for implementing state-of-the-art multimodal Vision-Language Models (VLMs).
This repository contains the source code for the paper "Improving the performance of unimodal dynamic hand gesture recognition with multimodal training"
[NeurIPS Datasets & Benchmarks 2025] SMMILE: An Expert-Driven Benchmark for Multimodal Medical In-Context Learning
The repository for the exclusive Daily Paper Club hosted at Agora every 10pm NYC time at this discord: https://discord.gg/Gnzh6dnzyz
Open-source RAG platform for pluggable document ingestion, multimodal indexing, hybrid search, tenant-isolated APIs, RBAC, citations, and MCP-based AI agent integration.
Tiny VLMs Lab is a Hugging Face Space and open-source project showcasing lightweight Vision-Language Models for image captioning, OCR, reasoning, and multimodal understanding. It offers a simple Gradio interface to upload images, query models, adjust generation settings, and export results in Markdown or PDF.
drex-062225-exp (document retrieval and extraction expert) model is a specialized fine-tuned version of docscopeocr-7b-050425-exp, optimized for document retrieval, content extraction, and analysis recognition. built on top of the qwen2.5-vl architecture.