PaddleOCR
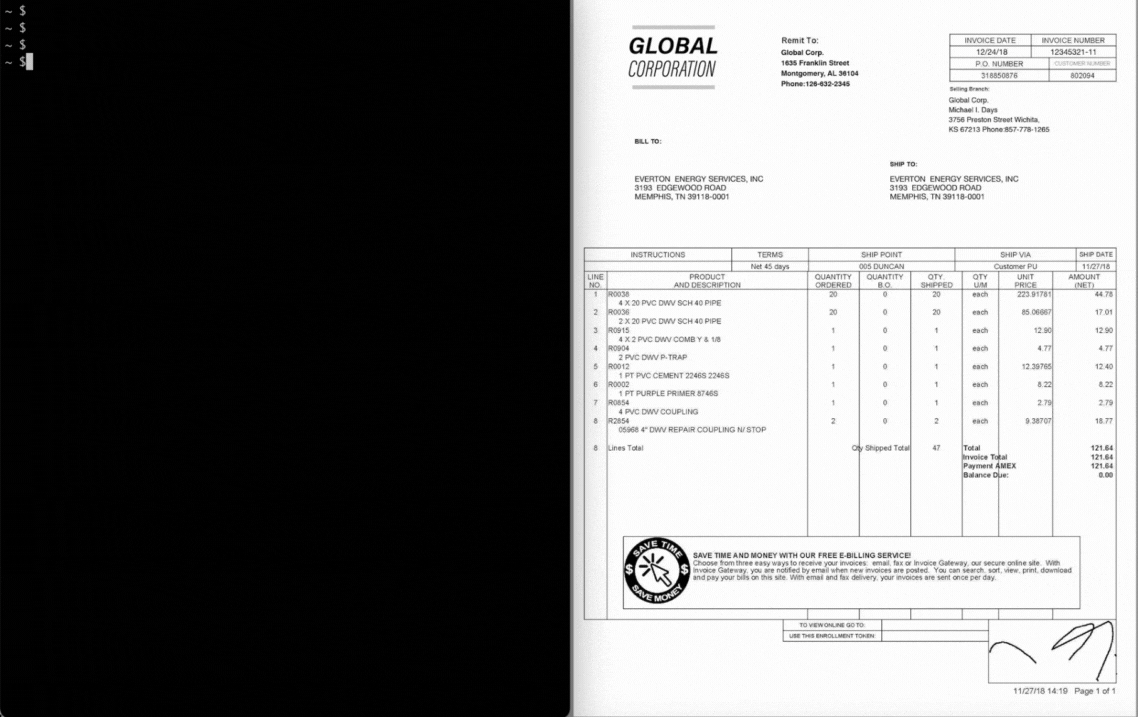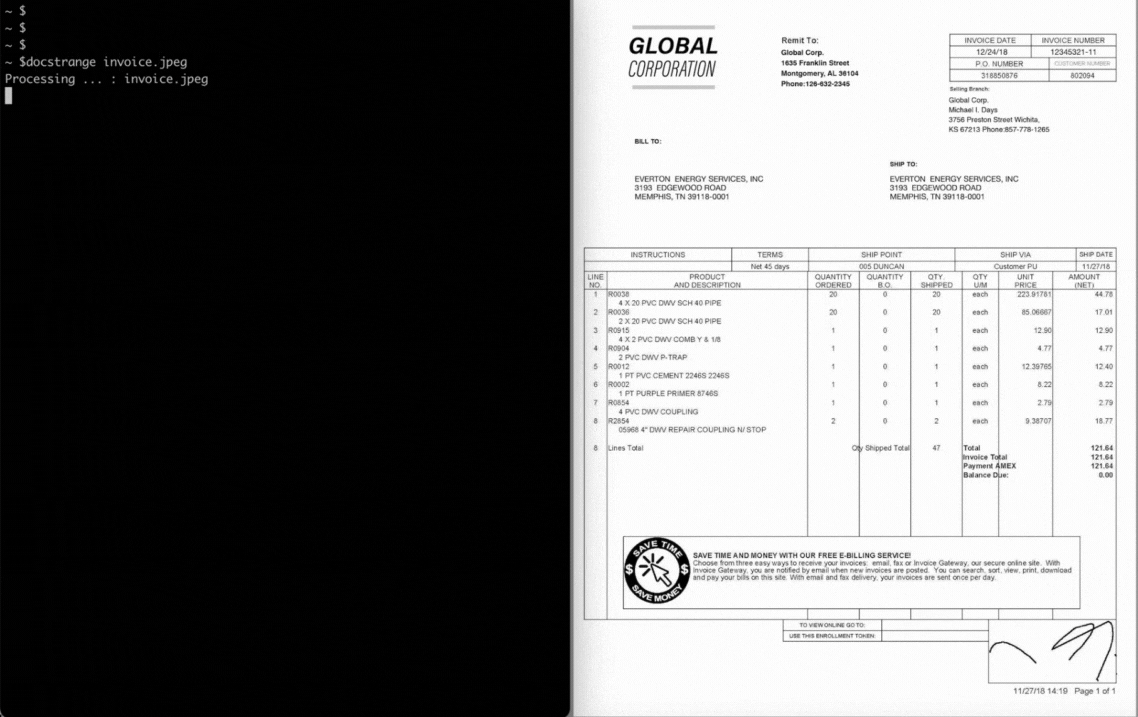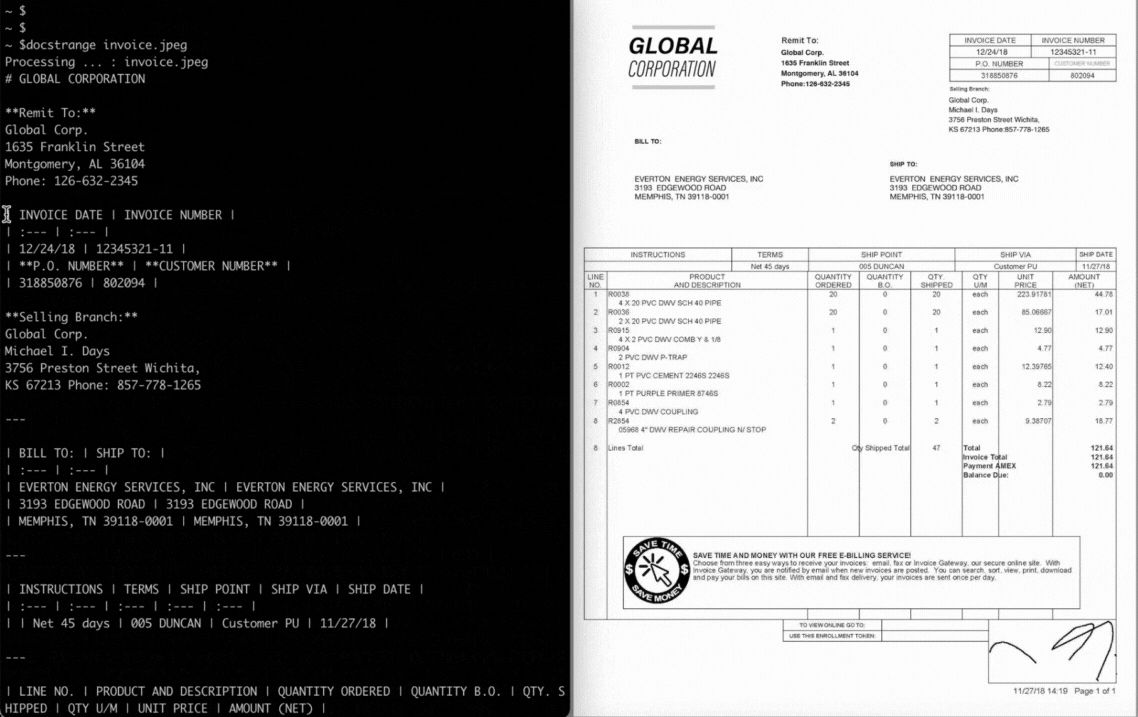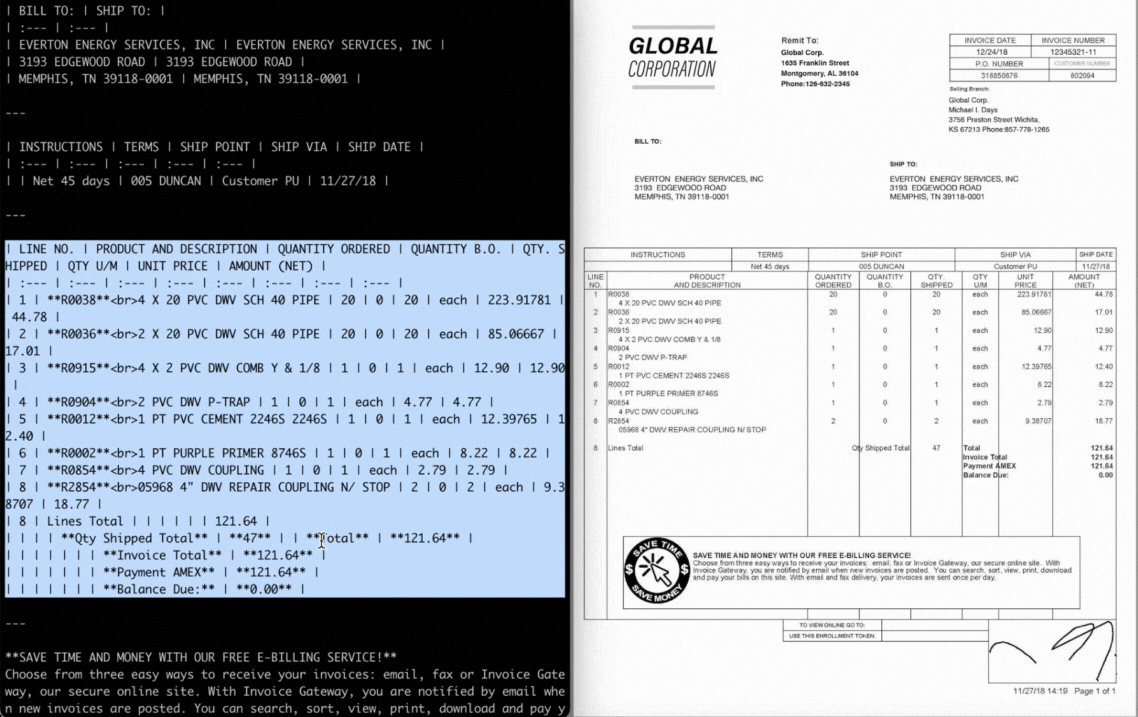
Turn any PDF or image document into structured data for your AI. A powerful, lightweight OCR toolkit that bridges the gap between images/PDFs and LLMs. Supports 100+ languages.
- 93k
- Python
- Apache-2.0
- 2 mo ago
Turn any PDF or image document into structured data for your AI. A powerful, lightweight OCR toolkit that bridges the gap between images/PDFs and LLMs. Supports 100+ languages.
PDF Parser for AI-ready data. Automate PDF accessibility. Open-source.
The official repo for “Dolphin: Document Image Parsing via Heterogeneous Anchor Prompting”, ACL, 2025.
PDF craft can convert PDF files into various other formats. This project will focus on processing PDF files of scanned books.
Extract and convert data from any document, images, pdfs, word doc, ppt or URL into multiple formats (Markdown, JSON, CSV, HTML) with intelligent structured data extraction and advanced OCR.
Dedoc is a library (service) for automate documents parsing and bringing to a uniform format. It automatically extracts content, logical structure, tables, and meta information from textual electronic documents. (Parse document; Document content extraction; Logical structure extraction; PDF parser; Scanned document parser; DOCX parser; HTML parser
A lightweight easy to use package to parse text from PDF files on client side without any server dependency.
Defensive PDF scanner using pdfid/pdf-parser with optional ClamAV and qpdf rewrite, wrapped in a Streamlit UI.