machine-learning-for-trading
Code for Machine Learning for Trading, 3rd edition — from data sourcing to live execution.
- 22k
- Jupyter Notebook
- MIT
- 5 h ago
Code for Machine Learning for Trading, 3rd edition — from data sourcing to live execution.
Easily fine-tune (SFT/RL), evaluate, and deploy Qwen, Gemma, or any open agentic LLM/VLM!
Data processing for and with foundation models! 🍎 🍋 🌽 ➡️ ➡️🍸 🍹 🍷
Build, Evaluate, and Optimize AI Systems. Includes evals, RAG, agents, fine-tuning, synthetic data generation, dataset management, MCP, and more.
Mimesis is a Python library for generating fake but realistic data in multiple languages and locales.
A procedural Blender pipeline for photorealistic training image generation
Distilabel is a framework for synthetic data and AI feedback for engineers who need fast, reliable and scalable pipelines based on verified research papers.
SDG is a specialized framework designed to generate high-quality structured tabular data.
🎨 NeMo Data Designer: Generate high-quality synthetic data from scratch or from seed data.
Synthadoc: An open-source LLM knowledge compilation engine that turns raw documents into structured, local-first wikis. A transparent, human-readable alternative to traditional RAG, which can be self-managed and self-improved without the use of any tools.
Synthetic data curation for post-training and structured data extraction
Synthetic data generators for tabular and time-series data
[ICLR 2025] Alignment Data Synthesis from Scratch by Prompting Aligned LLMs with Nothing. Your efficient and high-quality synthetic data generation pipeline!
Generate High-Quality Synthetics, Train, Measure, and Evaluate in a Single Pipeline
Curated list of open source tooling for data-centric AI on unstructured data.
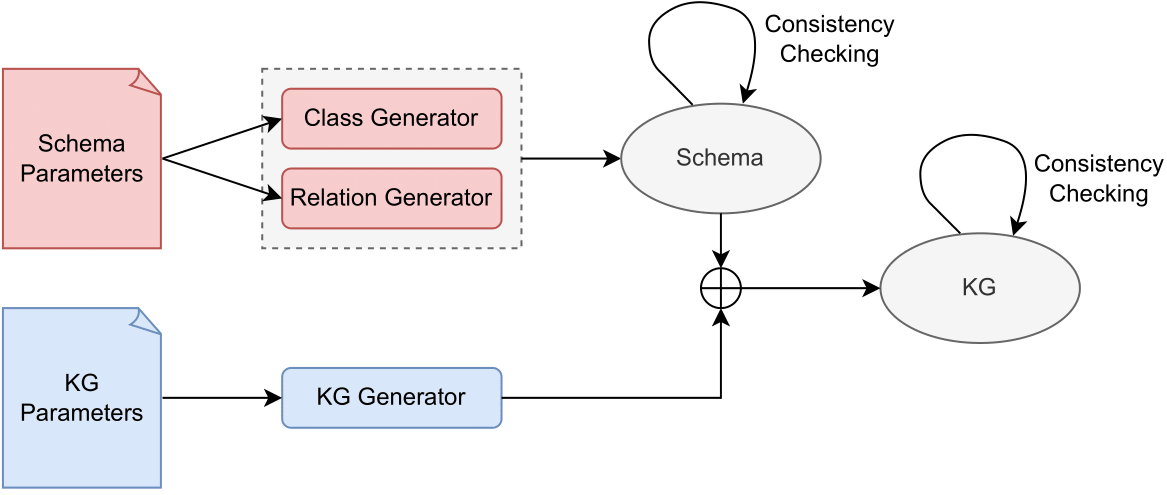
Configurable Generation of Synthetic Schemas and Knowledge Graphs at Your Fingertips
[CVPR'26 Highlight] Ditto: Scaling Instruction-Based Video Editing with a High-Quality Synthetic Dataset
Augmentation pipeline for rendering synthetic paper printing, faxing, scanning and copy machine processes
[ICML 2023] The official implementation of the paper "TabDDPM: Modelling Tabular Data with Diffusion Models"
Design, conduct and analyze results of AI-powered surveys and experiments. Simulate social science and market research with large numbers of AI agents and LLMs.
Generate relevant synthetic data quickly for your projects. The Databricks Labs synthetic data generator (aka `dbldatagen`) may be used to generate large simulated / synthetic data sets for test, POCs, and other uses in Databricks environments including in Delta Live Tables pipelines
[IROS 2020] se(3)-TrackNet: Data-driven 6D Pose Tracking by Calibrating Image Residuals in Synthetic Domains
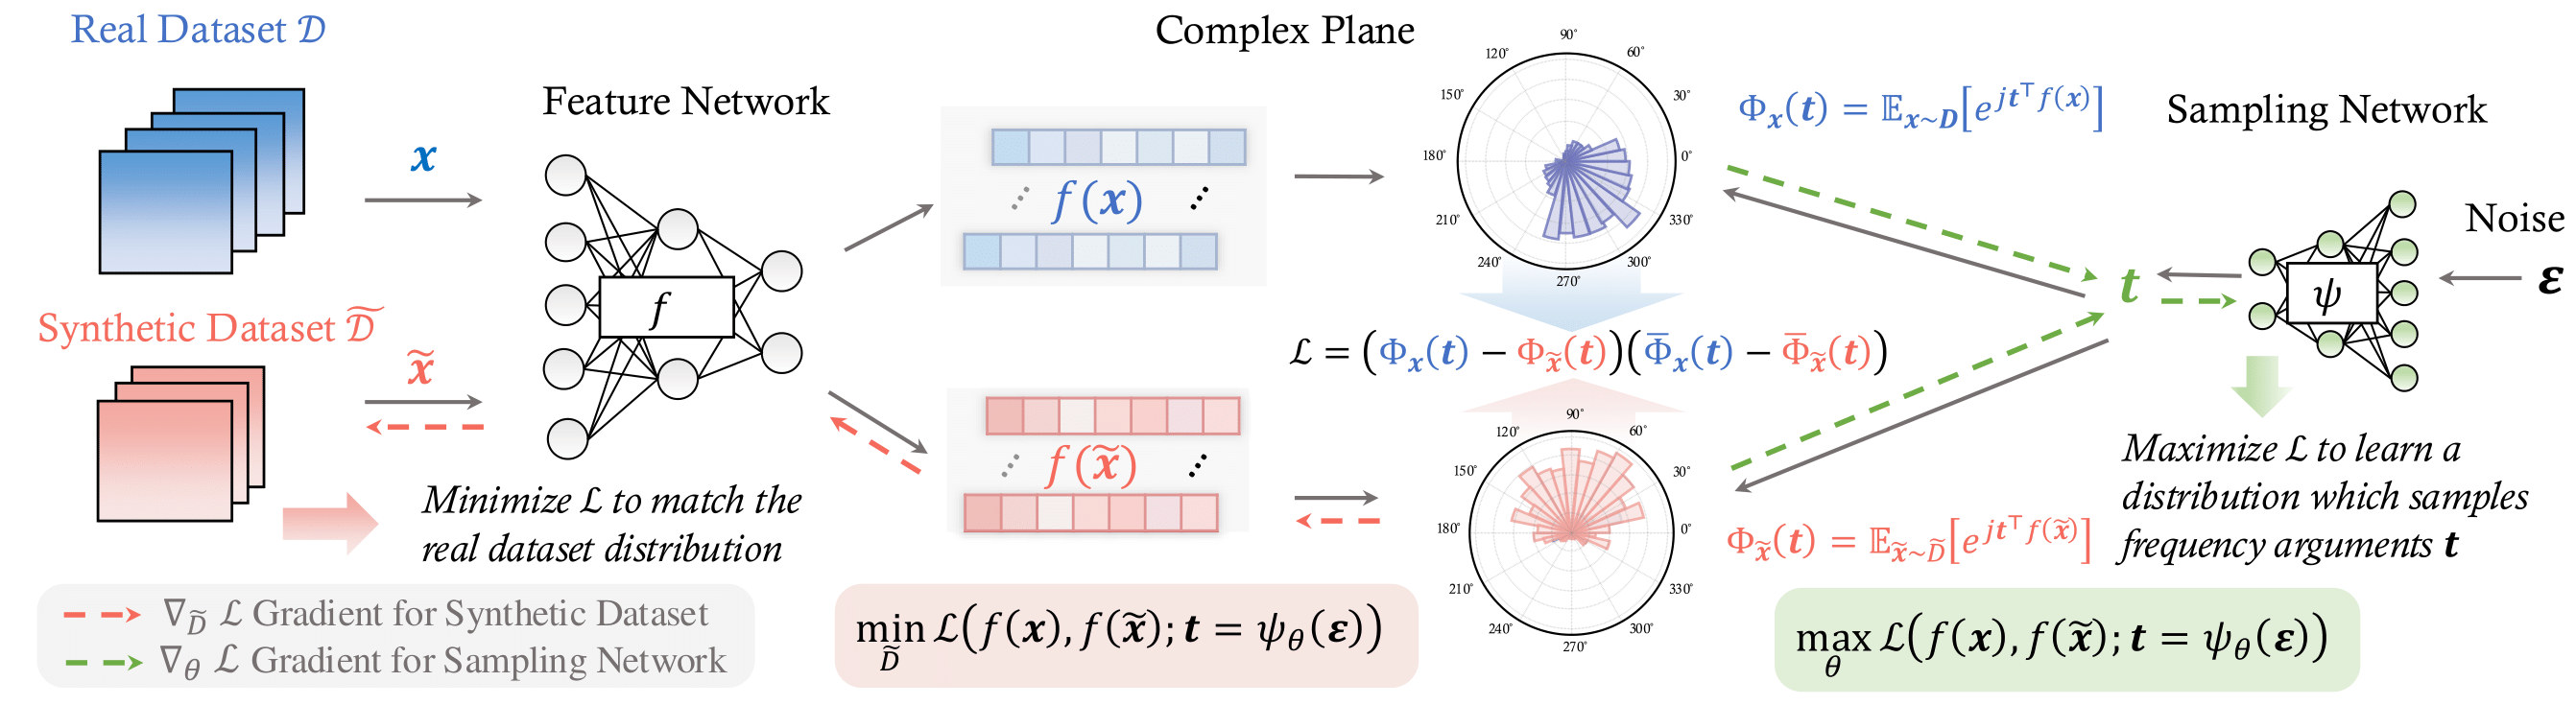
Official PyTorch implementation of the paper "Dataset Distillation with Neural Characteristic Function: A Minmax Perspective" (NCFM) in CVPR 2025 (Full Score, Highlight).
This repository contains the collection of UCI (real-life) datasets and Synthetic (artificial) datasets (with cluster labels and MATLAB files) ready to use with clustering algorithms.
Open-Source Software, Tutorials, and Research on Data-Centric AI 🤖
AgML is a centralized framework for agricultural machine learning. AgML provides access to public agricultural datasets for common agricultural deep learning tasks, with standard benchmarks and pretrained models, as well the ability to generate synthetic data and annotations.
Automatic speech recognition model, used with transformers.
Physical AI scenarios for Cosmos and Isaac validation
Runs in the browser on Hugging Face
Differentially private in-context learning (AAAI 2026)
Runs in the browser on Hugging Face
Predict elevator failure from 60 min of sensor data
Runs in the browser on Hugging Face