Soup
Fine-tune LLMs from one YAML. Layer streaming trains an 8B model on a 4 GB laptop GPU.
- 11k
- Python
- Apache-2.0
- 11 h ago
Fine-tune LLMs from one YAML. Layer streaming trains an 8B model on a 4 GB laptop GPU.
Easily fine-tune (SFT/RL), evaluate, and deploy Qwen, Gemma, or any open agentic LLM/VLM!
MedicalGPT: Training Your Own Medical GPT Model with ChatGPT Training Pipeline. 训练医疗大模型,实现了包括增量预训练(PT)、有监督微调(SFT)、RLHF、DPO、ORPO、GRPO。
🚀 An open-source, hands-on curriculum bridging the gap from basic RL concepts to LLM alignment, RLVR, and advanced Agentic systems.
Align Anything: Training All-modality Model with Feedback
[ICCV 2025] Official code of DeepMesh: Auto-Regressive Artist-mesh Creation with Reinforcement Learning
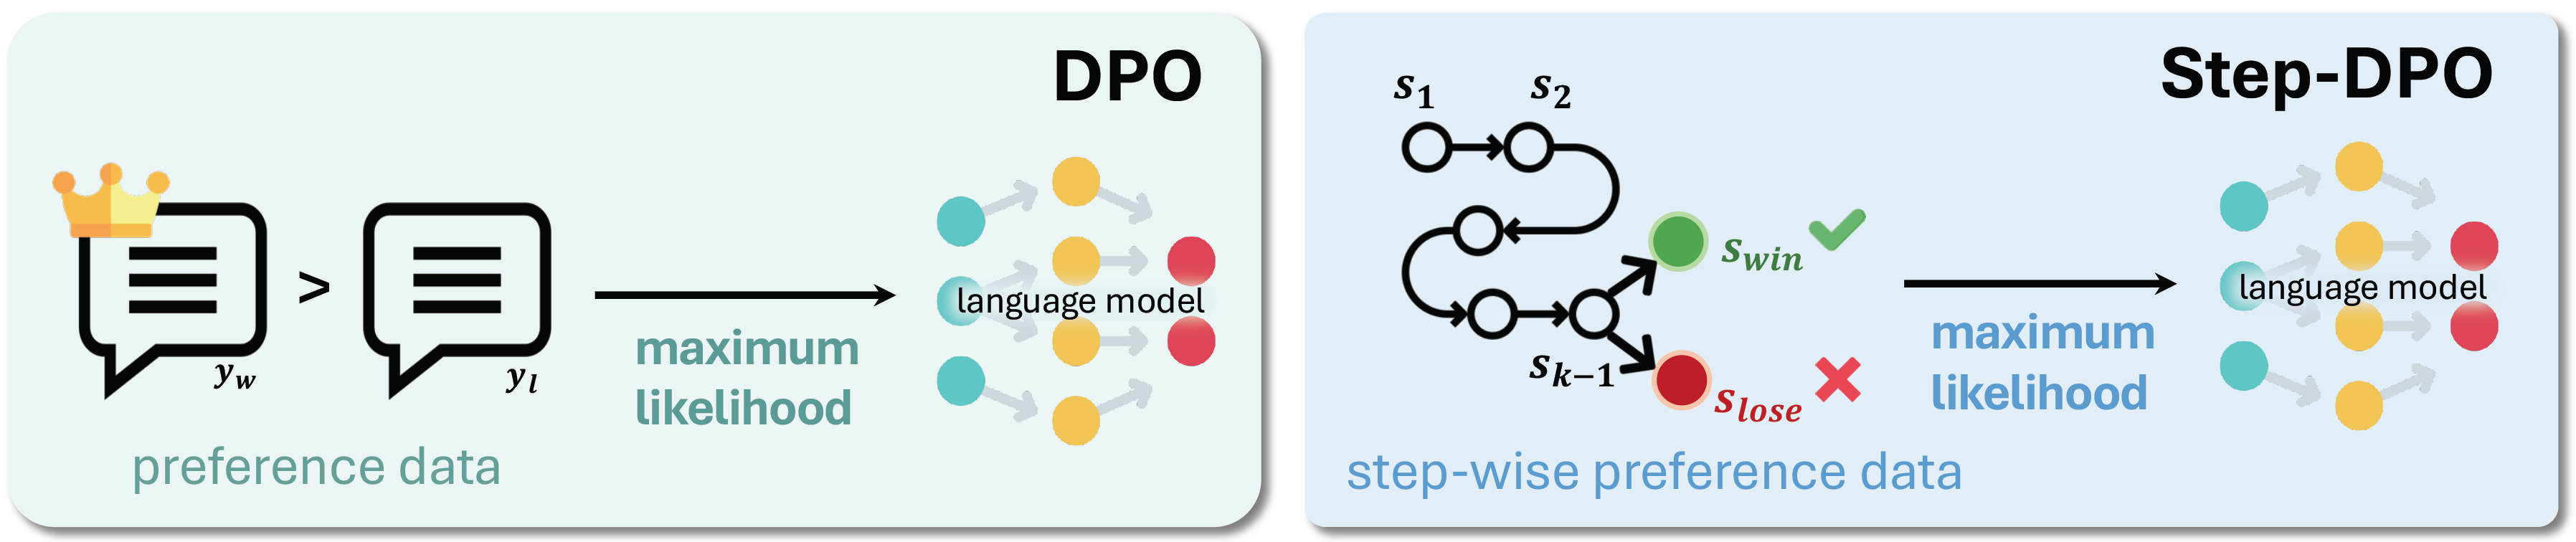
Implementation for "Step-DPO: Step-wise Preference Optimization for Long-chain Reasoning of LLMs"
Zero-friction LLM fine-tuning skill for Claude Code, Gemini CLI & any ACP agent. Unsloth on NVIDIA · TRL+MPS/MLX on Apple Silicon. Automates env setup, LoRA training (SFT, DPO, GRPO, vision), post-hoc GRPO log diagnostics, evaluation, and export end-to-end. Part of the Gaslamp AI platform.
从 MiniMind 源码读起,再延伸到现代大模型技术体系的中文学习笔记。主线逐行精读预训练 / SFT / DPO / PPO / GRPO 与训练机制;附录 17 篇进阶卷覆盖量化、投机解码、RLHF 全景、模型代际史等 MiniMind 没涉及、但进阶绕不开的主题。
Notus is a collection of fine-tuned LLMs using SFT, DPO, SFT+DPO, and/or any other RLHF techniques, while always keeping a data-first approach
动手学大模型全栈:CS336 中文精讲 · PyTorch 手搓 Transformer · 单卡复现 Pretrain/SFT/LoRA/DPO/GRPO/RLVR · PEFT/Agent/RAG 落地(含真实实验、曲线与复现脚本)
CHATS: Combining Human-Aligned Optimization and Test-Time Sampling for Text-to-Image Generation (ICML2025)
Human-feedback and data-governance infrastructure for RSI research: annotation, review, provenance and frozen dataset candidates.
基于Qwen2+SFT+DPO的医疗问答系统,项目中使用了自定义的 SFTTrainer/DPOTrainer/TRPOTrainer用于训练,其次,项目还调用各种知识库工具(neo4j, milvus, LDA, 等)进行自动化训练数据生成。另外,使用 vllm 用于推理和部署训好的模型, 该模型会通过 vllm API 来接入一个基于 embedder + Reranker 的 RAG 系统。另外还参考 MDAgents 论文实现了一个多智能体会诊系统,同样也支持 vllm api 接入。
A travel agent based on Qwen2.5, fine-tuned by SFT + DPO/PPO/GRPO using traveling question-answer dataset, a mindmap can be output using the response. A RAG system is build upon the tuned qwen2, using Prompt-Template + Tool-Use + Chroma embedding database + LangChain
This training offers an intensive exploration into the frontier of reinforcement learning techniques with large language models (LLMs). We will explore advanced topics such as Reinforcement Learning with Human Feedback (RLHF), Reinforcement Learning from AI Feedback (RLAIF), Reasoning LLMs, and demonstrate practical applications such as fine-tuning
Complete TensorFlow NLP Guide 2026: BERT, GPT and LLM Downstream Tasks Explained
Generate conversational, tool-calling, structured-output, and preference datasets — easily and at scale
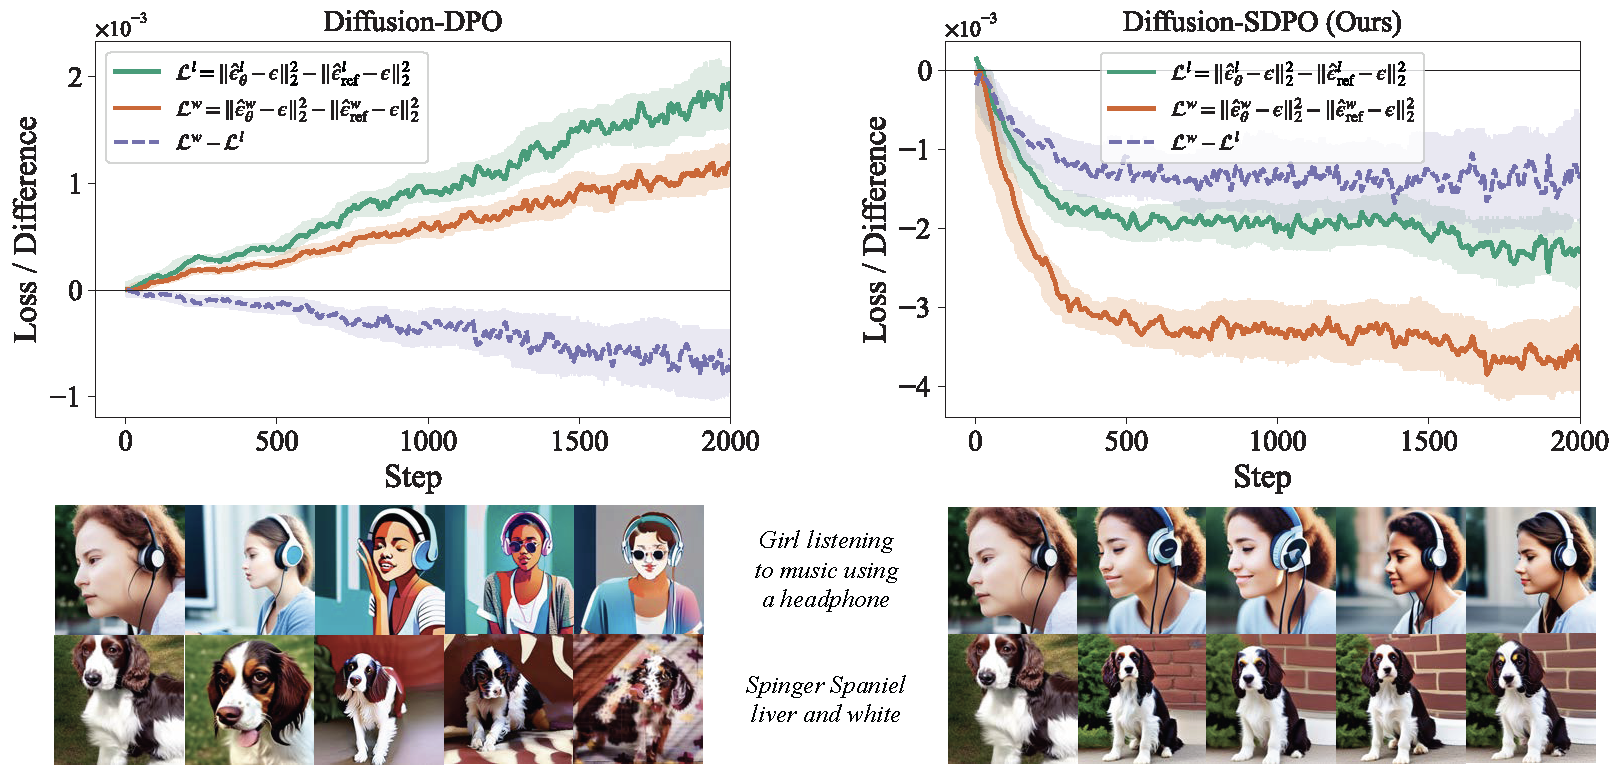
Diffusion-SDPO: Safeguarded Direct Preference Optimization for Diffusion Models
Asking for What Was Never Requested: horizontal and vertical proactivity in LLM agents. Need-graph metrics (no LLM judge) and Q&D, which trains a questioner from the consequences of its questions.
Your RL second brain: 34 source-cited topics from Q-learning to GRPO and agentic RL, kept fresh monthly. Obsidian vault + AI agent layer, Brainstein SSS+.
A curated list of reinforcement learning, preference optimization, and reward-driven post-training and alignment methods for video generation.
A minimal LLM pipeline that runs on a laptop, written from scratch in PyTorch and to be read: tokenizer, pretraining, inference, fine-tuning, RLHF and RLVR, with measured results and an interactive website.
20 runnable multi-GPU notebooks for Kaggle 2xT4: SFT, LoRA/QLoRA, DPO/GRPO alignment, and agent-trace eval
Async agent pipeline for LLM post-training: PyTorch preference losses (DPO/ORPO/GRPO) + simulated runs
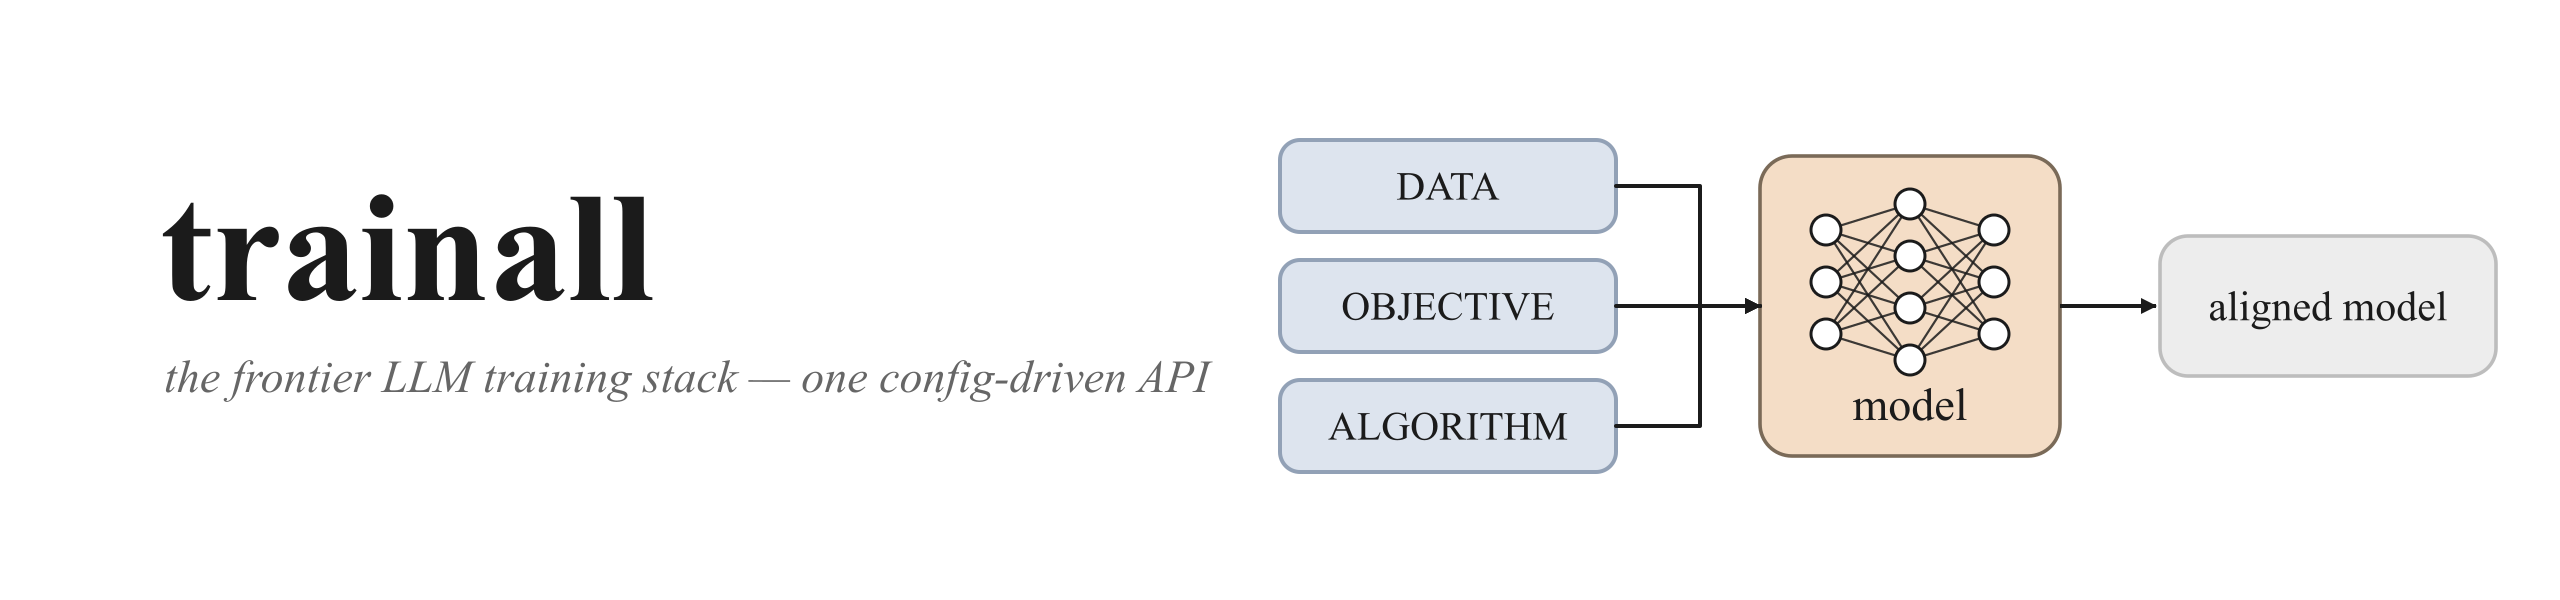
One library for the frontier LLM training stack — pre-training, CPT/DAPT, SFT, DPO/IPO/KTO/ORPO/SimPO/CPO, RLHF, RLVR+GRPO, agentic RL, distillation & self-play, LoRA/QLoRA — behind one config-driven, registry-based API. import trainall is torch-free.
Context Distillation via QLoRA SFT & DPO to eliminate 99.5% of system prompt bloat, shrink KV-cache by 15.3x, and accelerate vLLM TTFT latency by up to 17.5x
DPO on Qwen2.5-0.5B with HH-RLHF: hand-written loss in PyTorch, numerically tied out against TRL
A sketch-guided multi-objective alignment framework for improving the correctness, efficiency, and algorithmic reasoning of code language models.