VLX-Seek
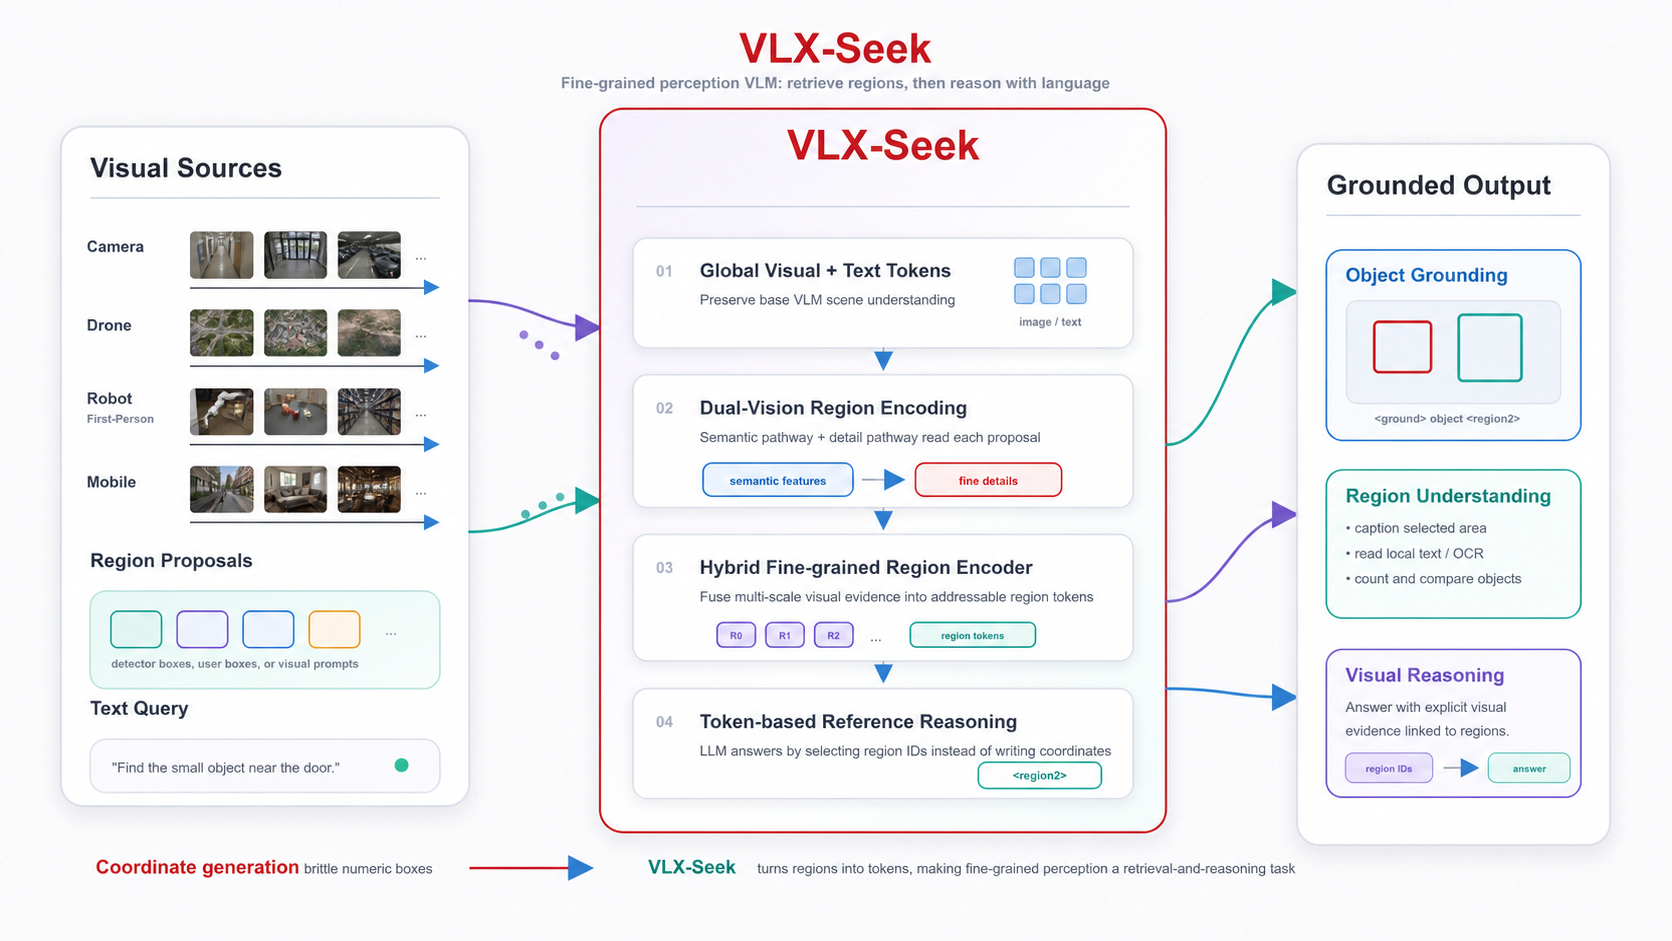
VLX-Seek is an efficient VLM that grounds fine-grained visual targets with high precision in wild environments.
- 2.3k
- Python
- 7 d ago
VLX-Seek is an efficient VLM that grounds fine-grained visual targets with high precision in wild environments.
awesome grounding: A curated list of research papers in visual grounding
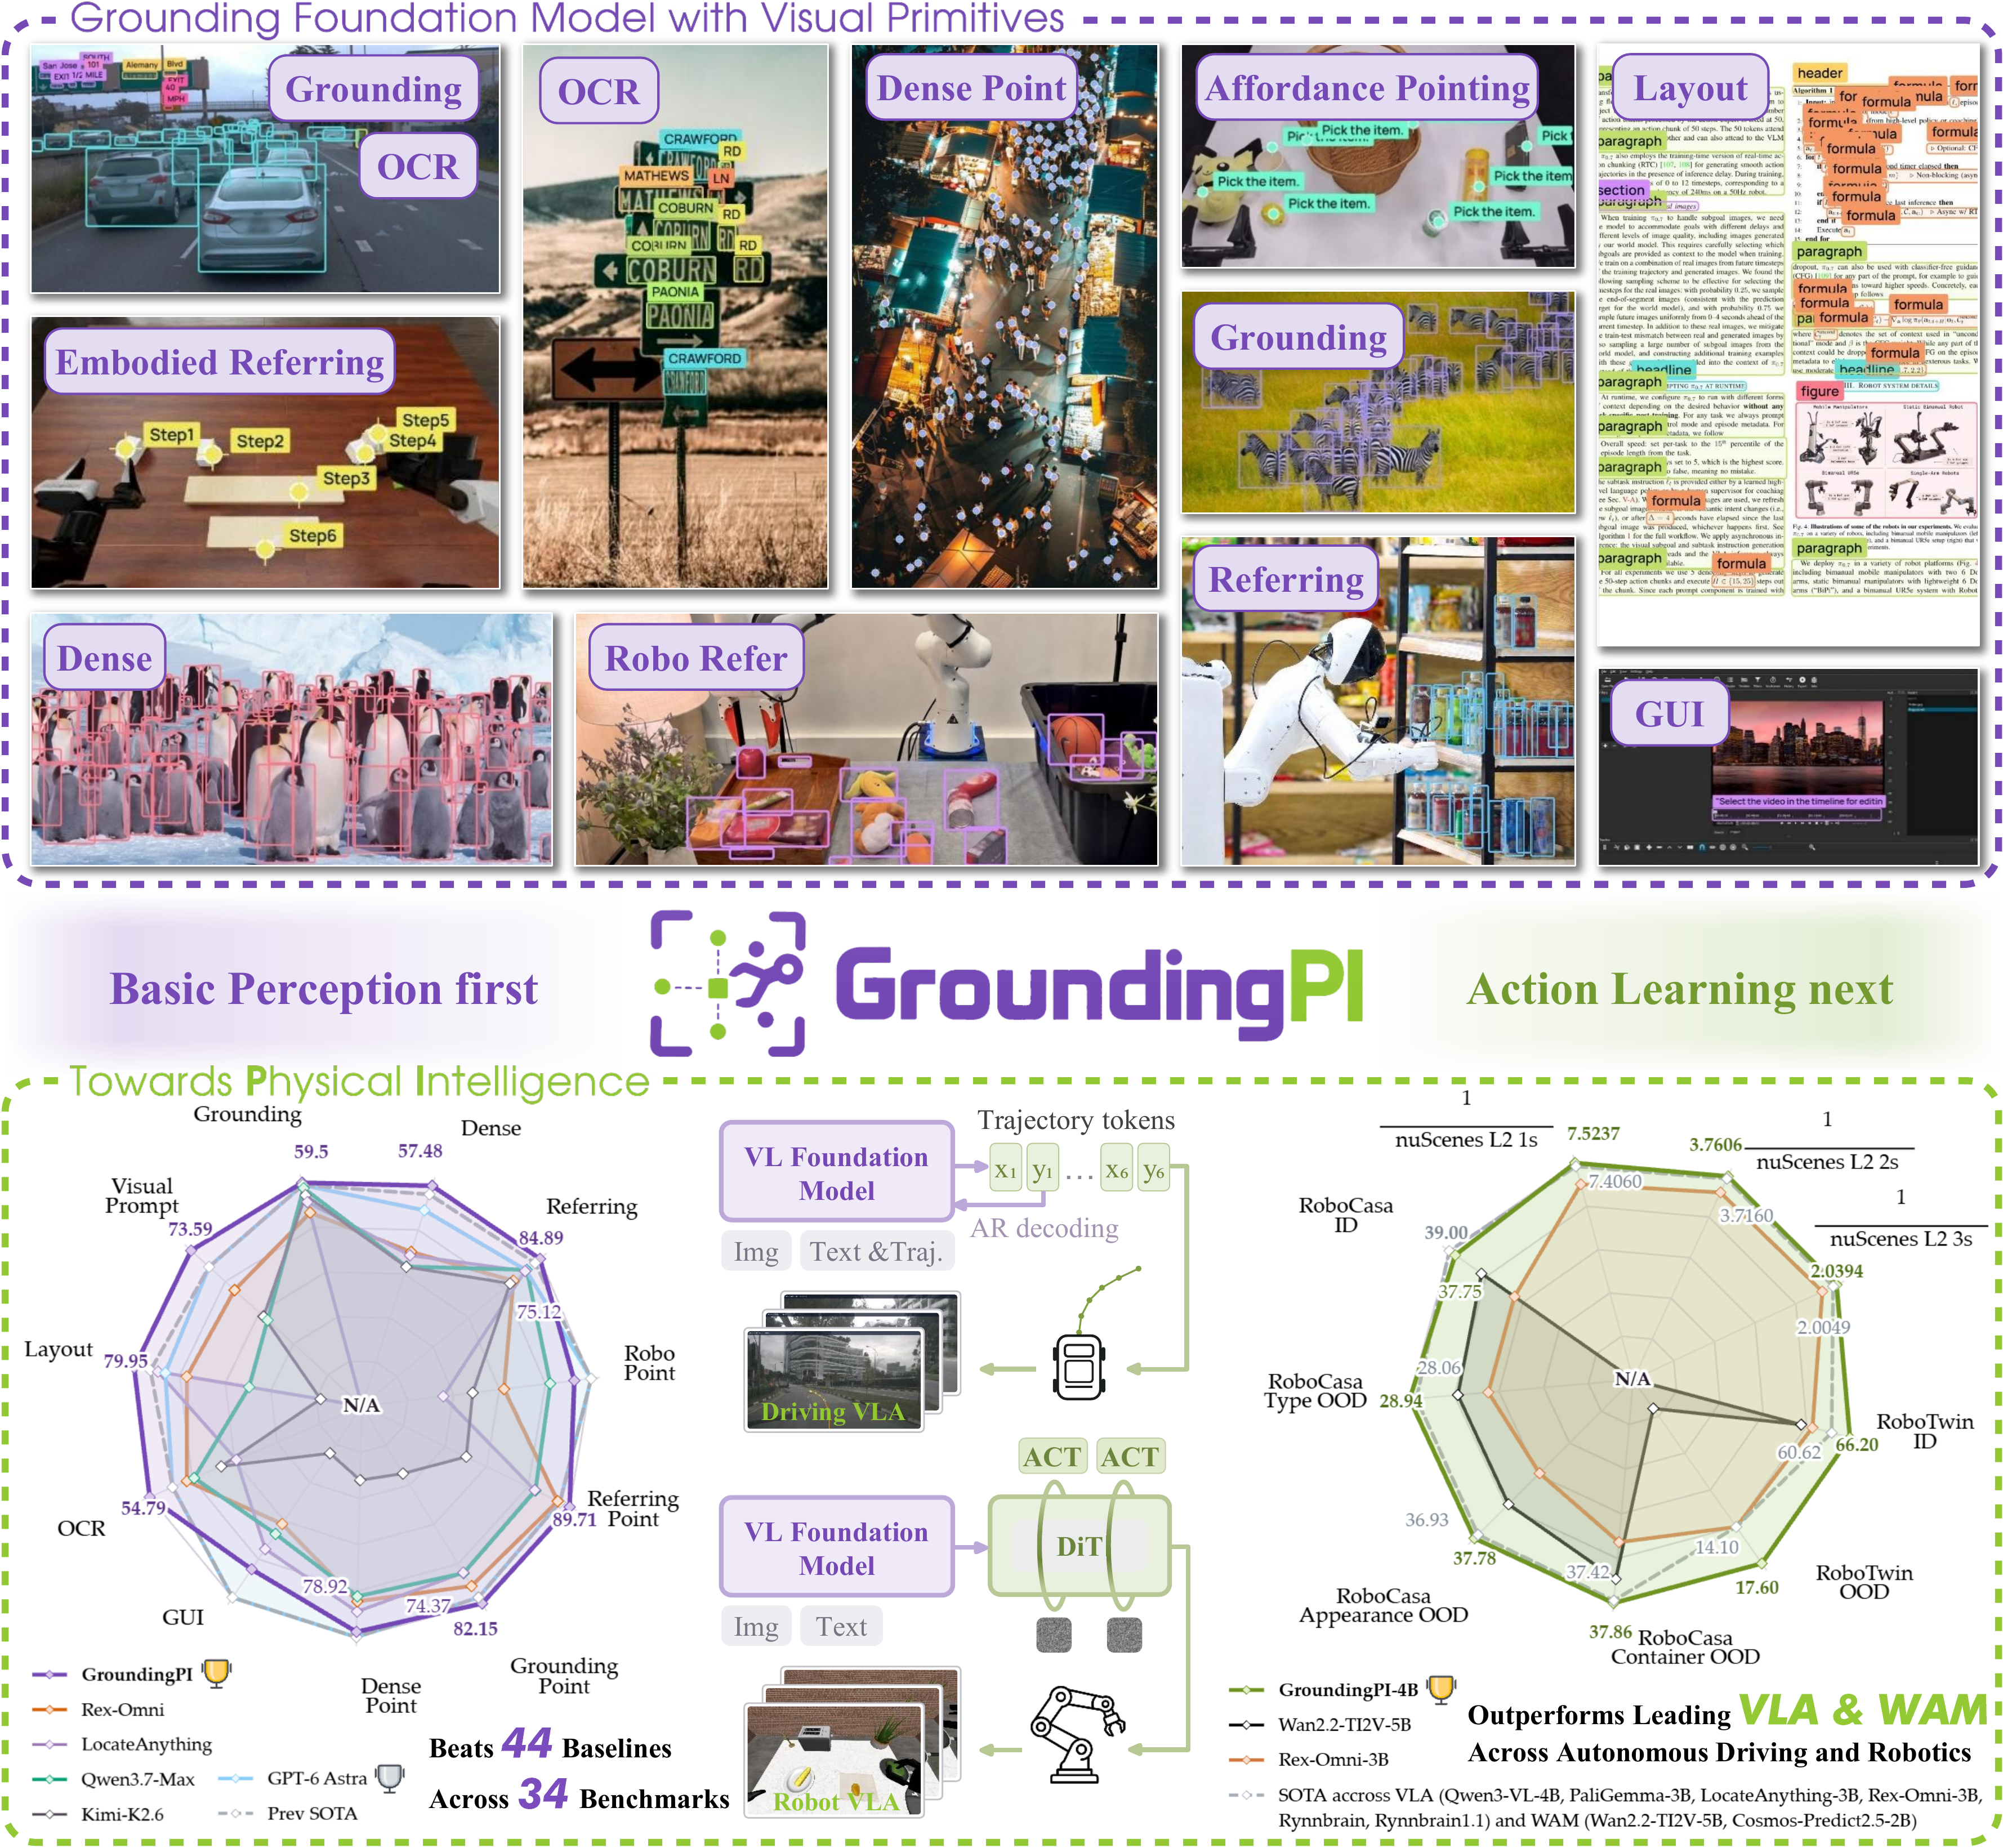
A 4B grounding foundation model for physical intelligence. Unifies detection, referring, pointing, OCR, GUI, and layout grounding, achieving SOTA overall across 34 benchmarks and improving robot generalization and data efficiency in controlled evaluations.
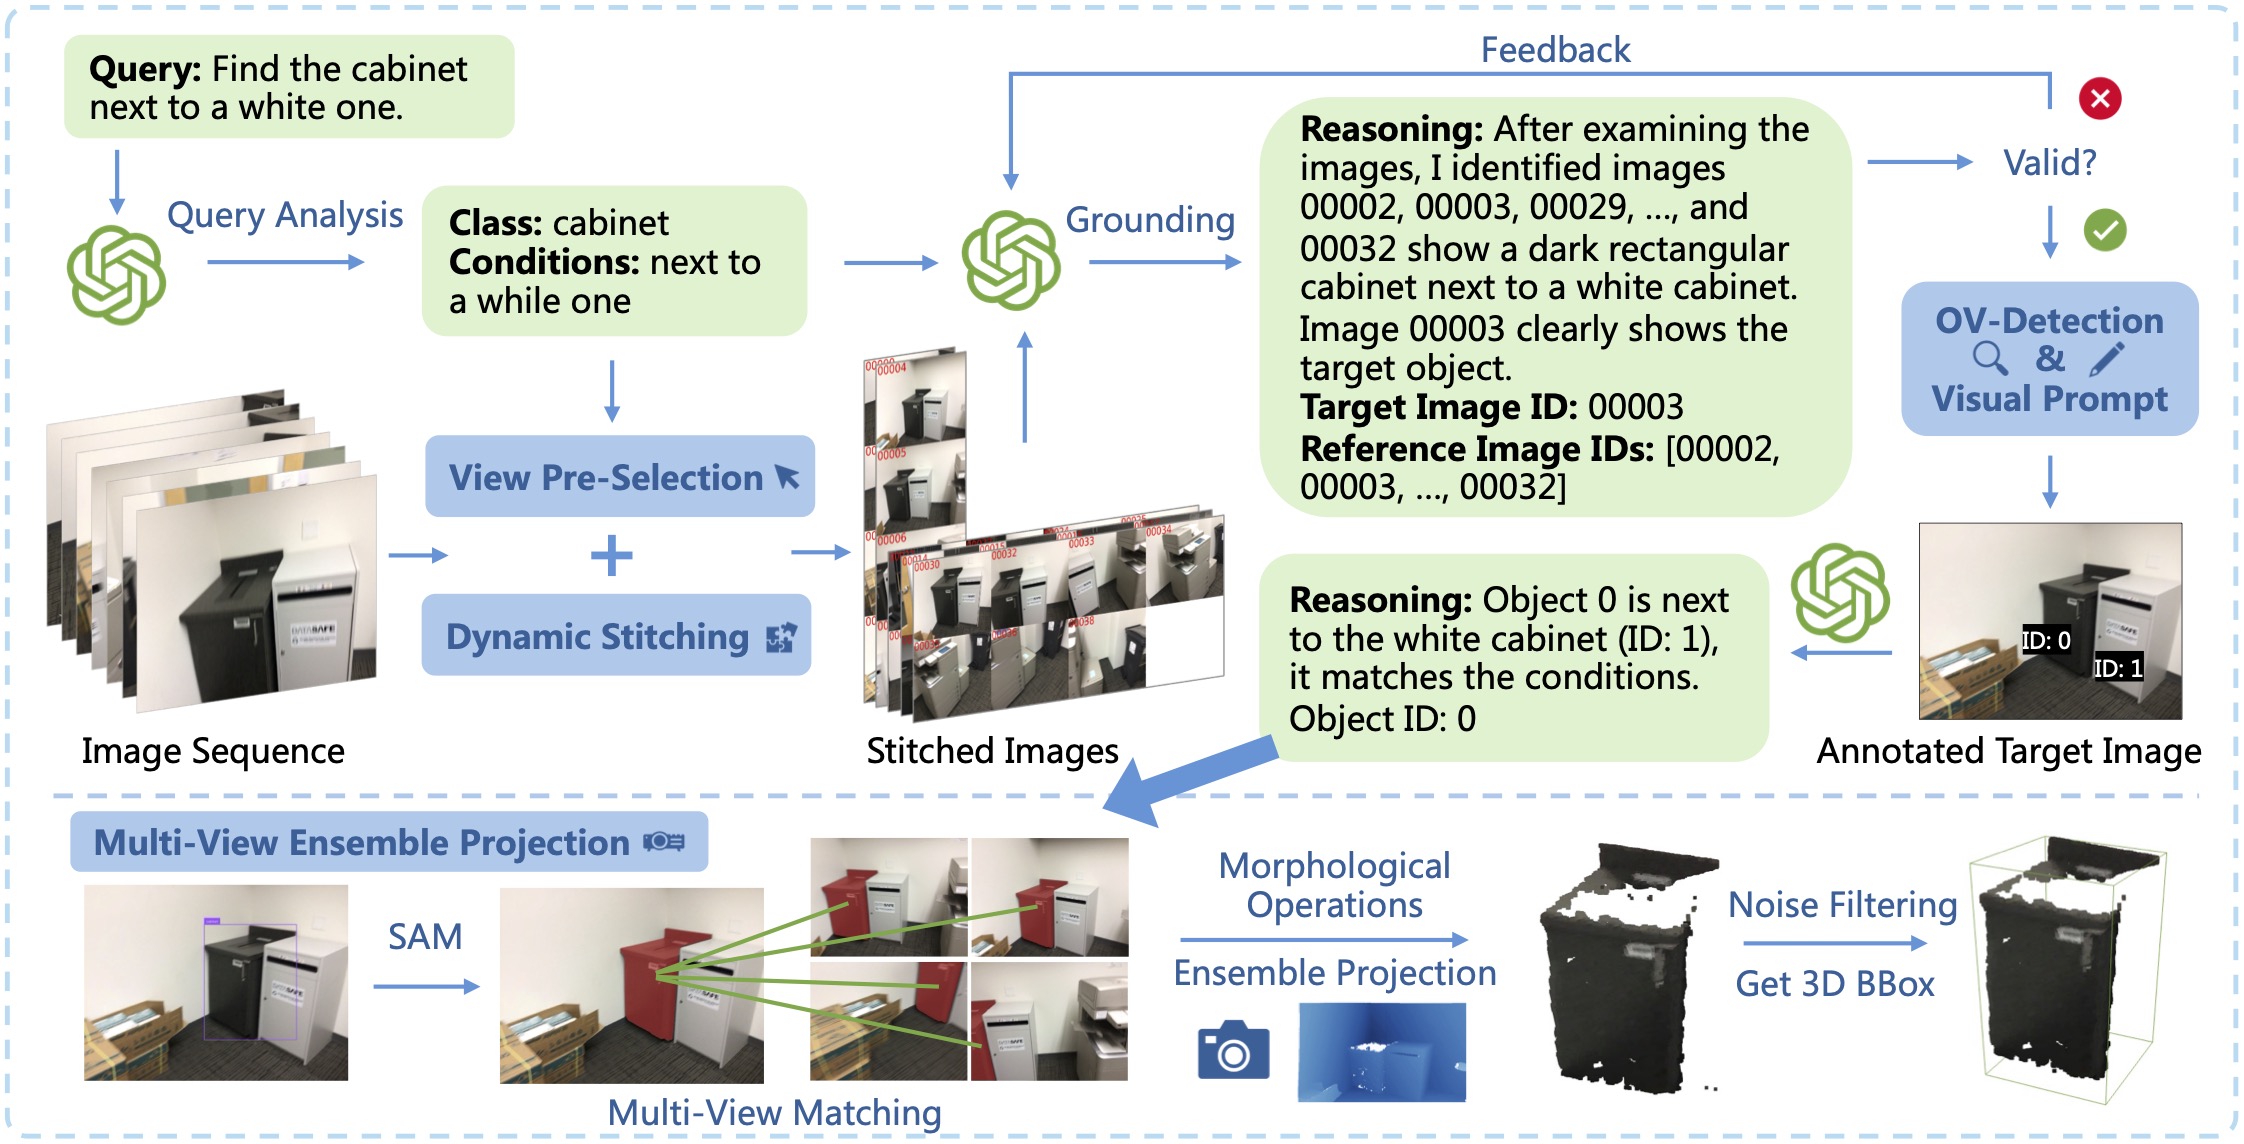
[CoRL 2024] VLM-Grounder: A VLM Agent for Zero-Shot 3D Visual Grounding
A curated list of papers and resources related to Described Object Detection, Open-Vocabulary/Open-World Object Detection and Referring Expression Comprehension. Updated frequently and pull requests welcomed.
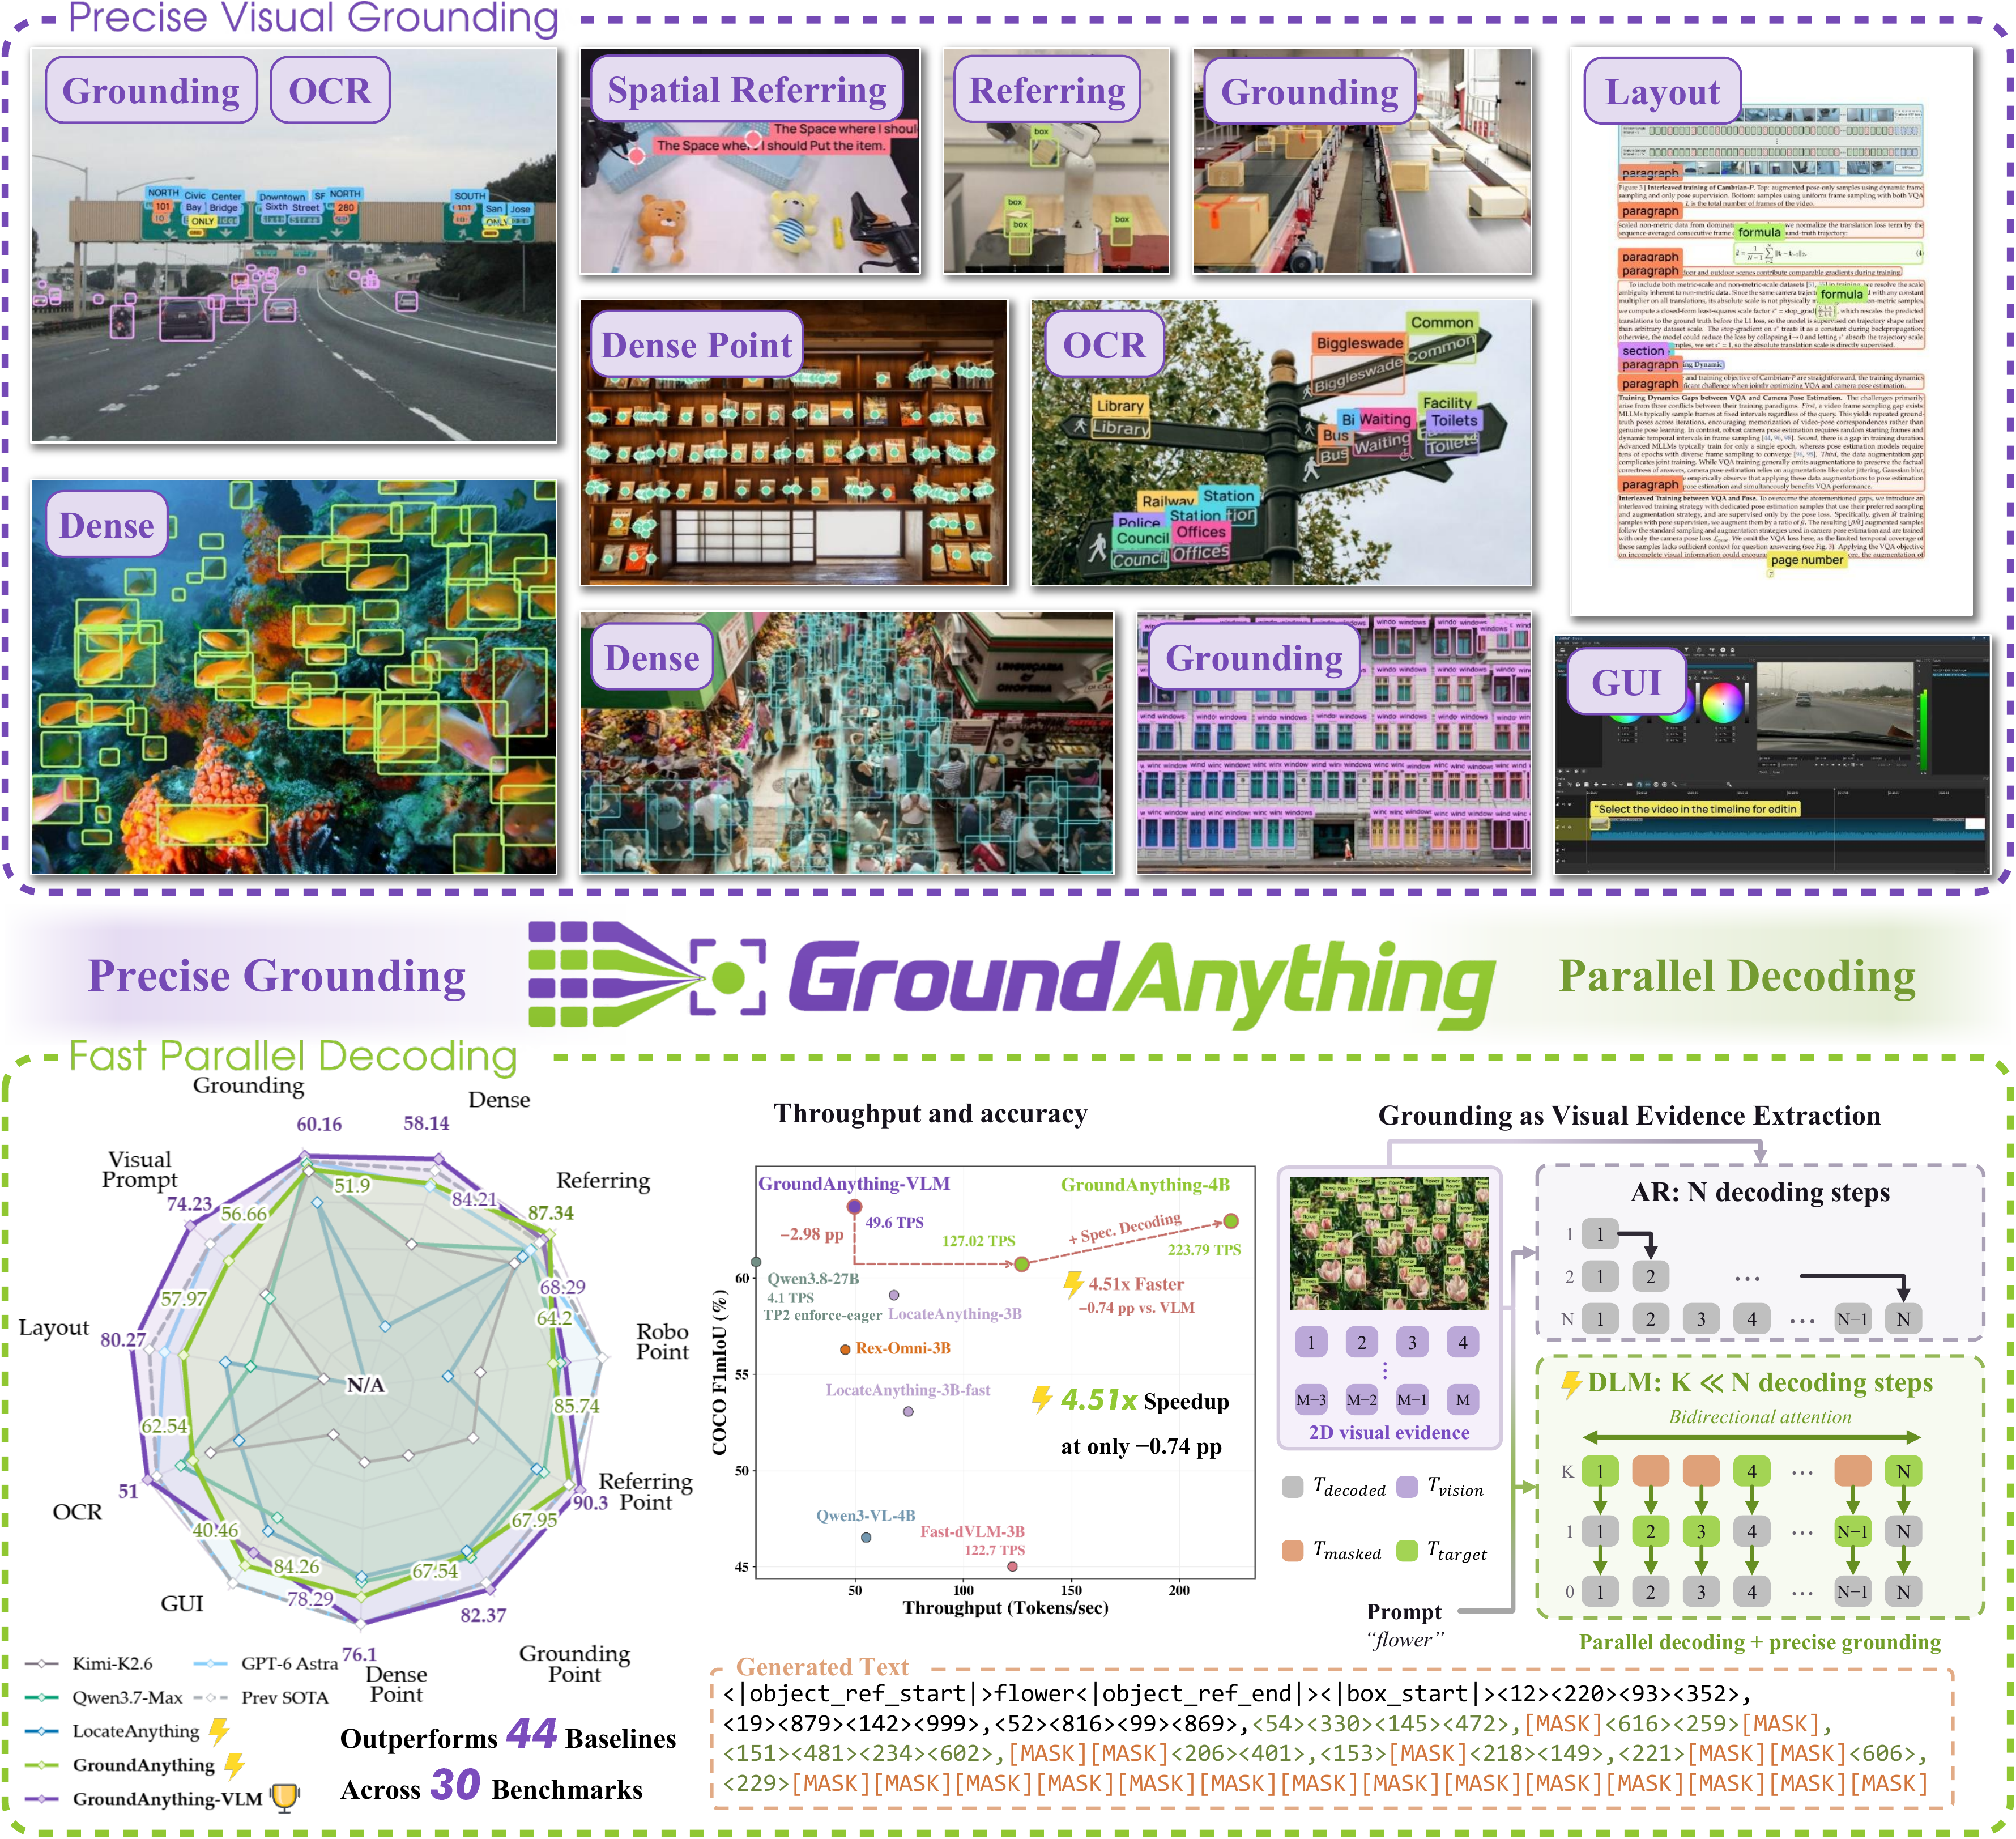
A 4B diffusion grounding model for fast, precise visual evidence extraction. Unifies diverse grounding tasks through parallel decoding, with optional self-speculative decoding delivering 4.51x autoregressive throughput on COCO.
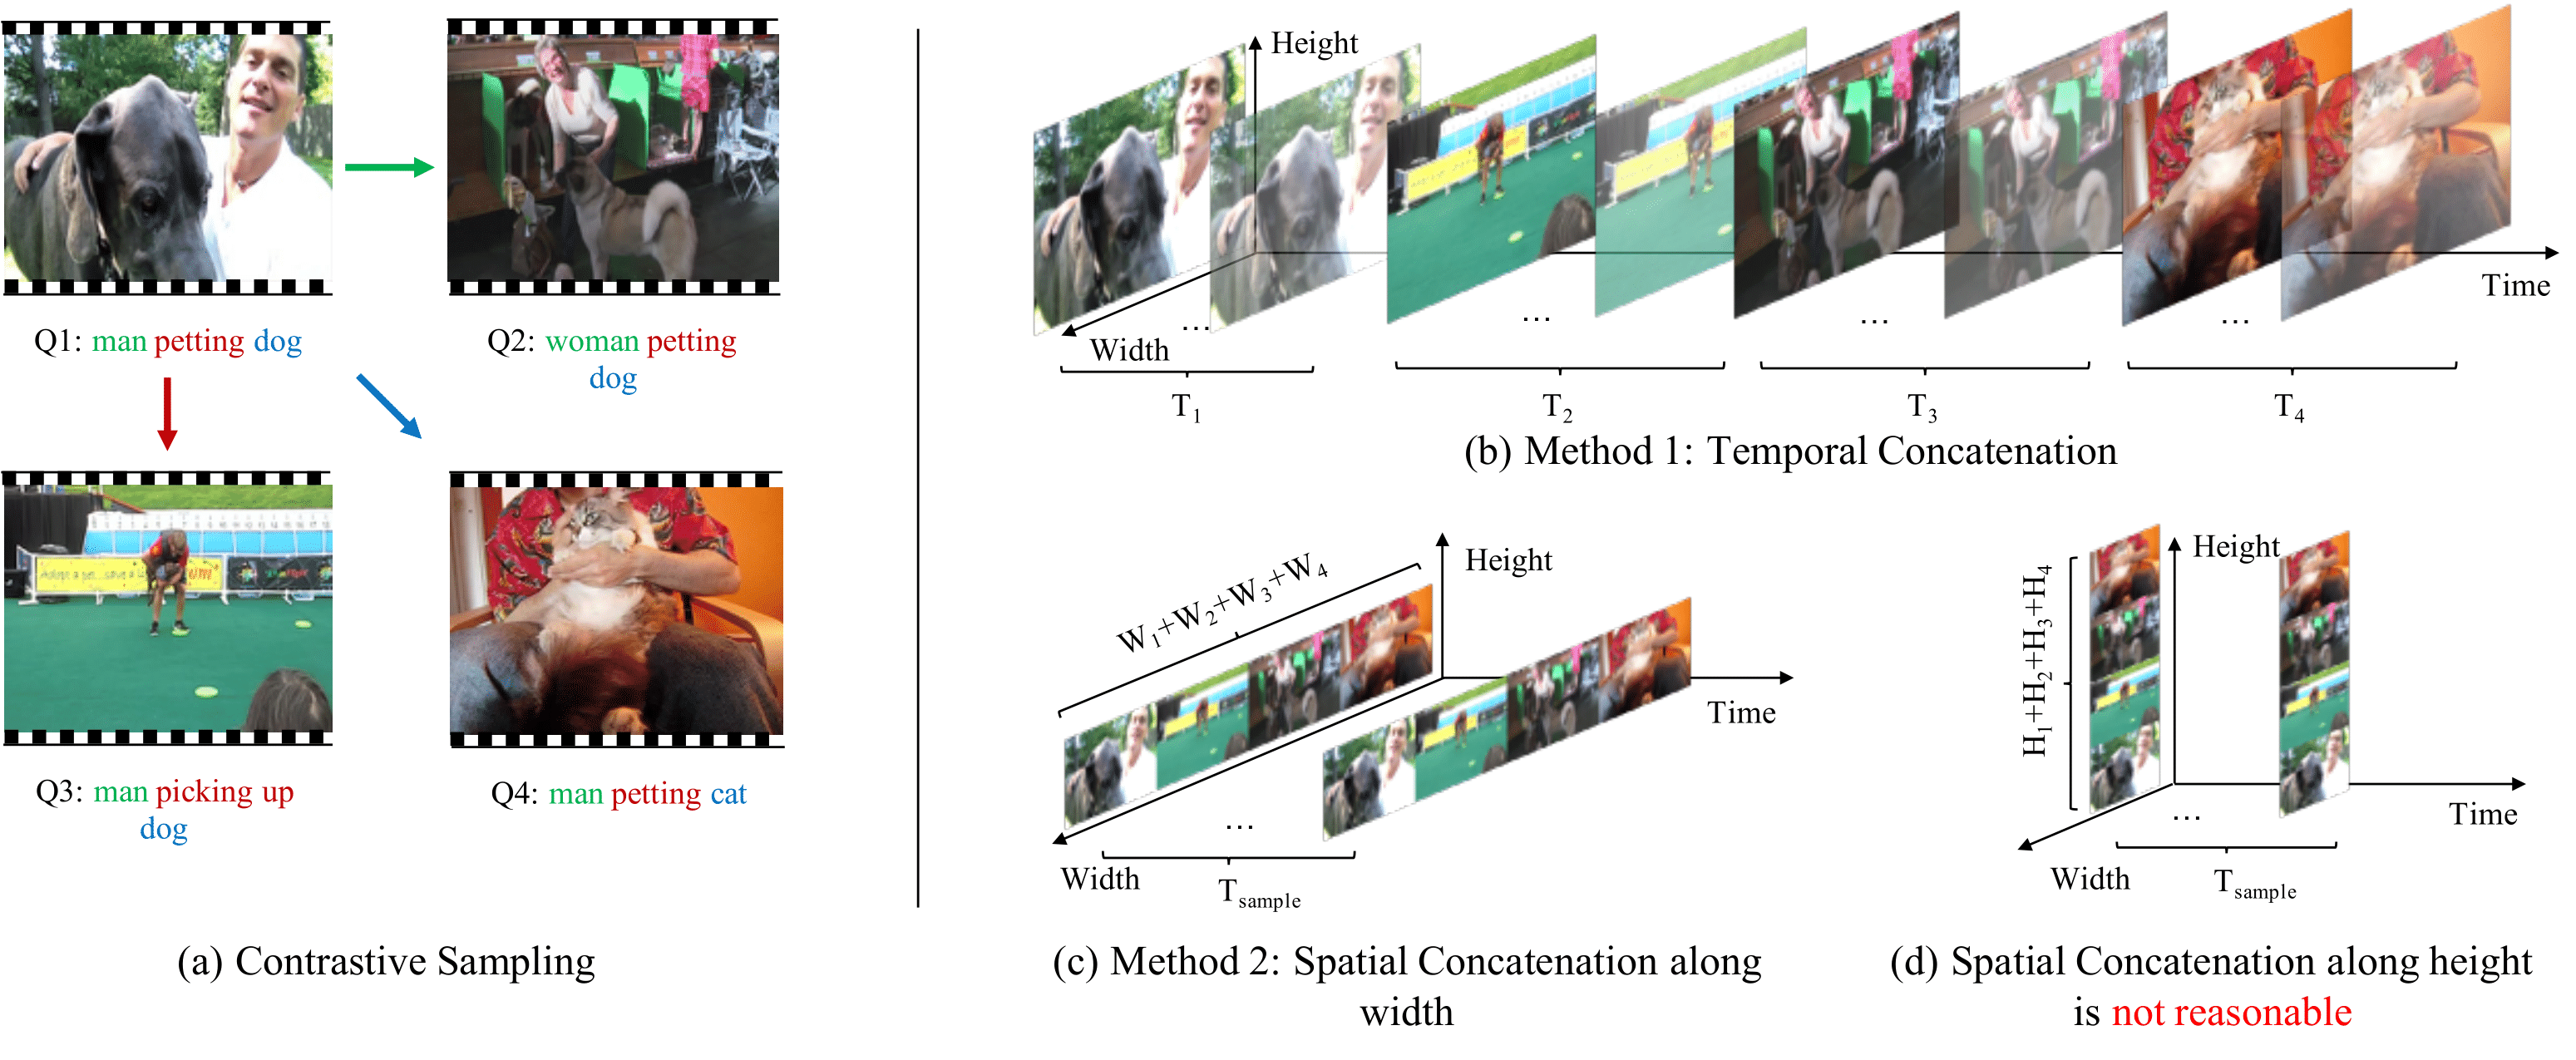
[CVPR20] Video Object Grounding using Semantic Roles in Language Description (https://arxiv.org/abs/2003.10606)
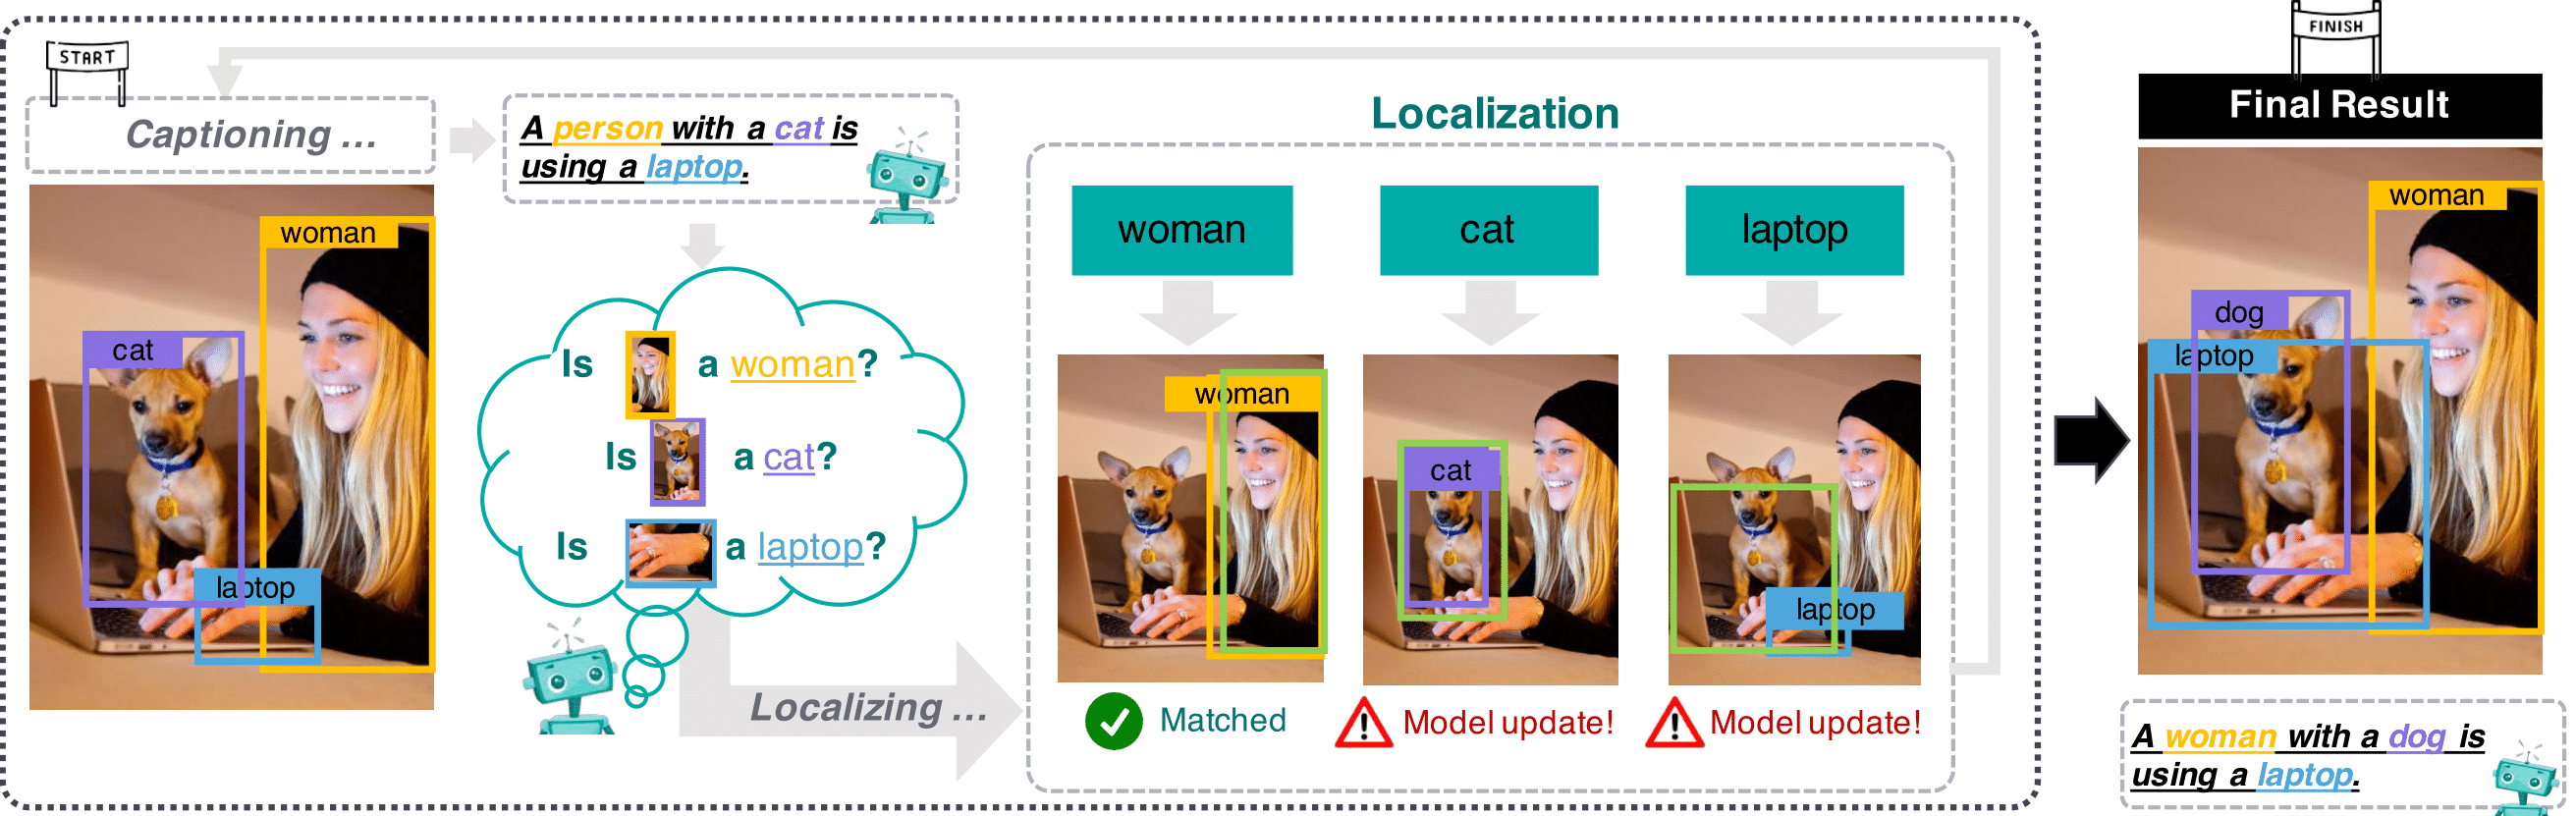
PyTorch code for: Learning to Generate Grounded Visual Captions without Localization Supervision
Unified reproductions, benchmarking & evaluation for perception-aware RLVR and OPD in VLMs, plus multi-turn agentic RL with HTTP, OpenEnv and OpenReward environments. 19 methods · 30+ benchmarks · Official code of CGPO (ACM MM 2026 Oral).
[NeurIPS 2025 Spotlight] Talk2Event: Grounded Understanding of Dynamic Scenes from Event Cameras
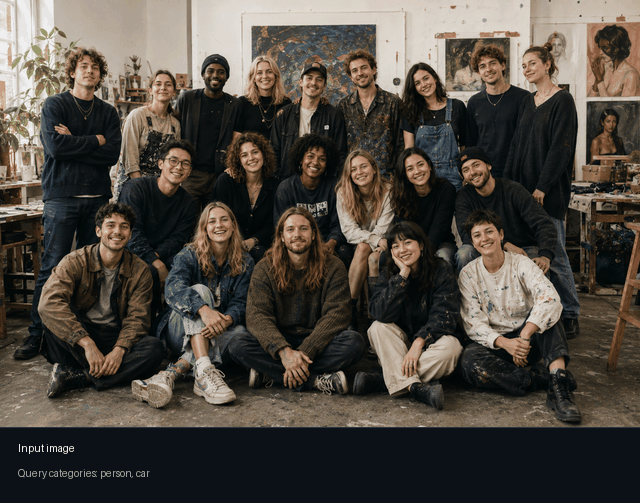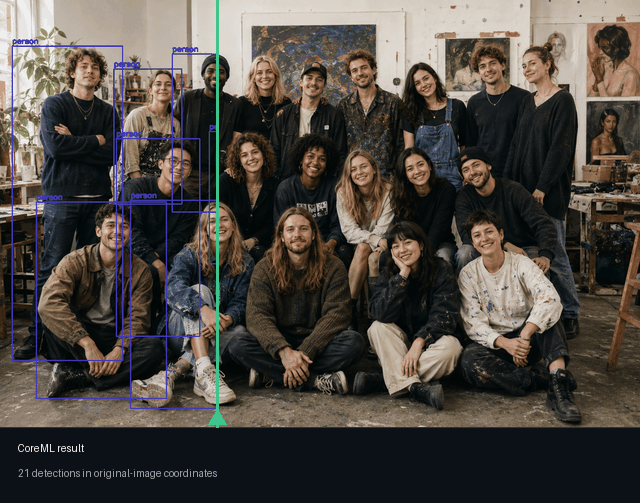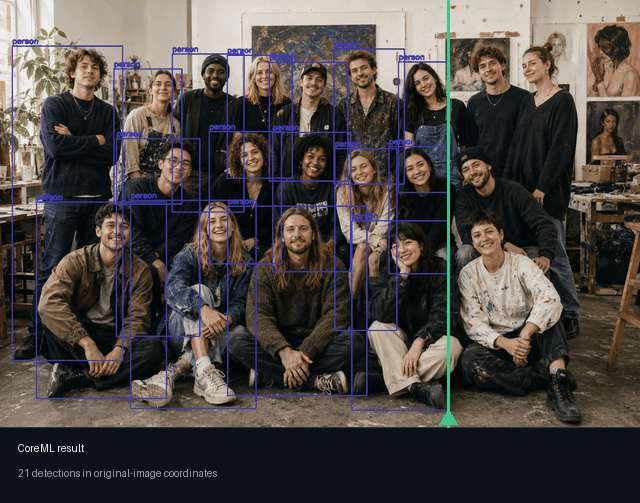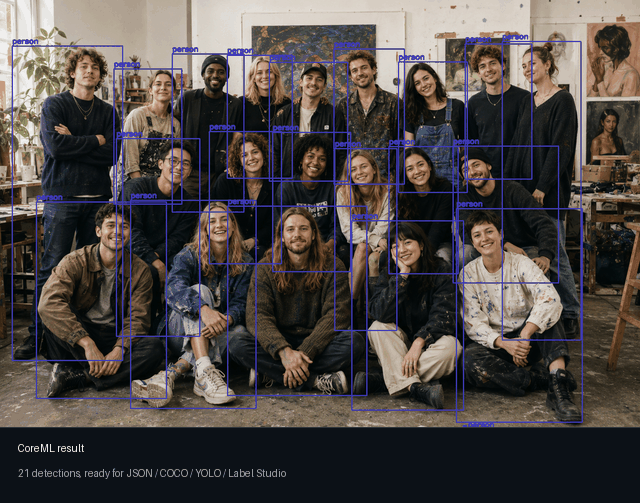
Open-vocabulary object localization on Apple Silicon with CoreML, no PyTorch runtime.
Implementation of Master Thesis on "Belief State for Visually Grounded, Task-Oriented Neural Dialogue Model"