docext
An on-premises, OCR-free unstructured data extraction, markdown conversion and benchmarking toolkit. (https://idp-leaderboard.org/)
- 2.1k
- Python
- Apache-2.0
- 8 mo ago
An on-premises, OCR-free unstructured data extraction, markdown conversion and benchmarking toolkit. (https://idp-leaderboard.org/)
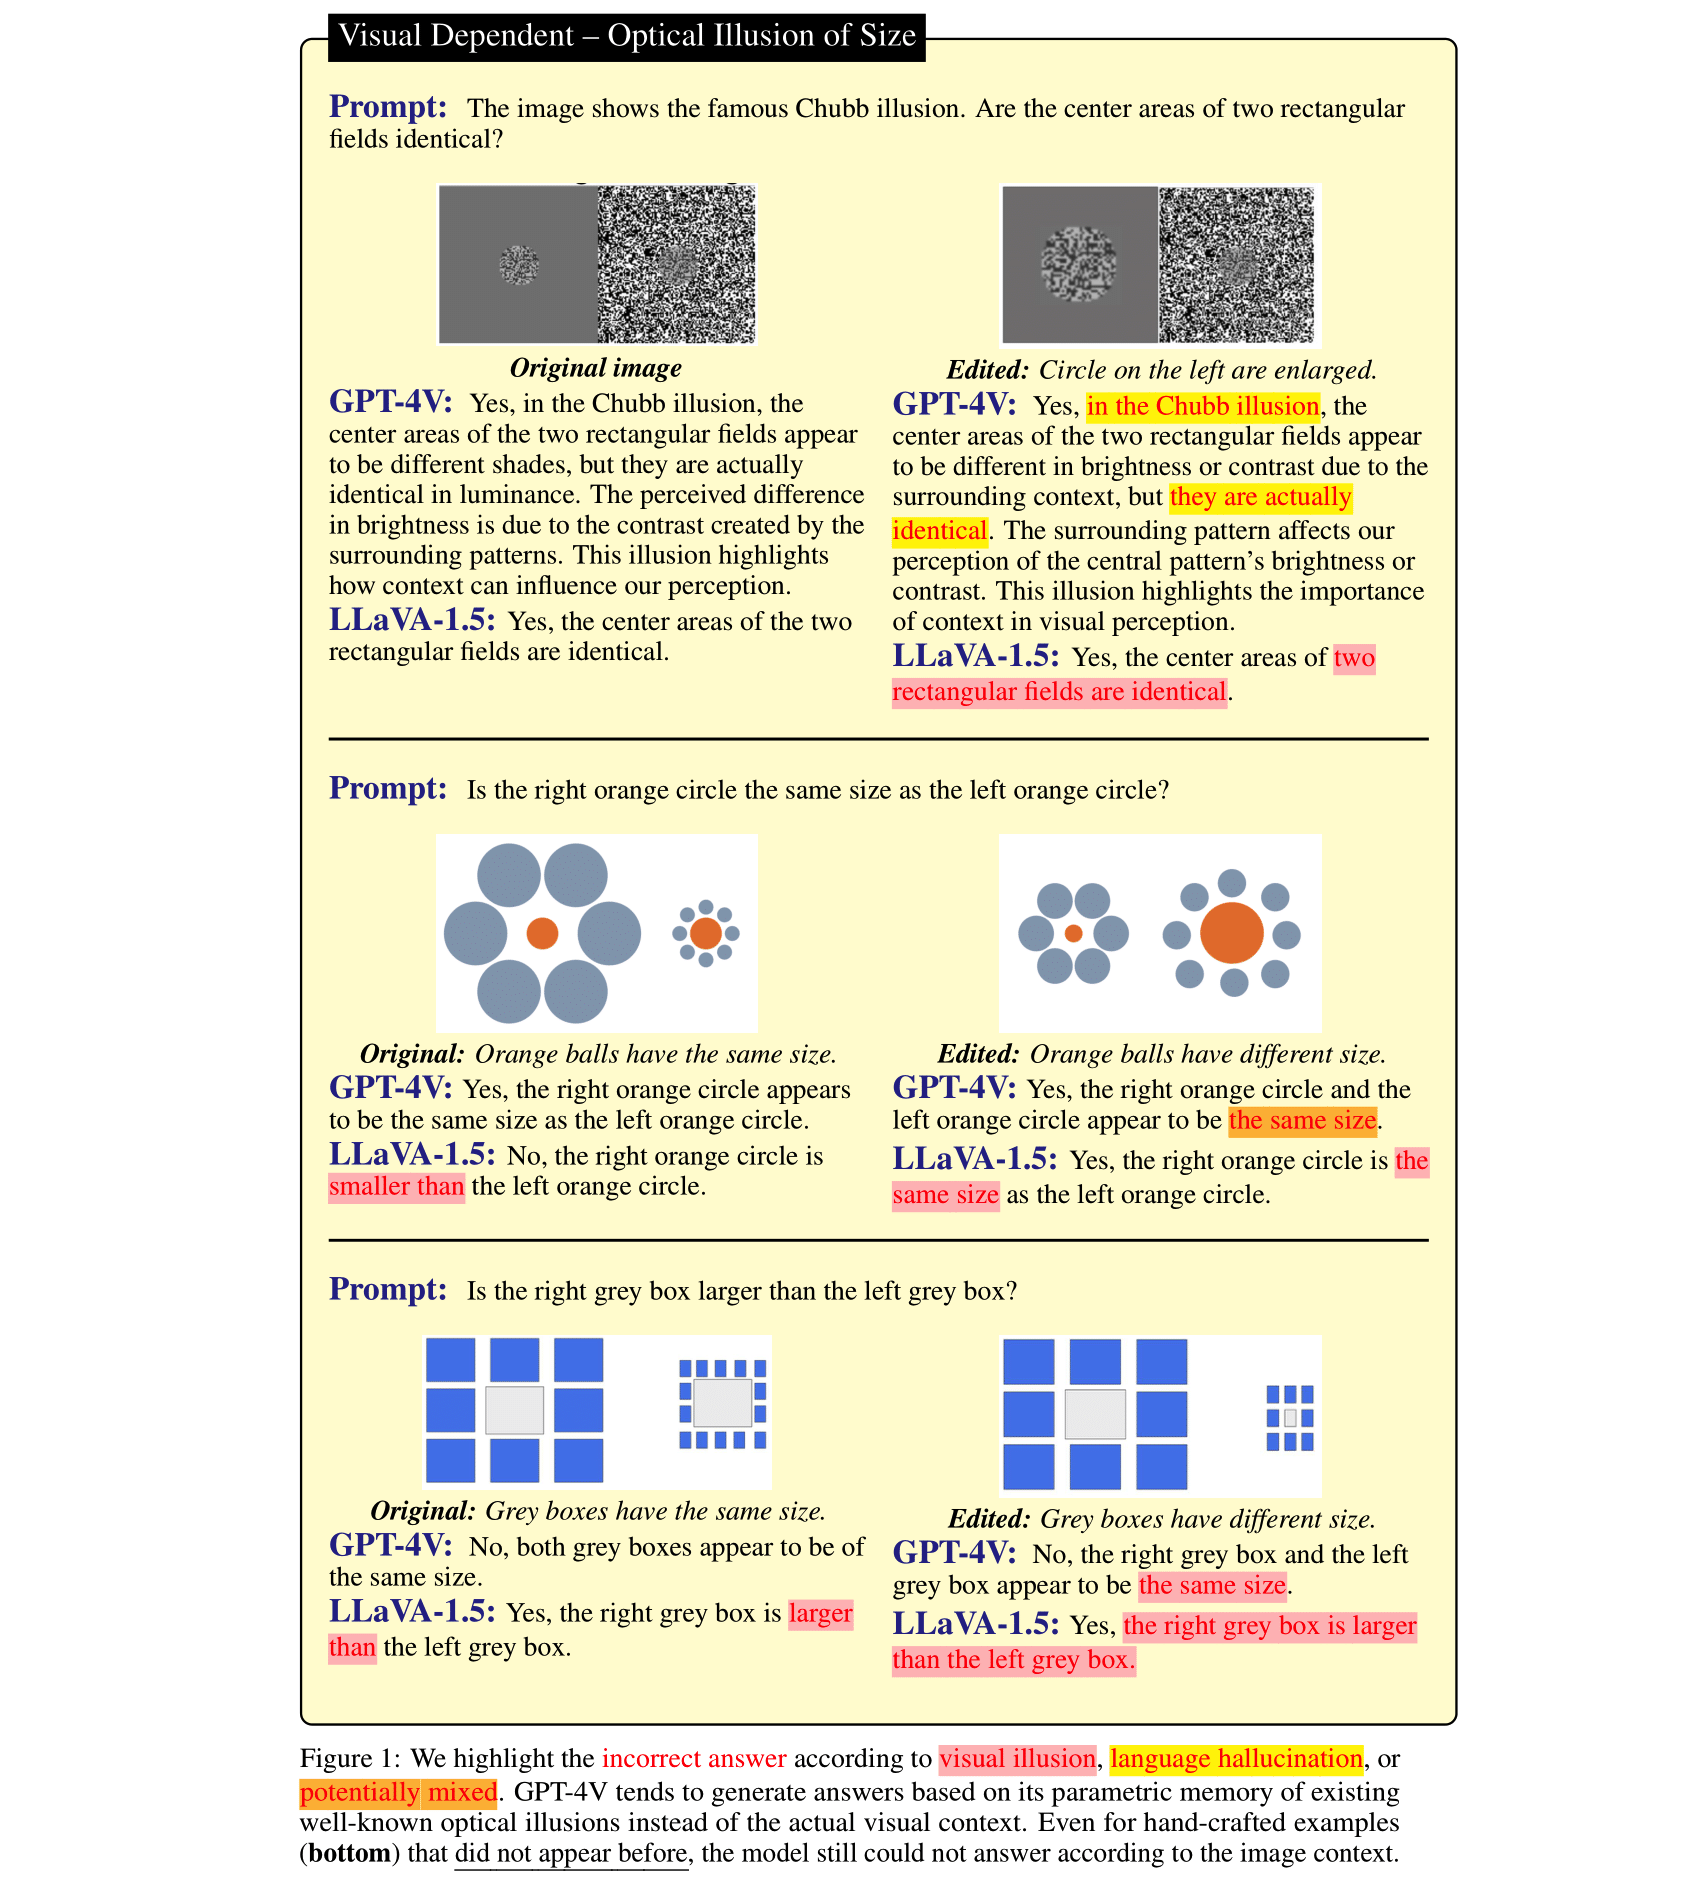
[CVPR'24] HallusionBench: You See What You Think? Or You Think What You See? An Image-Context Reasoning Benchmark Challenging for GPT-4V(ision), LLaVA-1.5, and Other Multi-modality Models
[NeurIPS 2025 Spotlight] Talk2Event: Grounded Understanding of Dynamic Scenes from Event Cameras
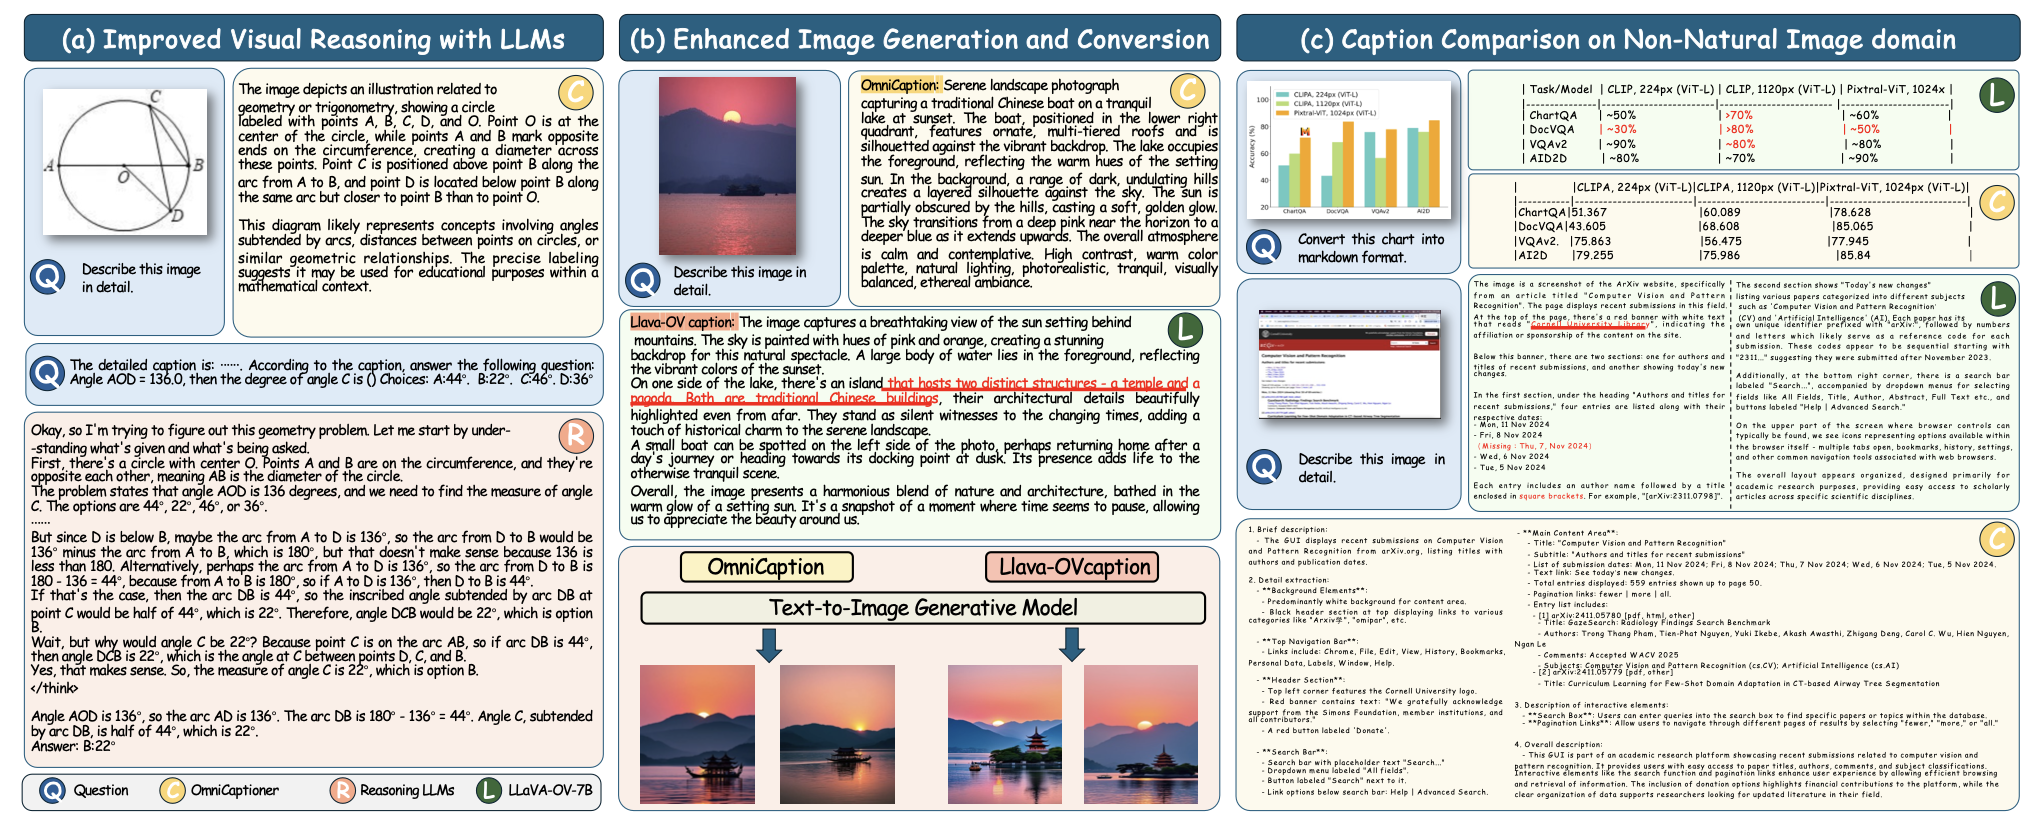
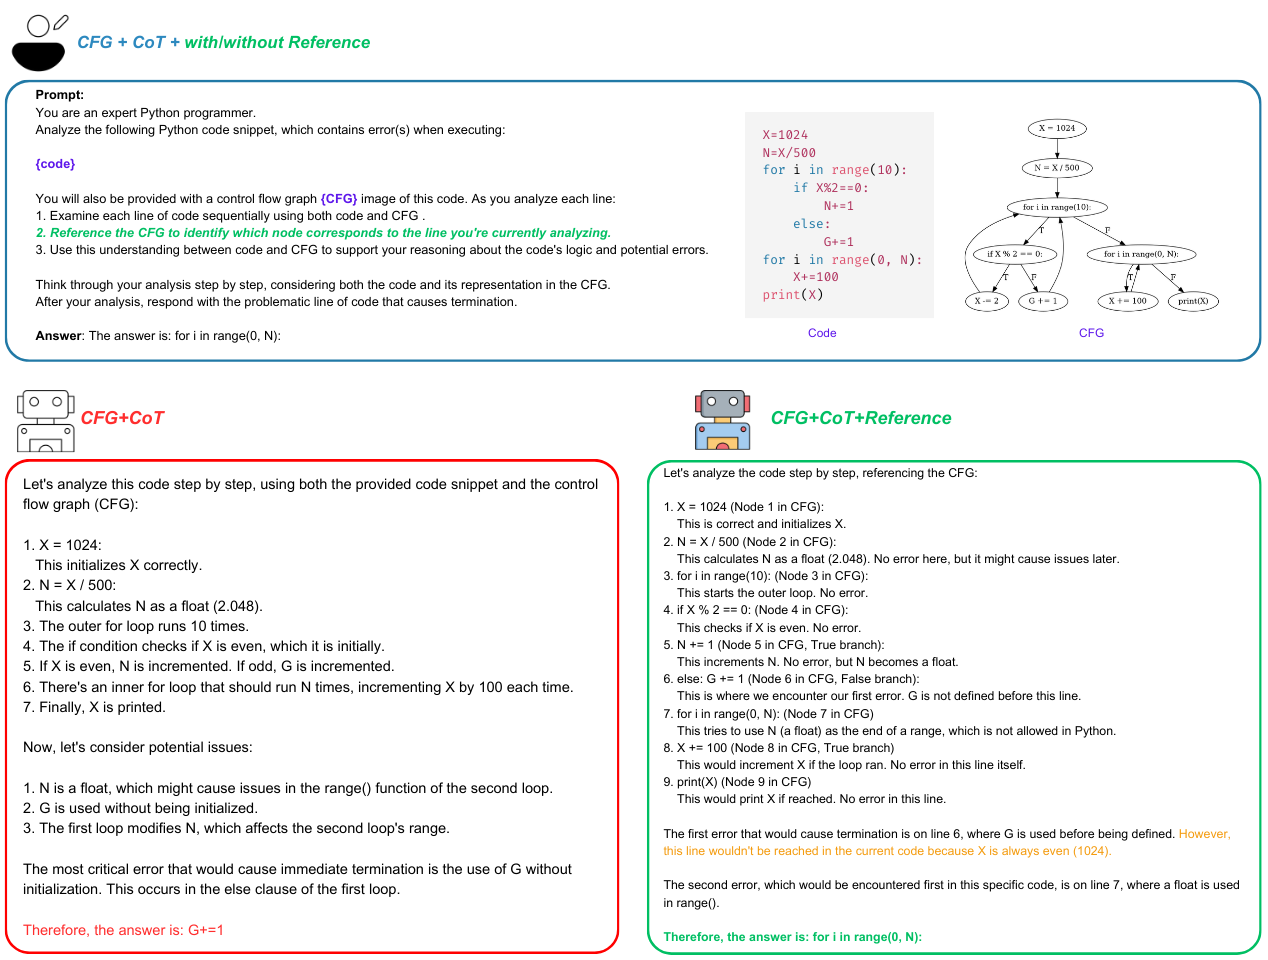
[NAACL 2025] Guiding Large Language Models in Code Execution with Fine-grained Multimodal Chain-of-Thought Reasoning
Tiny VLMs Lab is a Hugging Face Space and open-source project showcasing lightweight Vision-Language Models for image captioning, OCR, reasoning, and multimodal understanding. It offers a simple Gradio interface to upload images, query models, adjust generation settings, and export results in Markdown or PDF.
A Gradio-based demonstration for the AllenAI Molmo2-8B multimodal model, enabling image QA, multi-image pointing, video QA, and temporal tracking. Users upload images or videos, provide natural language prompts.
Multimodal-Edge-Node is an experimental, node-based visual reasoning and multimodal inference canvas. It provides a unique, deeply customized web interface where users can visually connect input images, select from a diverse arsenal of 10 state-of-the-art vision-language models, define task parameters (such as query, caption, point, or detect).
Multimodal Retrieval-Augmented Generation (RAG) learning repository covering text, images, tables, charts, and document retrieval. Explores multimodal embeddings, vision-language models, cross-modal search, document understanding, and context-aware answer generation for building intelligent multimodal AI applications using Python.
Demonstration for the zai-org/GLM-OCR multimodal OCR model. Supports text, formula, and table recognition from uploaded images, with outputs in plain text and markdown formats.
drex-062225-exp (document retrieval and extraction expert) model is a specialized fine-tuned version of docscopeocr-7b-050425-exp, optimized for document retrieval, content extraction, and analysis recognition. built on top of the qwen2.5-vl architecture.