TTS
🐸💬 - a deep learning toolkit for Text-to-Speech, battle-tested in research and production
- 46k
- Python
- MPL-2.0
- 2 y ago
🐸💬 - a deep learning toolkit for Text-to-Speech, battle-tested in research and production
Easily train a good VC model with voice data <= 10 mins!
Gradio WebUI for creators and developers, featuring key TTS (Edge-TTS, kokoro) and zero-shot Voice Cloning (E2 & F5-TTS, CosyVoice), with Whisper audio processing, YouTube download, Demucs vocal isolation, and multilingual translation.
Amphion (/æmˈfaɪən/) is a toolkit for Audio, Music, and Speech Generation. Its purpose is to support reproducible research and help junior researchers and engineers get started in the field of audio, music, and speech generation research and development.
Generate audiobooks from EPUBs, PDFs and text with synchronized captions.
An all-in-one, pure C++ inference engine for audio models, powered by ggml. Supports TTS, STT, VAD, voice conversion, music generation, and more, with highly optimized performance. No Python dependency.
A simple, high-quality voice conversion tool focused on ease of use and performance.
Automatic Speech Recognition (ASR), Speaker Verification, Speech Synthesis, Text-to-Speech (TTS), Language Modelling, Singing Voice Synthesis (SVS), Voice Conversion (VC)
🔊 A comprehensive list of open-source datasets for voice and sound computing (95+ datasets).
Easily select, start, and manage your preferred AI digital assistants on Android.
A ComfyUI custom node integration for local multi-engine multi-language Text-to-Speech and Voice Conversion. Supports: RVC, Echo-TTS, Qwen3-TTS, Cozy Voice 3, Step Audio EditX, IndexTTS-2, Chatterbox (classic and multilingual), F5-TTS, Higgs Audio 2, 3, and VibeVoice with unlimited text length, SRT timing, Character support, and many audio tools
The code for the bark-voicecloning model. Training and inference.
StarGANv2-VC: A Diverse, Unsupervised, Non-parallel Framework for Natural-Sounding Voice Conversion
A paper and project list about the cutting edge Speech Synthesis, Text-to-Speech (TTS), Singing Voice Synthesis (SVS), Voice Conversion (VC), Singing Voice Conversion (SVC), and related interesting works (such as Music Synthesis, Automatic Music Transcription, Automatic MOS Prediction, SSL-based ASR...etc).
PyTorch implementation of GAN-based text-to-speech synthesis and voice conversion (VC)
Easily train a good VC model with voice data <= 10 mins!
audio.cpp with a full-task WebUI - pure C++ audio-model inference engine powered by ggml. TTS, ASR/STT, VAD, voice conversion, speaker diarization, music generation. No Python dependency.
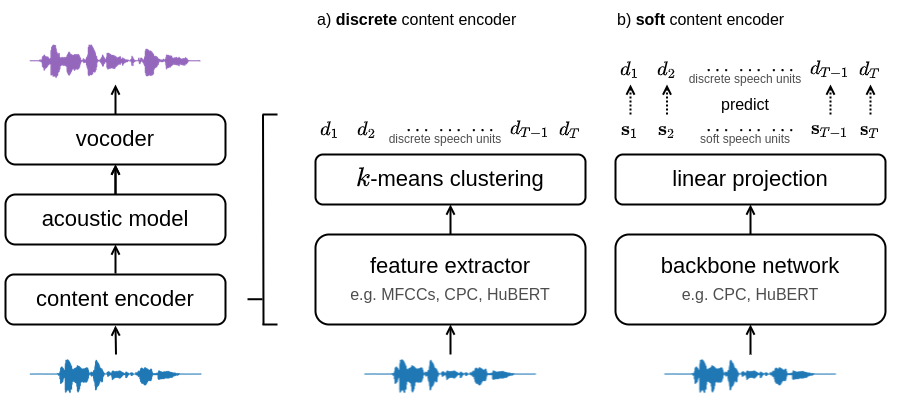
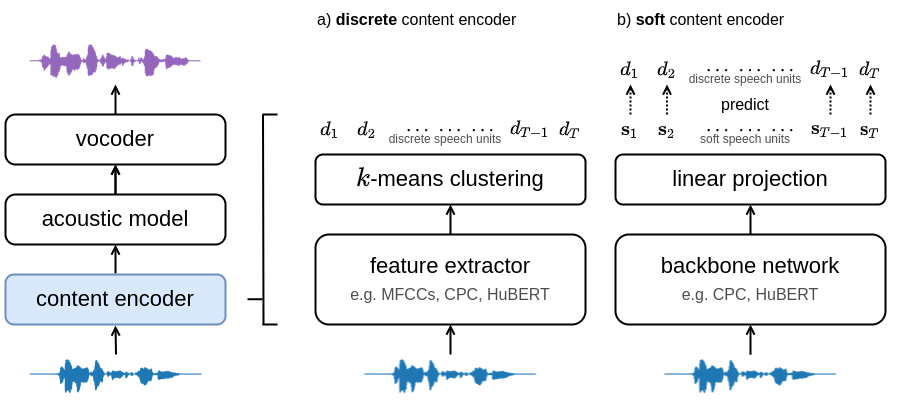
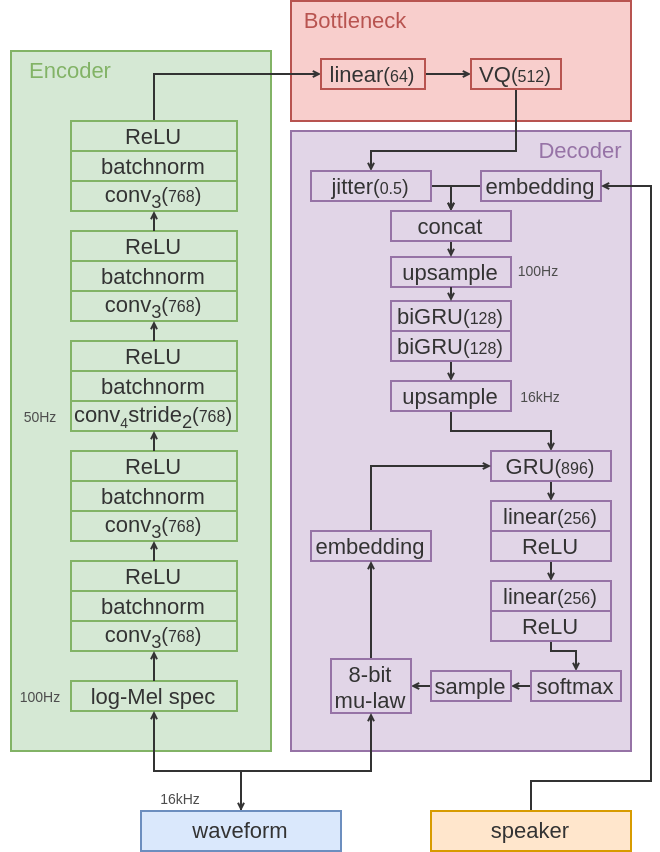
HuBERT content encoders for: A Comparison of Discrete and Soft Speech Units for Improved Voice Conversion
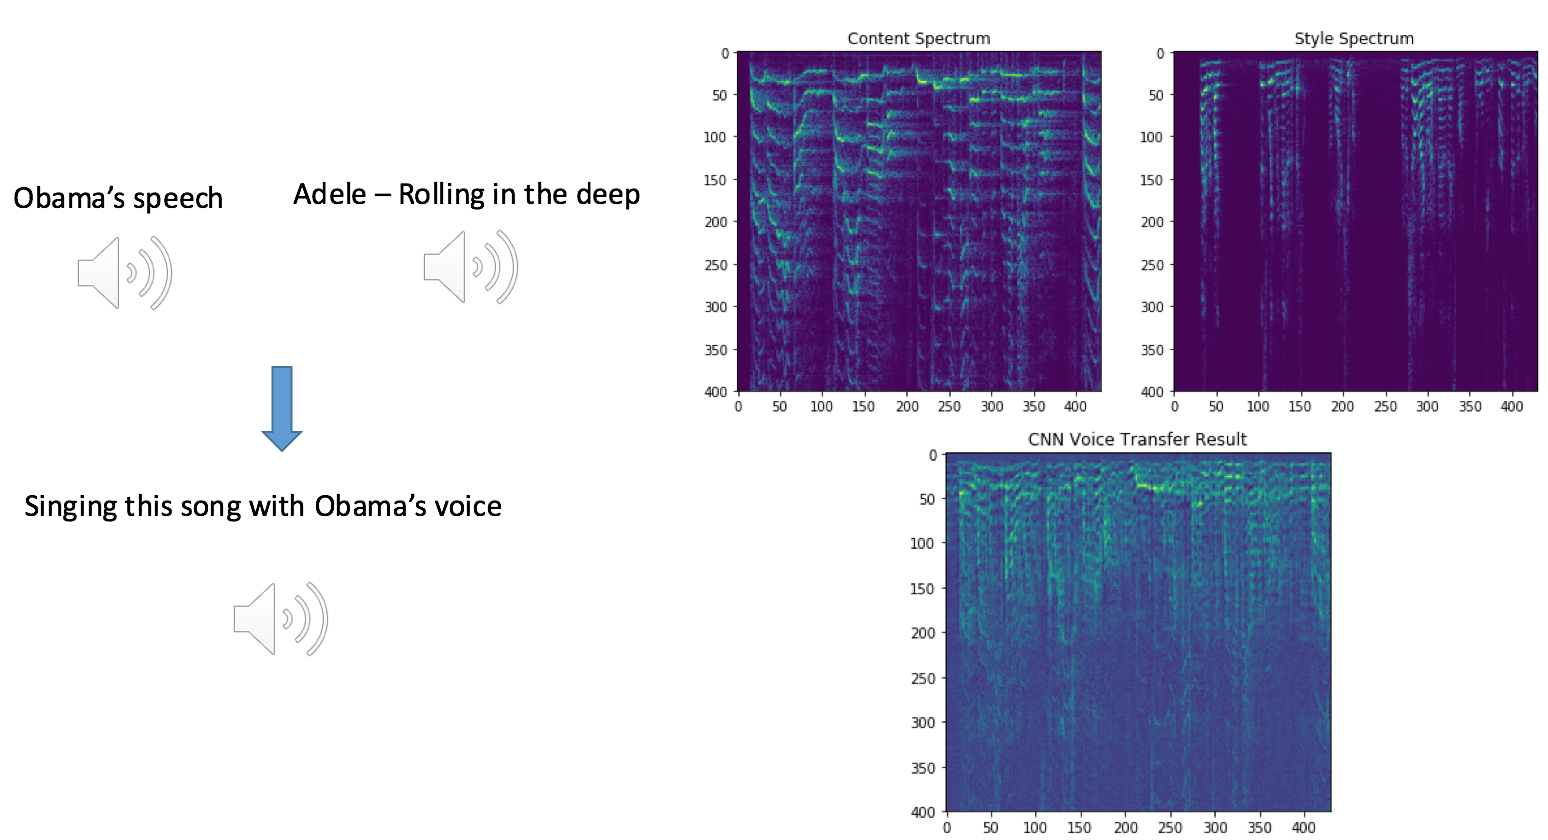
Audio style transfer with shallow random parameters CNN.
Library to build speech synthesis systems designed for easy and fast prototyping.
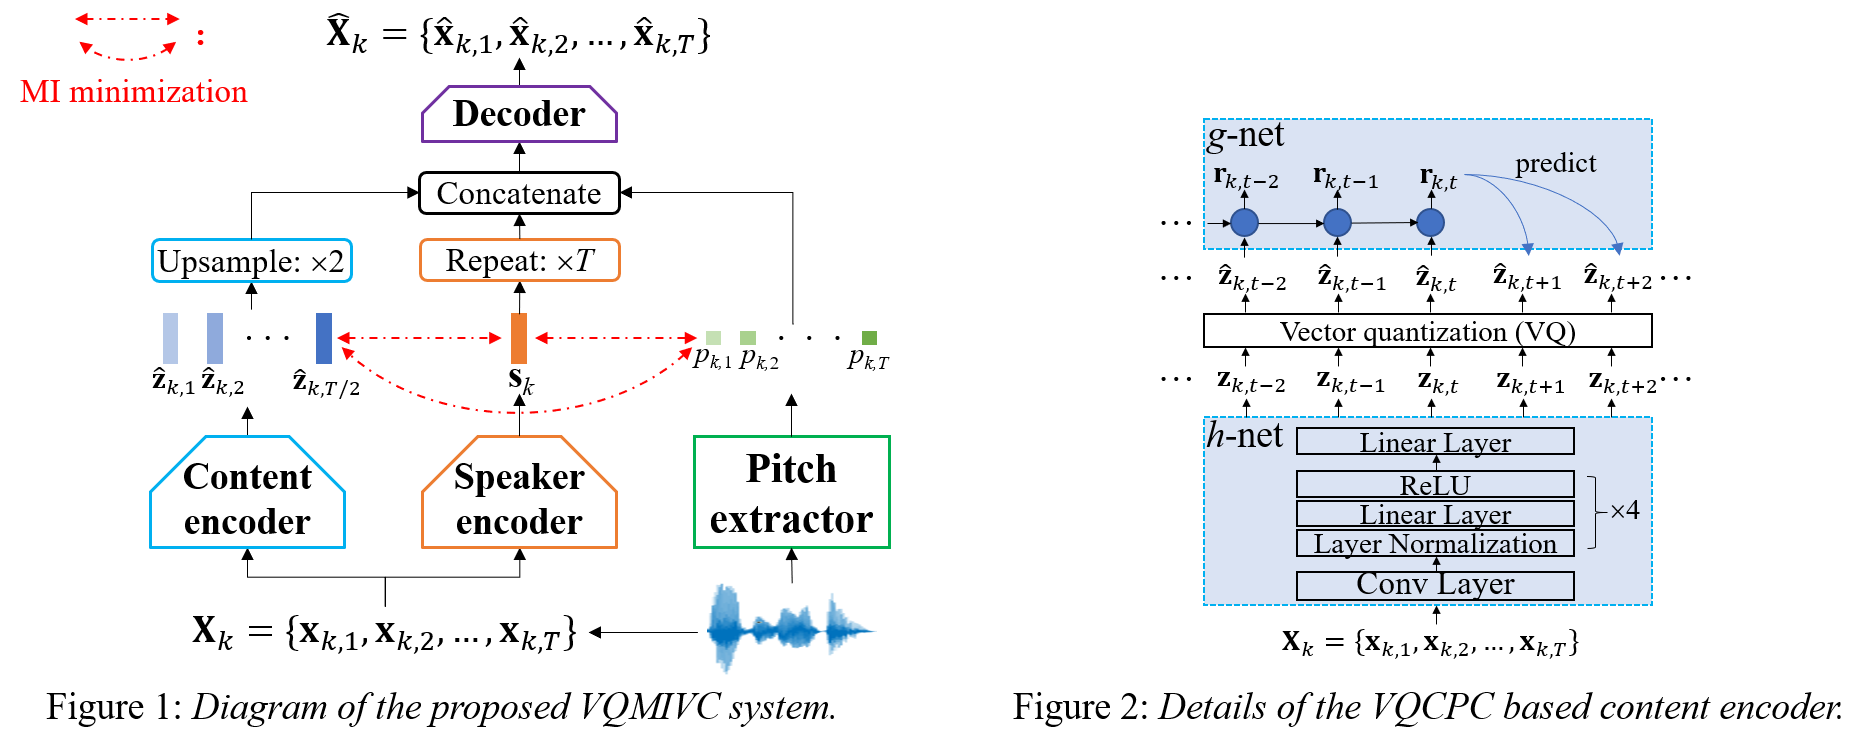
Official implementation of VQMIVC: One-shot (any-to-any) Voice Conversion @ Interspeech 2021 + Online playing demo!
Fully reproduce the paper of StarGAN-VC. Stable training and Better audio quality .
RVC-v2 Beatrice-v2 - CPU inference + training
Runs in the browser on Hugging Face
RVC-v2 Beatrice-v2 - CPU inference + training
Runs in the browser on Hugging Face