ollama
Get up and running with Kimi, GLM, MiniMax, DeepSeek, gpt-oss, Qwen, Gemma and other models.
- 188k
- Go
- MIT
- 17 h ago
[ICLR 2024] This is the official PyTorch implementation of "QLLM: Accurate and Efficient Low-Bitwidth Quantization for Large Language Models"
Repo ModelTC/QLLM, read from GitHub 12 h ago. ModelTC has not joined Take My Repo.
ModelTC/QLLM is a public repo on GitHub by ModelTC. [ICLR 2024] This is the official PyTorch implementation of "QLLM: Accurate and Efficient Low-Bitwidth Quantization for Large Language Models". It declares the Apache-2.0 license on GitHub. It is written mainly in Python, has 39 stars and last changed on 2024-03-11. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-22.
This is the official PyTorch implementation of QLLM: Accurate and Efficient Low-Bitwidth Quantization for Large Language Models.
By Jing Liu, Ruihao Gong, Xiuying Wei, Zhiwei Dong, Jianfei Cai, and Bohan Zhuang.
We propose QLLM, an accurate and efficient low-bitwidth post-training quantization method designed for LLMs.
conda create -n qllm python=3.10 -y
conda activate qllm
git clone https://github.com/ModelTC/QLLM
cd QLLM
pip install --upgrade pip
pip install -e .
We provide the training scripts in scripts folder. For example, to perform W4A8 quantization for LLaMA-7B, run
sh scripts/llama-7b/w4a4.sh
Remember to change the path of model model and output path output_dir.
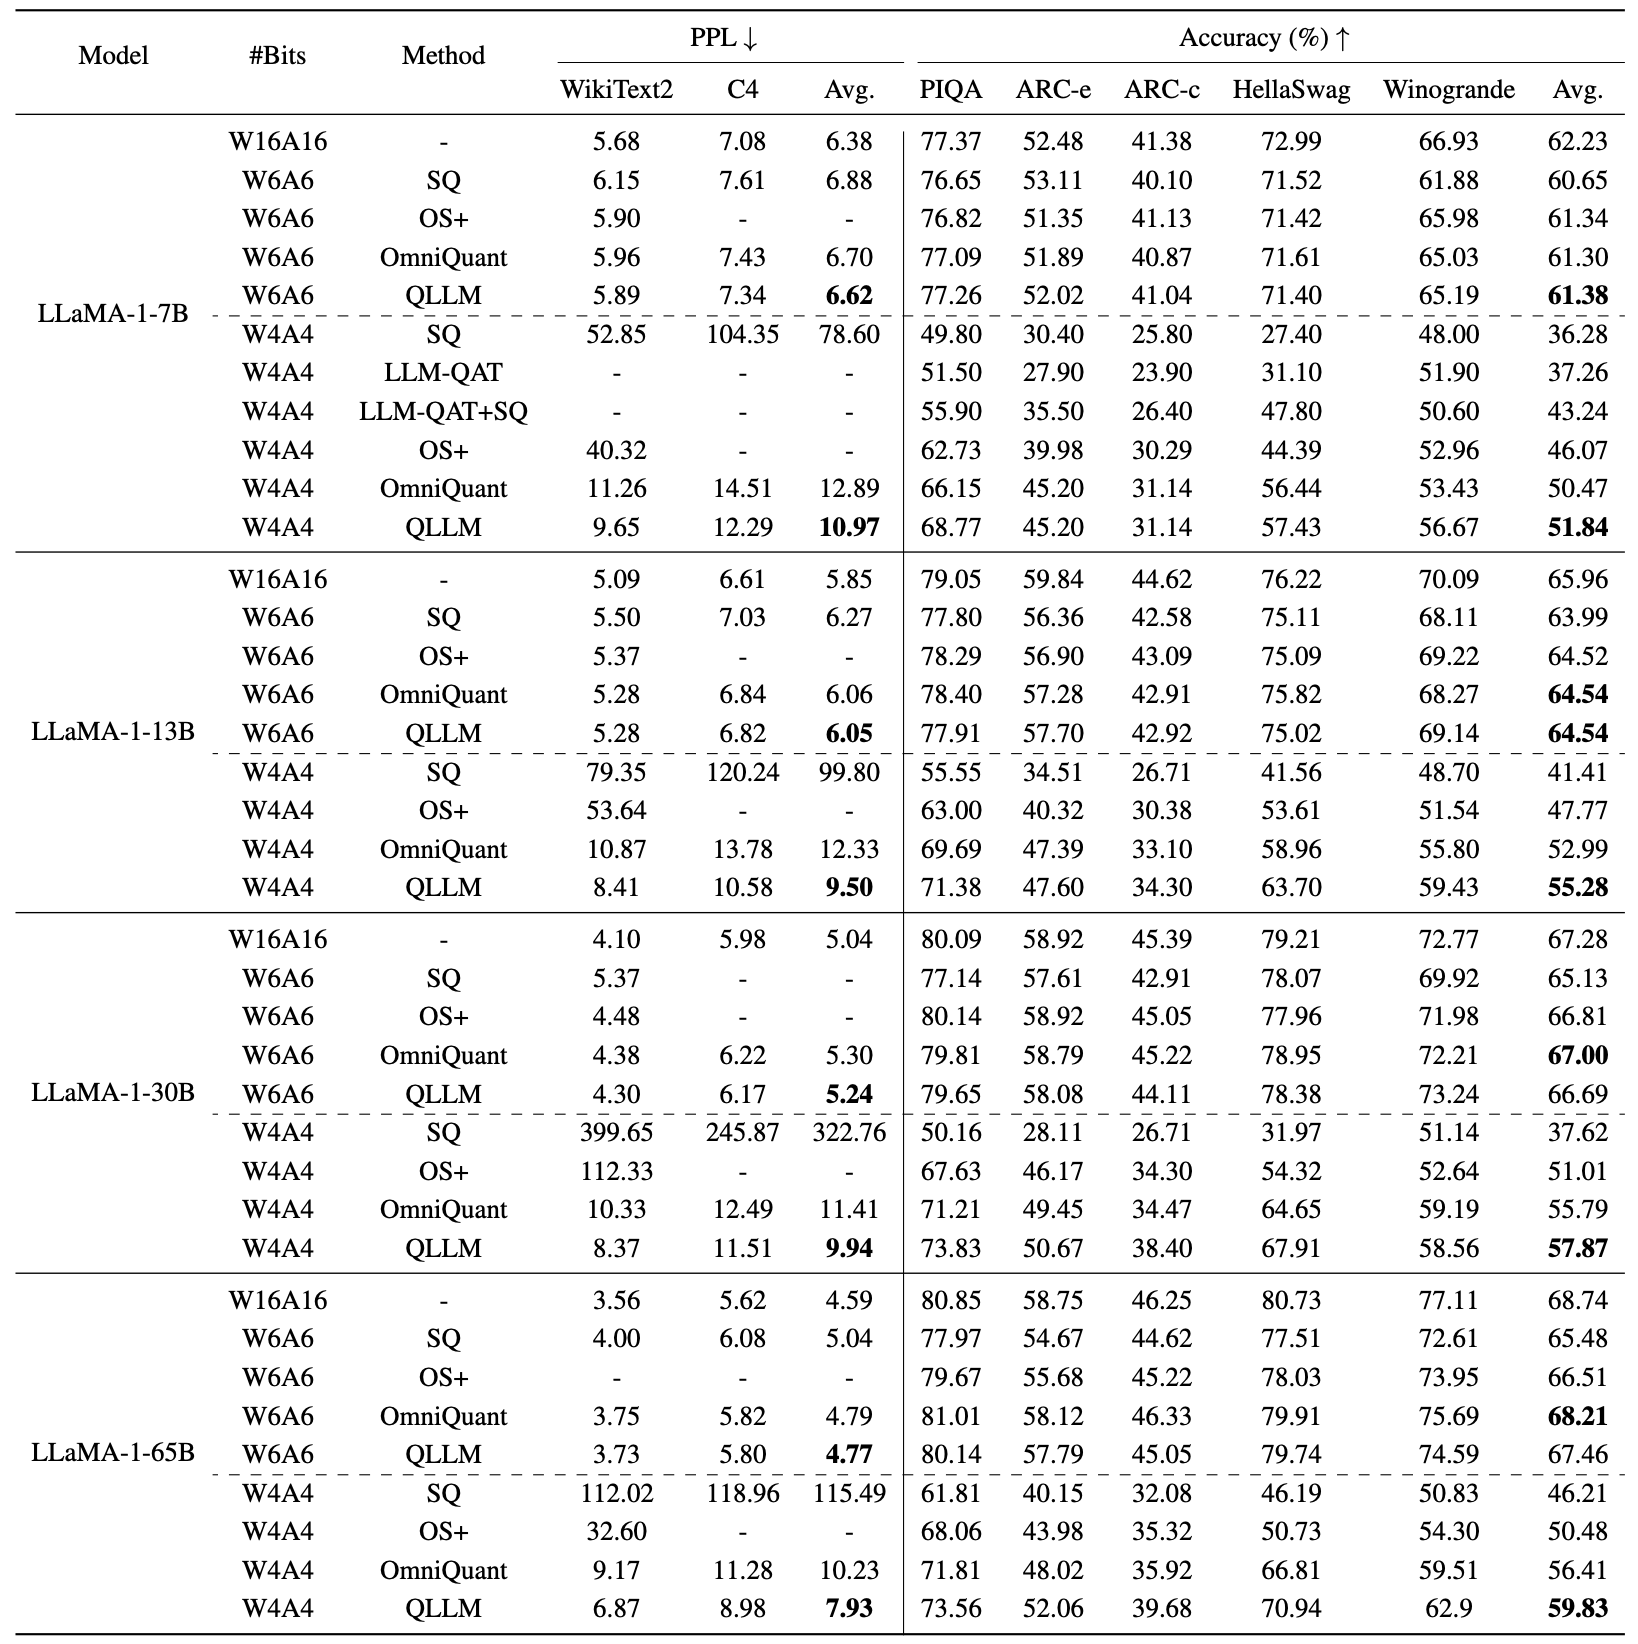
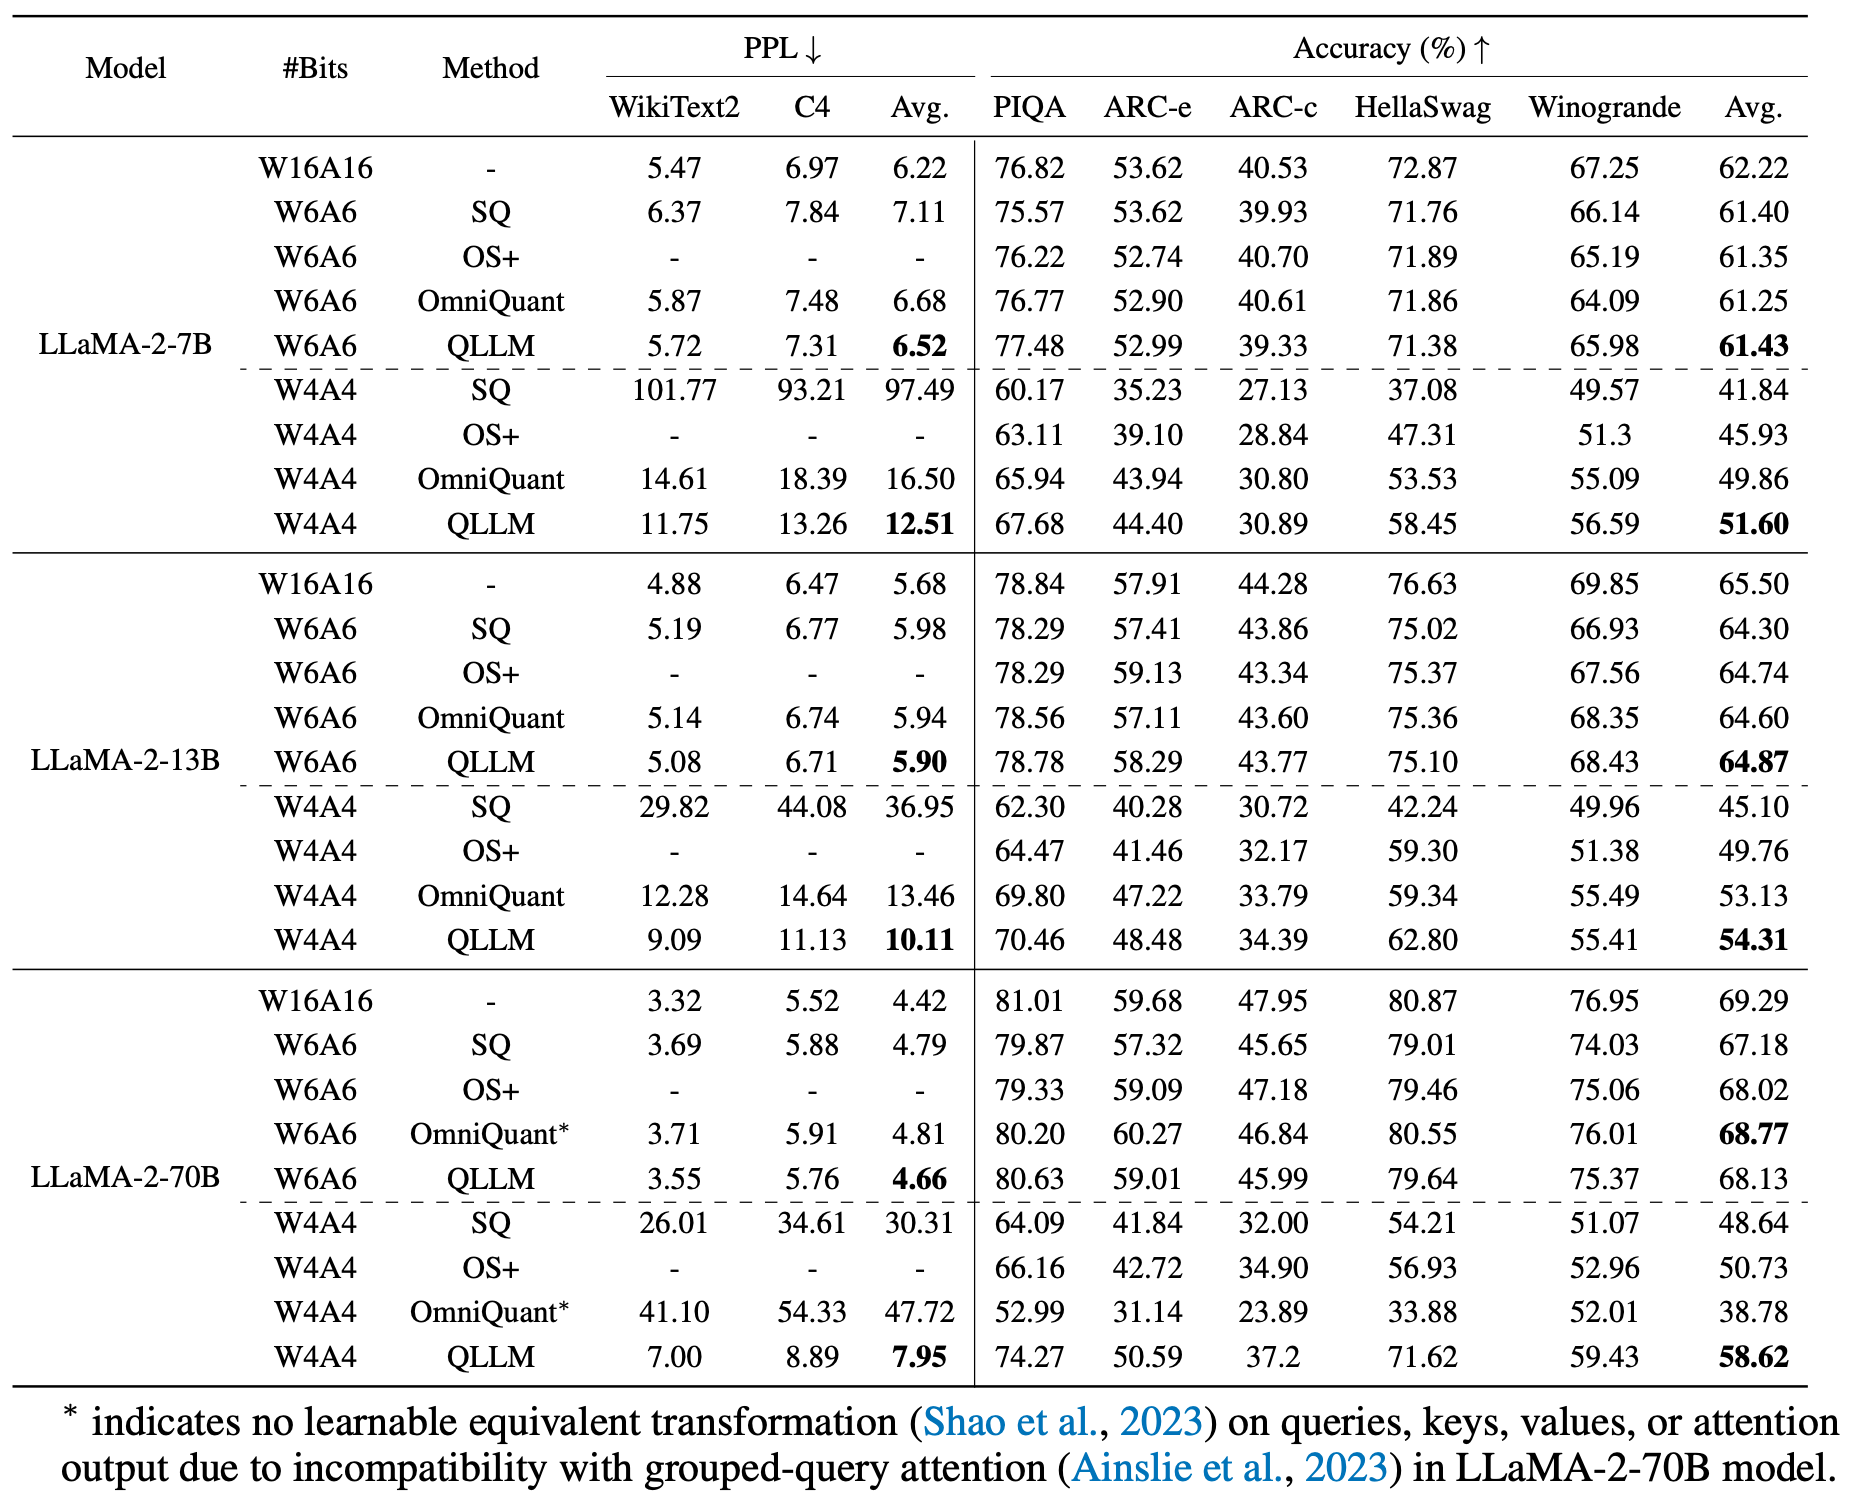
If you find our QLLM useful in your research, please consider to cite the following related papers:
@inproceedings{liu2024qllm,
  title = {{QLLM}: Accurate and Efficient Low-Bitwidth Quantization for Large Language Models},
  author = {Liu, Jing and Gong, Ruihao and Wei, Xiuying and Dong, Zhiwei and Cai, Jianfei and Zhuang, Bohan},
  booktitle = {International Conference on Learning Representations (ICLR)},
  year = {2024},
}
This repository is released under the Apache 2.0 license as found in the LICENSE file.
This repository is built upon OmniQuant. We thank the authors for their open-sourced code.
ModelTC/QLLM is a public repo on GitHub by ModelTC. [ICLR 2024] This is the official PyTorch implementation of "QLLM: Accurate and Efficient Low-Bitwidth Quantization for Large Language Models".
It declares the Apache-2.0 license on GitHub.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Its last change on GitHub was on 2024-03-11. GitHub counts 2 open issues and pull requests. Take My Repo does not judge from that whether it is maintained.
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.
Get up and running with Kimi, GLM, MiniMax, DeepSeek, gpt-oss, Qwen, Gemma and other models.
[NeurIPS'23 Oral] Visual Instruction Tuning (LLaVA) built towards GPT-4V level capabilities and beyond.
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
SOTA low-bit LLM quantization (INT8/FP8/MXFP8/INT4/MXFP4/NVFP4) & sparsity; leading model compression techniques on PyTorch, TensorFlow, and ONNX Runtime
A high-throughput and memory-efficient inference and serving engine for LLMs
LightLLM is a Python-based LLM (Large Language Model) inference and serving framework, notable for its lightweight design, easy scalability, and high-speed performance.
Qwen-Image-Lightning: Speed up Qwen-Image model with distillation
[EMNLP 2024 & AAAI 2026] A powerful toolkit for compressing large models including LLMs, VLMs, and video generative models.