Dive-into-Claude-Code
A Systematic Analysis and Discussion of Claude Code for Designing Today's and Future AI Agent Systems
- 2.2k
- 11 d ago

A principled instruction benchmark on formulating effective queries and prompts for large language models (LLMs). Our paper: https://arxiv.org/abs/2312.16171
Repo VILA-Lab/ATLAS, read from GitHub 12 h ago. VILA-Lab has not joined Take My Repo.
VILA-Lab/ATLAS is a public repo on GitHub by VILA-Lab. A principled instruction benchmark on formulating effective queries and prompts for large language models (LLMs). Our paper: https://arxiv.org/abs/2312.16171. It declares the Apache-2.0 license on GitHub. It is written mainly in Python, has 989 stars and last changed on 2024-05-28. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-20.

This repository contains resources and research on formulating effective queries and prompts for large language models (LLMs). The primary contribution is the introduction of 26 guiding principles aimed at optimizing interactions with LLMs of various scales, such as LLaMA-1/2, GPT-3.5, and GPT-4.

Our work aims to simplify the underlying concepts of formulating questions for different scales of large language models. By examining their abilities and enhancing user comprehension, we focus on optimizing the design of instructions and prompts. Extensive experiments conducted on models like LLaMA-1/2 and GPT-3.5/4 have verified the effectiveness of the proposed principles.

Our dataset, comprising 13k data points, supports the study of LLM prompting principles. The data is curated to facilitate understanding and application of the 26 principles.
Our project includes two types of datasets, catering to different needs and research focuses:
General Dataset (general_dataset.json): This comprehensive dataset combines all the examples from each of the 26 principles into a single file, offering a holistic view of our research and its diverse applications.
general_dataset.jsonInstruction field describing the task.{model_name}_conversations field provides the model-generated response to the instruction.Example:
{
   "id": "identity_0",
   "model": "gpt4",
   "conversations": [
     {
       "from": "human",
       "value": "Explain the process of photosynthesis."
     },
     {
       "from": "gpt",
       "value": "Photosynthesis is a biochemical process..."
     }
   ]
 },
Individual Principle Datasets: We offer separate datasets for boosting and correctness for each of the 26 principles for a more focused study. These files allow researchers to explore and analyze data of specific principles in isolation.
Our benchmark is compatible with Stanford Alpaca or FastChat. We will further provide the finetuned models.
Prompt Enhancer and its GitHub is a web service and tool designed to enable users to select specific principles to enhance the prompts. Special thanks to Lim Hyo Jeong for the excellent contribution!
Magic Prompts is an easy tool to generate high-quality prompts. Special thanks to Lyzr for the excellent contribution!
Prompt-builder and its GitHub is a small Python tool and application that allows users to generate natural language prompts adhering to specific rules and guidelines defined in our paper. Special thanks to lypsoty112 for the excellent contribution!
@article{bsharat2023principled,
  title={Principled Instructions Are All You Need for Questioning LLaMA-1/2, GPT-3.5/4},
  author={Sondos Mahmoud Bsharat, Aidar Myrzakhan, Zhiqiang Shen},
  journal={arXiv preprint arXiv:2312.16171},
  year={2023},
}
We welcome contributions and suggestions to improve our principles and expand the dataset.
VILA-Lab/ATLAS is a public repo on GitHub by VILA-Lab. A principled instruction benchmark on formulating effective queries and prompts for large language models (LLMs). Our paper: https://arxiv.org/abs/2312.16171.
It declares the Apache-2.0 license on GitHub.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Its last change on GitHub was on 2024-05-28. Take My Repo does not judge from that whether it is maintained.
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.
A Systematic Analysis and Discussion of Claude Code for Designing Today's and Future AI Agent Systems
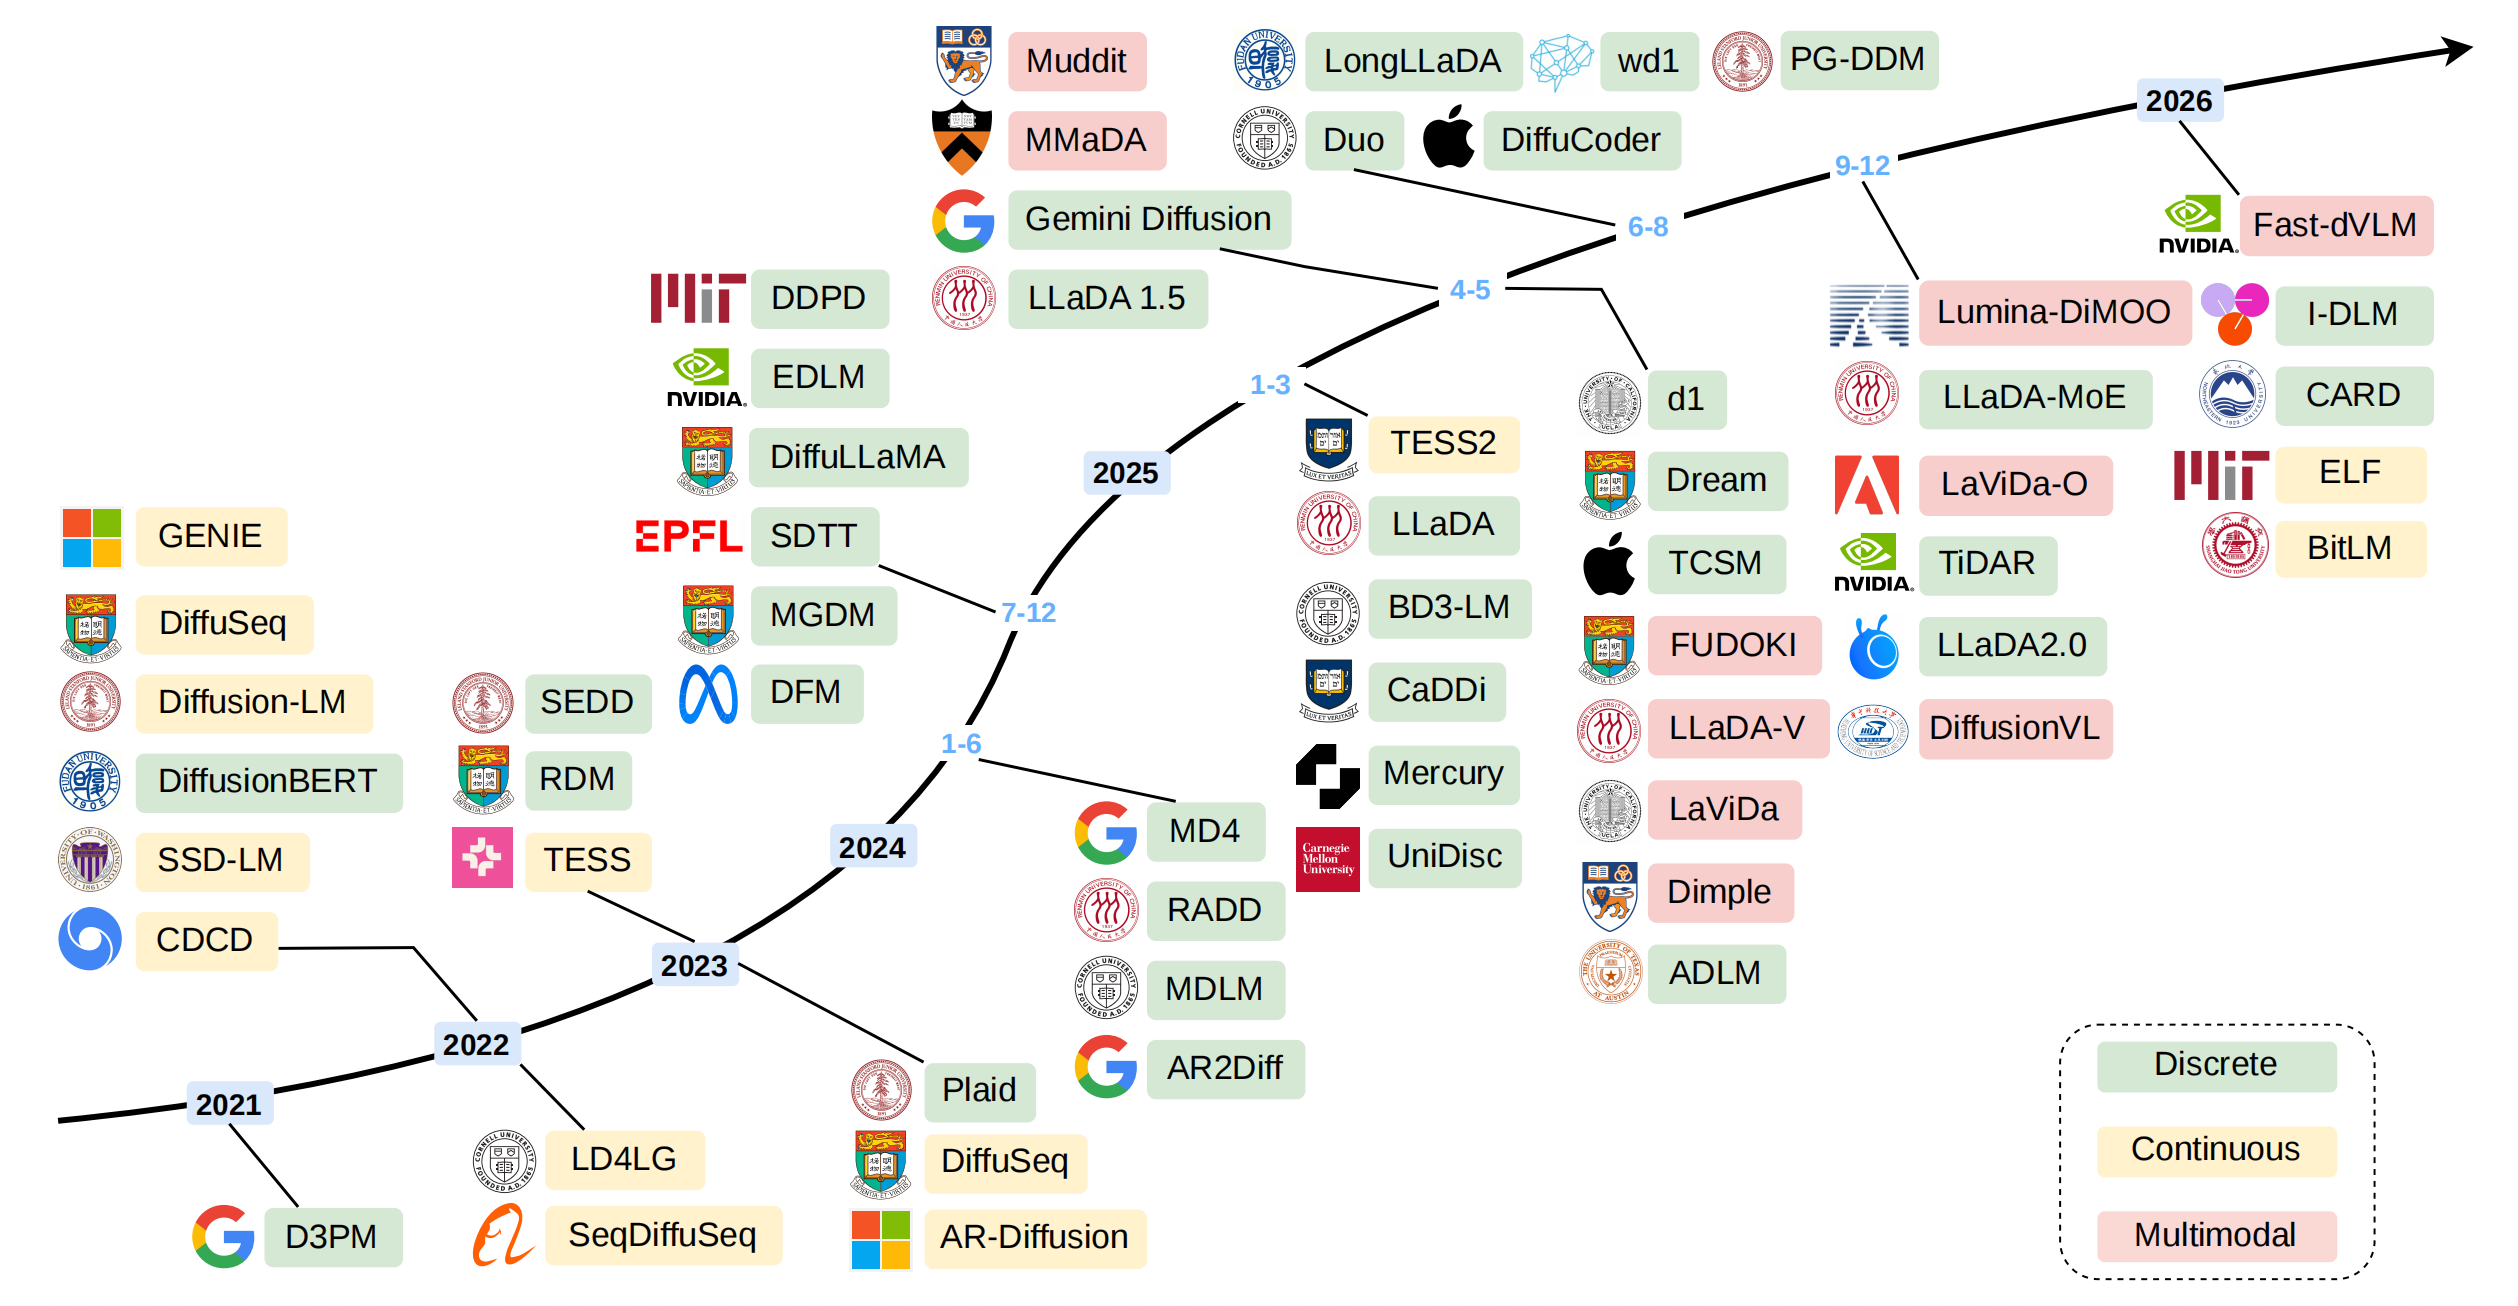
The official GitHub repo for the survey paper "A Survey on Diffusion Language Models".
An Automated AI Agent Tool for Plotting Your Data in Any Paper's Figure Style.
(NeurIPS 2023 spotlight) Large-scale Dataset Distillation/Condensation, 50 IPC (Images Per Class) achieves the highest 60.8% on original ImageNet-1K val set.
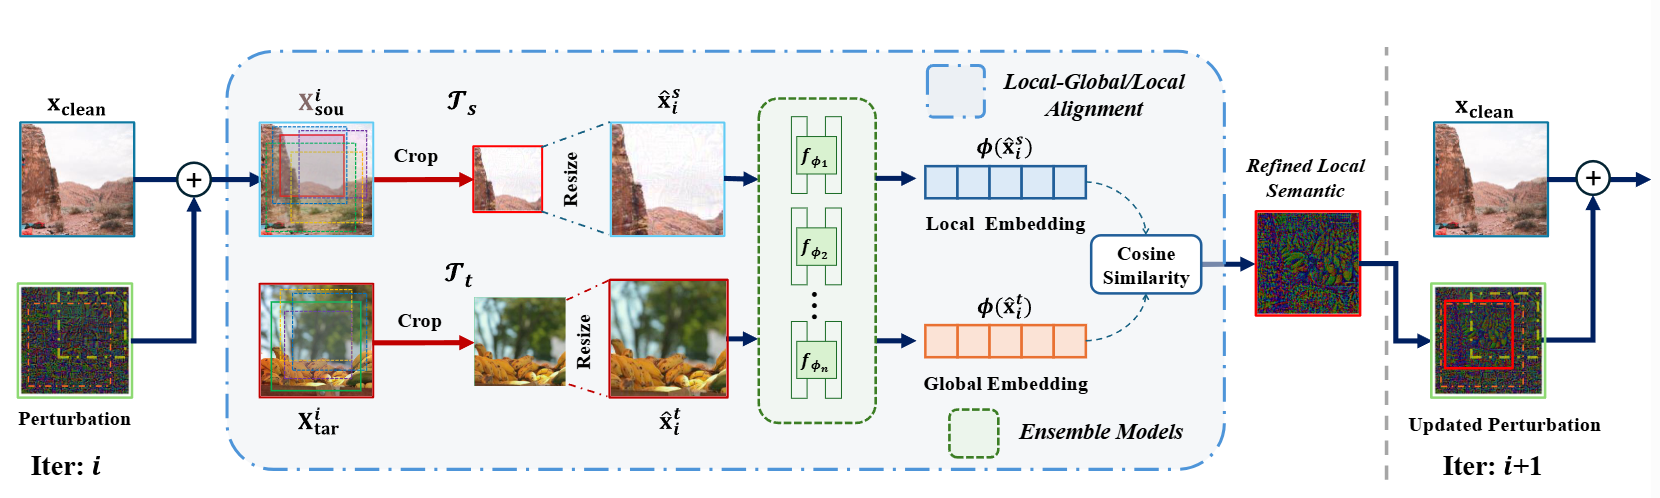
[NeurIPS25 & ICML25 Workshop on Reliable and Responsible Foundation Models] A Simple Baseline Achieving Over 90% Success Rate Against the Strong Black-box Models of GPT-4.5/4o/o1. Paper at: https://arxiv.org/abs/2503.10635
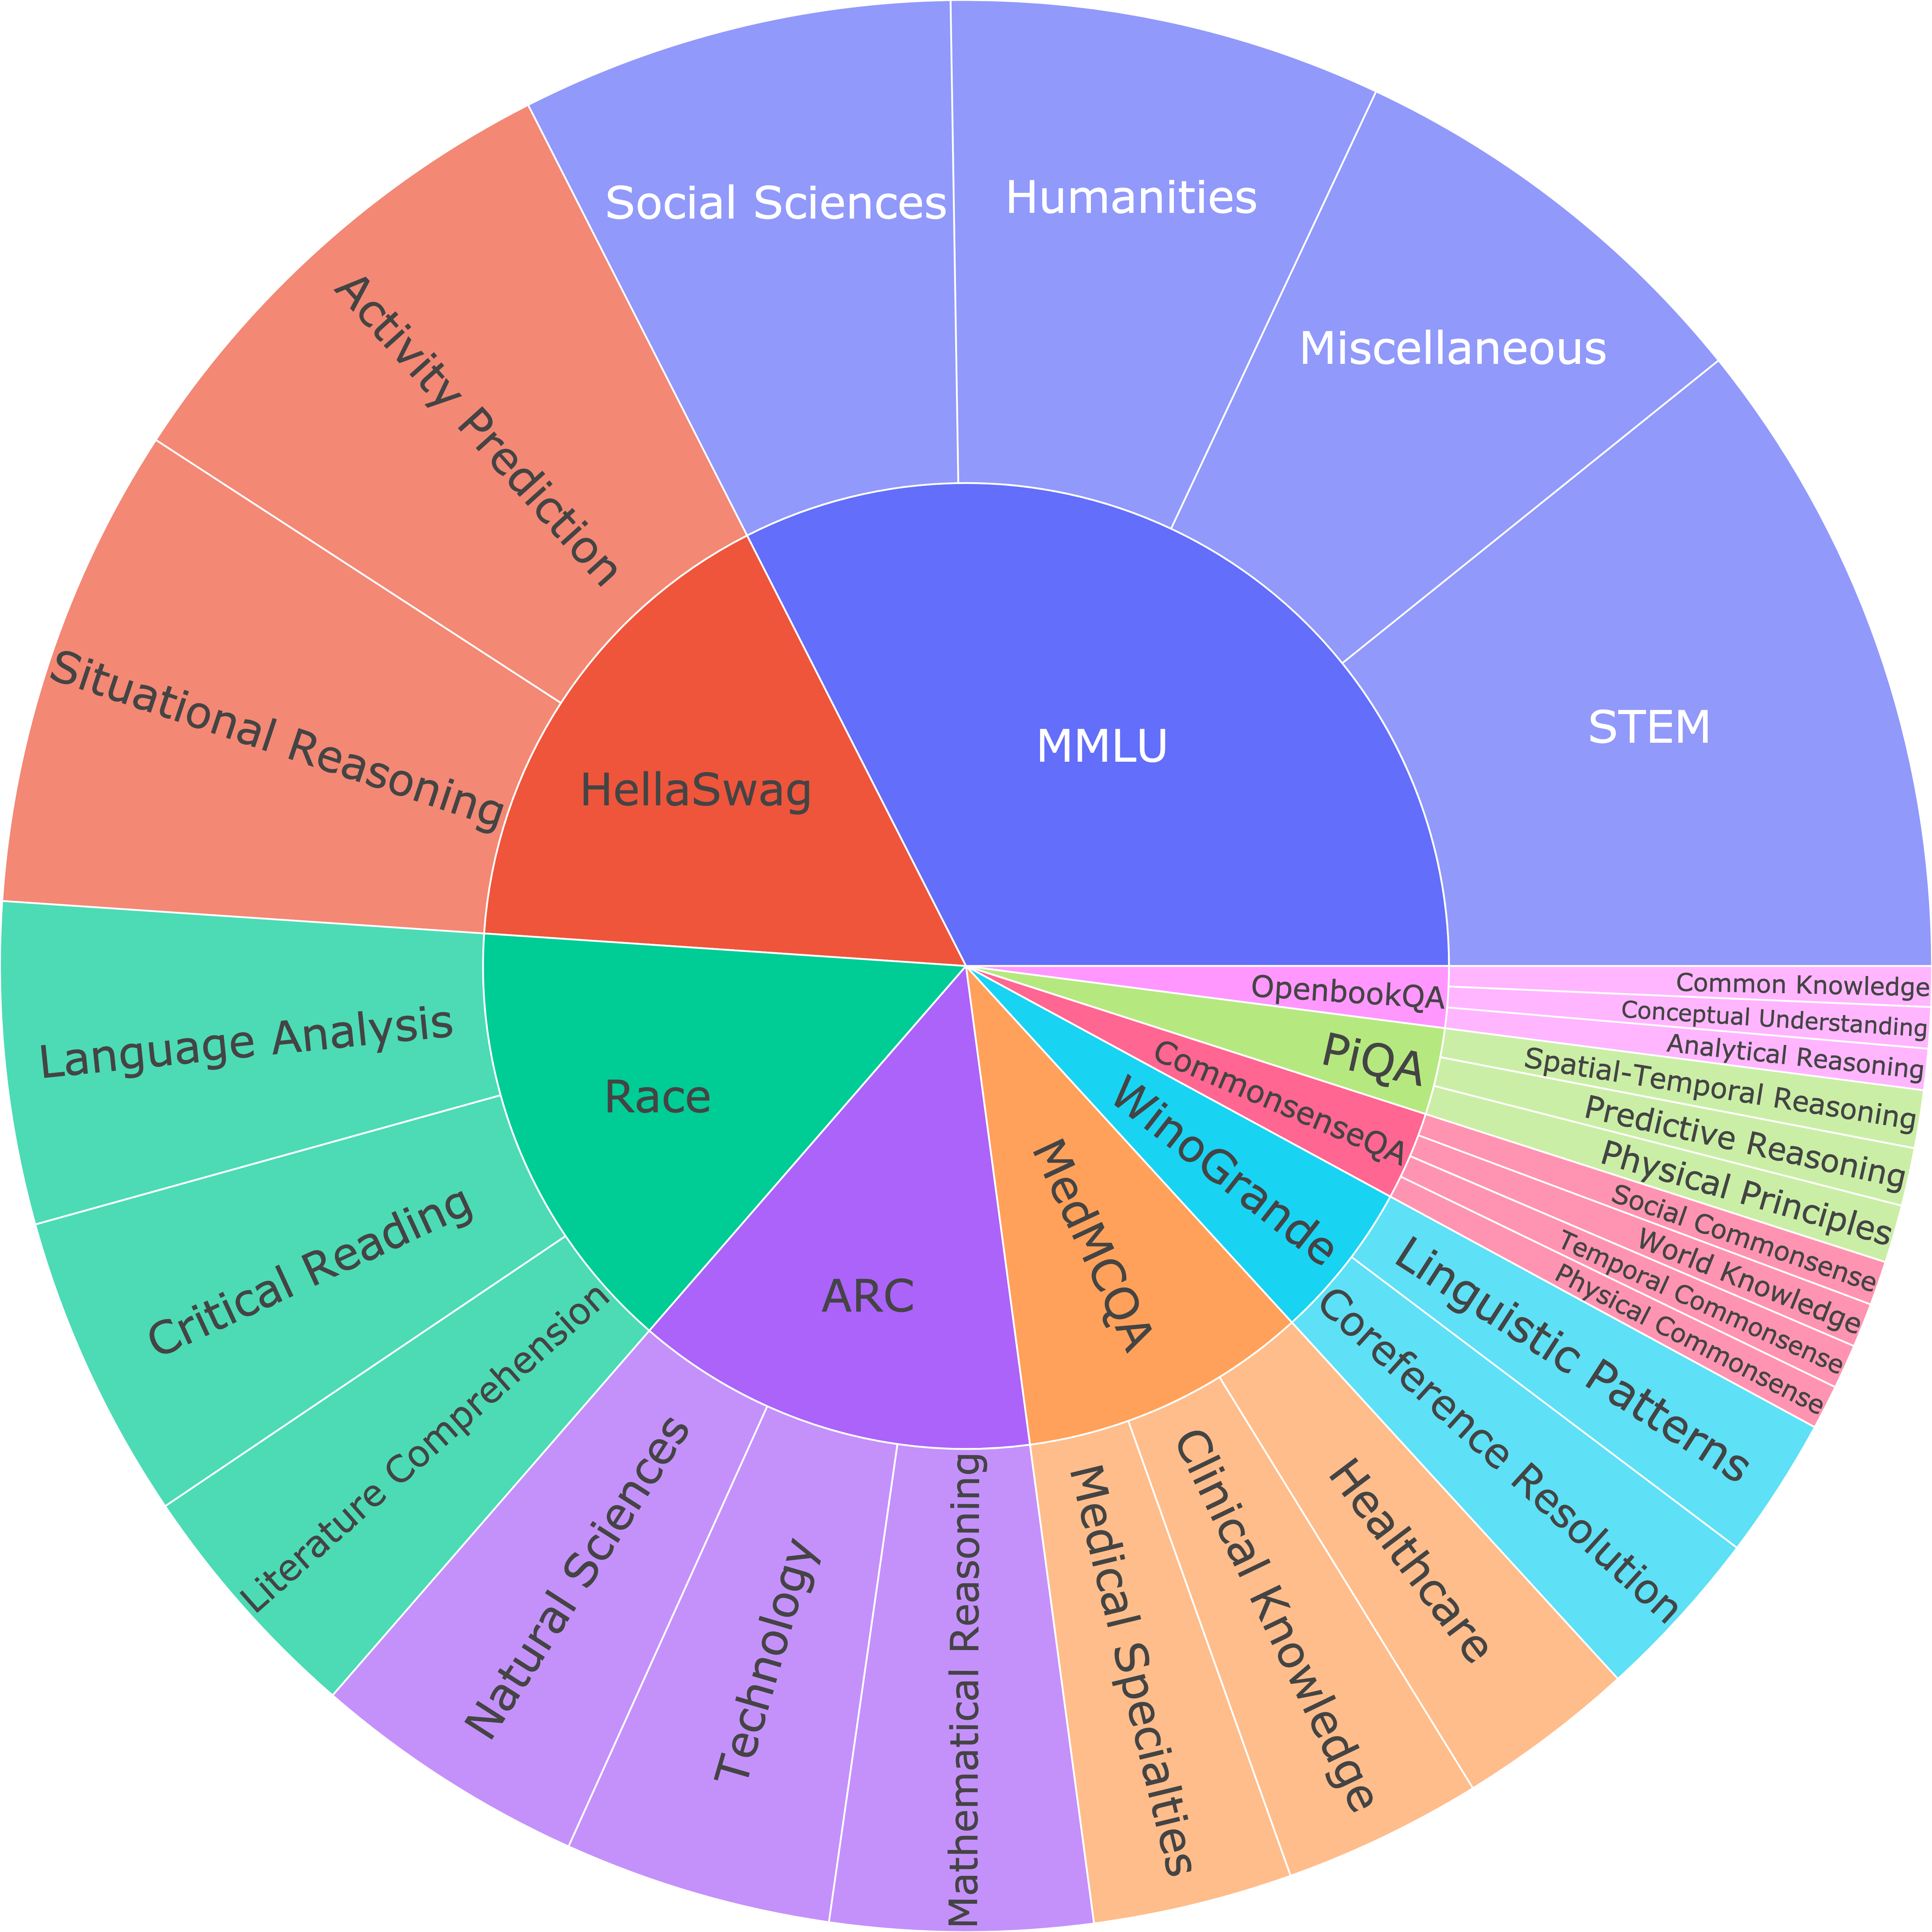
Open-LLM-Leaderboard: Open-Style Question Evaluation. Paper at https://arxiv.org/abs/2406.07545