Dive-into-Claude-Code
A Systematic Analysis and Discussion of Claude Code for Designing Today's and Future AI Agent Systems
- 2.2k
- 11 d ago
Operation-guided benchmark for AI-text detection under progressive human–AI revision trajectories.
Repo VILA-Lab/OpAI-Bench, read from GitHub 23 h ago. VILA-Lab has not joined Take My Repo.
VILA-Lab/OpAI-Bench is a public repo on GitHub by VILA-Lab. Operation-guided benchmark for AI-text detection under progressive human–AI revision trajectories. It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it. It is written mainly in Python, has 11 stars and last changed on 2026-06-07. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-20.
GitHub is limiting requests or did not answer. The facts on this page still come from the last successful read.
Open on GitHubVILA-Lab/OpAI-Bench is a public repo on GitHub by VILA-Lab. Operation-guided benchmark for AI-text detection under progressive human–AI revision trajectories.
It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Its last change on GitHub was on 2026-06-07. Take My Repo does not judge from that whether it is maintained.
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.
A Systematic Analysis and Discussion of Claude Code for Designing Today's and Future AI Agent Systems
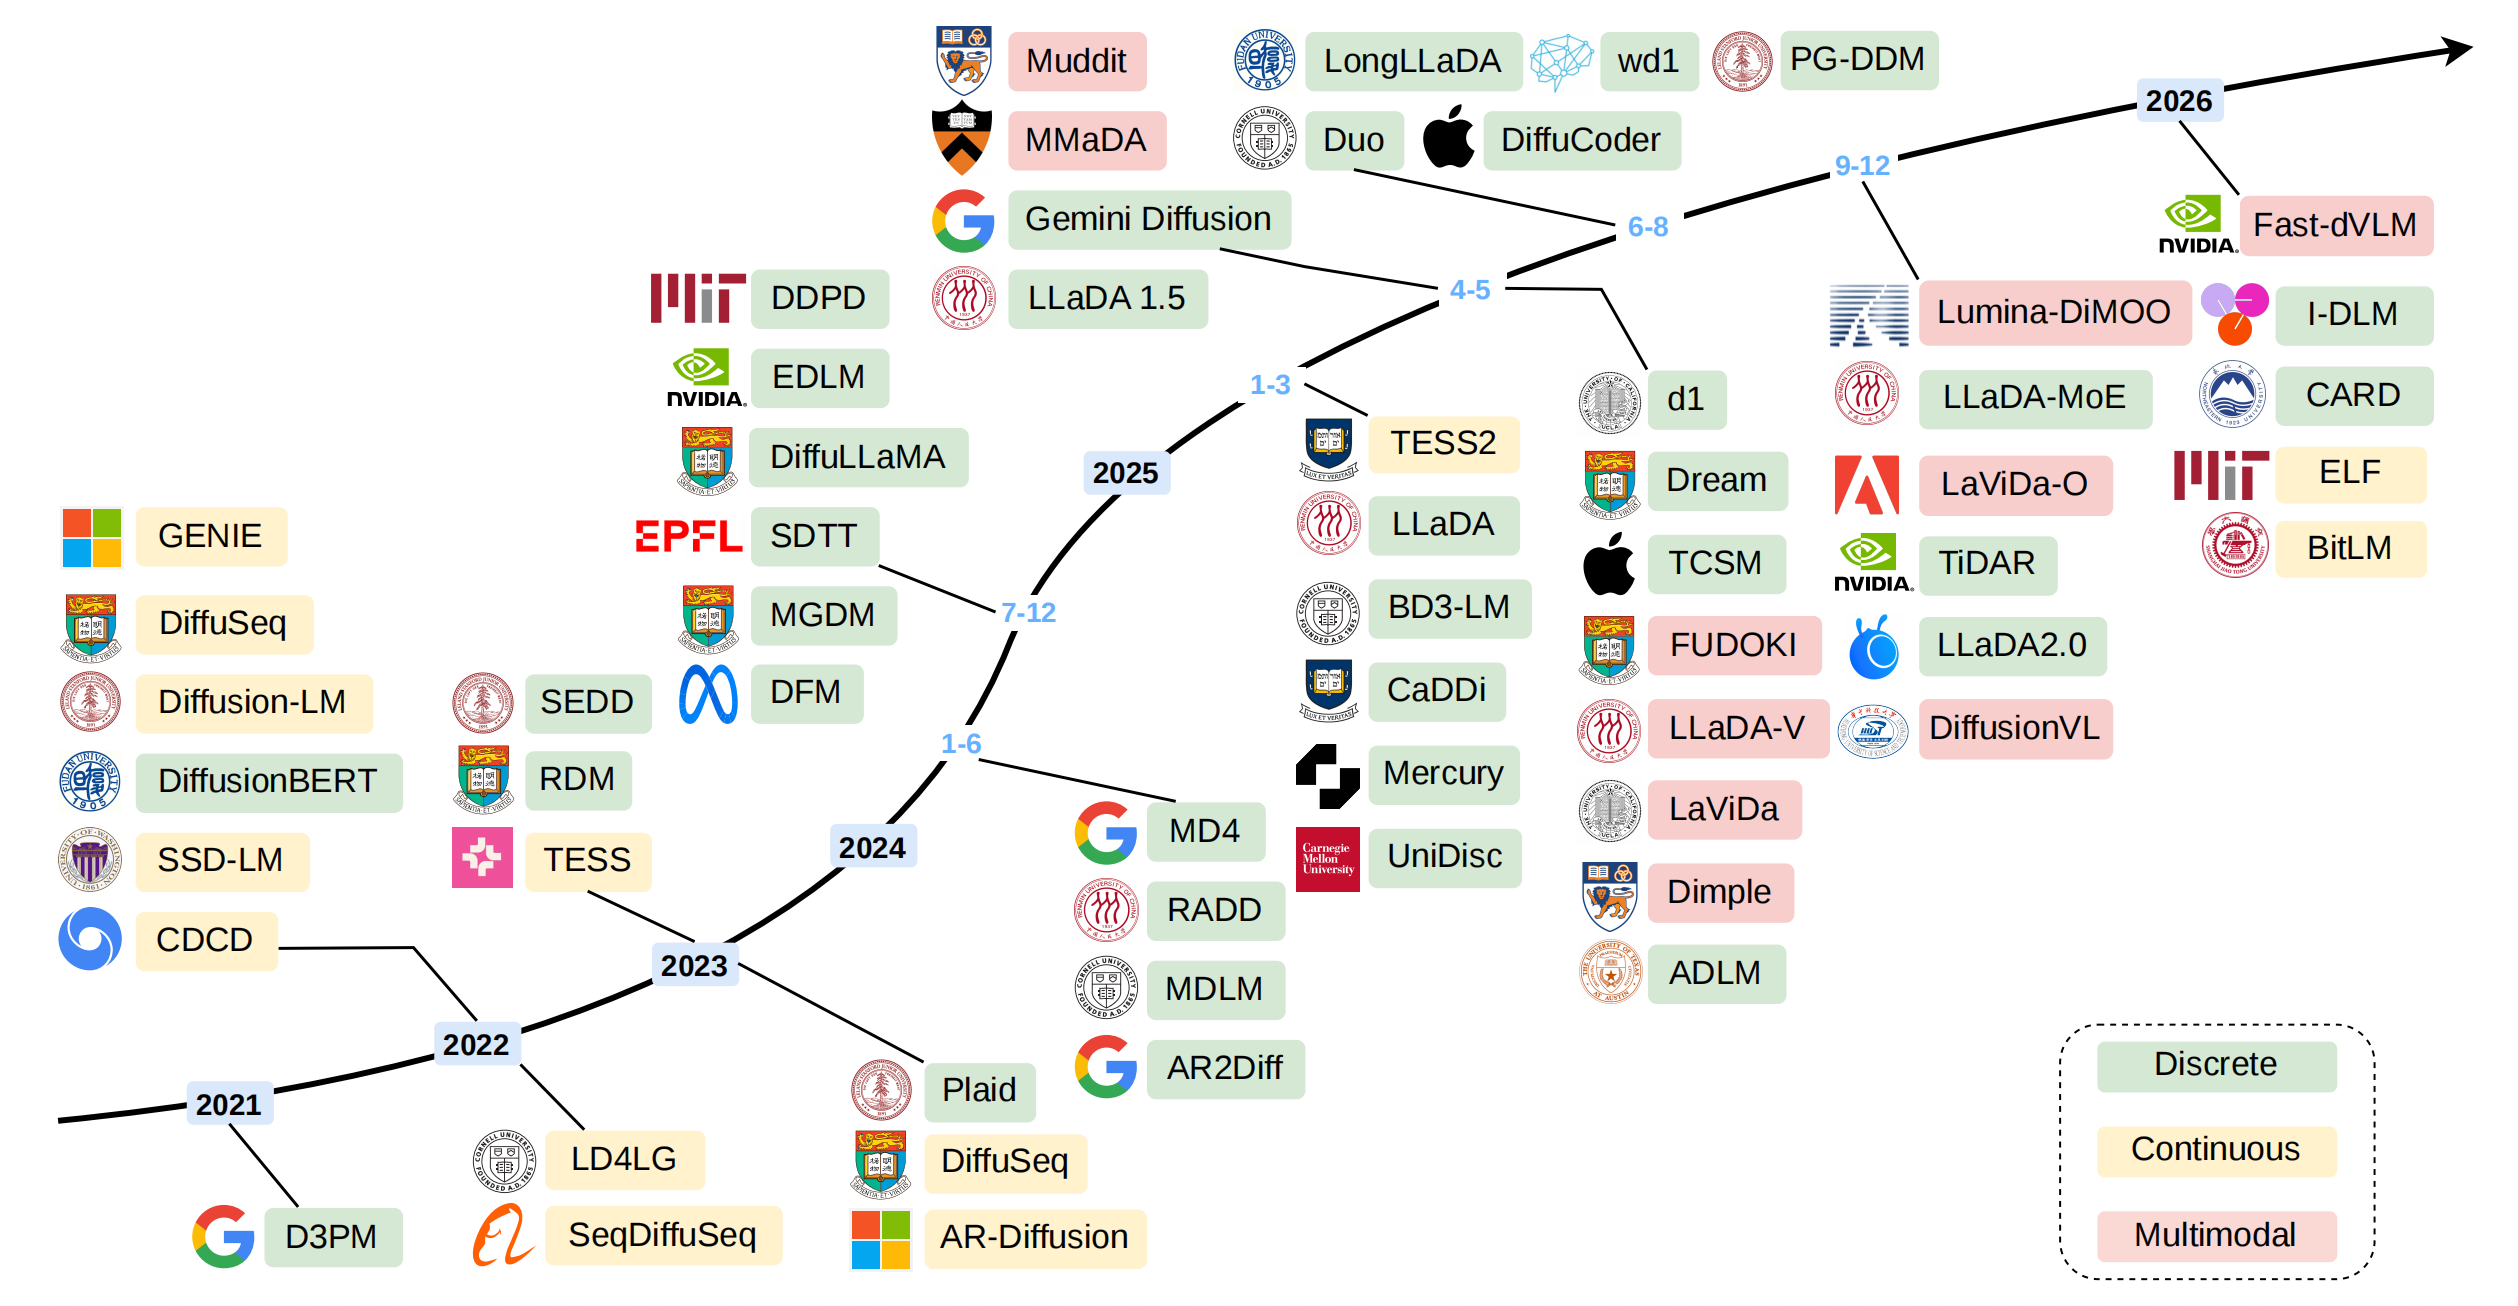
The official GitHub repo for the survey paper "A Survey on Diffusion Language Models".
A principled instruction benchmark on formulating effective queries and prompts for large language models (LLMs). Our paper: https://arxiv.org/abs/2312.16171
An Automated AI Agent Tool for Plotting Your Data in Any Paper's Figure Style.
(NeurIPS 2023 spotlight) Large-scale Dataset Distillation/Condensation, 50 IPC (Images Per Class) achieves the highest 60.8% on original ImageNet-1K val set.