sdxl


SUPIR
SUPIR aims at developing Practical Algorithms for Photo-Realistic Image Restoration In the Wild. Our new online demo is also released at suppixel.ai.
- 5.7k
- Python
- 19 mo ago

onediff
OneDiff: An out-of-the-box acceleration library for diffusion models.
- 2k
- Jupyter Notebook
- Apache-2.0
- 12 mo ago

ComfyUI_Comfyroll_CustomNodes
Custom nodes for SDXL and SD1.5 including Multi-ControlNet, LoRA, Aspect Ratio, Process Switches, and many more nodes.
- 1.4k
- Python
- 2 y ago

comfyui
ComfyUI docker images for use in GPU cloud and local environments. Includes AI-Dock base for authentication and improved user experience.
- 1.1k
- Shell
- 2 y ago


Awesome-DiT-Inference
📚A curated list of Awesome Diffusion Inference Papers with Codes: Sampling, Cache, Quantization, Parallelism, etc.🎉
- 598
- Python
- GPL-3.0
- 5 mo ago

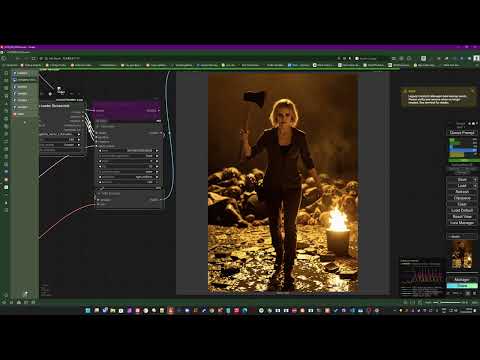
comfyUI-Realtime-Lora
Train and block edit and save LoRAs directly inside ComfyUI for Z-image, Flux Klein, SDXL, Flux, WAN 2.2, SD 1.5
- 579
- Python
- MIT
- 3 d ago

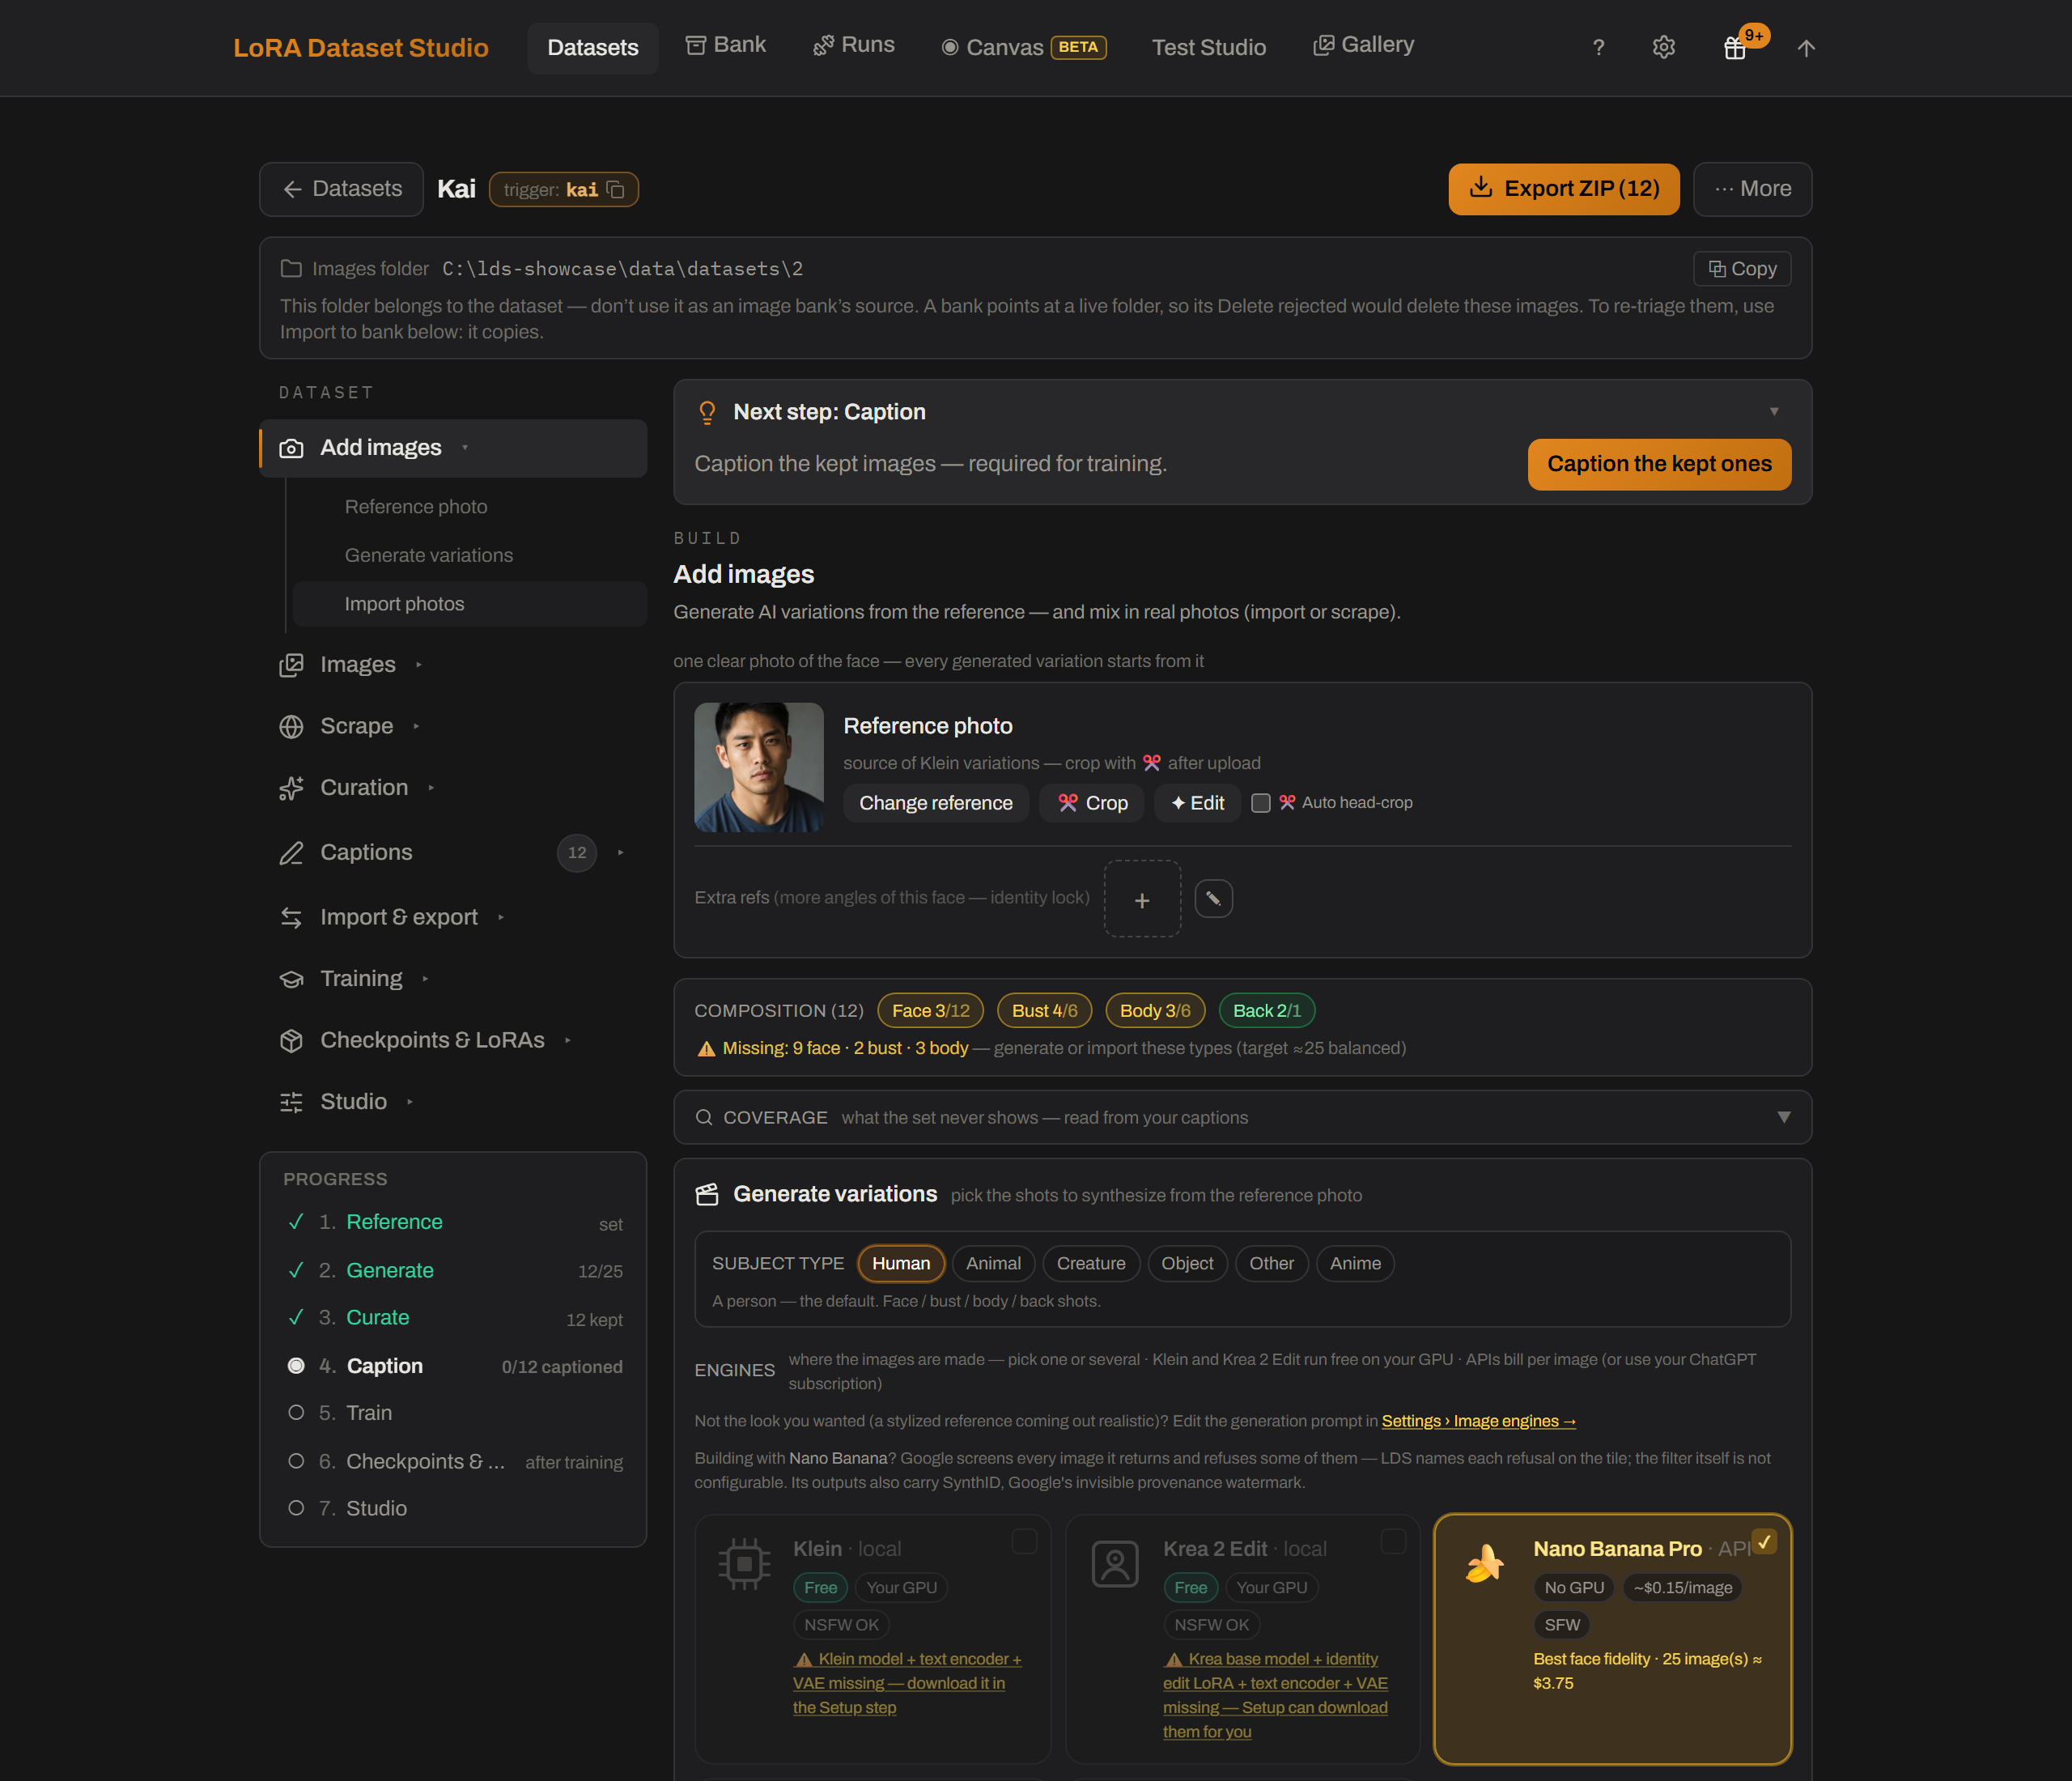
lora-dataset-studio
Free local LoRA training studio: build character, style and concept datasets from one photo or a big image folder, caption them (JoyCaption, prose or booru tags), train LoRAs with ai-toolkit for Krea 2, FLUX.1, FLUX.2 Klein, Qwen-Image 2.1, Z-Image, SDXL and Anima, then compare checkpoints side by side. ComfyUI-powered, self-hosted.
- 362
- Python
- 6 d ago

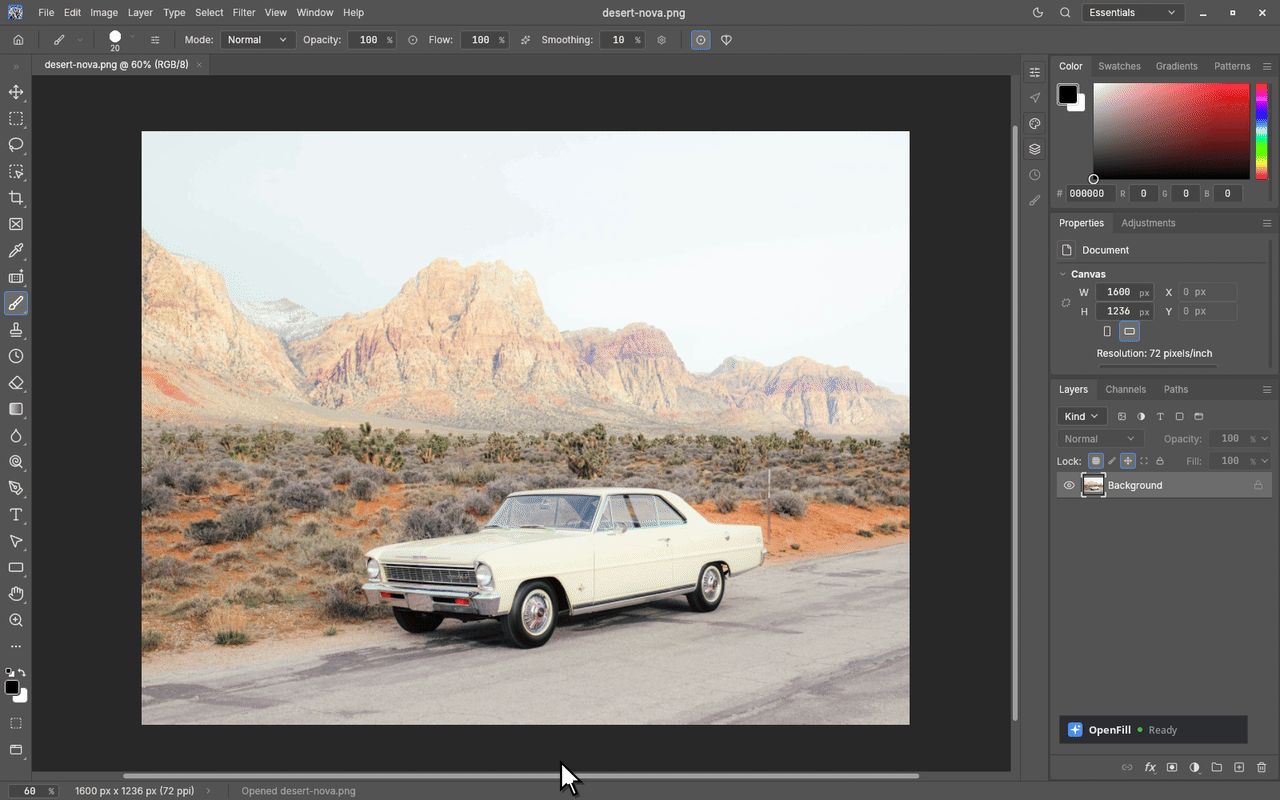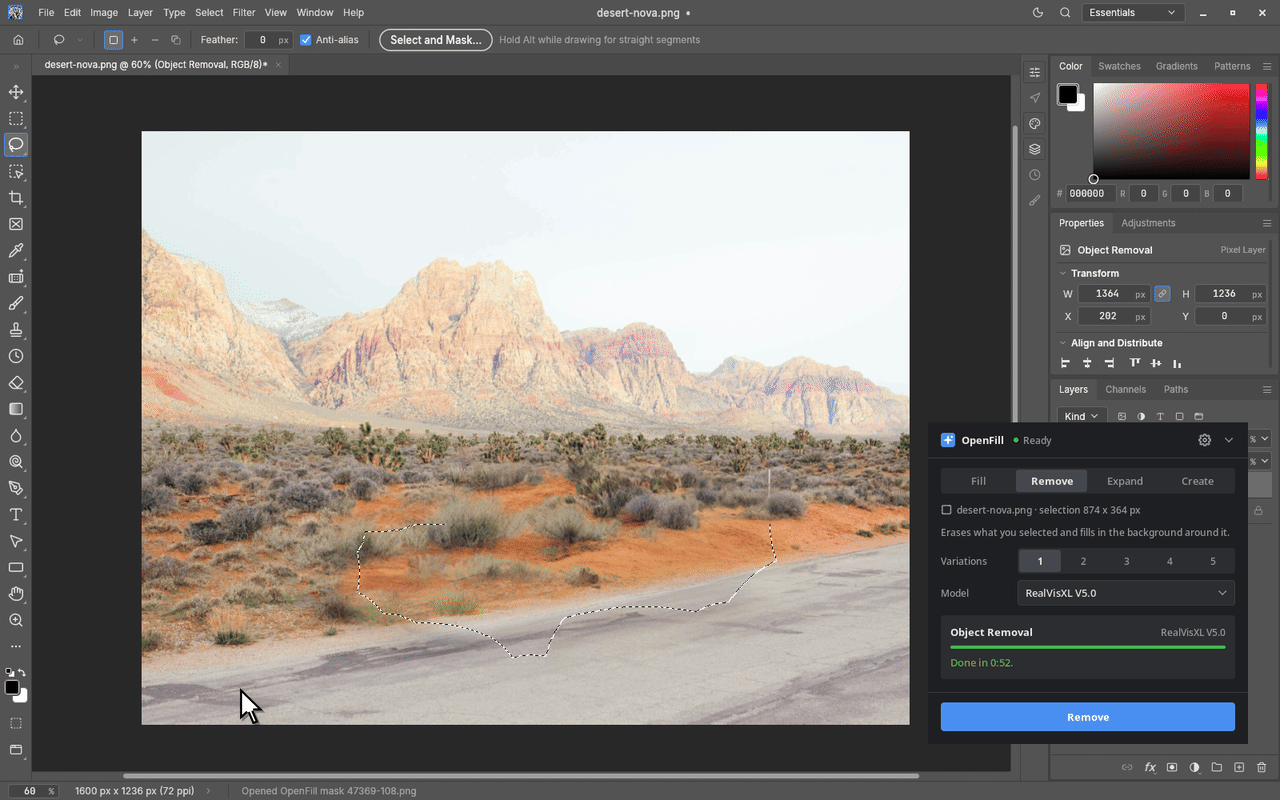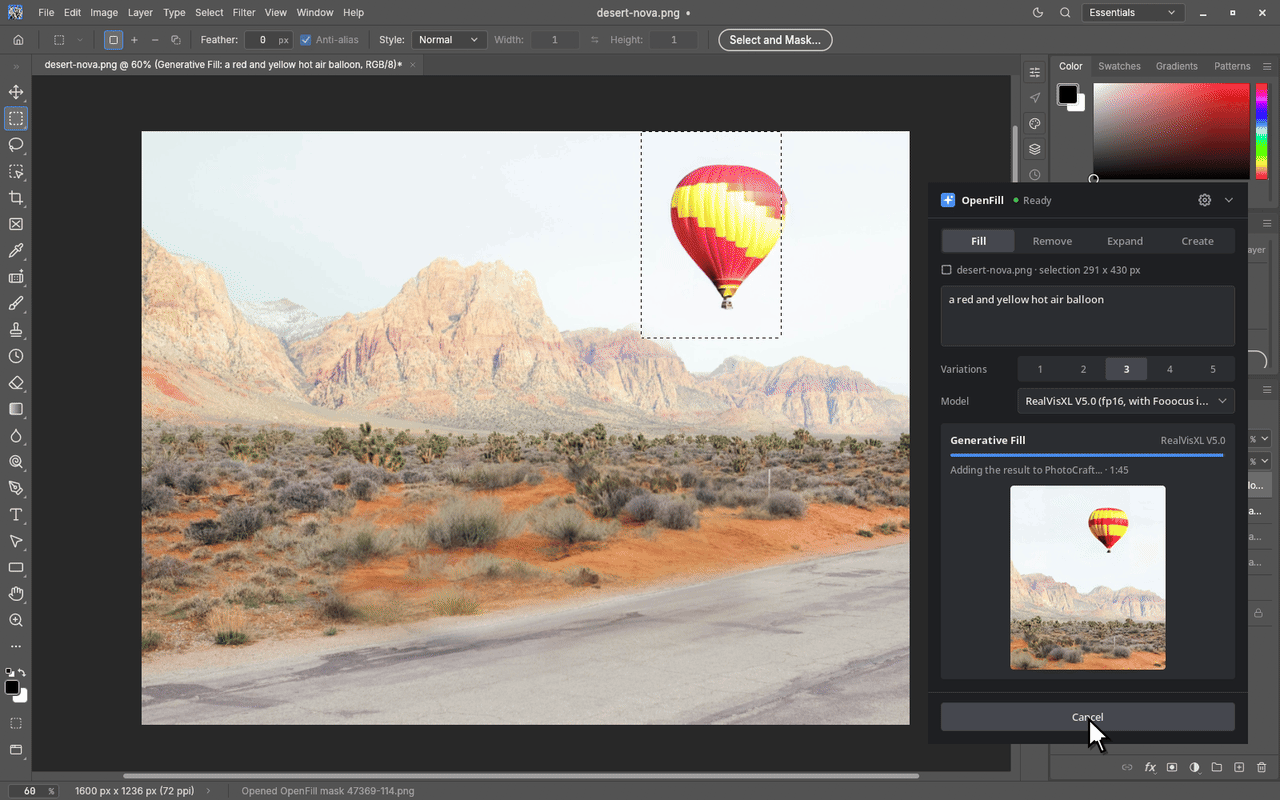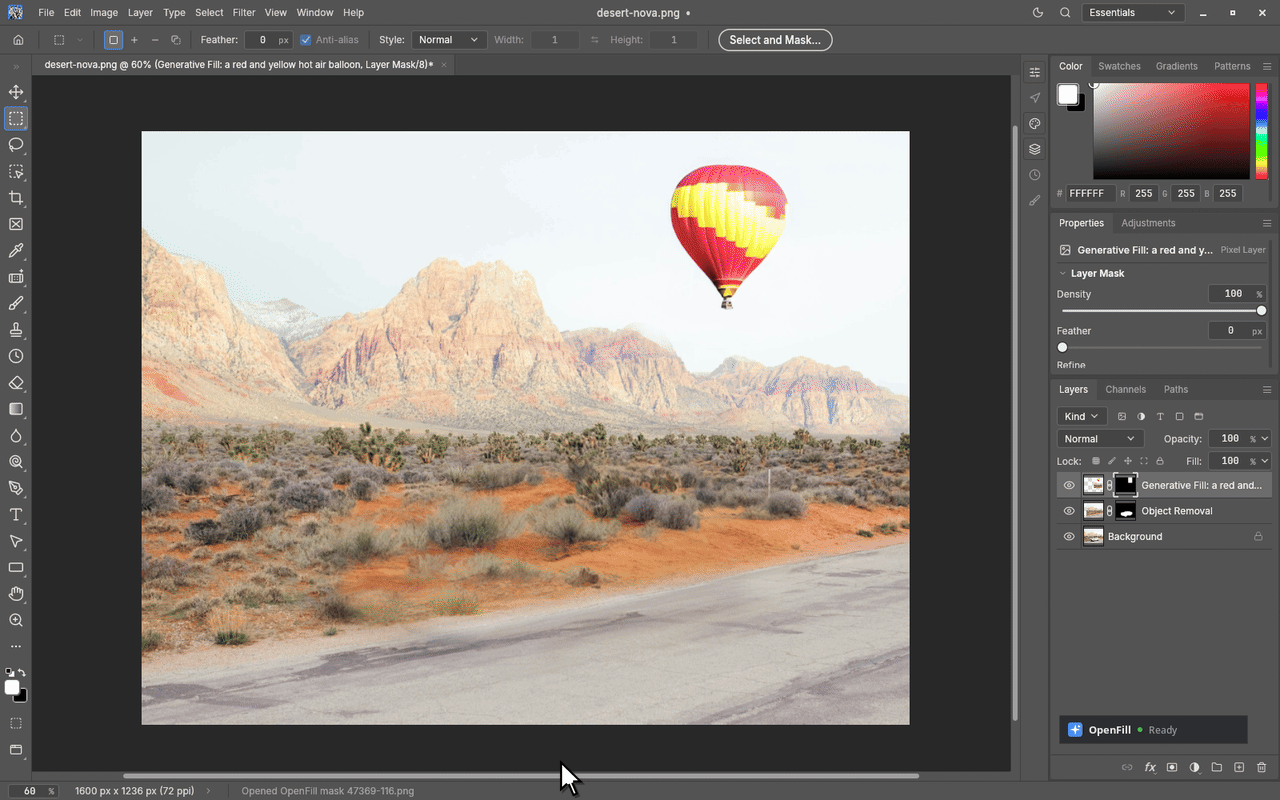
openfill
Generative Fill, Remove object, Generative Expand and Text to Image for PhotoCraft and GIMP 3. Free, local, on your own GPU through ComfyUI.
- 322
- Python
- Apache-2.0
- 2 d ago

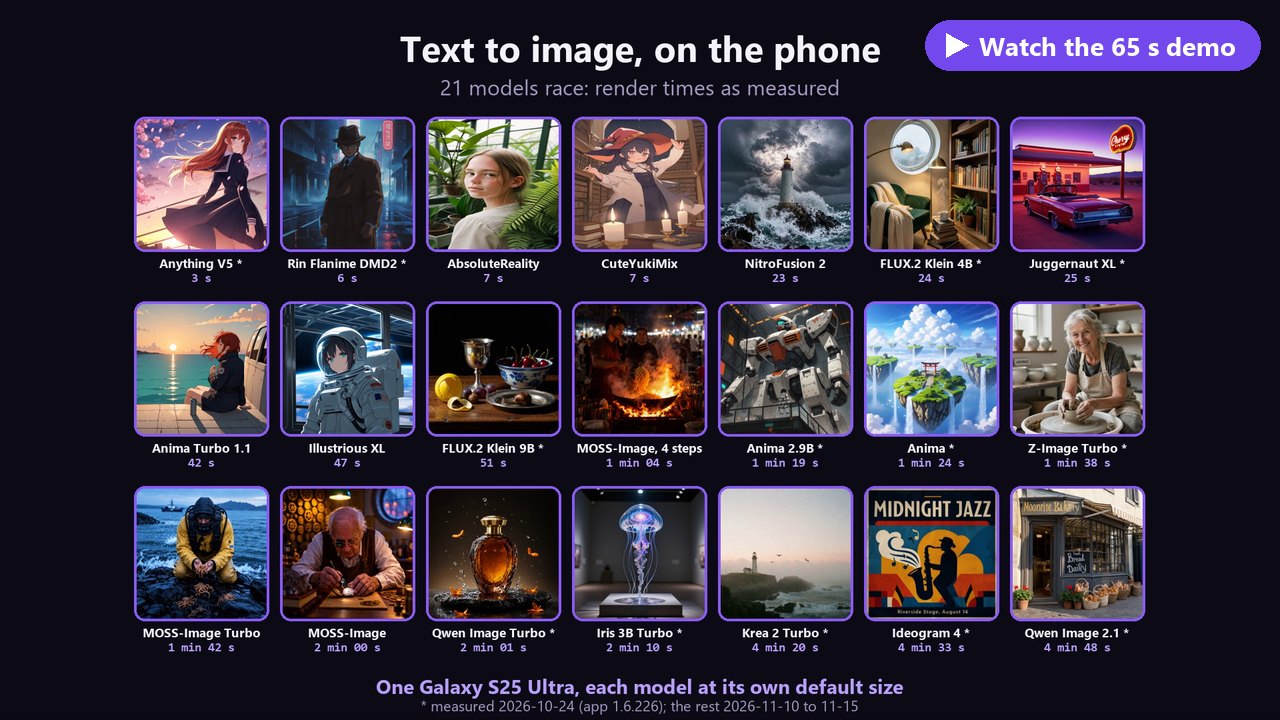
nightmare-mobile
On-device, ComfyUI-style node graph for image/video diffusion on Android. Run MiniMax H3 and WAN 2.2 14B on the Qualcomm Hexagon NPU. SD1.5, SDXL, Flux, Z-Image, Anima, Qwen Image 2.1, Krea 2 & MOSS Image. Inpainting, outpainting, ControlNet, LoRA, IP-Adapter & LivePortrait. Fully offline, no server, no account.
- 301
- Kotlin
- 20 h ago


diffused-texture-addon
Generate Diffuse Textures on Meshes directly in Blender 3D with Stable Diffusion.
- 262
- Python
- GPL-3.0
- 4 wk ago


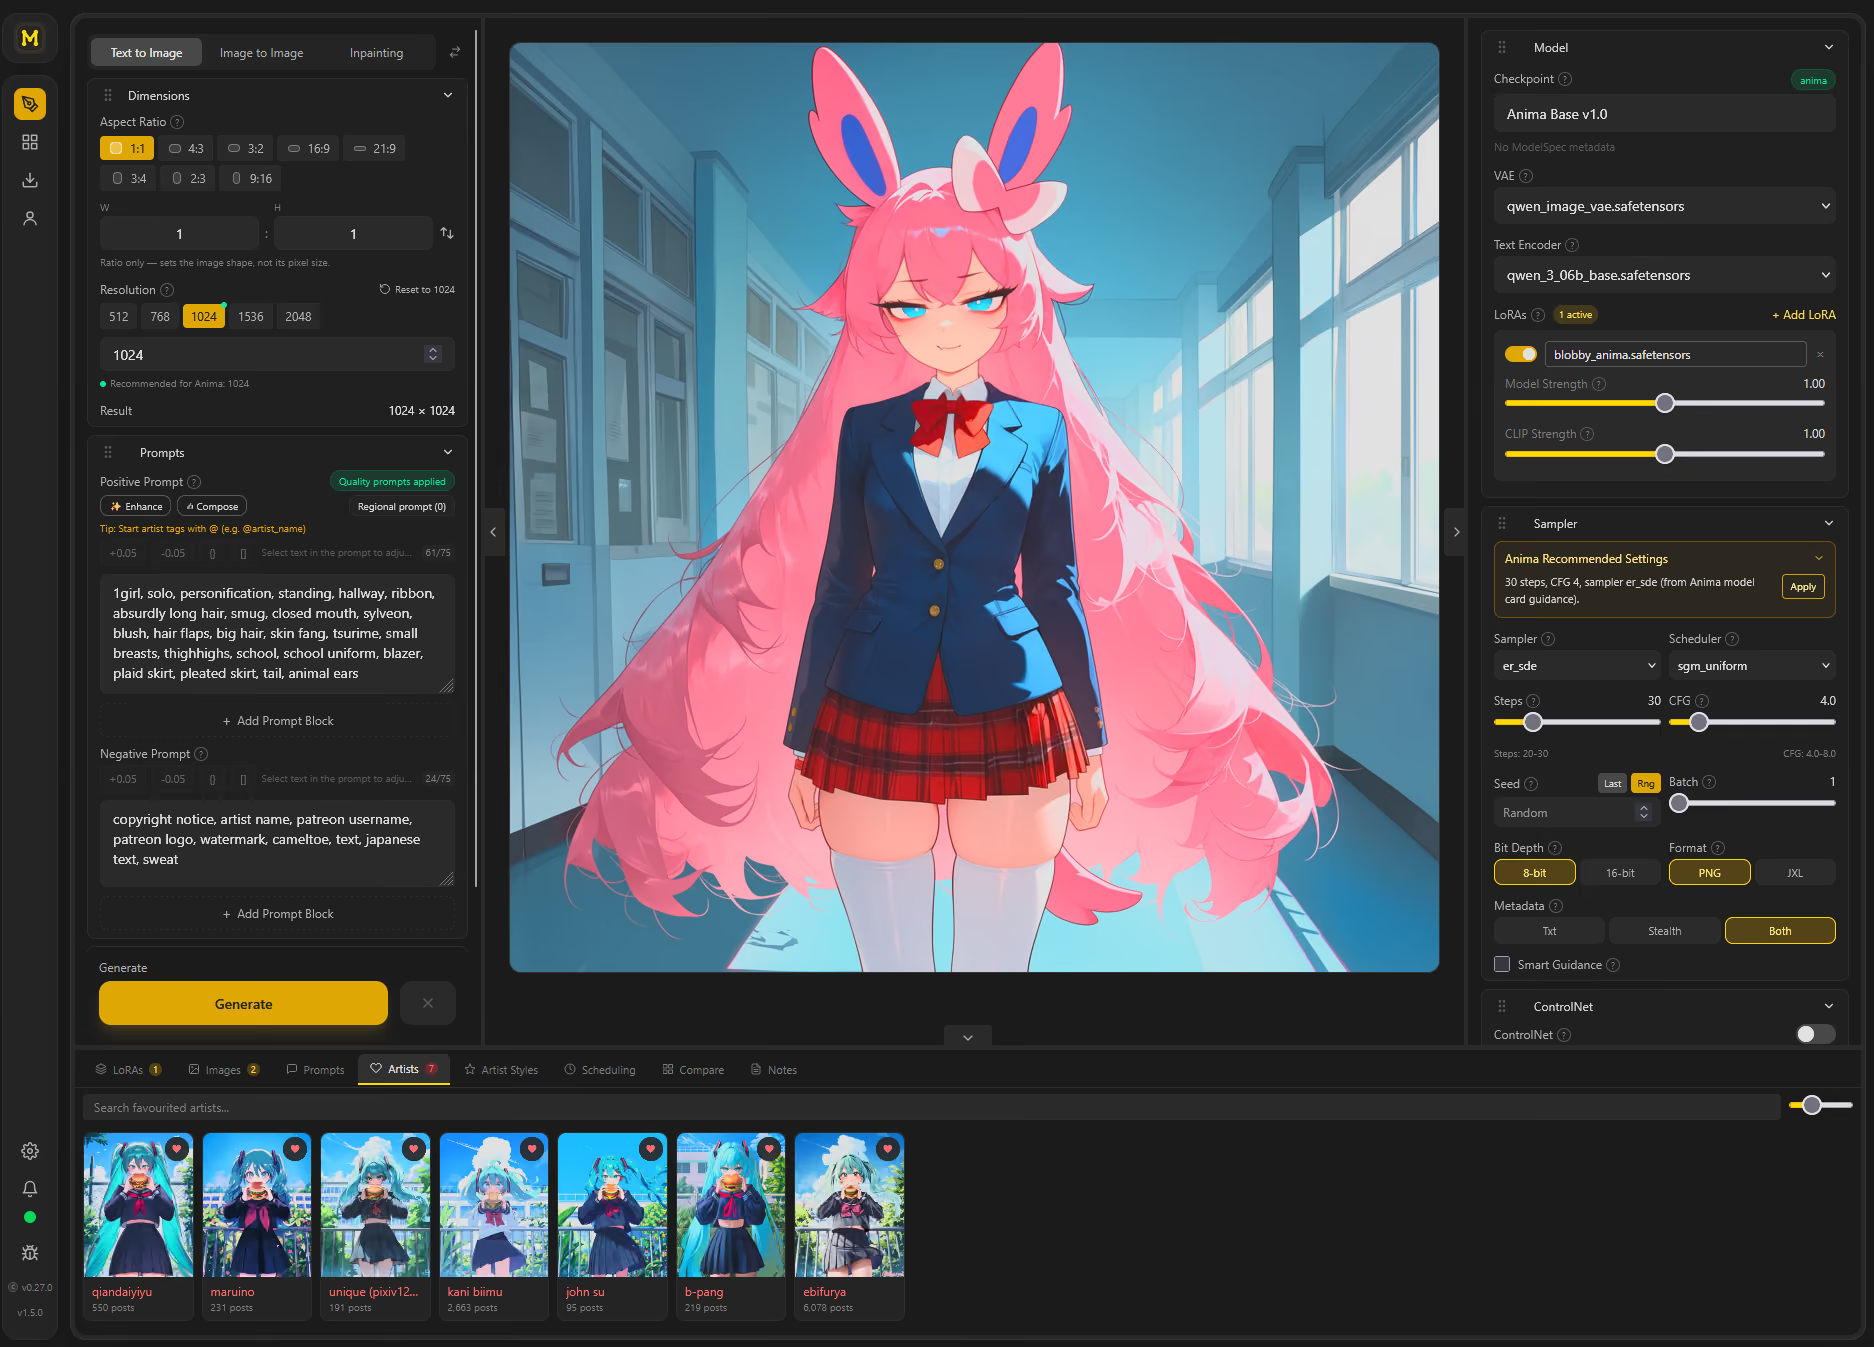

WeeLLM
WeeLLM runs large diffusion models with as little as 4 GB of VRAM, without any quantization. It dynamically determines how many layers can fit within the available VRAM and streams the text encoder and transformer layers to the GPU layer by layer, enabling inference on hardware with limited VRAM. It supports both safetensors and GGUF models.
- 158
- Python
- 2 wk ago

caption-upsampling
This repository implements the idea of "caption upsampling" from DALL-E 3 with Zephyr-7B and gathers results with SDXL.
- 157
- Python
- Apache-2.0
- 3 y ago

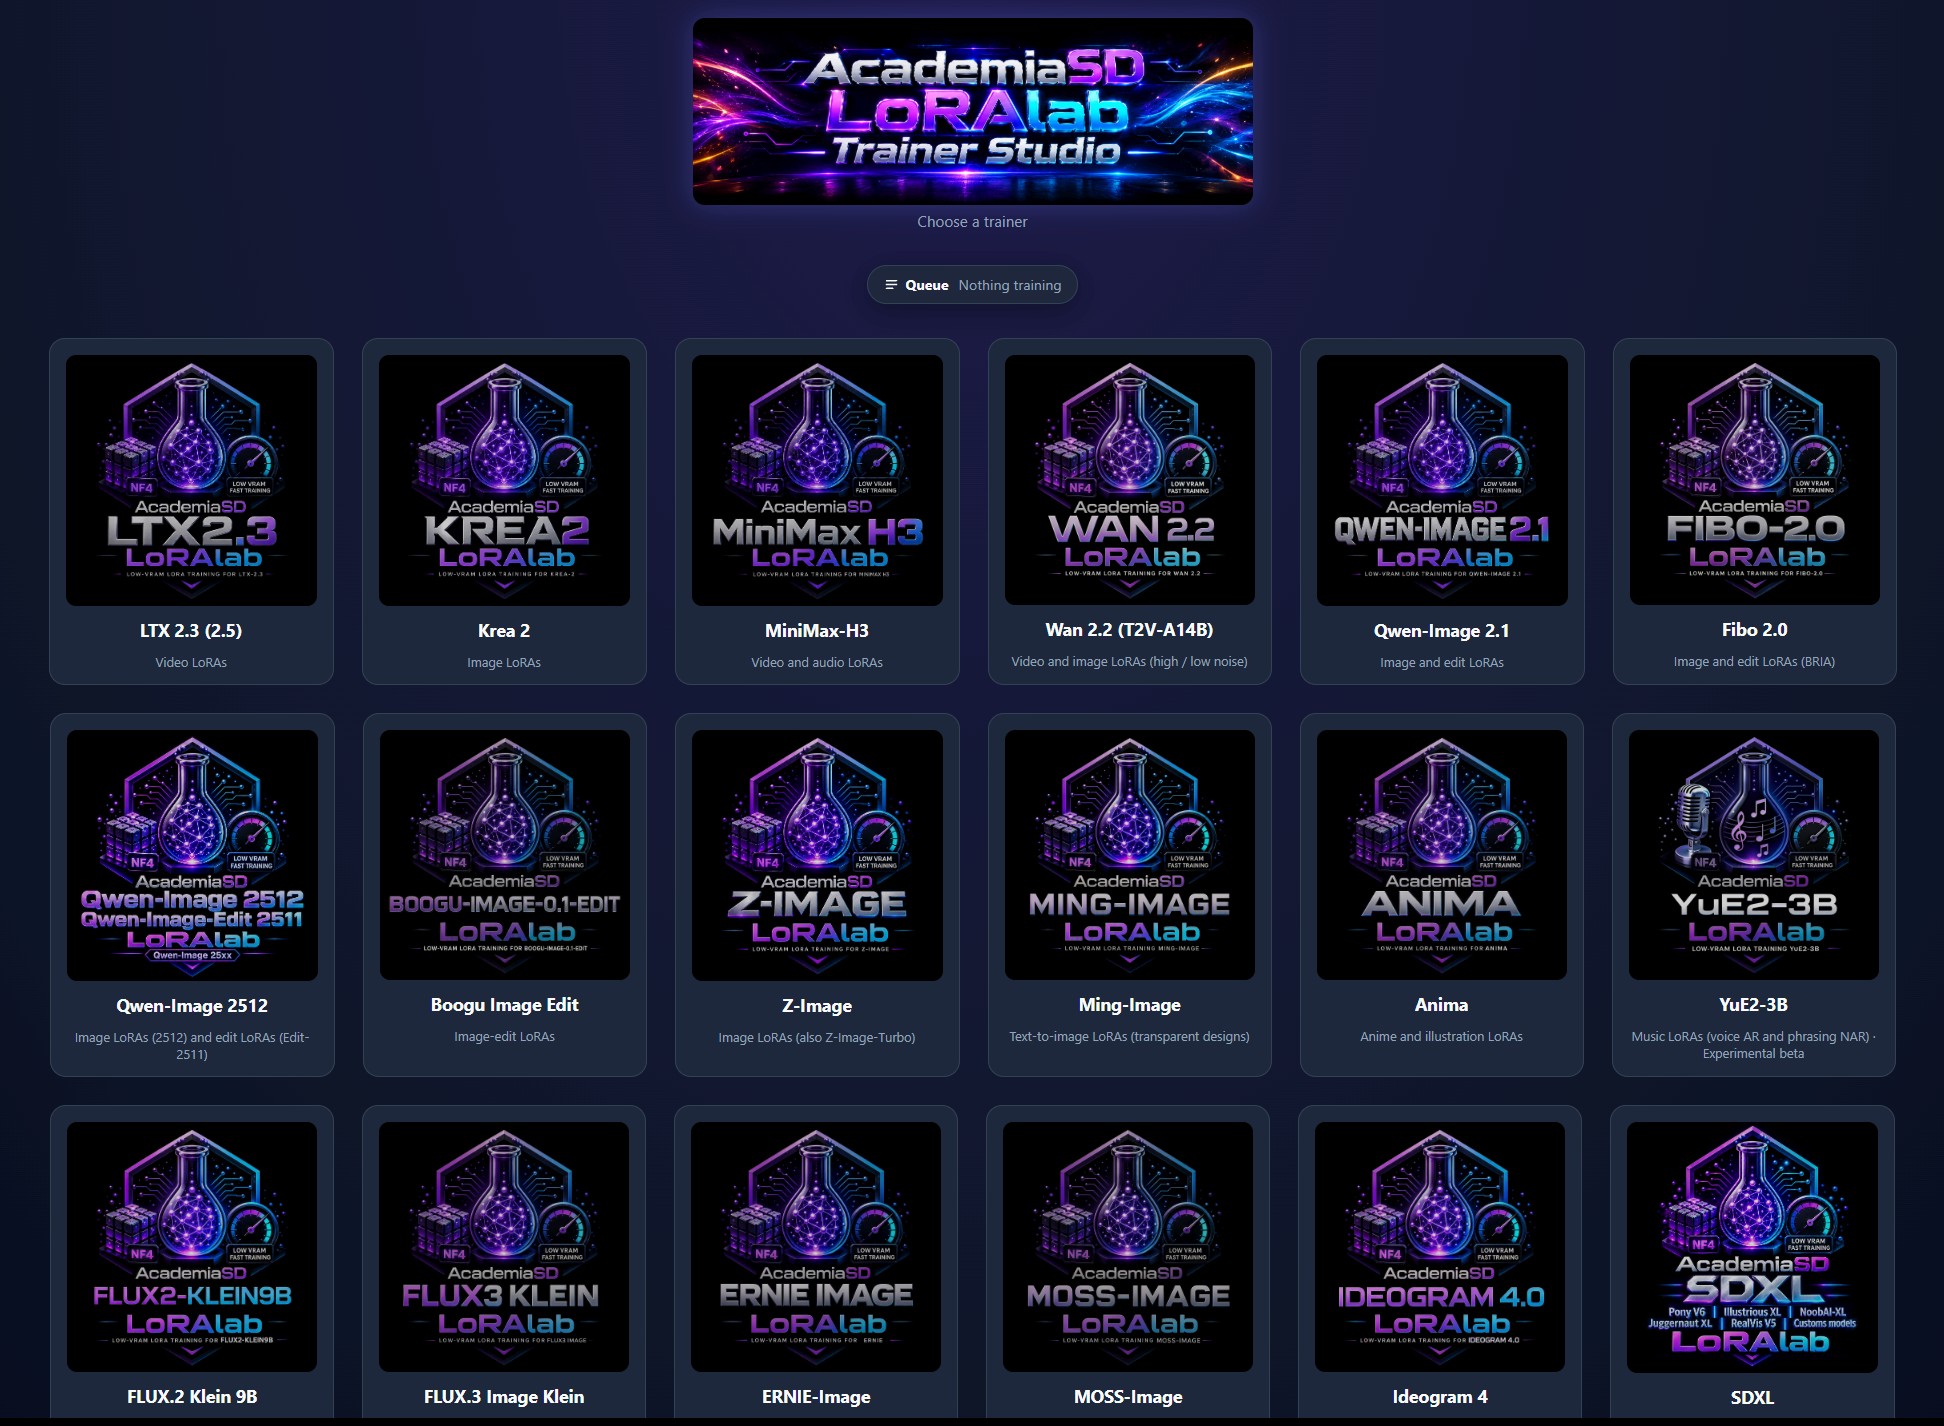
AcademiaSD_LoRAlab-TrainerStudio
Train LoRAs for Qwen-Image 2.1, FLUX.2 Klein 9B, FLUX.3 Image Klein, Krea 2, Z-Image, MOSS-Image, ERNIE-Image, Ideogram 4, Anima, SDXL (Pony, Illustrious, NoobAI), LTX 2.3, MiniMax-H3, and more on NVIDIA GPUs from 4–8 GB VRAM. One install, one launcher, NF4 models. Windows, Linux and RunPod.
- 156
- Python
- MIT
- 7 h ago

comfyui-client
all ComfyUI http/ws APIs. support NodeJS / Browser environments. and advanced programmable workflow.
- 151
- TypeScript
- MIT
- 4 wk ago

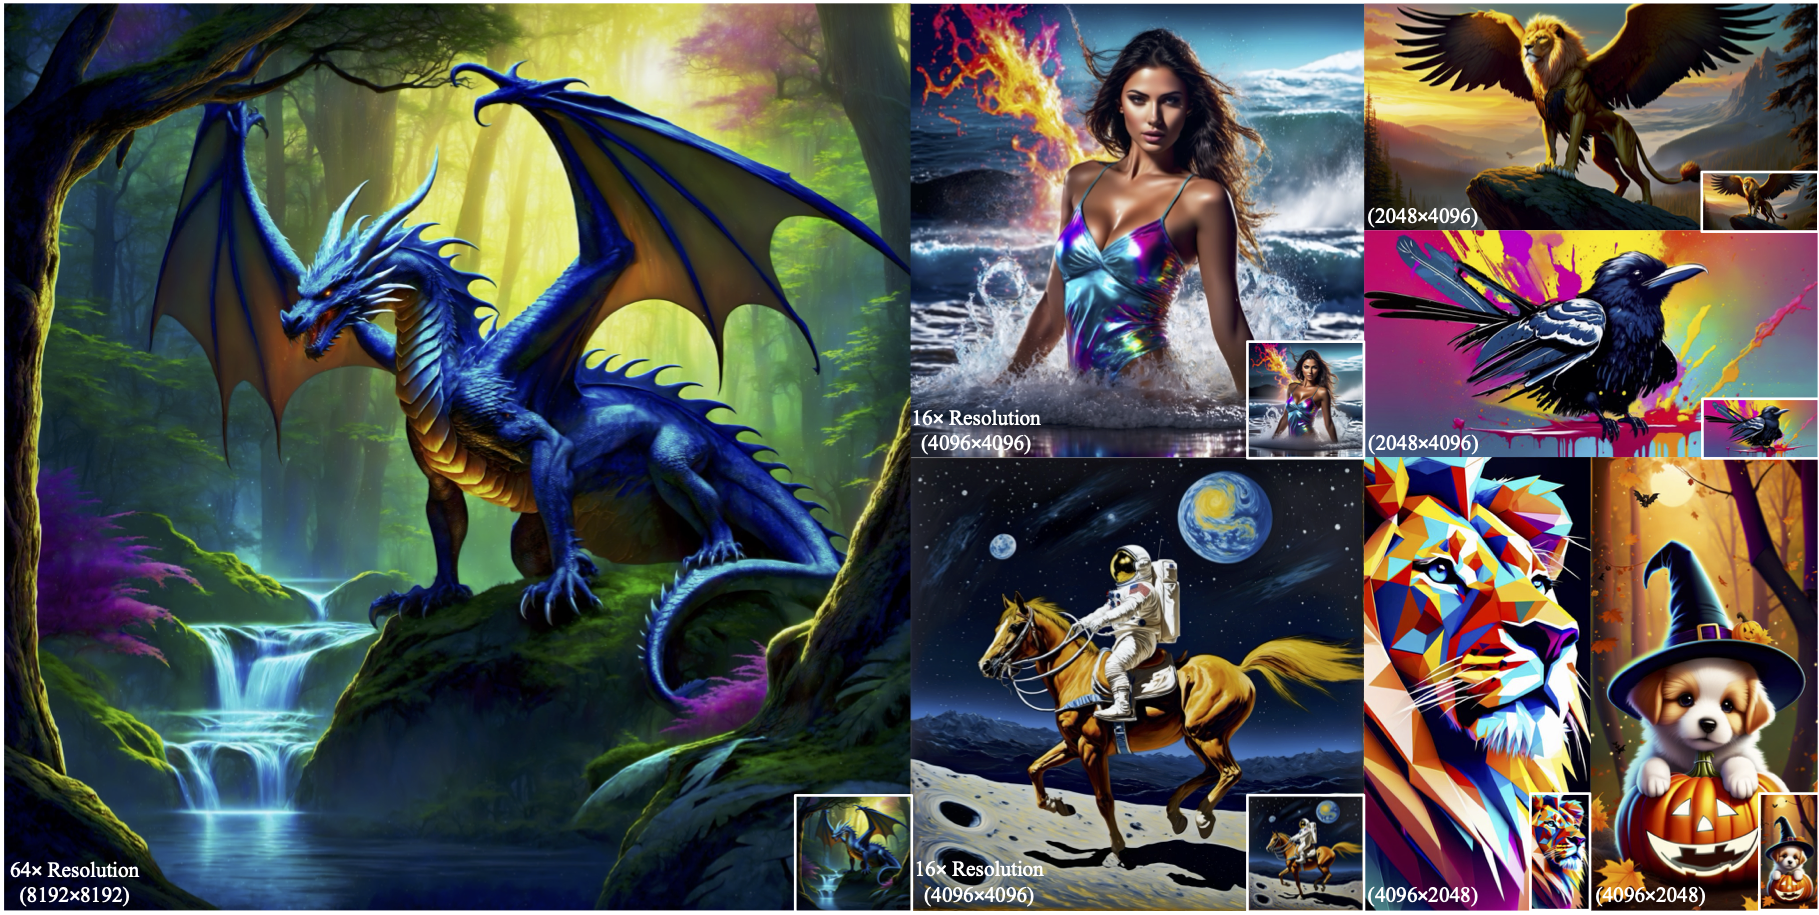
FreeScale
[ICCV 2025] Code for FreeScale, a tuning-free method for higher-resolution visual generation
- 148
- Python
- Apache-2.0
- 14 mo ago

libwaifu
Your local AI waifu! Local SDXL / Qwen-Image / Anima / IndexTTS / CosyVoice inference in Rust + C++, CUDA / Metal / Vulkan
- 114
- Rust
- MIT
- 7 d ago


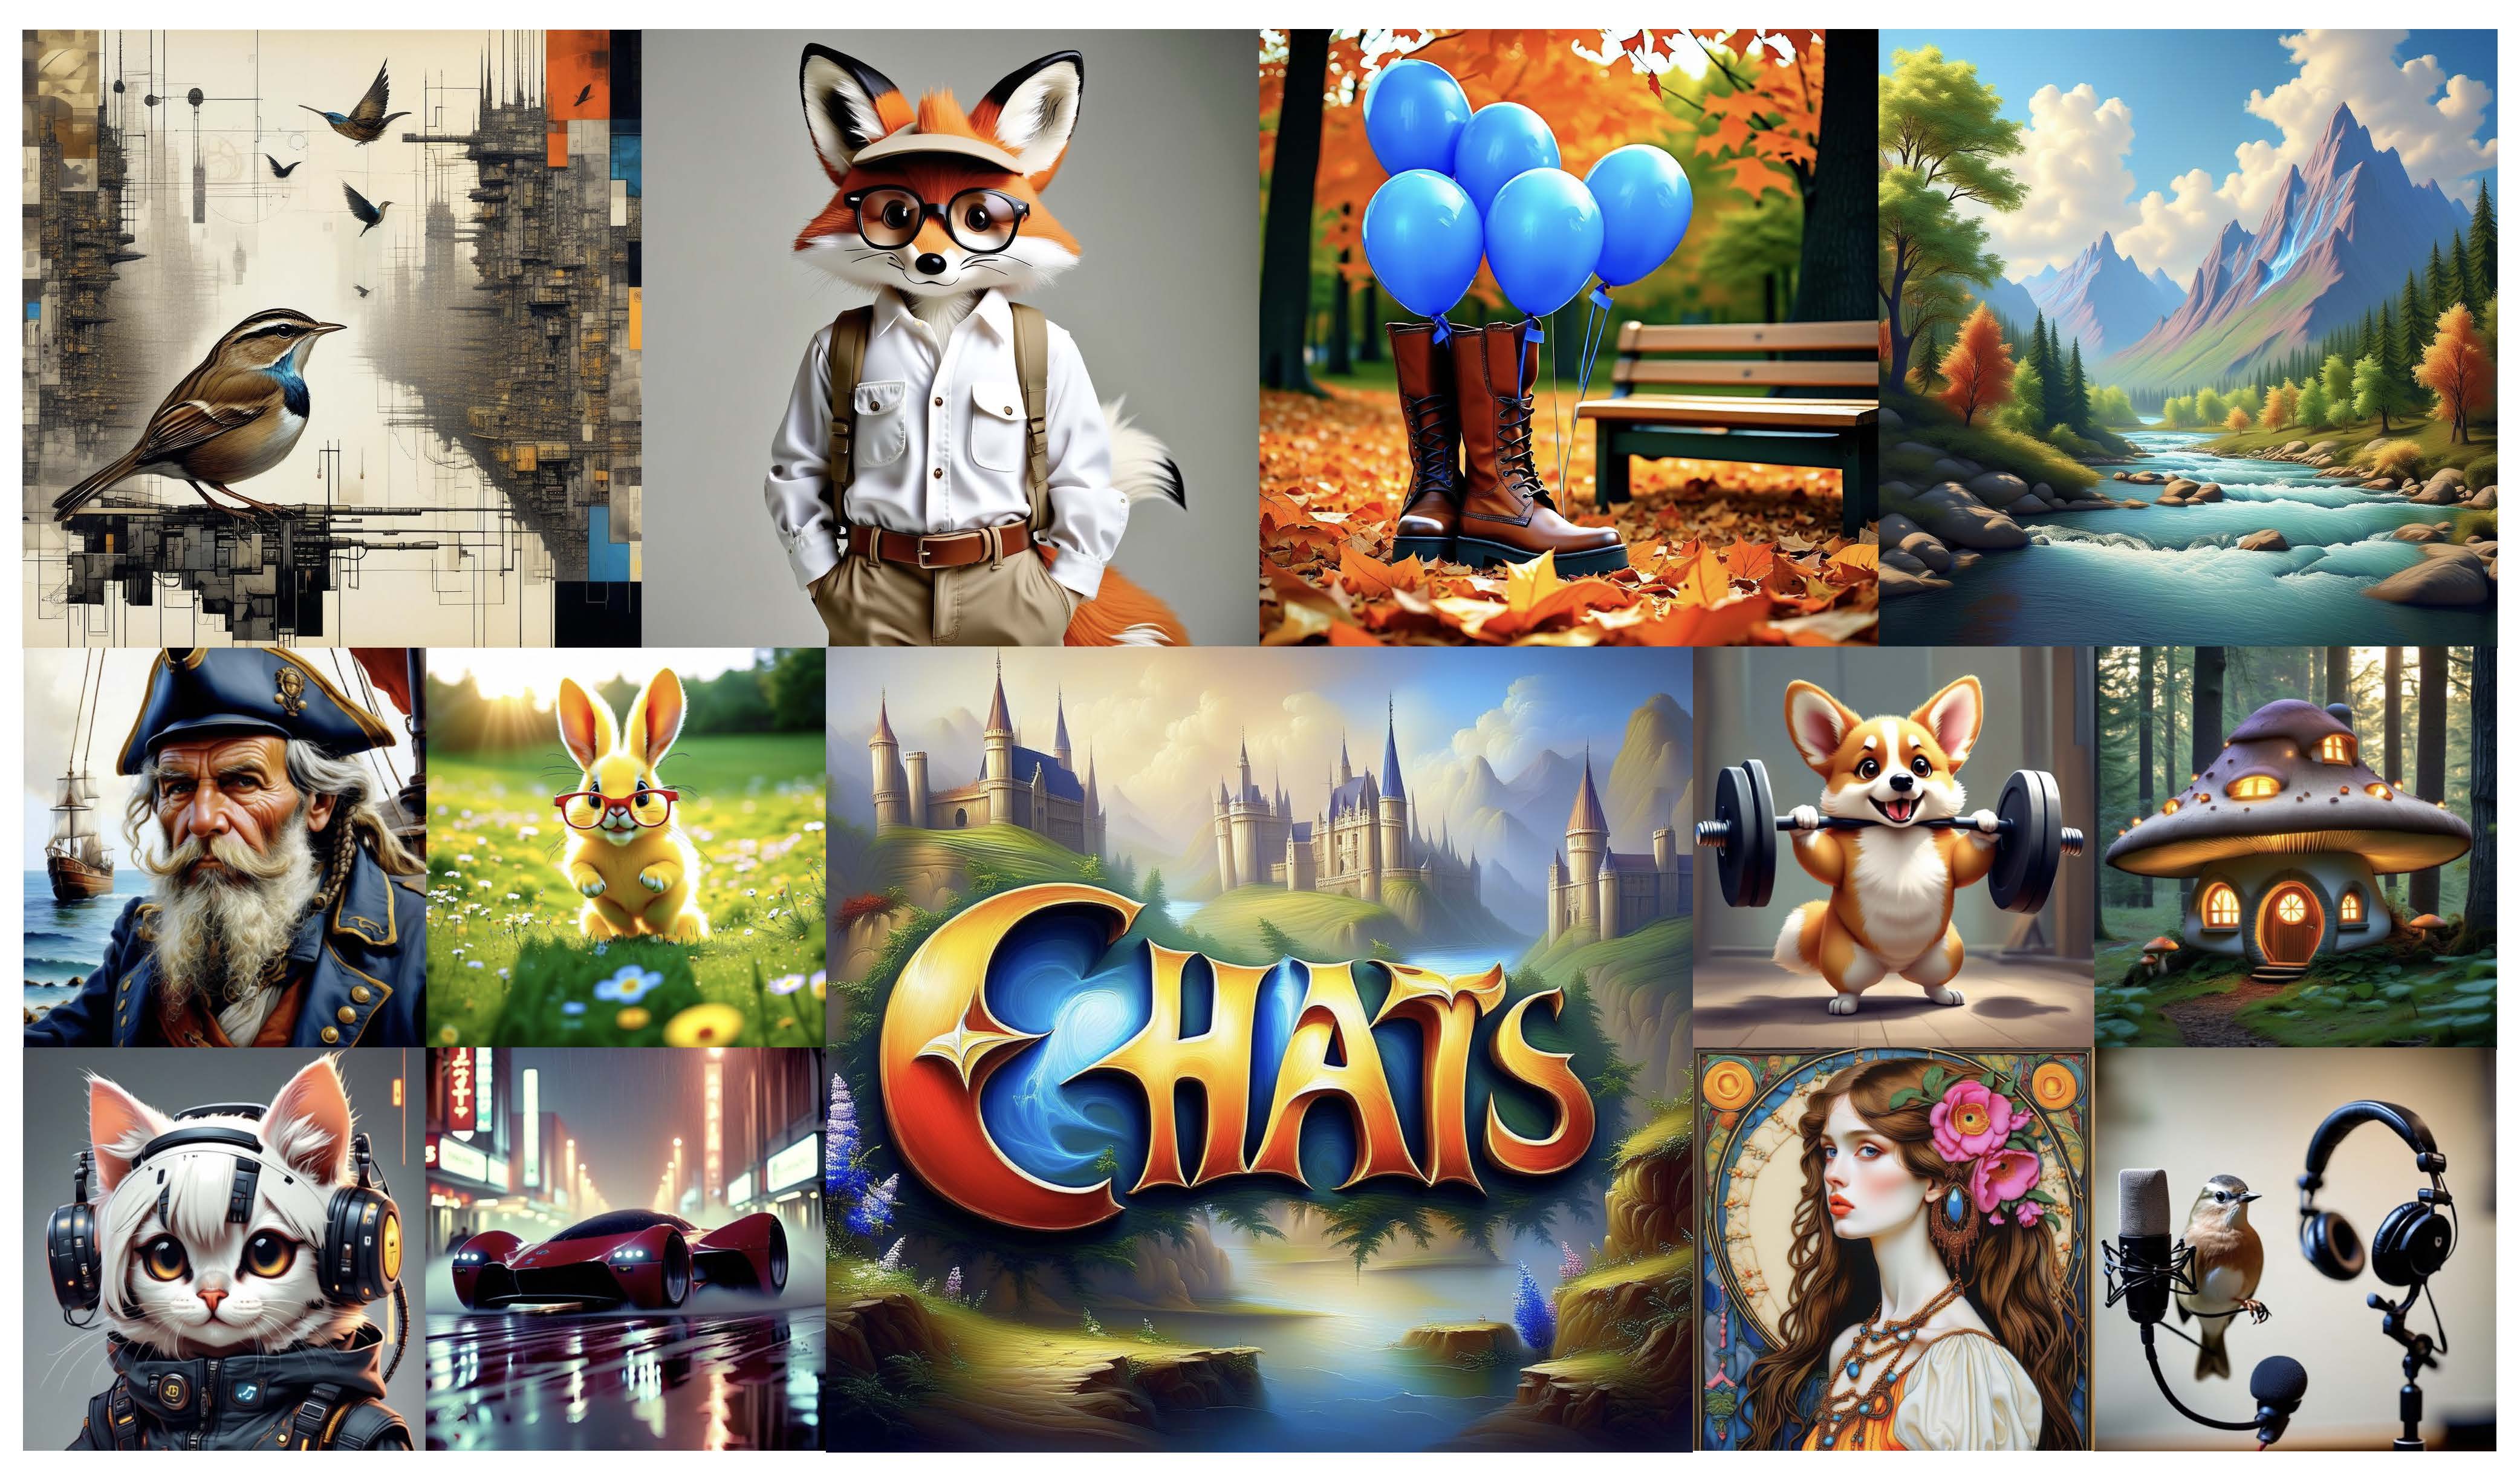
CHATS
CHATS: Combining Human-Aligned Optimization and Test-Time Sampling for Text-to-Image Generation (ICML2025)
- 106
- Python
- Apache-2.0
- 15 mo ago

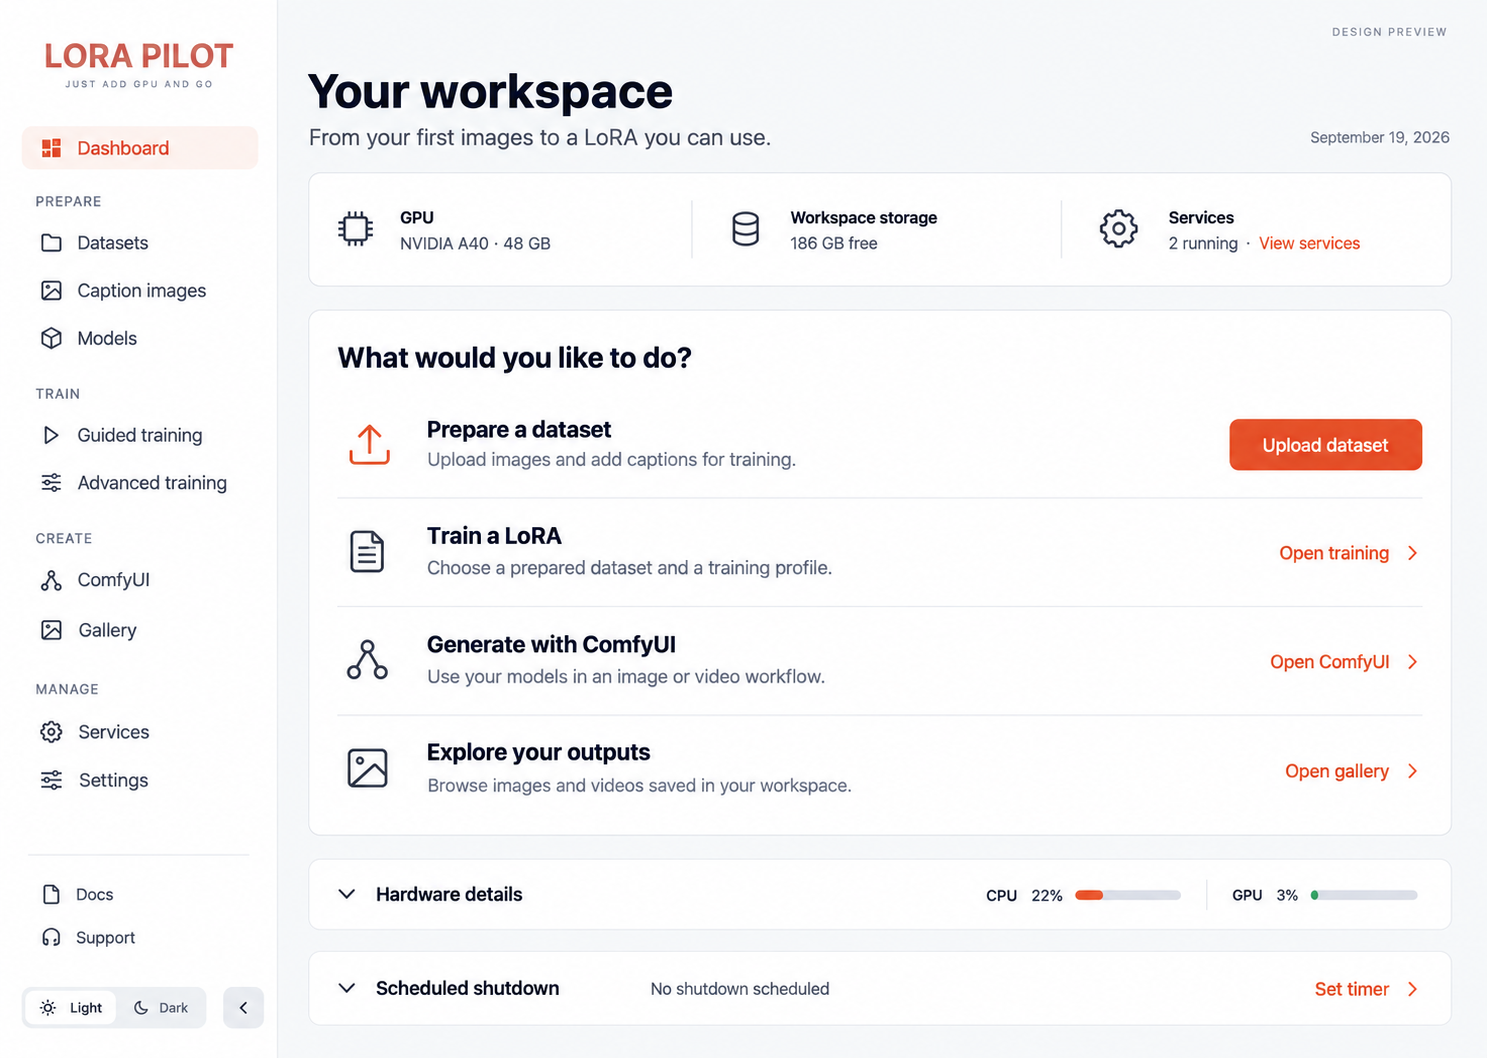
lora-pilot
From dataset to trained LoRA to finished image or video. One browser workspace for your models, datasets, training, and generation. LoRA Pilot supports 50+ training model groups, with ComfyUI, Kohya, AI Toolkit, and Diffusion Pipe included. Run on your own GPU or RunPod, and connect AI agents through MCP.
- 92
- Python
- MIT
- 12 h ago

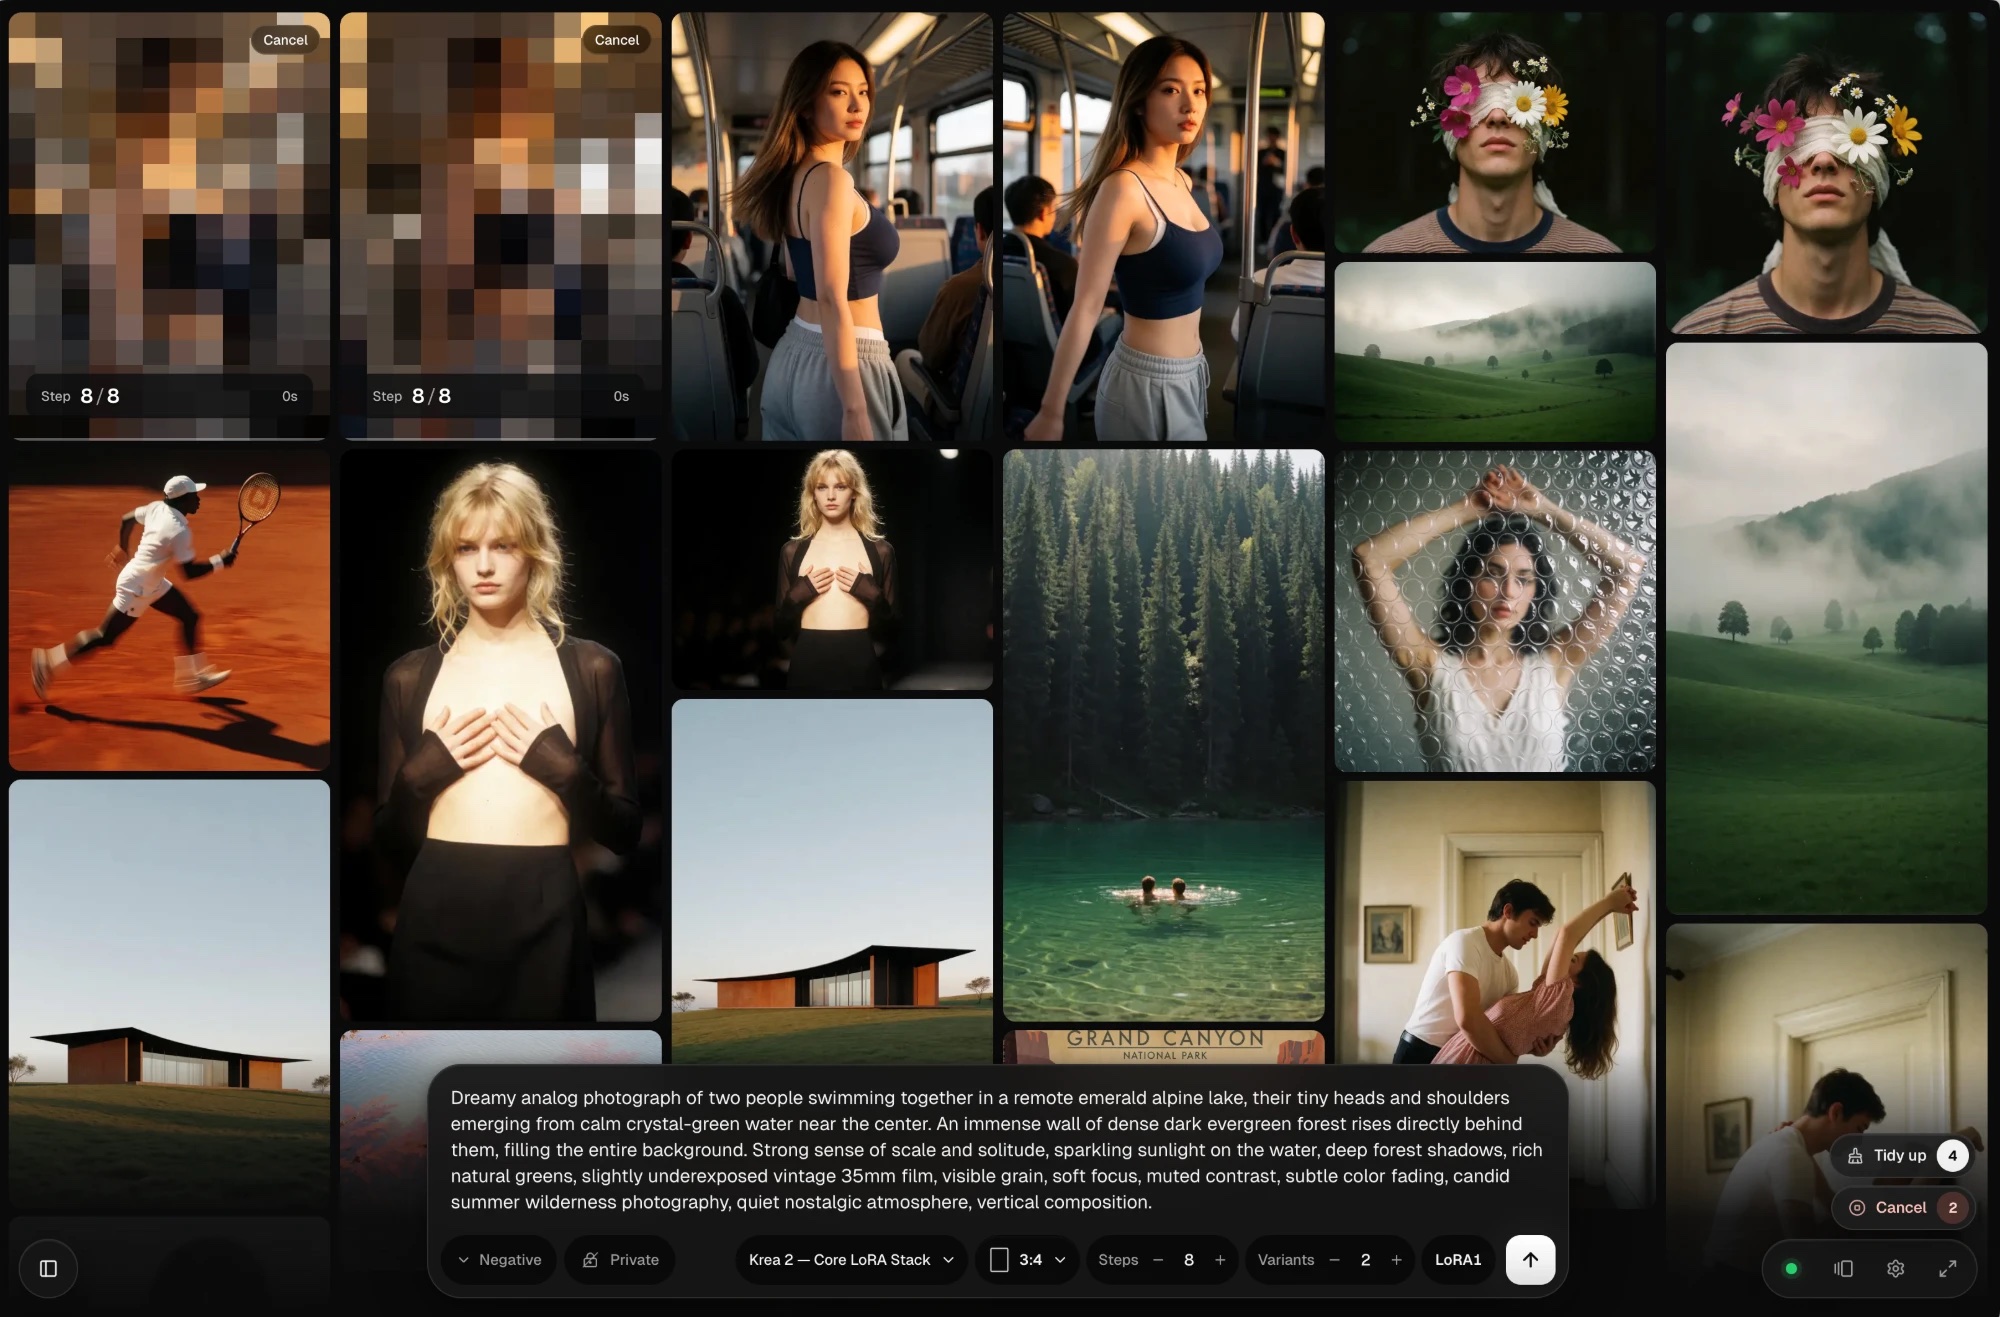
HEISS-UI
ComfyUI, without the graph. A calm, local front end for ComfyUI. Bring your own workflows, write a prompt, watch it render.
- 84
- JavaScript
- MIT
- 5 d ago

stable-diffusion-docker
Docker image for Stable Diffusion WebUI with ControlNet, After Detailer, Dreambooth, Deforum and ReActor extensions, as well as Kohya_ss and ComfyUI
- 76
- Shell
- GPL-3.0
- 4 d ago

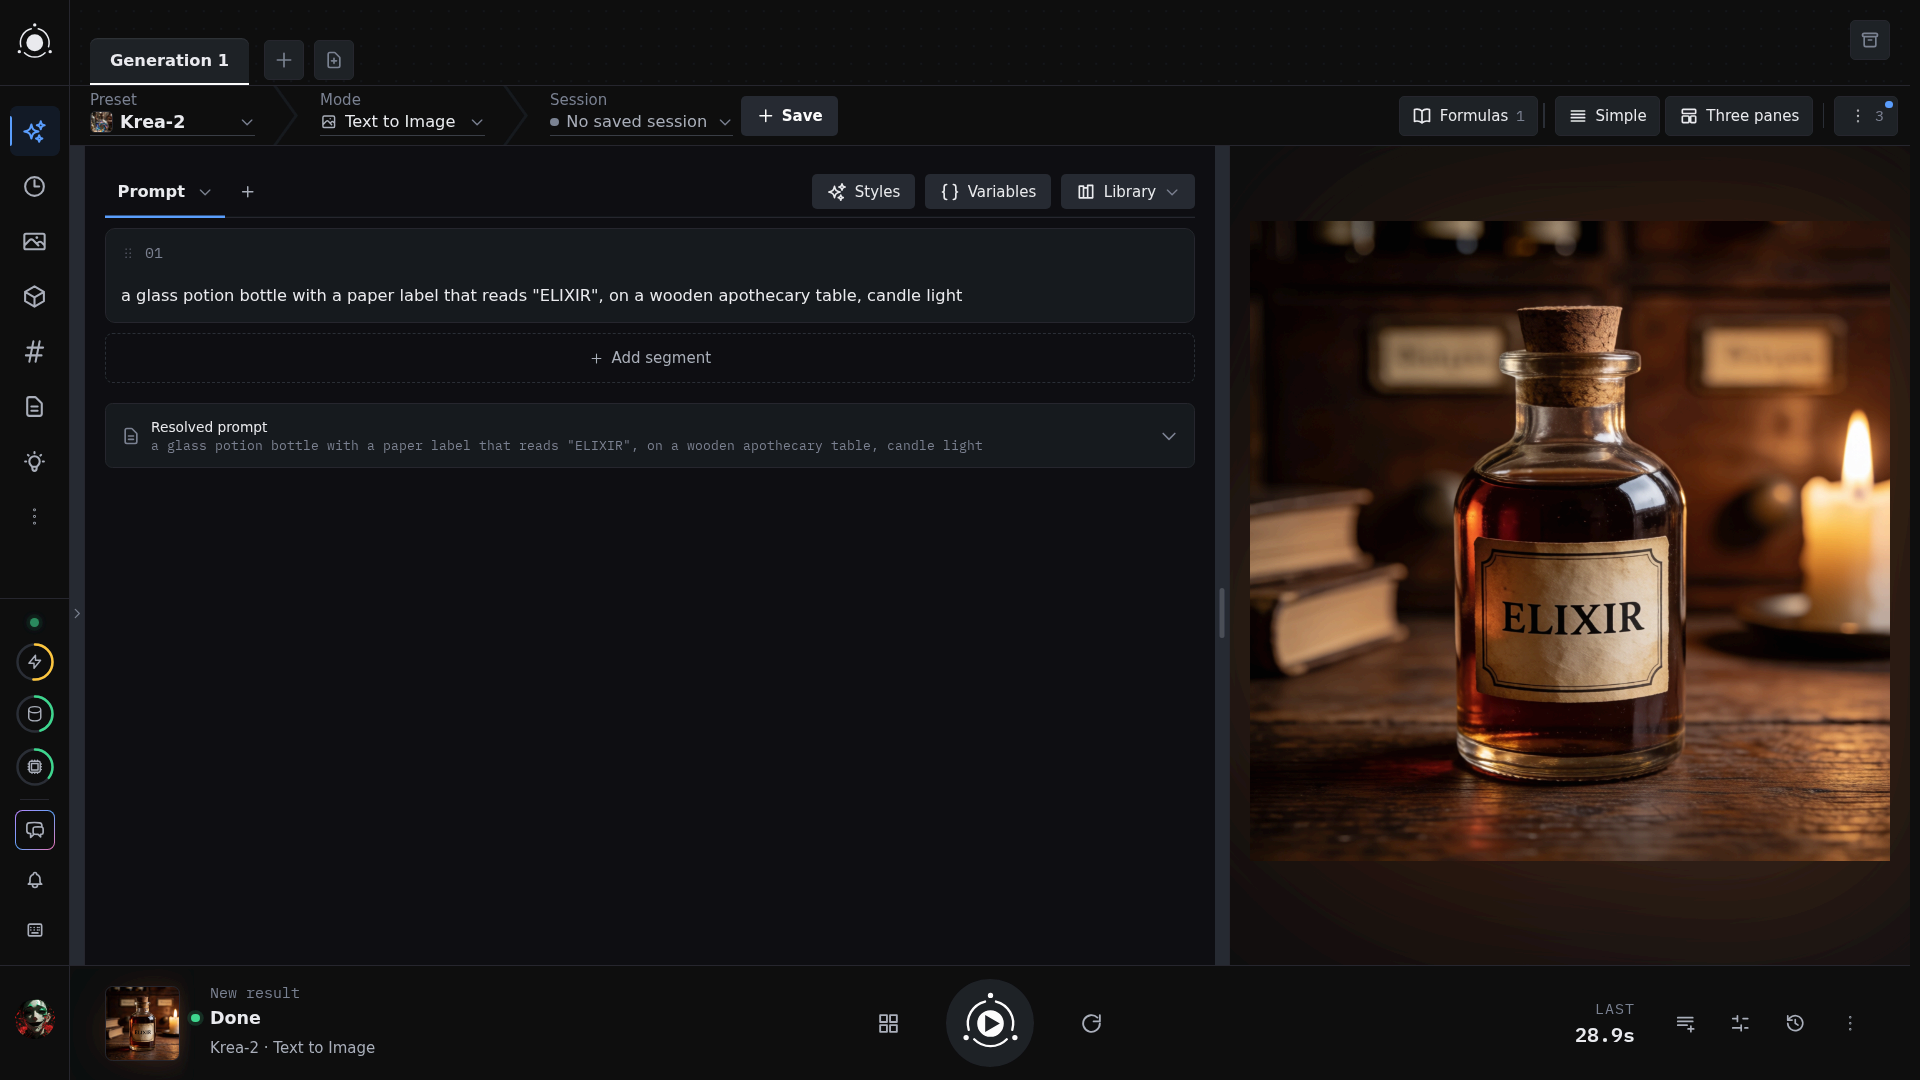
PotionUI
Self-hosted AI studio for images, video and music on your own GPU. Multi-user with logins and limits, no node graphs, drivable over MCP.
- 65
- Python
- GPL-3.0
- 2 d ago


comfyui-docker
Docker image for ComfyUI: The most powerful and modular stable diffusion GUI, api and backend with a graph/nodes interface.
- 60
- Shell
- GPL-3.0
- 4 d ago
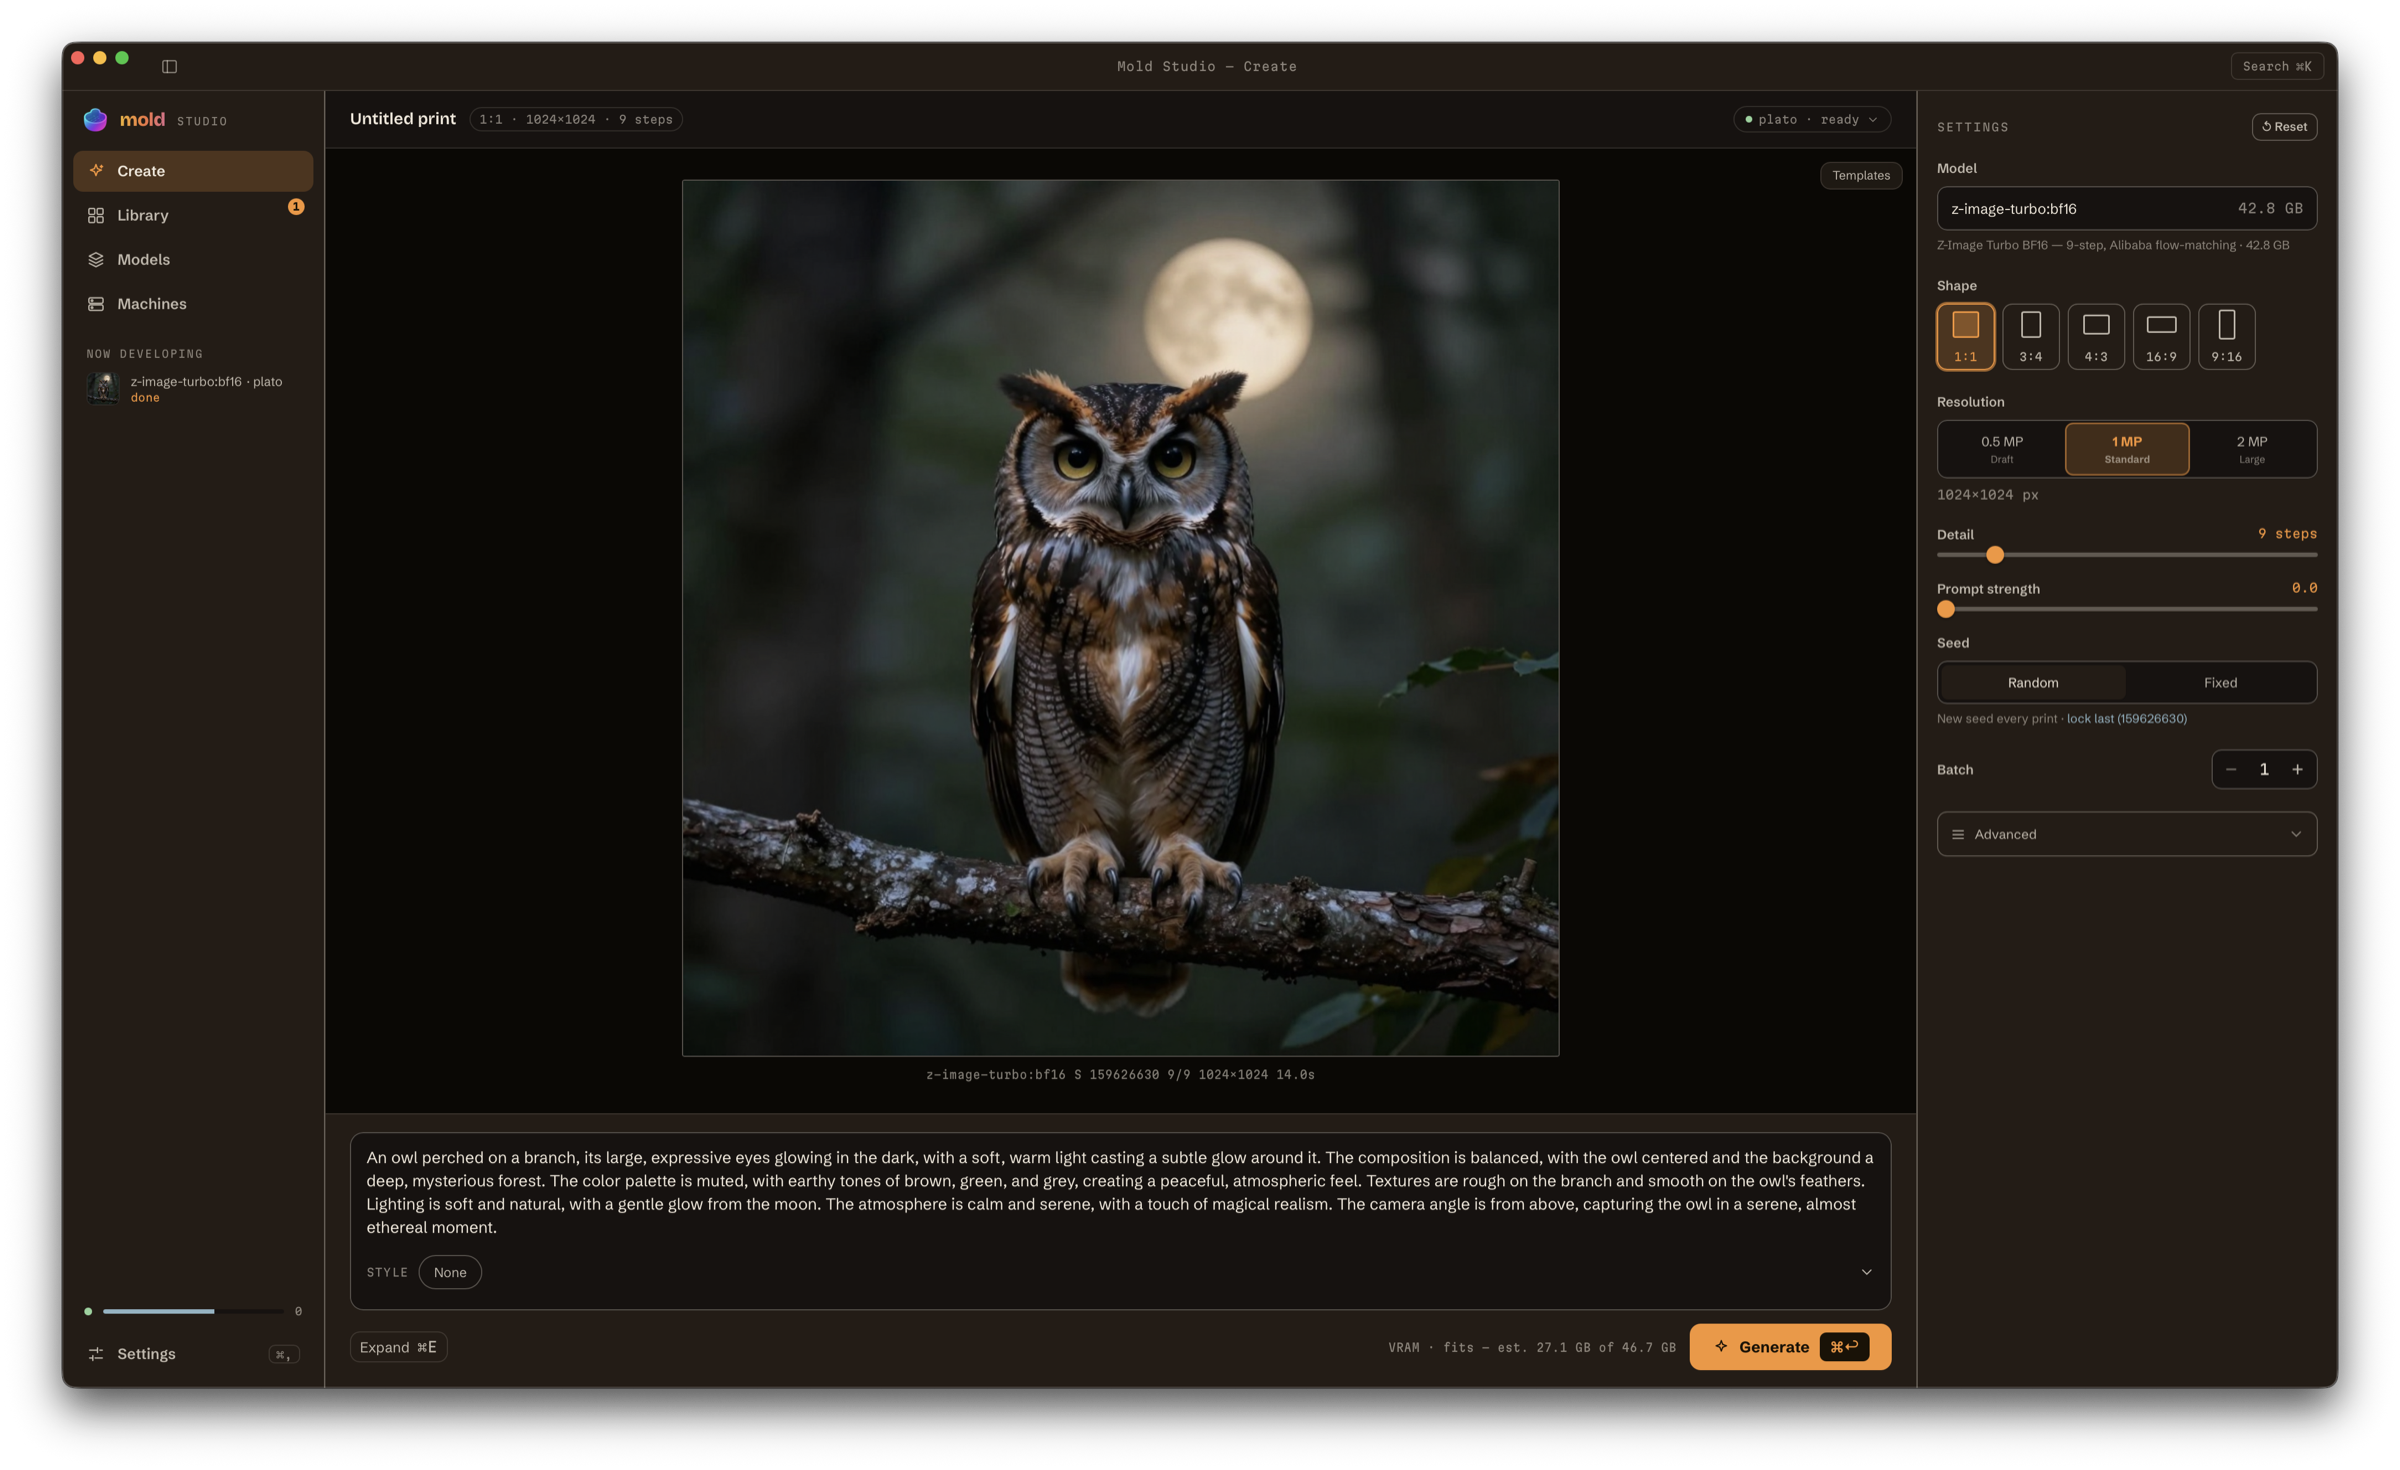
mold
CLI-native local AI image and video generation for people, scripts, and agents — CUDA on Linux, Metal on macOS, plus desktop, web, iPhone, REST/SSE, and MCP.
- 58
- Rust
- MIT
- 3 wk ago

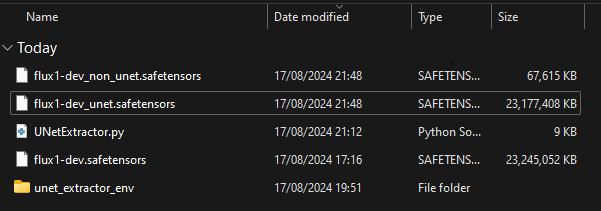
extract-unet-safetensor
Processes SafeTensors files for Stable Diffusion 1.5 (SD 1.5), Stable Diffusion XL (SDXL), and FLUX models. It extracts the UNet into a separate file and creates a new file with the remaining model components (without the UNet).
- 58
- Python
- MIT
- 2 y ago

Aozora-Forge
Low VRAM SDXL Fine-Tuning Toolkit 2026: Train Full-Quality AI Models on 12GB GPUs
- 57
- HTML
- 8 h ago

ComfyUI_JosiaNodes
一套功能完整、轻量稳定的 ComfyUI 实用节点集。初衷是为了平替一些断更插件的功能,会持续更新一些新开发的节点插件。有好的创意可以发Issues,我会力所能及想办法做出来。全中文界面,原生控件,不依赖第三方库。
- 50
- JavaScript
- MIT
- 3 d ago

vram-sage-training
The 2026 VRAM-Smart Fine-Tuning Suite for SDXL and ANIMA on 12GB GPUs
- 57
- HTML
- 10 h ago

stable-diffusion-xl-api
Reverse engineered API of Stable Diffusion XL 1.0 ( Midjourney Alternative ), A text-to-image generative AI model that creates beautiful 1024x1024 images.
- 41
- Python
- MIT
- 3 y ago

Inpaint/Outpaint (any size)
Modifies one detail or background of your image, freely
Runs in the browser on Hugging Face
- 11
- mit
- 16 mo ago
Image-to-Image SDXL Turbo (any size)
Modifies the render of your image, at any resolution, freely
Runs in the browser on Hugging Face
- 10
- mit
- 16 mo ago
Uncrop image
Completes borders of your image to show out-of-frame details
Runs in the browser on Hugging Face
- 8
- mit
- 2 y ago