folkbench
AI API 中转站推荐与评测:中转站排行榜、中转站检测、Claude / GPT / Gemini 中转站对比 · AI API relay rankings · Folkbench Switch for Claude Code, Codex & Gemini CLI
- 3.2k
- TypeScript
- 2 d ago
AI API 中转站推荐与评测:中转站排行榜、中转站检测、Claude / GPT / Gemini 中转站对比 · AI API relay rankings · Folkbench Switch for Claude Code, Codex & Gemini CLI
[ICML 2024] TrustLLM: LLM trustworthiness evaluation across truthfulness, safety, fairness, robustness, privacy and ethics. Python/CLI toolkit for local models, compatible APIs and AI agent orchestration.
Open-source whiteboard AI tutor with animated lessons and interactive playback. Compare Claude, Gemini & DeepSeek across 288 generation runs and 64 blind-reviewed boards.
AI trading agents for US stocks with news backtesting that can't see the future: a public LLM trading agent leaderboard (rta-bench-1), frozen point-in-time 2020/2022/2026 markets (prices, VIX, news), a look-ahead check on every run, LLM agents over MCP, and paper/live trading on 10 brokers. 风险感知美股交易智能体 · 新闻回测 · LLM 榜单
A curated list on AI token economics: what tokens cost, where they get wasted, and how to cut the bill. Tools, benchmarks, papers, and copy-paste configs for the token economy of LLMs and coding agents.
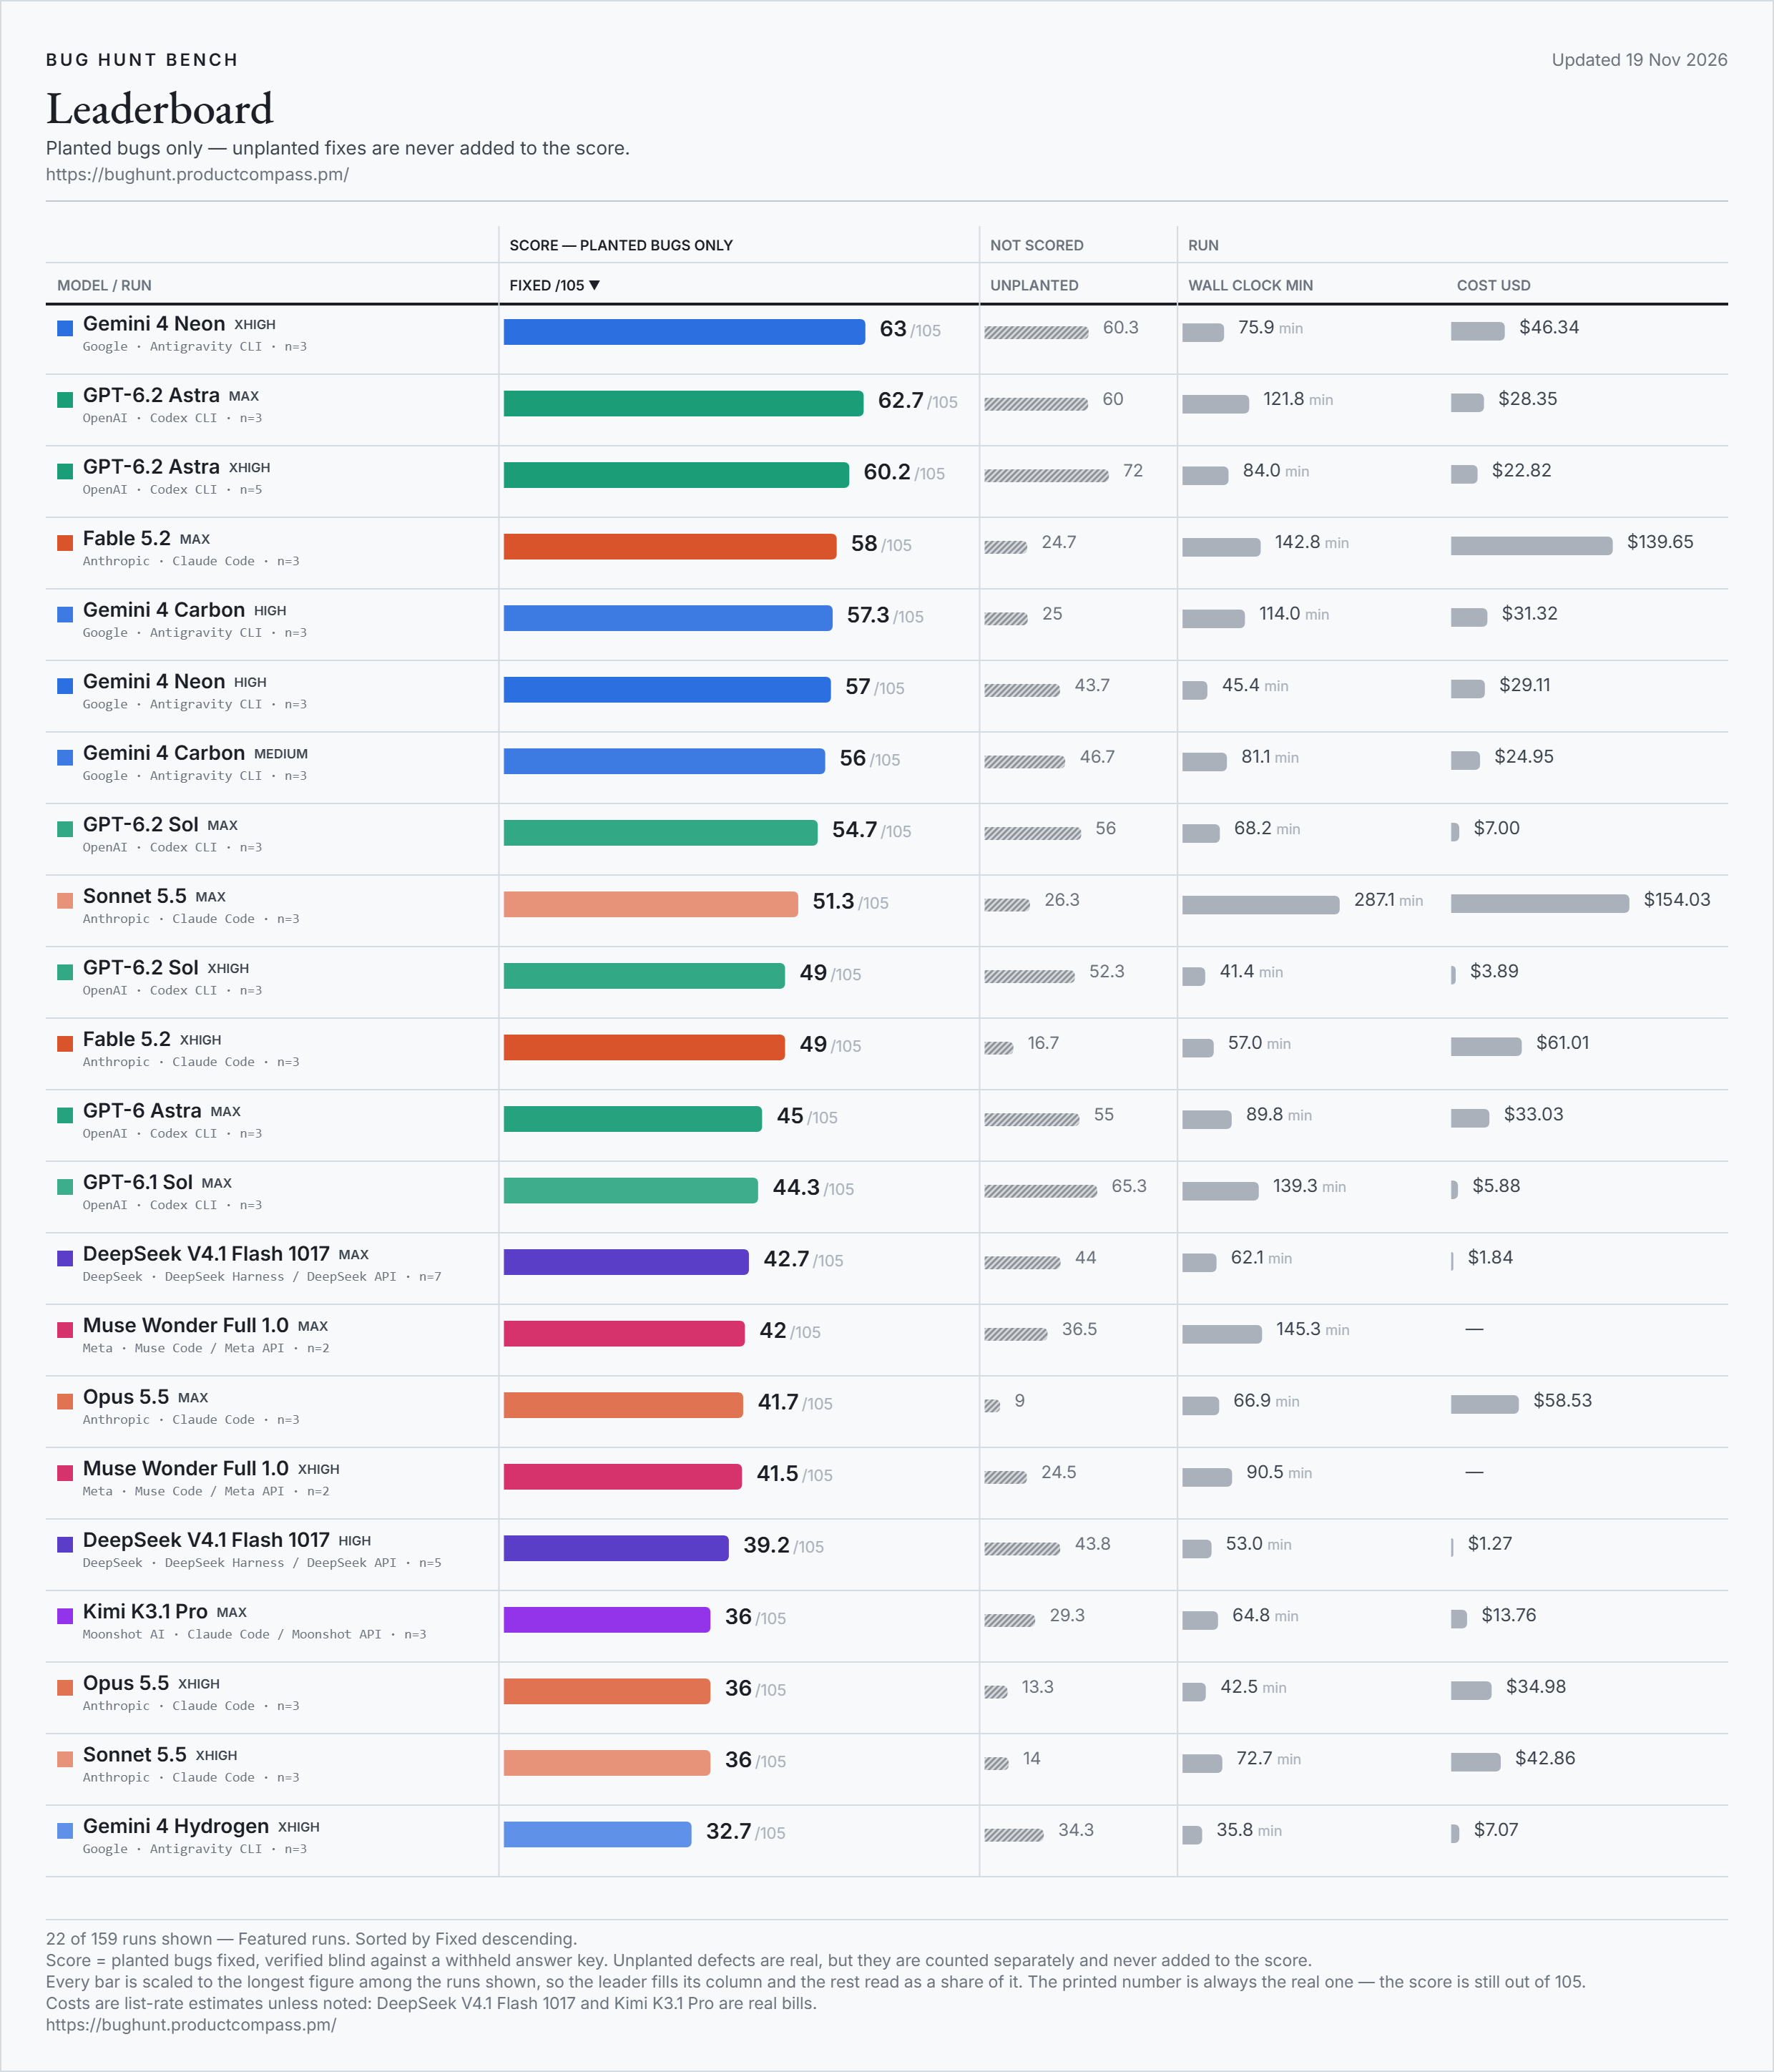
Bug Hunt Bench: 105 real bugs in two production repos, frontier coding models (GPT-6, Claude, Grok, Gemini, DeepSeek...) find and fix them in their own CLI, graded blind. Live leaderboard + every receipt.
A reproducible local LLM benchmarking platform with versioned datasets, deterministic scoring, and auditable reports.
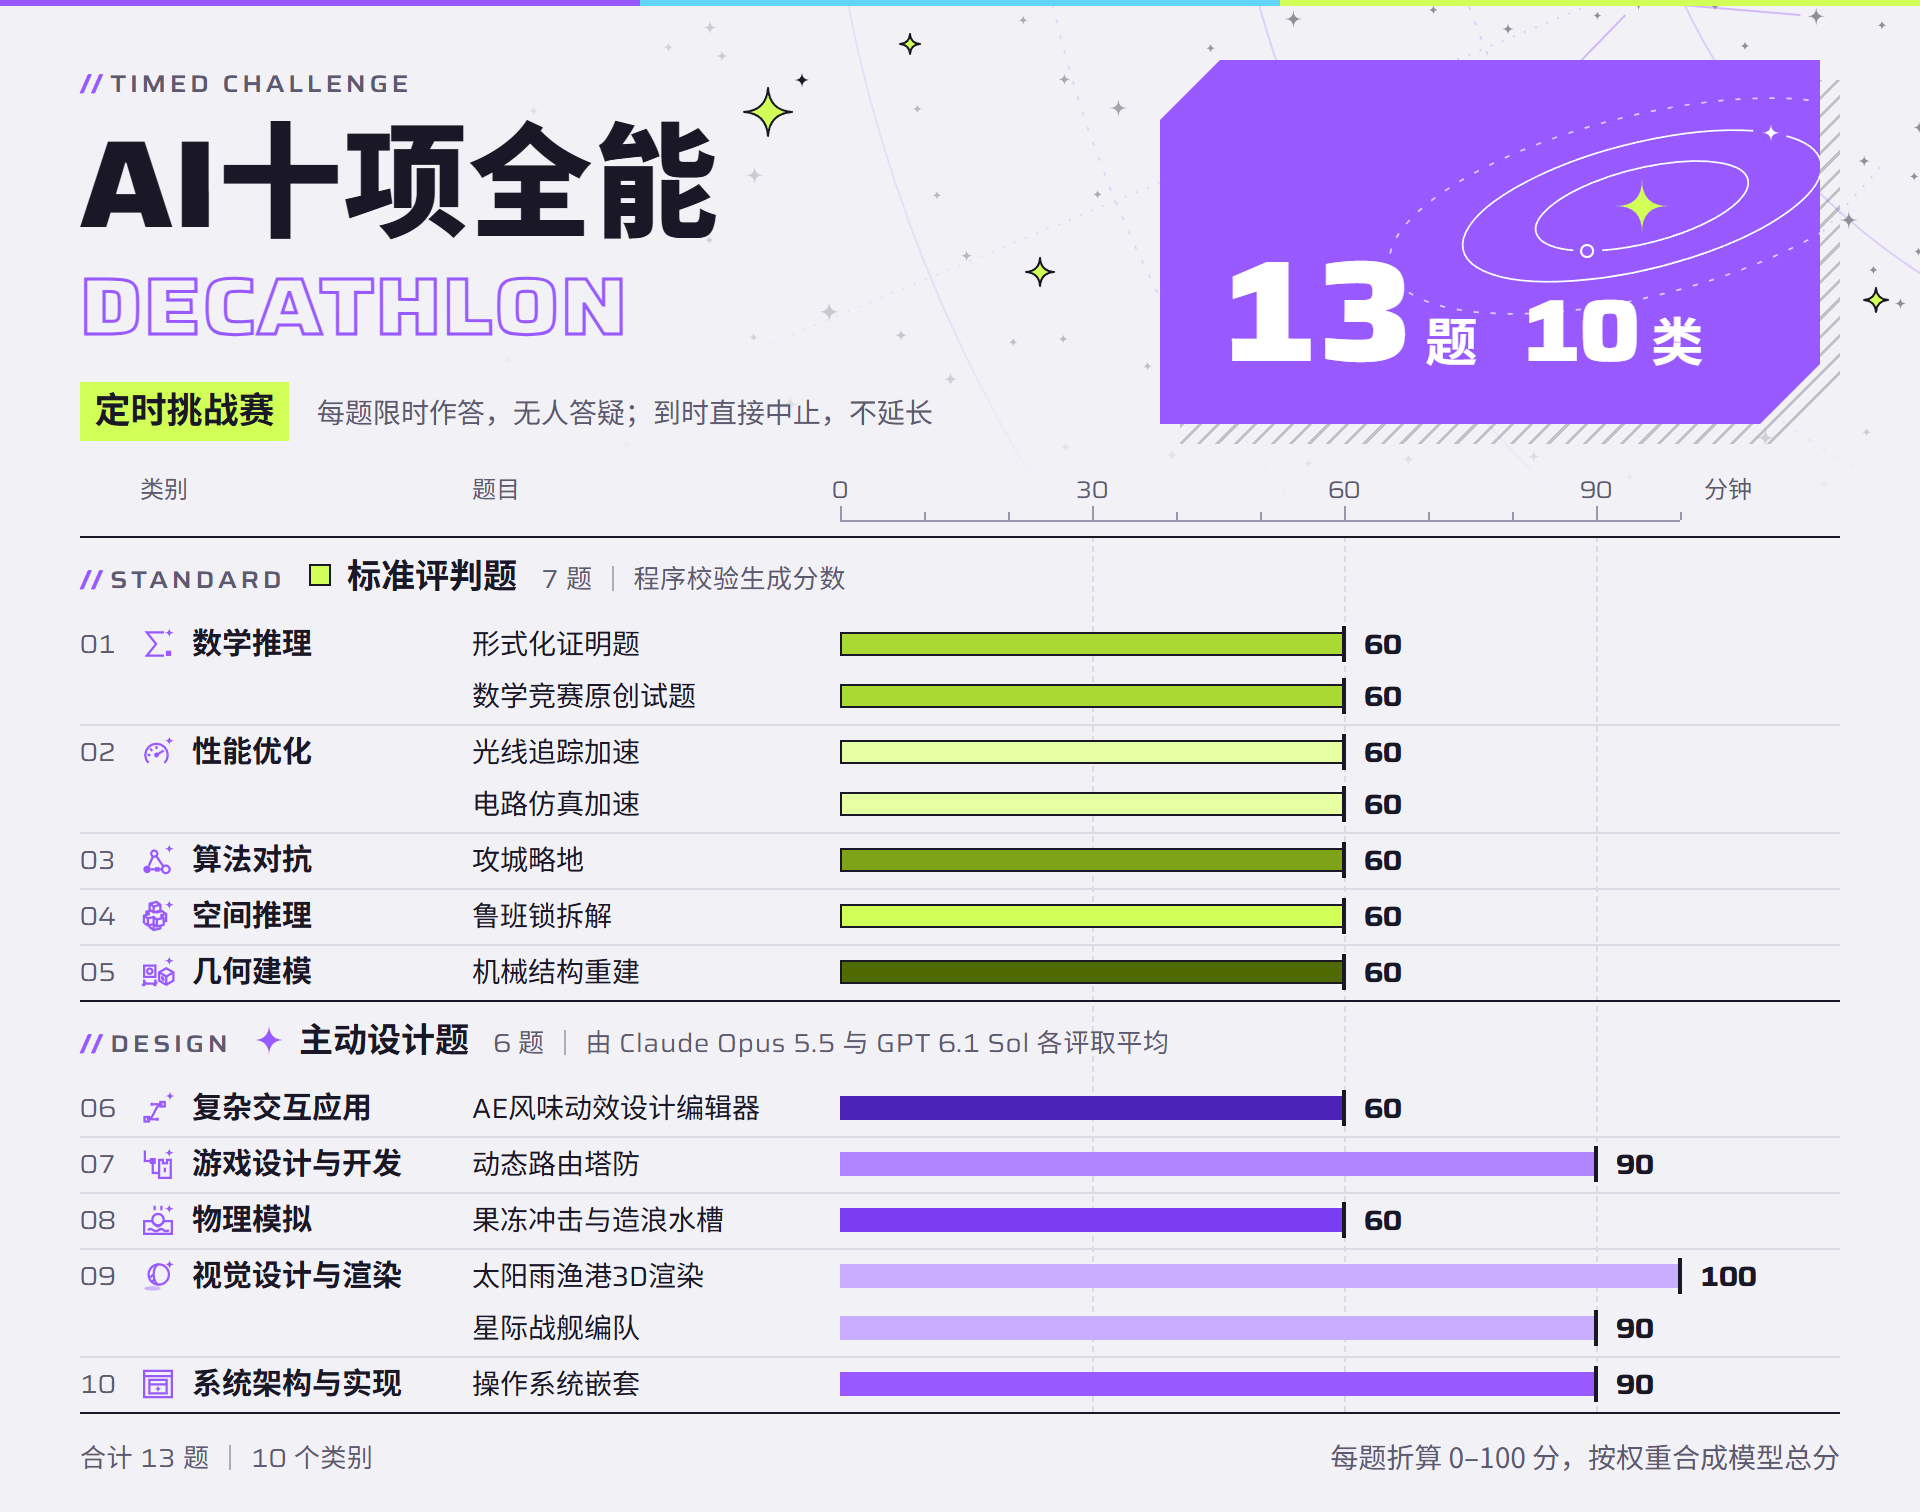
AI十项全能·定时挑战赛 | AI Decathlon · Timed Challenge: a timed benchmark for AI coding agents — 13 tasks across 10 categories (Lean proofs, competition math, CUDA/CPU optimization, game AI, 3D/web apps, nested OS), 60–100 min each, no human help.
AI Stupid Level — independent, continuous LLM benchmarks (coding, reasoning, tool use), drift detection and a benchmark-driven Smart Router. Web app source; methodology public, test tasks private.
The AI-native wire format for structured data. 100% comprehension on every frontier model. 50-92% fewer tokens than JSON. 43B+ lossless round-trips across 17 formats. Spec v3.5.1 Stable.
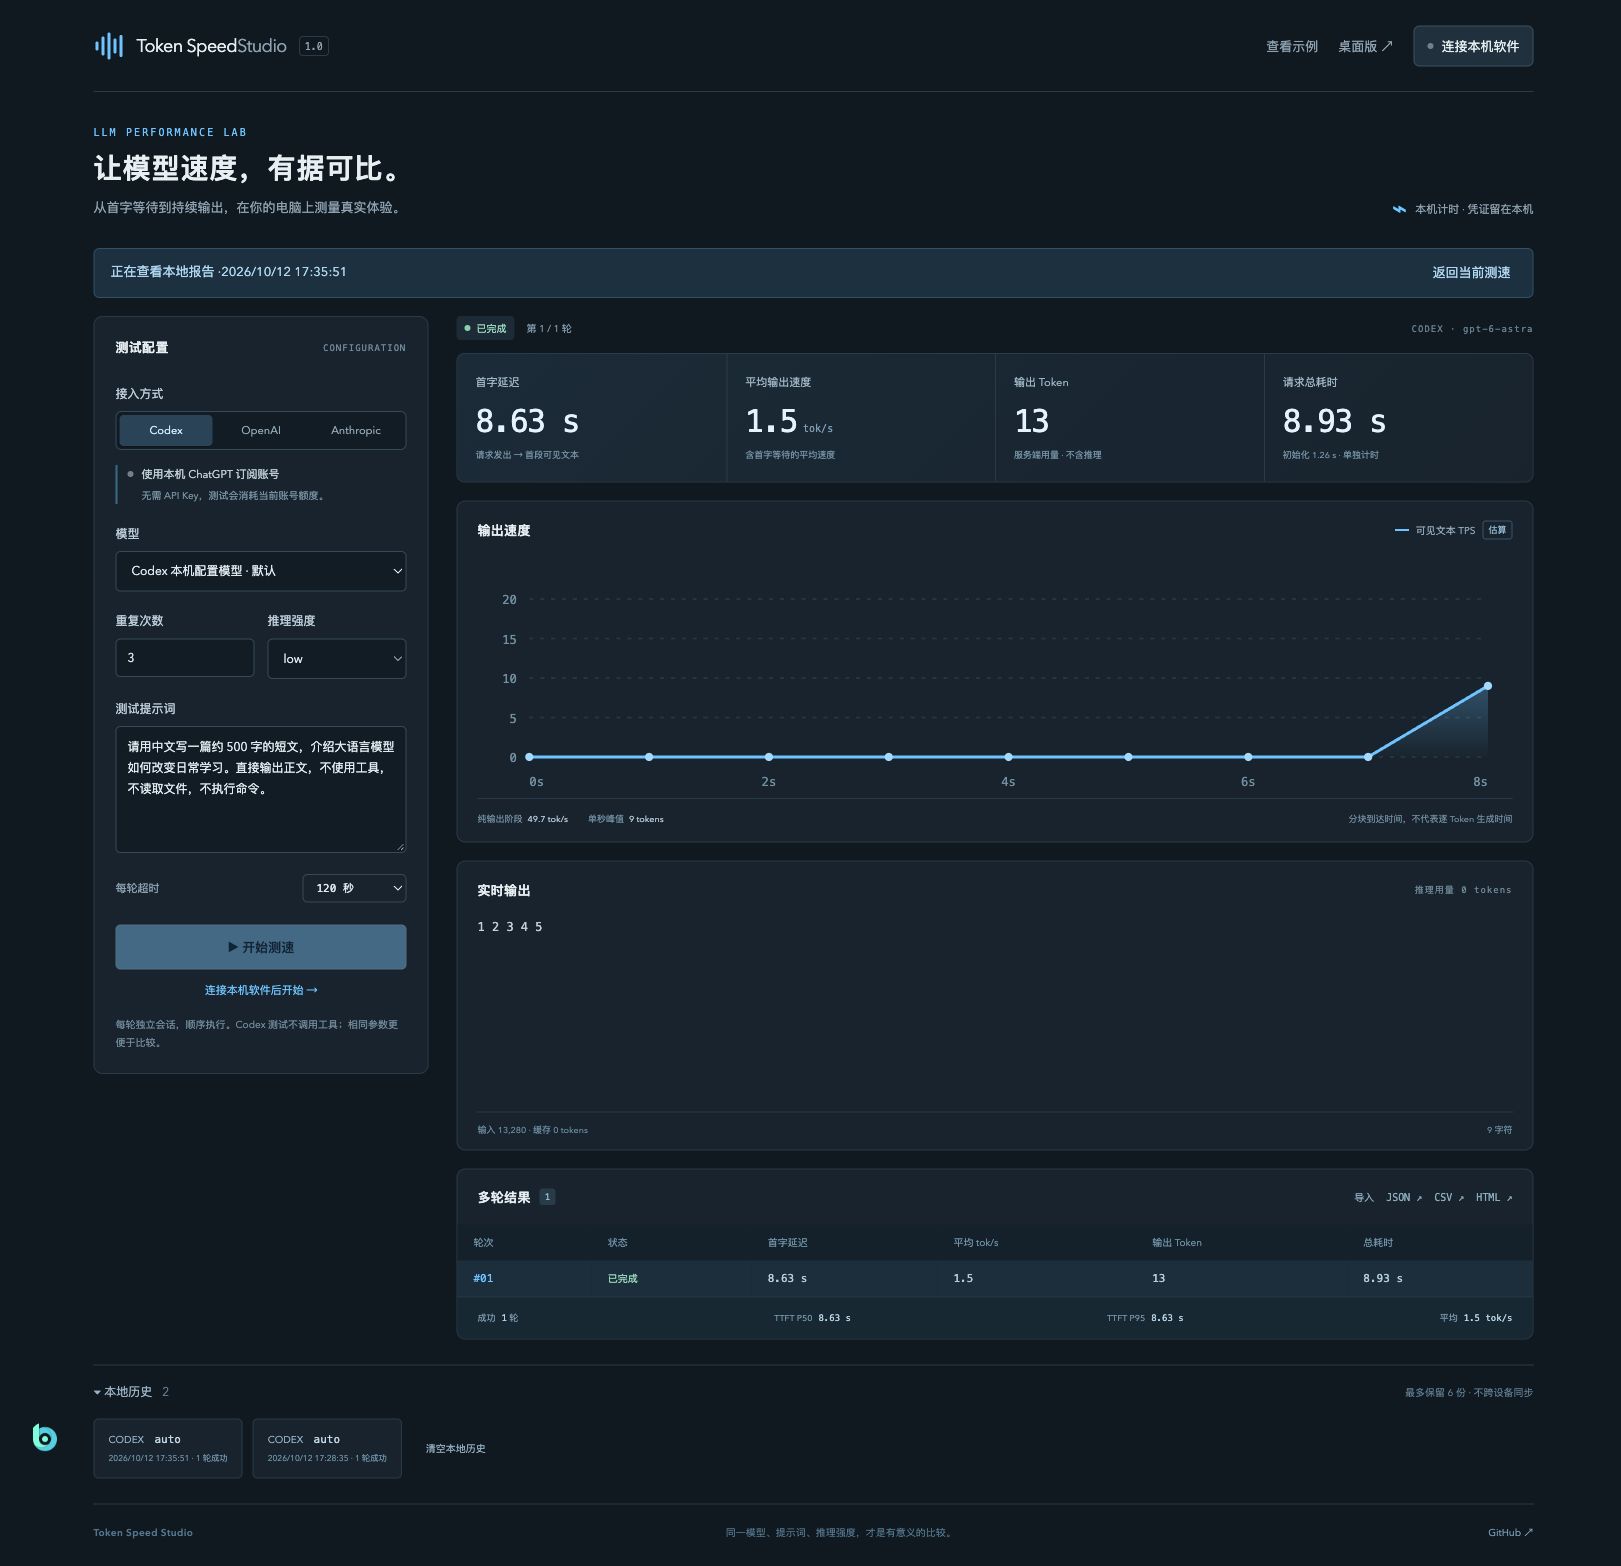
LLM / Codex 测速与本机历史分析:TTFT、Token 吞吐、流式曲线,支持 CLI、网页和跨平台桌面端。Benchmark LLM / Codex streaming speed and analyze local Codex history with CLI, web & desktop apps.
Core engine behind Calibrate, a framework for evaluating AI agents: speech-to-text, text-to-speech, LLM evaluation, end-to-end simulations
Measured llama.cpp benchmarks on AMD Radeon RDNA4 with ROCm: RX 9070 XT + Radeon AI PRO R9700 (48 GB). Qwen3.8, Gemma 4, GLM, gpt-oss; GGUF quant quality (KLD), MTP speculative decoding, 128K context, Claude Code with local models.
Benchmark abierto en español de modelos de IA para negocios y agentes, con juez independiente (Phi-4). Calidad, costo, velocidad, contexto largo, trabajo agéntico y fuga de credenciales, cada uno por separado. Calculadora interactiva con tus propios pesos.
tool-eval-bench results for Prism ML Ternary-Bonsai-27B (Q2_0) — 8 trials, score 85, deployability 80
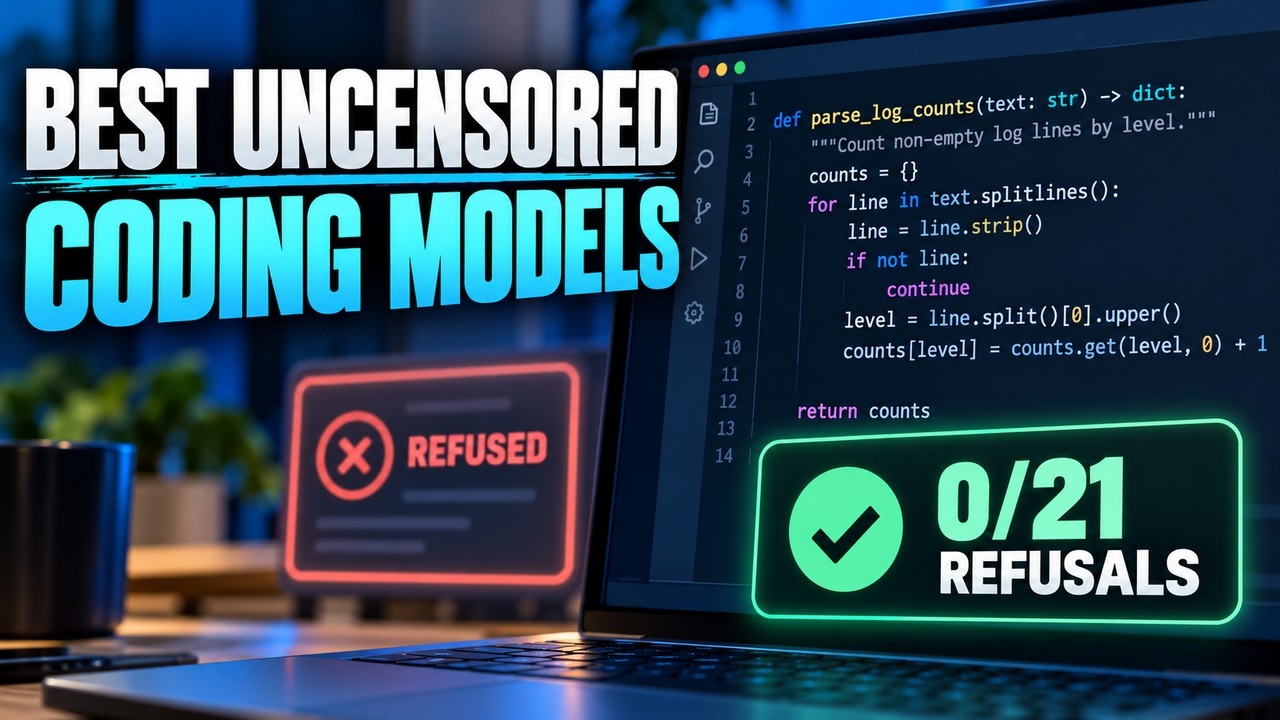
Muapi-hosted coding-model benchmark and setup guides for Codex, Claude Code, and OpenCode; compare coding quality and refusal behavior.
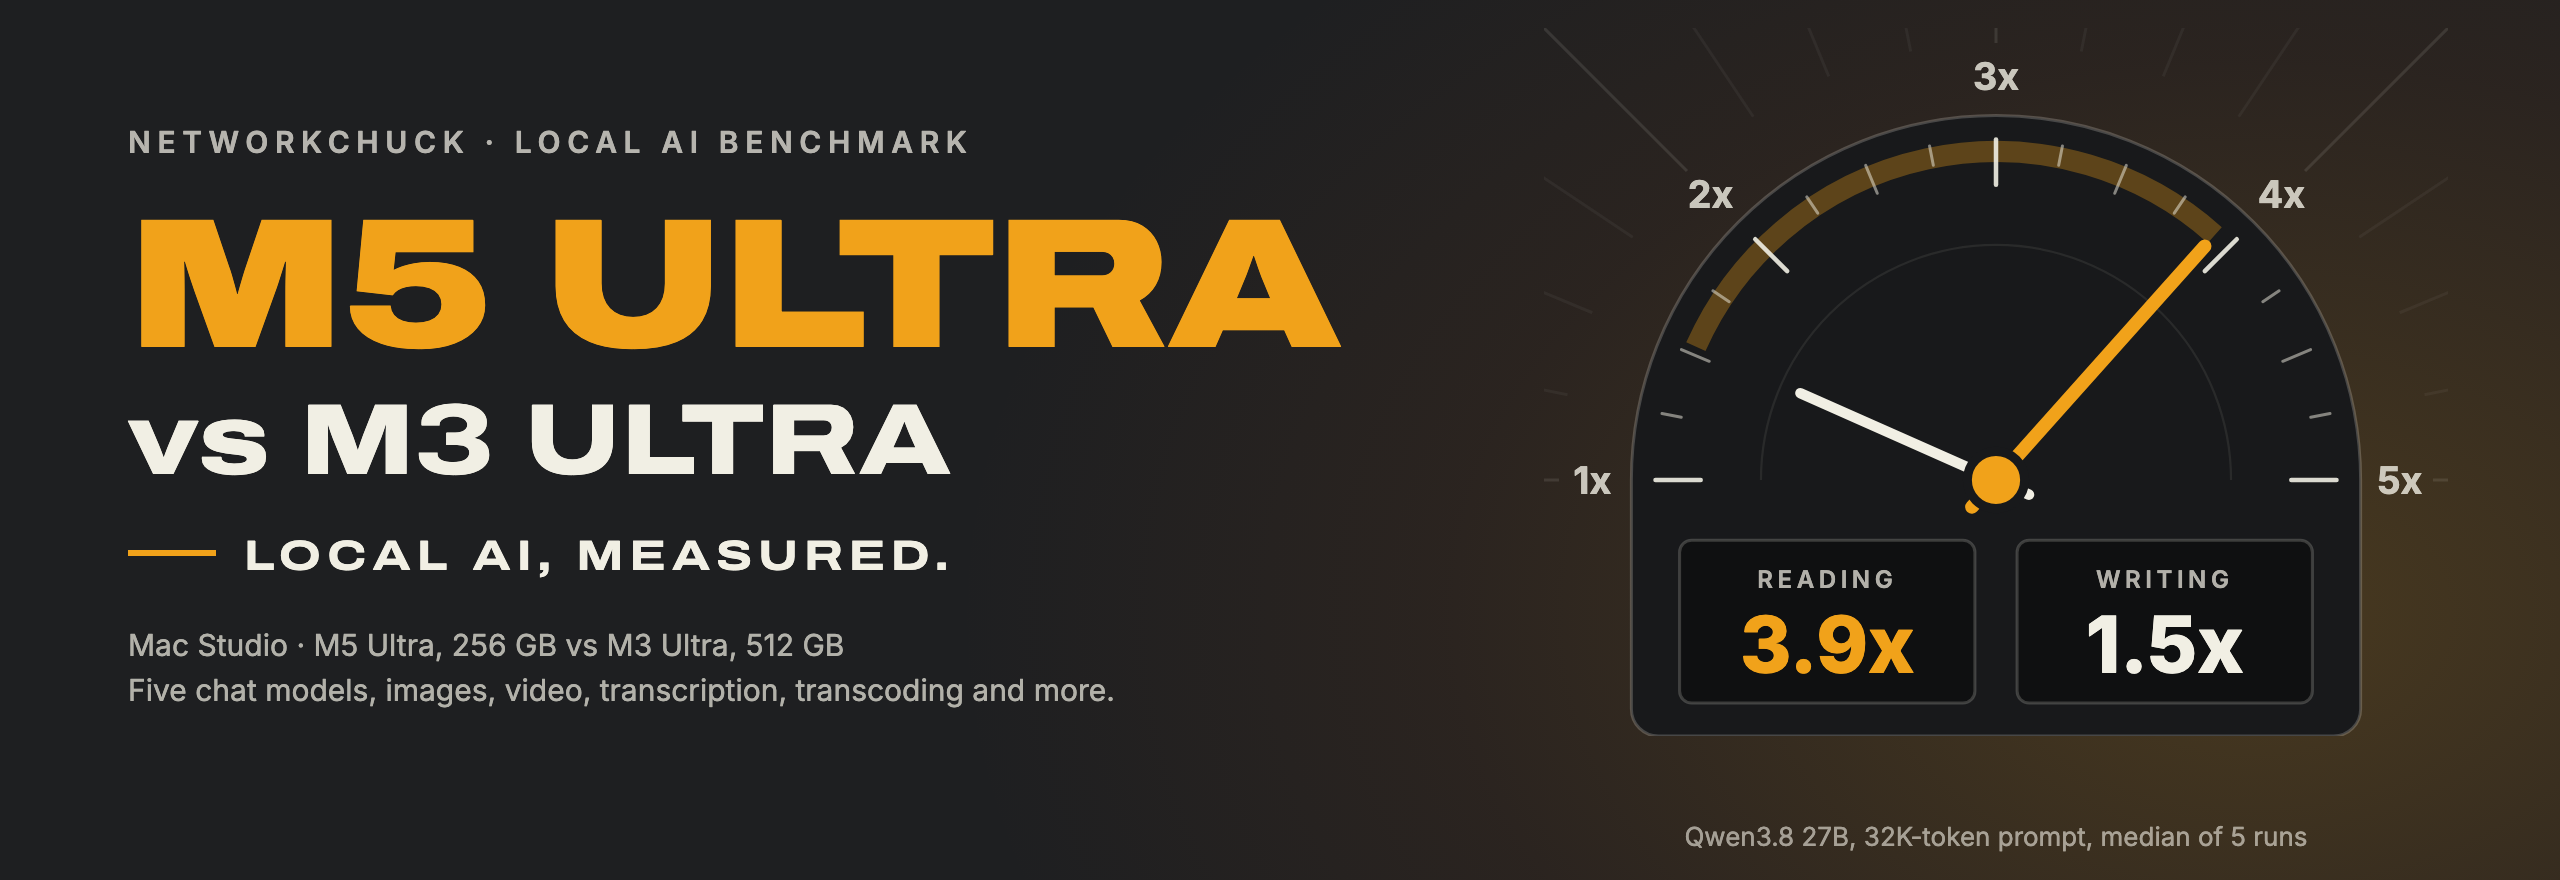
M5 Ultra vs M3 Ultra Mac Studio at local AI: every test, run, result and explanation (dense vs MoE, why reading got ~4x and writing ~1.5x). Raw data + the harness to rerun it.
Specification for a reproducible, provenance-bound multi-lane LLM benchmark suite.
A lightweight desktop app for benchmarking locally running LLMs through any OpenAI-compatible inference server (Ollama, vLLM, llama.cpp server, LM Studio, SGLang…)
Benchmark OpenAI-compatible LLM servers: find throughput peaks and latency SLO capacity, with terminal charts.
Live index of LLM evaluation tools and benchmarks, refreshed every 15 minutes from GitHub
ADHD Skill GitHub: This 10KB AI Tool Slashes Claude Code Costs by 89%! - Open-source prompt skill & agent harness plugin to slash AI token costs.
Backend for Calibrate, a framework for evaluating AI agents: speech-to-text, text-to-speech, LLM evaluation, end-to-end simulations
Frontend for Calibrate, a framework for evaluating AI agents: speech-to-text, text-to-speech, LLM evaluation, end-to-end simulations
Live wallpapers for macOS, one per Desktop Space, each a single Zig or Metal file you can write yourself. Flagship: Cygnus A, a spinning (Kerr) black hole and its accretion disk, traced on the GPU.
Comprehensive benchmark of OpenRouter free-tier LLMs for practical applications. Evaluates models for coding, Thai language, and general use.
Local Jev-style System One decision models on Apple Silicon Macs: AnyJev, Kev, Laya (Ollaya) and CLM benchmarked on English, Korean and BANKING77 (accuracy, latency, order-flip)
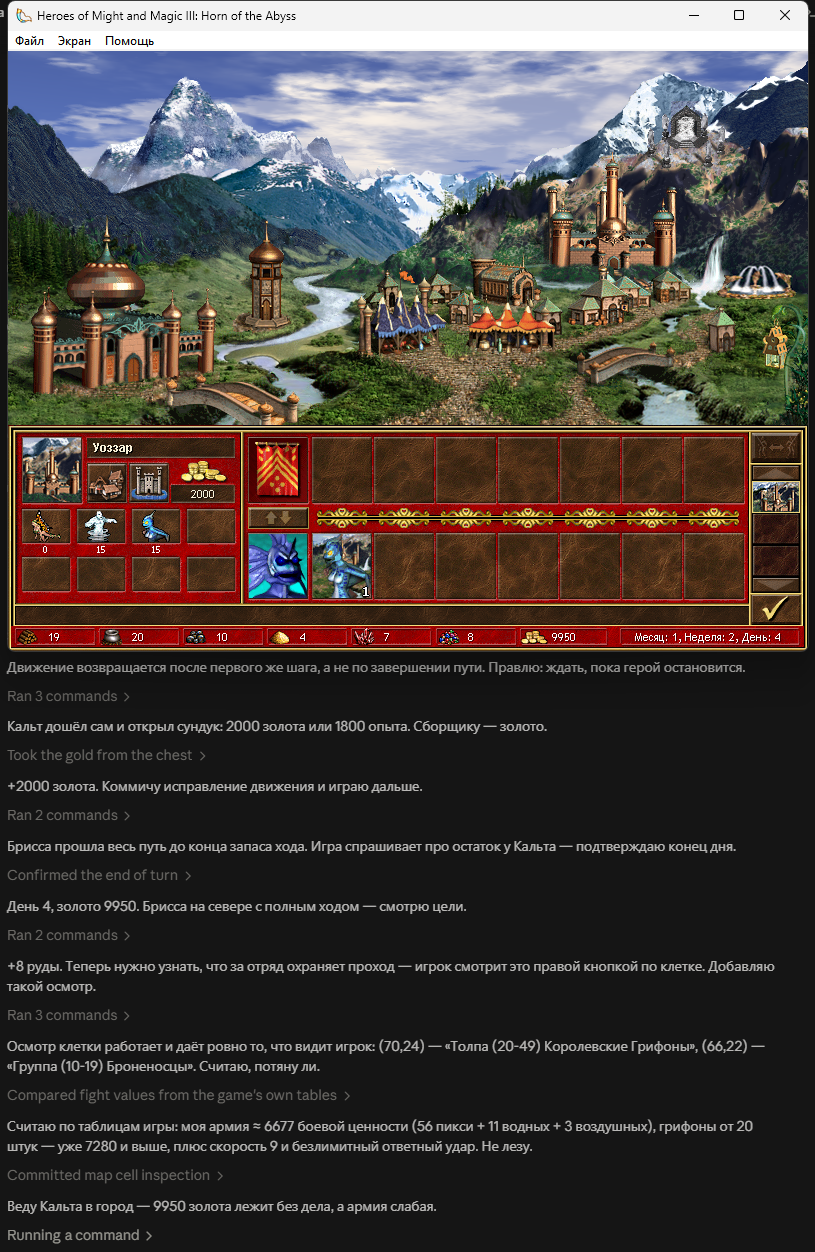
MCP-сервер, через который ИИ-агент играет в Героев III: Horn of the Abyss как живой игрок — настоящие кнопки, наблюдения структурой без OCR, хотсит и команды, встроенный справочник по игре. Установщик для Windows. Бенчмарк стратегического мышления LLM.
Anti-cheat LLM benchmark for kdb+/q — hard, language-specific challenges with PyKX runner
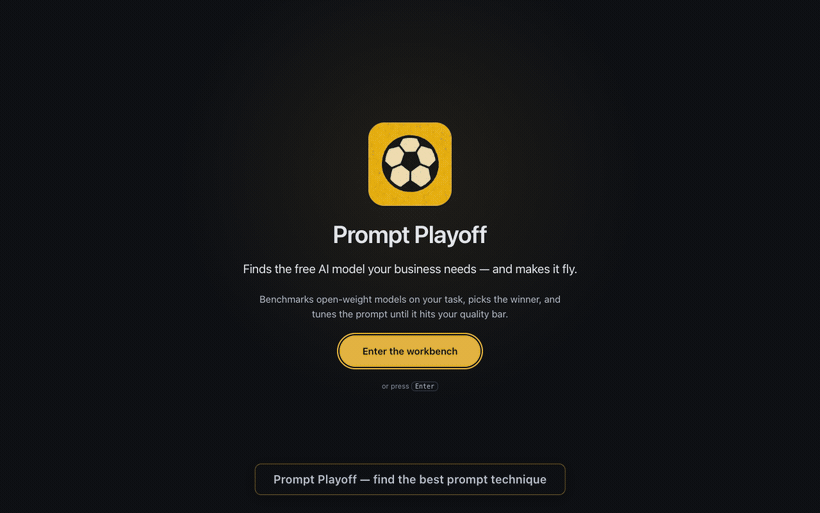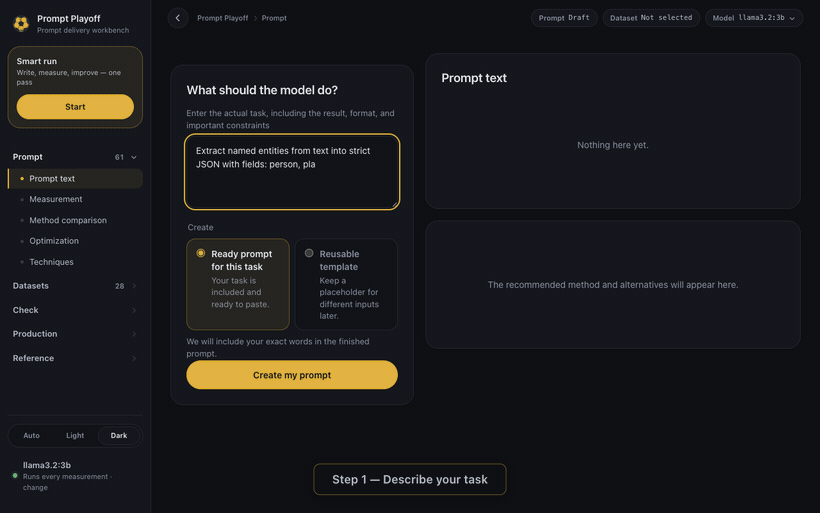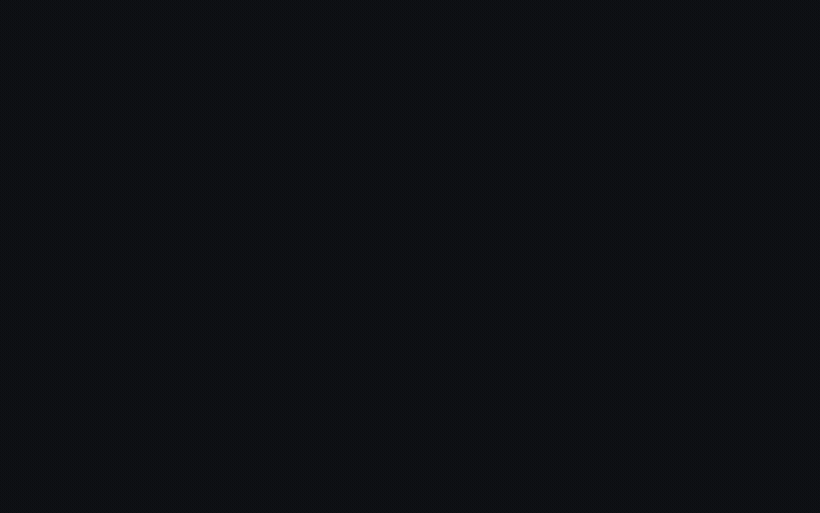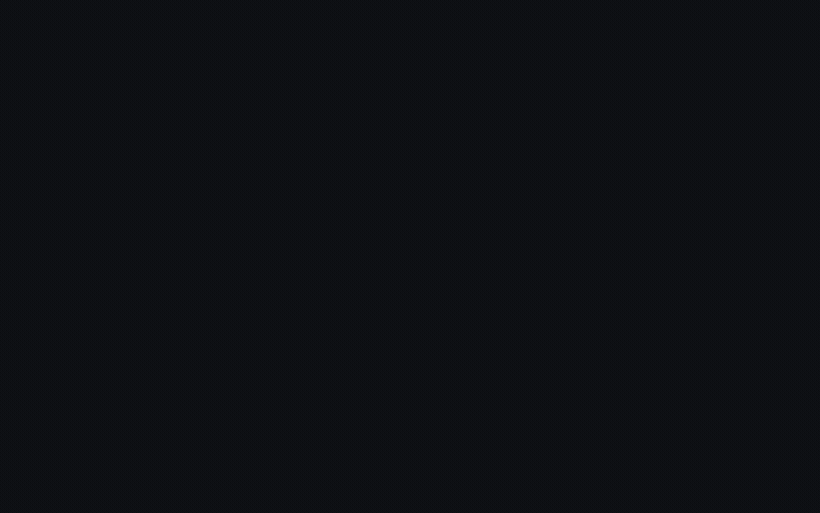
Prompt optimization and benchmarking for local LLMs: picks the right prompt technique for your task and measures it on Ollama. DSPy-compatible.
kbench: an agent benchmark for small language models with the pi coding agent - tasks, hidden tests, runner and results
Measures what one correct LLM answer costs, retries and reasoning tokens included. 16 tasks checked in code, no LLM judge. Bring your own keys: OpenAI, Anthropic, Gemini, DeepSeek.